{
  "fetched_at": "2026-10-20T03:06:23Z",
  "source_url": "https://www.kaggle.com/competitions/111-2-uta-dl-app-hw1/data",
  "pages": [
    {
      "name": "data-description",
      "content": "<h2> Data Format </h2>\nThe training and testing images are 28x28 gray images.  There are 62 classes (0 ~ 9 & A ~ Z & a ~z) in EMNIST dataset, which are labeled sequentially as 0, 1, 2, ..., 61. The original data are saved in both binary and MATLAB format. We've converted it into NumPy format so you can easily load the data.\n\n<h3>👀 <b><i>Note! the data have been uploaded to Kaggle, which is called \"NTUTEMNIST\". </i></b></h3>\n[www.kaggle.com/darkfanxing/ntutemnist](https://www.kaggle.com/darkfanxing/ntutemnist)\n<h3><b><i>You can add the data directly in Python notebook. Our example code already included the data.</i></b></h3>\n [how to add dataset to your notebook.](https://ibb.co/HdNsLjq)\n\n<h2>File descriptions</h2>\n<ul>\n<li><strong>emnist-byclass-train.npz</strong> - the training images and labels</li>\n<li><strong>emnist-byclass-test.npz</strong> - the test images</li>\n<li><strong>simple_nn_train.ipynb</strong> - A Jupyter notebook example of training a simple DNN model </li>\n</ul>",
      "isPublished": false,
      "hasIsPublished": false,
      "postTitle": "",
      "hasPostTitle": false,
      "mimeType": "",
      "hasMimeType": false
    },
    {
      "name": "Description",
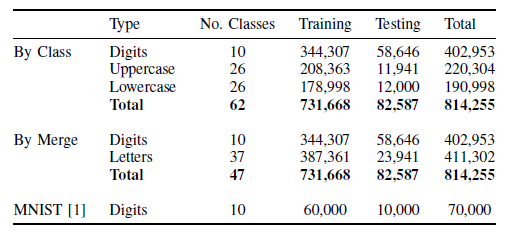
      "content": "<h2>Objective</h2>\n<p>In this homework, we will train a model for classifying handwritten letters and digits in Extended-MNIST (EMNIST) dataset (<a href=\"https://www.kaggle.com/crawford/emnist\">link</a>). \nThe EMNIST include 52 letters (capital and small letters) and 10 digits. We will use the default test dataset (emnist-byclass-test) to evaluate your model.   </p>\n<p>\nYou are free to use any neural network architecture, any DL library (PyTorch, TensorFlow, ...), or even any language. This is just a warm-up homework so don't worry about the accuracy too much. As long as your accuracy is better than random guess, you will get the credit.\n</p>\n<p>\n<b>Please register a Kaggle account starting with your student ID, so we can recognize you. </b>\n(同學們的Kaggle帳號請用學號當帳號名稱開頭, 以便登記分數時辨識.)\n</p>\n<h2>Input Data</h2>\n<p>We've converted the EMNIST binary data to NumPy npz format. The code below shows how to load training data:</p>\n<pre>import numpy as np\n# Load training data\ndata = np.load('emnist-byclass-train.npz')\ntrain_labels = data['training_labels']\ntrain_data = data['training_images']\n\n# Load testing data\ntest_data = np.load('emnist-byclass-test.npz')['testing_images']\n</pre>\n<p>You are free to download the original EMNIST from its official website. However <b>DON'T USE ByClass Testing Images for Training!</b>\nThe statistics of the EMNIST is shown in the table below: </p>\n![](https://www.googleapis.com/download/storage/v1/b/kaggle-user-content/o/inbox%2F1978103%2F22d9375e2ccf3684eb2d2732314f57ec%2Femnist_stats.png?generation=1569073009753035&amp;alt=media)\n\n<p>The <b>By_Class</b> split includes 62 classes comprising [0-9], [a-z] and [A-Z], while the <b>By_Merge</b> split has merged the uppercase and lowercase letters of C, I, J, K, L, M, O, P, S, U,  V, W, X, Y and Z, and include only 47 classes. </p>\n<br>\n\n<h2>Output Format</h2>\n<p>A submission file of prediction results should be a CSV file containing two columns: Id and Category, separated by ','. </p>\n<p>The file should contain a header and have the following format:</p>\n<pre>Id,Category\n0,15\n1,7\n2,30\n3,22\n...\n</pre>\n\nWe will use Category Accuracy as the metric. There are 62 classes (0 ~ 9 &amp; A ~ Z &amp; a ~z) in ByClass split of EMNIST dataset, which are labeled sequentially as 0, 1, 2, ..., 61.\n\n<h2>Kaggel Notebook Example</h2>\nYou can refer to the notebook to see how to train a model on Kaggle: (Code -&gt; Notebook)\n<a href=\"https://www.kaggle.com/kuantinglai/110-2-dl-app-hw1\">https://www.kaggle.com/kuantinglai/110-2-dl-app-hw1</a>\n\n<h2>References</h2>\n<ol>\n<li><a href=\"https://www.nist.gov/itl/iad/image-group/emnist-dataset\">EMNIST Official Website</a></li>\n<li><a href=\"https://arxiv.org/abs/1702.05373v1\">EMNIST paper</a></li>\n</ol>",
      "isPublished": false,
      "hasIsPublished": false,
      "postTitle": "",
      "hasPostTitle": false,
      "mimeType": "",
      "hasMimeType": false
    },
    {
      "name": "rules",
      "content": " This is an individual homework, butyou can discuss with your classmates. A few things to note:\n\n - Don't use test data for training\n\n - Apply yourself!\n\n - Have fun!",
      "isPublished": false,
      "hasIsPublished": false,
      "postTitle": "",
      "hasPostTitle": false,
      "mimeType": "",
      "hasMimeType": false
    }
  ]
}