 \n
Figure 2: A screenshot visualising the outcome of the supervised learning process in ChatGPT, taken from
https://www.youtube.com/watch?v=VPRSBzXzavo
 \n
Figure 3: Stable Diffusion visualised, image taken from
https://medium.com/@steinsfu/stable-diffusion-clearly-explained-ed008044e07e\"
 \n
Figure 4: An image generated by Stable Diffusion 2.1 given the prompt \"a fox eating biscuits on the bed\"
\n","metadata":{}},{"cell_type":"markdown","source":"# Video Processing and Generation\nSuppose you had a friend, Jack, who doesn’t know what a video is, but he knows what images are. How would you explain the concept of a video to Jack? Or an AI model? Perhaps you might have heard of how videos have frame rates, the YouTube video you watched yesterday has a frame rate of 24 fps (frames per second), etc. A video is a bunch of images shown in an order, and a video at 24 fps plays through 24 images per second. The point we’re making here is that videos are just images with a temporal order. If AI can process images, and it can register this temporal order, then it can process videos and tell us what’s going on in the video. Suddenly this seems quite similar to the LLM, you can have the same frequency of words appearing in two sentences but mean completely different things, and each frame, analogous to each word, could have its own meaning. If you recall what we talked about Transformers used in LLMs, they have a component which stores information about the lexical meaning of each word, and another component which stores information about the position of each word. [21] Video processing models behave analogously to Transformers. Here is a quick showcase of a plethora of video technologies.\n\n### Generating Image/Video Descriptions\n\nVideo-LLaMa is an AI model that looks at a video and processes its visual and auditory data. From there, it can give accurate descriptions of the video, and it seems to be capable of interpreting basic sentiments that are probably found in its training data. [21] \n\n### Video Editing, Made Really Simple\n\nFFMPerative is an AI model that does video editing based on commands in natural language. This makes the video editing process a lot simpler! [22]\n\n### Video Generation\n\nMeta has also released an AI that generates videos based on text, image, and video inputs. The video outputs are extremely lifelike, and they claim to have a 3x better representation of the text input and 3x better quality. [23]\n\nVideo generation products could potentially use to improve the quality of simulations and generate important training data, such as simulations for driving students and autonomous vehicles to avoid the need to learn by crashing cars.\n","metadata":{}},{"cell_type":"markdown","source":"# 3D Visualisation and Generation\n\nThink about this, although we live in a 3D world, we only have 2D vision. That means, our vision can be represented by static images on a plane, such as paintings or photographs. Yet, we are able to discern the proximity of an object to ourselves by studying this 2D map. This suggests that there is something, perhaps in the colours or something else, that hints how far an object really is from us. And most importantly, if we can do it, so can AI!\n\nGenerating 3D structures can often be helpful because it gives us an idea of what we can be working with. OpenAI has released Shap-E, a model based on diffusion that takes in a text prompt and generates a 3D representation of it. Examples are provided on the GitHub page [24], and details can be found in the paper. [25] Although the generated models look a little cartoonish, they can be used for rough purposes and their potential is great. \n\n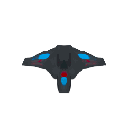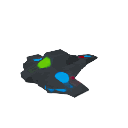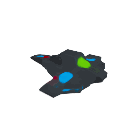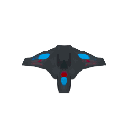\nFigure 5: GIF of 3D spaceship generated by Shap-E, posted on https://github.com/openai/shap-e
\n\nAnother important field which features 3D generation is image reconstruction. As images are captured by modern technology, they are compressed from 3D to 2D objects, which results in a loss of information. However, not all information about the dimensionality is lost (as per the earlier example), and AI can be trained to generate a 3D reconstruction of an image. Researchers from MIT and Princeton IAS have trained an AI to do precisely so, along with a corresponding depth map of the reconstructed 3D scene. [26] Neuralangelo, on the other hand, creates a 3D model based on an RGB video capture. [27]","metadata":{}},{"cell_type":"markdown","source":"# Speech Generation Technology\n\nSpeech generation is also trending on social media as deepfake technology become more accessible. We can find parodies of celebrities and politicians giving speeches by doing quick searches on YouTube. Here are references to videos of a deepfaked campaign speech by POTUS Joe Biden and a deepfake speech by Morgan Freeman. [34][35] We also think that audio generation has advanced so greatly that we are unable to discern the quality of the models solely by listening.\n\nAudioPaLM, a model released very recently, seems to have an impressive showcase on its website. [36][37] As a show of its capabilities, this model accepts speech in other languages and outputs an audio of the speaker speaking the same thing in English, preserving the qualities of the speaker’s voice. As translation services on the internet become better, innovations such as this allow language barriers to be bypassed. This model accepts speech as an input, tokenises the audio and text, and outputs a translation of the text, preserving the voice of a speaker. That is, a man speaking Chinese to the model lets the model generate an audio of the same person speaking the corresponding English translation of whatever he has said. Such a method allows very human-like audio samples to be generated.\n\nText-to-speech audio has become more realistic, also indiscernible to our ears. Many models now accept text and output a realistic audio reading the text. They also accept audio of a voice as an additional parameter and output the voice reading the text instead. Some examples of AI text-to-speech products include Voicebox by Meta [38] and a voice AI made by ElevenLabs. [39]","metadata":{}},{"cell_type":"markdown","source":"# Music Generation and Deepfake Singing\n\nMusic generation using AI has also been an ongoing field of research. It’s not a new field of study, but it hasn’t exactly been perfect either. In 2019, Huawei collaborated with musician Lucas Cantor to complete Schubert’s “Unfinished” 8th Symphony, which was incomplete at the time of his death. Among praises, some reviews were critical in saying that the parts filled in by the AI neither reflected the earlier parts of the piece nor Schubert’s compositions. [28] There is also a sentiment that the parts filled in by the AI sounded like film music. [29] Let’s look at updates from 2023.\n\nIn 2023, we have MusicLM by Google, an impressive text-to-music model that generates music based on text prompting. It is capable of responding to rather complex prompts consisting of a few sentences, but it is still unable to generate music according to oddly specific text prompts such as “vladimir lenin smoking weed with bob marley”. [30] It is also capable of accepting other forms of input such as audio, by whistling or humming. This is done by tokenising text and audio, and its training is heavily inspired by AudioLM. [31] It also has an additional feature that makes its outputs relevant to the prompt: it tokenises two components of audio inputs, a temporal feature and an acoustic feature. The temporal feature captures patterns and relationships between the start of the music, middle of the music, and end of the music, so the music doesn’t sound completely random; whereas the acoustic feature captures details about the music including its timbre, pitch, melody, etc. [31] For MusicLM, the text and audio inputs are embedded with BERT and ResNet-50 respectively.\n\nWe also seem to be seeing a lot of deepfakes on YouTube this year. In 2023, the public has greater access to deepfake services because more companies monetise their deepfake products and there are also free services online if you look hard enough. An interesting instance of deepfake music we see is deepfake singing, where models are trained on the original music, the voice of another person (usually a singer or president), and outputs an audio with the other person singing it instead of the original singer. One such model used is Musicfy, a model that learns any voice of the user’s desire and generates singing with the voice. [32] This video on YouTube is a deepfake audio of Cupid covered by Bruno Mars. [33] \n[Video: Bruno Mars singing Cupid generated by Musicfy](https://www.youtube.com/watch?v=yqQ8OKvDlww)\n\nWe believe that music generation technology can help people gain a greater appreciation for the aesthetics, but it has a long way to go and a tough fight against intellectual property rules.","metadata":{}},{"cell_type":"markdown","source":"# Future Changes\n\nThroughout the past decade, GenAI was powered by convolutional techniques, and its outputs have become more detailed and surreal as convolutional models improve when equipped with novel concepts and new functionalities. Just in case it’s not obvious, Transformers are 2D convolutional models that span the token space and the time space (which encodes the position of the each word). These new technologies have capabilities surpassing what used to be our state-of-the-art models, such as LSTMs for language learning, and GANs for media generation. We foresee that the quality of 3D generation will continue to improve, and technology becomes readily available for those who seek a fuller comprehension of the world they live in.\n\nFinally, we think that in future work, we may expect to see generative technology used to study more theoretical concepts which might prove important for science, for example, to provide a visualisation of abstract spaces, higher and fractional dimensions, and revolutionise the pedagogical approach towards many subjects.","metadata":{}},{"cell_type":"markdown","source":"# Conclusion\n\nThe ability of neural networks to learn is most impressive, and it has done extremely well in capturing even patterns incomprehensible by us. Generative AI, in particular, specialises in transforming intangible ideas into something that can be understood by humans and machines alike. Before we end, however, we would like to pose one final question: how similar are humans to AI? What a dehumanising question, but think about it – human memory is prone to being altered by doctored images or experiences [40], and ChatGPT have been reported to hallucinate. [41] We show confirmation bias, and so do LLMs. The list goes on, but there is a pattern of irrational cognitive behaviour amongst us, and corresponding unexplained behaviour in LLMs. Does this mean that irrational behaviour comes from the training data (or the lack of it)? Could it arise from the architecture of LLMs, or other AI models for that matter? We believe such questioning may proceed to yield rich answers, and may help us develop a deeper understanding of human cognition, a primitive function of us that has continued the human species through the years.\n\nFinally, we think that among all this sentience shown by chatbots, there could very much be a shift in ideals as the limits of knowledge corrode over the next decade. It was a joy for us to write this essay, and we hope to meet you again with exciting ideas. Till then, seeya!\n","metadata":{}},{"cell_type":"markdown","source":"# References\n\n[1] K. Hornik, M. Stinchcombe, and H. White, “Multilayer feedforward networks are universal approximators,” Neural Networks, vol. 2, no. 5, pp. 359–366, 1989. doi:10.1016/0893-6080(89)90020-8 \n\n[2] D. Mazurek, “Rizz Meaning & Origin,” Dictionary.com, https://www.dictionary.com/e/slang/rizz/ (accessed Jun. 25, 2023). \n\n[3] A. Karpathy, “The hottest new programming language is English,” Twitter, https://twitter.com/karpathy/status/1617979122625712128 (accessed Jun. 25, 2023). \n\n[4] arXiv: 1706.03762 [cs.CL]\n\n[5] arXiv: 2303.08774 [cs.CL] \n\n[6] Google, https://bard.google.com/ (accessed Jun. 25, 2023). \n\n[7] arXiv: 2302.13971 [cs.CL] \n\n[8] R. Albergotti, “The secret history of Elon Musk, Sam Altman, and OpenAI,” Semafor, https://www.semafor.com/article/03/24/2023/the-secret-history-of-elon-musk-sam-altman-and-openai (accessed Jun. 24, 2023). \n\n[9] arXiv: 2005.14165 [cs.CL]\n\n[10] Radford, A., Wu, J., Child, R., Luan, D., Amodei, D. & Sutskever, I. (2018). Language Models are Unsupervised Multitask Learners.\n\n[11] “GPT-4’s very last words to humanity before our collective doom,” Reddit, https://www.reddit.com/r/ChatGPT/comments/13o8tx3/gpt4s_very_last_words_to_humanity_before_our/ (accessed Jun. 25, 2023). \n\n[12] L. Brown, “Unlock Your Inner Poet: A Guide to Writing Romantic Love Letters with ChatGPT Prompts,” Filmora, https://filmora.wondershare.com/chatgpt/romantic-chatgpt-prompts.html (accessed Jun. 25, 2023). \n\n[13] “The Top 5 Funniest Jokes Generated by ChatGPT,” Reddit, https://www.reddit.com/r/ChatGPT/comments/13430s2/the_top_5_funniest_jokes_generated_by_chatgpt/ (accessed Jun. 25, 2023). \n\n[14] V. L. Bommineni, S. Bhagwagar, D. Balcarcel, C. Davatzikos, and D. Boyer, Performance of ChatGPT on the MCAT: The road to personalized and equitable premedical learning, 2023. medRxiv doi:10.1101/2023.03.05.23286533 \n\n[15] I. Anghel, “PWC introduces AI chatbot for 4,000 lawyers to speed up work,” Bloomberg.com, https://www.bloomberg.com/news/articles/2023-03-15/pwc-introduces-ai-chatbot-for-4-000-lawyers-to-speed-up-work (accessed Jun. 25, 2023). \n\n[16] Person and S. Merken, “New York lawyers sanctioned for using fake ChatGPT cases in legal brief,” Reuters, https://www.reuters.com/legal/new-york-lawyers-sanctioned-using-fake-chatgpt-cases-legal-brief-2023-06-22/ (accessed Jun. 25, 2023). \n\n[17] arXiv: 2112.10752 [cs.CV]\n\n[18] arXiv: 1705.07202 [cs.CV] \n\n[19] T. Agrawal, “GANs Failure Modes: How to Identify and Monitor Them,” neptune.ai, https://neptune.ai/blog/gan-failure-modes (accessed Jun. 26, 2023). \n\n[20] S. Tobin, “Getty asks London Court to stop UK sales of stability AI system,” Reuters, https://www.reuters.com/technology/getty-asks-london-court-stop-uk-sales-stability-ai-system-2023-06-01/ (accessed Jun. 26, 2023). \n\n[21] arXiv: 2306.02858 [cs.CL] \n\n[22] remyxai, “remyxai/FFMPerative: Chat to process video,” GitHub, https://github.com/remyxai/FFMPerative (accessed Jun. 26, 2023). \n\n[23] arXiv: 2209.14792 [cs.CV]\n\n[24] OpenAI, “Shap-E: Generate 3D objects conditioned on text or images,” GitHub, https://github.com/openai/shap-e (accessed Jul. 2, 2023). \n\n[25] arXiv: 2305.02463 [cs.CV] \n\n[26] arXiv: 2306.11719 [cs.CV] \n\n[27] arXiv: 2306.03092 [cs.CV] \n\n[28] G. Richter, “Composers are under no threat from AI, if Huawei’s finished Schubert symphony is a guide,” The Conversation, https://theconversation.com/composers-are-under-no-threat-from-ai-if-huaweis-finished-schubert-symphony-is-a-guide-111630 (accessed Jun. 26, 2023). \n\n[29] TwoSetViolin, “Artificial Intelligence Composed This Symphony!?,” YouTube, https://www.youtube.com/watch?v=R69JYEfCSeI (accessed Jun. 26, 2023). \n\n[30] bycloud, “Google’s MusicLM: Text Generated Music & It’s Absurdly Good,” YouTube, https://www.youtube.com/watch?v=2CUKU2iAzAs (accessed Jun. 26, 2023). \n\n[31] arXiv: 2301.11325 [cs.SD] \n\n[32] “Musicfy: Product Features,” Musicfy, https://musicfy.lol/product-features (accessed Jun. 26, 2023). \n\n[33] Sijro Mashups, “Bruno Mars - Cupid [ai cover of Fifty Fifty],” YouTube, https://www.youtube.com/watch?v=yqQ8OKvDlww (accessed Jun. 26, 2023). \n\n[34] “AI Joe Biden tells it like it is. #tdsthrowback #shorts #politics,” YouTube, https://www.youtube.com/shorts/HbBjonrc6cY (accessed Jun. 26, 2023). \n\n[35] “This is not Morgan Freeman - A Deepfake Singularity,” YouTube, https://www.youtube.com/watch?v=oxXpB9pSETo (accessed Jun. 26, 2023). \n\n[36] arXiv: 2306.12925 [cs.CL] \n\n[37] AudioPaLM: A Large Language Model That Can Speak and Listen, https://google-research.github.io/seanet/audiopalm/examples/ (accessed Jun. 26, 2023). \n\n[38] “Introducing Voicebox: The Most Versatile AI for Speech Generation,” Meta, https://about.fb.com/news/2023/06/introducing-voicebox-ai-for-speech-generation/ (accessed Jun. 26, 2023). \n\n[39] “Prime Voice AI,” ElevenLabs, https://beta.elevenlabs.io/ (accessed Jun. 26, 2023). \n\n[40] E. F. Loftus and J. C. Palmer, “Reconstruction of Automobile Destruction: An example of the interaction between language and memory,” Journal of Verbal Learning and Verbal Behavior, vol. 13, no. 5, pp. 585–589, 1974. doi:10.1016/s0022-5371(74)80011-3 \n\n[41] “ChatGPT’s hallucination just got OpenAI sued. Here’s what happened,” ZDNET, https://www.zdnet.com/article/chatgpts-hallucination-just-got-openai-sued-heres-what-happened (accessed Jul. 2, 2023). \n","metadata":{}},{"cell_type":"code","source":"import pandas as pd\n\nsubmission = pd.read_csv(\"../input/2023-kaggle-ai-report/sample_submission.csv\", index_col=\"type\")\n\nsubmission.loc['essay_category'] = 'Generative AI'\nsubmission.loc['essay_url'] = 'https://www.kaggle.com/code/acetonewong/what-genai-looks-like-in-2023'\nsubmission.loc['feedback1_url'] = 'https://www.kaggle.com/code/sanketshindes20/generative-ai-unleashing-the-power-of-creativity/comments#2331174'\nsubmission.loc['feedback2_url'] = 'https://www.kaggle.com/code/lannister/kaggle-ai-report-generative-ai-in-computer-vision/comments#2336702'\nsubmission.loc['feedback3_url'] = 'https://www.kaggle.com/code/mahadevan39/the-generative-leap/comments#2340390'\n\nsubmission.to_csv('submission.csv', index=True)","metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"execution":{"iopub.status.busy":"2023-07-09T20:32:29.250846Z","iopub.execute_input":"2023-07-09T20:32:29.251260Z","iopub.status.idle":"2023-07-09T20:32:29.334912Z","shell.execute_reply.started":"2023-07-09T20:32:29.251228Z","shell.execute_reply":"2023-07-09T20:32:29.333269Z"},"trusted":true},"execution_count":null,"outputs":[]}]}