{
  "id": 368190,
  "title": "9th Place Solution ",
  "url": "/competitions/AI4Code/writeups/ogy-9th-place-solution",
  "author_name": "",
  "post_date": "2022-11-24T03:29:22.360Z",
  "votes": 12,
  "comment_count": 4,
  "views": 0,
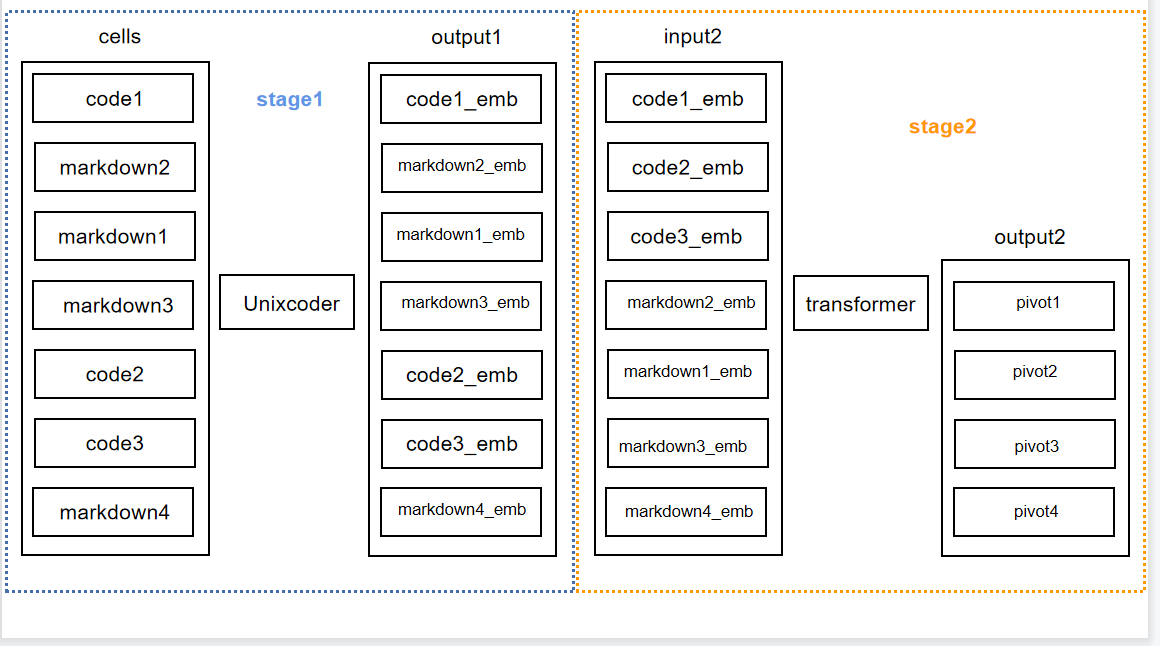
  "content": "<h1><strong>Overview</strong></h1>\n<p>The final submission of us is a blend of three models with same architecture and different training data. Three models share the same pipline. We applied a two stage method for the competition.</p>\n<ol>\n<li>Training a bert model (Unixcoder) to get sentence embedding for each cell;</li>\n<li>Training a simple transformer with sentence embedding (or cell embedding) input.<br>\n<img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F847605%2F80fe690c1982391400afb3cf290bd89e%2F1.png?generation=1669259314036608&amp;alt=media\" alt=\"\"></li>\n</ol>\n<h1><strong>Our Code</strong>:</h1>\n<p>Submit and training code : <a href=\"https://www.kaggle.com/code/qiaoshiji/fork-of-ai4code-infer-22e56e/data?scriptVersionId=103071263\" target=\"_blank\">https://www.kaggle.com/code/qiaoshiji/fork-of-ai4code-infer-22e56e/data?scriptVersionId=103071263</a></p>\n<h1><strong>What Worked</strong></h1>\n<ol>\n<li>Using unixcoder as first stage pretrained model. The inital score of different model is shown as following:<br>\ncodebert 0.8226<br>\ngraphcodebert 0.8482<br>\nPlbart 0.8492<br>\ncodet5 0.8475<br>\nunixcoder 0.8594</li>\n<li>Pretrain first stage model using three different types of the task as following:</li>\n</ol>\n<ul>\n<li>Randomly selecting N successive cells and training rerank task;</li>\n<li>Randomly selecting one cell and predicting next cell;</li>\n<li>Randomly selecting N successive cells and choosing one cell as query, rest as answer.</li>\n</ul>\n<ol>\n<li>Using longer sequence input in second stage, 512 code cells and 512 markdown cells for our final model</li>\n<li>Multi task for second stage model:</li>\n</ol>\n<ul>\n<li>Position as regression task</li>\n<li>The position of markdown between which two code cells</li>\n<li>The number of markdown cells between every two code cells</li>\n</ul>\n<ol>\n<li>Using more data:</li>\n</ol>\n<ul>\n<li>Raw data for model1</li>\n<li>Raw data + ext data1 for model2</li>\n<li>Raw data + ext data2 for model3<br>\nExt data is from KGTorrent:&nbsp;<a href=\"https://github.com/collab-uniba/KGTorrent\" target=\"_blank\">https://github.com/collab-uniba/KGTorrent</a></li>\n</ul>\n<h1><strong>What Didn’t Work</strong></h1>\n<ol>\n<li>Classify model as ensemble model</li>\n<li>Making group by the number of cells and training models for each group</li>\n</ol>\n<h1><strong>Important Citations</strong></h1>\n<ol>\n<li>KGTorrent<br>\nGithub:&nbsp;<a href=\"https://github.com/collab-uniba/KGTorrent\" target=\"_blank\">https://github.com/collab-uniba/KGTorrent</a><br>\nPaper:&nbsp;<a href=\"https://arxiv.org/abs/2103.10558\" target=\"_blank\">https://arxiv.org/abs/2103.10558</a></li>\n<li>UniXcoder<br>\nGithub:&nbsp;<a href=\"https://github.com/microsoft/CodeBERT/tree/master/UniXcoder#1-code-and-nl-embeddings\" target=\"_blank\">https://github.com/microsoft/CodeBERT/tree/master/UniXcoder#1-code-and-nl-embeddings</a></li>\n</ol>\n<h1><strong>Thanks and Acknowledgements</strong></h1>\n<p>Many thanks to organizer for hosting such a great competition.</p>\n<h1><strong>Team Members</strong>:</h1>\n<p><a href=\"https://www.kaggle.com/guoday\" target=\"_blank\">@guoday</a> <br>\n<a href=\"https://www.kaggle.com/mahluo\" target=\"_blank\">@mahluo</a> </p>",
  "messages": [
    {
      "id": "2041536",
      "postDate": "11/24/2022 03:19:15",
      "content": "<h1><strong>Overview</strong></h1>\n<p>The final submission of us is a blend of three models with same architecture and different training data. Three models share the same pipline. We applied a two stage method for the competition.</p>\n<ol>\n<li>Training a bert model (Unixcoder) to get sentence embedding for each cell;</li>\n<li>Training a simple transformer with sentence embedding (or cell embedding) input.<br>\n<img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F847605%2F80fe690c1982391400afb3cf290bd89e%2F1.png?generation=1669259314036608&amp;alt=media\" alt=\"\"></li>\n</ol>\n<h1><strong>Our Code</strong>:</h1>\n<p>Submit and training code : <a href=\"https://www.kaggle.com/code/qiaoshiji/fork-of-ai4code-infer-22e56e/data?scriptVersionId=103071263\" target=\"_blank\">https://www.kaggle.com/code/qiaoshiji/fork-of-ai4code-infer-22e56e/data?scriptVersionId=103071263</a></p>\n<h1><strong>What Worked</strong></h1>\n<ol>\n<li>Using unixcoder as first stage pretrained model. The inital score of different model is shown as following:<br>\ncodebert 0.8226<br>\ngraphcodebert 0.8482<br>\nPlbart 0.8492<br>\ncodet5 0.8475<br>\nunixcoder 0.8594</li>\n<li>Pretrain first stage model using three different types of the task as following:</li>\n</ol>\n<ul>\n<li>Randomly selecting N successive cells and training rerank task;</li>\n<li>Randomly selecting one cell and predicting next cell;</li>\n<li>Randomly selecting N successive cells and choosing one cell as query, rest as answer.</li>\n</ul>\n<ol>\n<li>Using longer sequence input in second stage, 512 code cells and 512 markdown cells for our final model</li>\n<li>Multi task for second stage model:</li>\n</ol>\n<ul>\n<li>Position as regression task</li>\n<li>The position of markdown between which two code cells</li>\n<li>The number of markdown cells between every two code cells</li>\n</ul>\n<ol>\n<li>Using more data:</li>\n</ol>\n<ul>\n<li>Raw data for model1</li>\n<li>Raw data + ext data1 for model2</li>\n<li>Raw data + ext data2 for model3<br>\nExt data is from KGTorrent:&nbsp;<a href=\"https://github.com/collab-uniba/KGTorrent\" target=\"_blank\">https://github.com/collab-uniba/KGTorrent</a></li>\n</ul>\n<h1><strong>What Didn’t Work</strong></h1>\n<ol>\n<li>Classify model as ensemble model</li>\n<li>Making group by the number of cells and training models for each group</li>\n</ol>\n<h1><strong>Important Citations</strong></h1>\n<ol>\n<li>KGTorrent<br>\nGithub:&nbsp;<a href=\"https://github.com/collab-uniba/KGTorrent\" target=\"_blank\">https://github.com/collab-uniba/KGTorrent</a><br>\nPaper:&nbsp;<a href=\"https://arxiv.org/abs/2103.10558\" target=\"_blank\">https://arxiv.org/abs/2103.10558</a></li>\n<li>UniXcoder<br>\nGithub:&nbsp;<a href=\"https://github.com/microsoft/CodeBERT/tree/master/UniXcoder#1-code-and-nl-embeddings\" target=\"_blank\">https://github.com/microsoft/CodeBERT/tree/master/UniXcoder#1-code-and-nl-embeddings</a></li>\n</ol>\n<h1><strong>Thanks and Acknowledgements</strong></h1>\n<p>Many thanks to organizer for hosting such a great competition.</p>\n<h1><strong>Team Members</strong>:</h1>\n<p><a href=\"https://www.kaggle.com/guoday\" target=\"_blank\">@guoday</a> <br>\n<a href=\"https://www.kaggle.com/mahluo\" target=\"_blank\">@mahluo</a> </p>",
      "rawMarkdown": "# **Overview** \n\nThe final submission of us is a blend of three models with same architecture and different training data. Three models share the same pipline. We applied a two stage method for the competition.\n1. Training a bert model (Unixcoder) to get sentence embedding for each cell;\n2. Training a simple transformer with sentence embedding (or cell embedding) input.\n![](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F847605%2F80fe690c1982391400afb3cf290bd89e%2F1.png?generation=1669259314036608&alt=media)\n\n# **Our Code**: \nSubmit and training code : https://www.kaggle.com/code/qiaoshiji/fork-of-ai4code-infer-22e56e/data?scriptVersionId=103071263\n\n#**What Worked**\n1. Using unixcoder as first stage pretrained model. The inital score of different model is shown as following:\ncodebert 0.8226\ngraphcodebert 0.8482\nPlbart 0.8492\ncodet5 0.8475\nunixcoder 0.8594\n2. Pretrain first stage model using three different types of the task as following:\n- Randomly selecting N successive cells and training rerank task;\n- Randomly selecting one cell and predicting next cell;\n- Randomly selecting N successive cells and choosing one cell as query, rest as answer.\n3. Using longer sequence input in second stage, 512 code cells and 512 markdown cells for our final model\n4. Multi task for second stage model:\n- Position as regression task\n- The position of markdown between which two code cells\n- The number of markdown cells between every two code cells\n5. Using more data:\n- Raw data for model1\n- Raw data + ext data1 for model2\n- Raw data + ext data2 for model3\nExt data is from KGTorrent: https://github.com/collab-uniba/KGTorrent\n#**What Didn’t Work**\n1. Classify model as ensemble model\n2. Making group by the number of cells and training models for each group\n\n#**Important Citations**\n1. KGTorrent\nGithub: https://github.com/collab-uniba/KGTorrent\nPaper: https://arxiv.org/abs/2103.10558\n2. UniXcoder\nGithub: https://github.com/microsoft/CodeBERT/tree/master/UniXcoder#1-code-and-nl-embeddings\n#**Thanks and Acknowledgements**\nMany thanks to organizer for hosting such a great competition.\n\n#**Team Members**: \n@guoday \n@mahluo",
      "votes": null
    },
    {
      "id": "2041688",
      "postDate": "11/24/2022 06:06:14",
      "content": "<p>Hearty congratulations for the result and thanks for the detailed approach note and code. All the best to <a href=\"https://www.kaggle.com/qiaoshiji\" target=\"_blank\">@qiaoshiji</a>, <a href=\"https://www.kaggle.com/guoday\" target=\"_blank\">@guoday</a> and <a href=\"https://www.kaggle.com/mahluo\" target=\"_blank\">@mahluo</a>!</p>",
      "rawMarkdown": "Hearty congratulations for the result and thanks for the detailed approach note and code. All the best to @qiaoshiji, @guoday and @mahluo!",
      "votes": null
    },
    {
      "id": "2042835",
      "postDate": "11/25/2022 04:32:54",
      "content": "<p>Interesting unixcoder worked much better for you while it performed worse for a number of other teams.</p>",
      "rawMarkdown": "Interesting unixcoder worked much better for you while it performed worse for a number of other teams.",
      "votes": null
    },
    {
      "id": "2042936",
      "postDate": "11/25/2022 06:03:26",
      "content": "<p>great teammates 👍</p>",
      "rawMarkdown": "great teammates 👍",
      "votes": null
    },
    {
      "id": "2058074",
      "postDate": "12/07/2022 15:45:09",
      "content": "<p>For UniXcoder, you need to add prefix to use encoder-only model (i.e. <code>&lt;s&gt; &lt;encoder-only&gt; &lt;/s&gt; .... &lt;/s&gt;</code>). Otherwise, it will perform very bad.</p>",
      "rawMarkdown": "For UniXcoder, you need to add prefix to use encoder-only model (i.e. `<s> <encoder-only> </s> .... </s>`). Otherwise, it will perform very bad.",
      "votes": null
    }
  ],
  "comments": [
    {
      "id": 2041688,
      "author_name": "ravi20076",
      "author_url": "",
      "post_date": "11/24/2022 06:06:14",
      "content": "<p>Hearty congratulations for the result and thanks for the detailed approach note and code. All the best to <a href=\"https://www.kaggle.com/qiaoshiji\" target=\"_blank\">@qiaoshiji</a>, <a href=\"https://www.kaggle.com/guoday\" target=\"_blank\">@guoday</a> and <a href=\"https://www.kaggle.com/mahluo\" target=\"_blank\">@mahluo</a>!</p>",
      "votes": null,
      "replies": []
    },
    {
      "id": 2042835,
      "author_name": "dmytropoplavskiy",
      "author_url": "",
      "post_date": "11/25/2022 04:32:54",
      "content": "<p>Interesting unixcoder worked much better for you while it performed worse for a number of other teams.</p>",
      "votes": null,
      "replies": [
        {
          "id": 2058074,
          "author_name": "guoday",
          "author_url": "",
          "post_date": "12/07/2022 15:45:09",
          "content": "<p>For UniXcoder, you need to add prefix to use encoder-only model (i.e. <code>&lt;s&gt; &lt;encoder-only&gt; &lt;/s&gt; .... &lt;/s&gt;</code>). Otherwise, it will perform very bad.</p>",
          "votes": null,
          "replies": []
        }
      ]
    },
    {
      "id": 2042936,
      "author_name": "mahluo",
      "author_url": "",
      "post_date": "11/25/2022 06:03:26",
      "content": "<p>great teammates 👍</p>",
      "votes": null,
      "replies": []
    }
  ],
  "raw_markdown_by_id": {
    "2041536": "# **Overview** \n\nThe final submission of us is a blend of three models with same architecture and different training data. Three models share the same pipline. We applied a two stage method for the competition.\n1. Training a bert model (Unixcoder) to get sentence embedding for each cell;\n2. Training a simple transformer with sentence embedding (or cell embedding) input.\n![](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F847605%2F80fe690c1982391400afb3cf290bd89e%2F1.png?generation=1669259314036608&alt=media)\n\n# **Our Code**: \nSubmit and training code : https://www.kaggle.com/code/qiaoshiji/fork-of-ai4code-infer-22e56e/data?scriptVersionId=103071263\n\n#**What Worked**\n1. Using unixcoder as first stage pretrained model. The inital score of different model is shown as following:\ncodebert 0.8226\ngraphcodebert 0.8482\nPlbart 0.8492\ncodet5 0.8475\nunixcoder 0.8594\n2. Pretrain first stage model using three different types of the task as following:\n- Randomly selecting N successive cells and training rerank task;\n- Randomly selecting one cell and predicting next cell;\n- Randomly selecting N successive cells and choosing one cell as query, rest as answer.\n3. Using longer sequence input in second stage, 512 code cells and 512 markdown cells for our final model\n4. Multi task for second stage model:\n- Position as regression task\n- The position of markdown between which two code cells\n- The number of markdown cells between every two code cells\n5. Using more data:\n- Raw data for model1\n- Raw data + ext data1 for model2\n- Raw data + ext data2 for model3\nExt data is from KGTorrent: https://github.com/collab-uniba/KGTorrent\n#**What Didn’t Work**\n1. Classify model as ensemble model\n2. Making group by the number of cells and training models for each group\n\n#**Important Citations**\n1. KGTorrent\nGithub: https://github.com/collab-uniba/KGTorrent\nPaper: https://arxiv.org/abs/2103.10558\n2. UniXcoder\nGithub: https://github.com/microsoft/CodeBERT/tree/master/UniXcoder#1-code-and-nl-embeddings\n#**Thanks and Acknowledgements**\nMany thanks to organizer for hosting such a great competition.\n\n#**Team Members**: \n@guoday \n@mahluo",
    "2041688": "Hearty congratulations for the result and thanks for the detailed approach note and code. All the best to @qiaoshiji, @guoday and @mahluo!",
    "2042835": "Interesting unixcoder worked much better for you while it performed worse for a number of other teams.",
    "2042936": "great teammates 👍",
    "2058074": "For UniXcoder, you need to add prefix to use encoder-only model (i.e. `<s> <encoder-only> </s> .... </s>`). Otherwise, it will perform very bad."
  },
  "source": "meta"
}