If you like my work,please consider giving an upvote !
","metadata":{}},{"cell_type":"markdown","source":"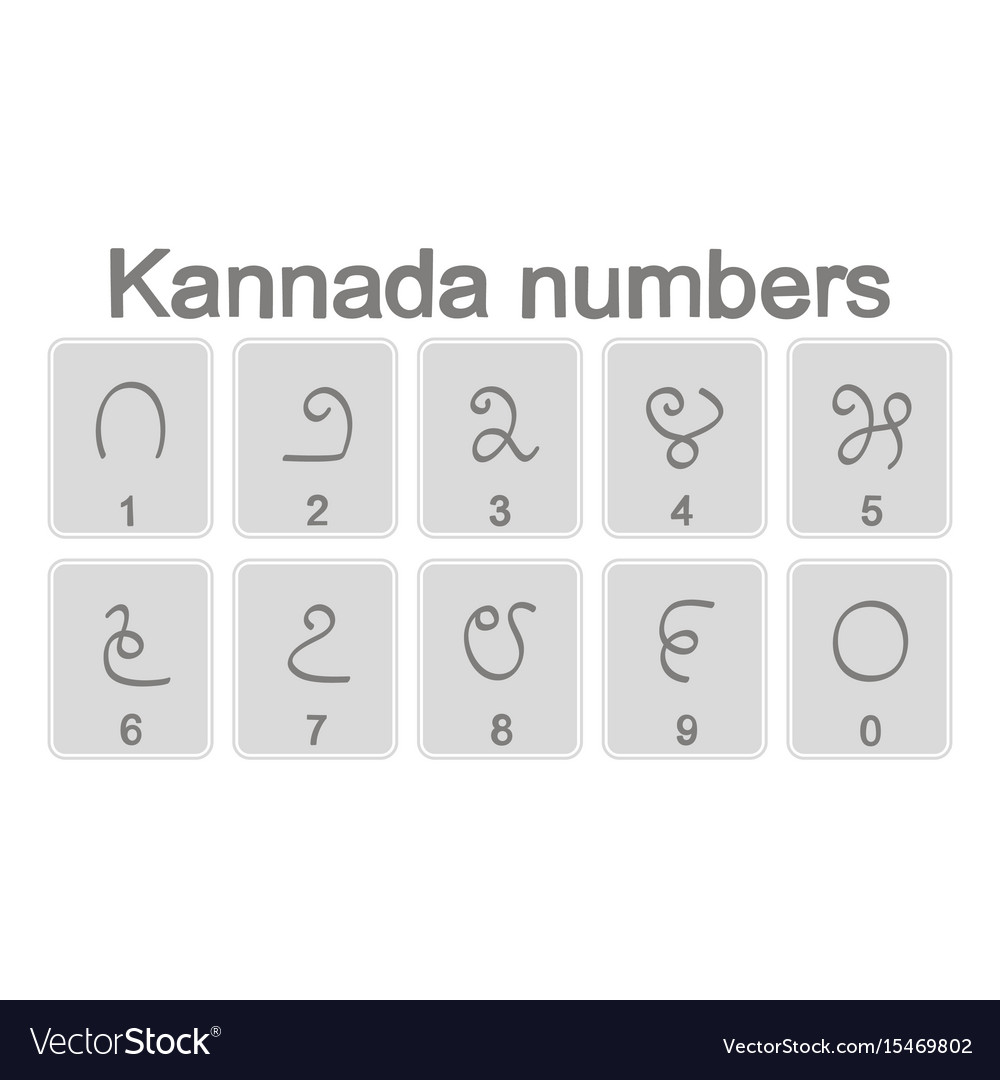","metadata":{}},{"cell_type":"markdown","source":"## Importing whatever we need !","metadata":{}},{"cell_type":"markdown","source":"We will mainly use 3 libraries.\n- **pandas :** It's used to handle our csv files.\n- **matplotlib & seaborn :** Used for charting and plotting.\n- **sklearn :** Popular ML library.We will use it for splitting our data.\n- **Keras :** Popular Deep learning library,we will use it to build our CNN Network.","metadata":{}},{"cell_type":"code","source":"import pandas as pd\nimport numpy as np\nimport matplotlib.pyplot as plt\nimport seaborn as sns\n\n\n\nfrom sklearn.model_selection import train_test_split\nfrom sklearn.metrics import confusion_matrix\n\nfrom keras.utils.np_utils import to_categorical\nfrom keras.preprocessing.image import ImageDataGenerator\nfrom keras.models import Sequential\nfrom keras.layers import Dense,Conv2D,Flatten,MaxPool2D,Dropout,BatchNormalization\nfrom keras.optimizers import RMSprop\nfrom keras.callbacks import ReduceLROnPlateau","metadata":{"_uuid":"d629ff2d2480ee46fbb7e2d37f6b5fab8052498a","_cell_guid":"79c7e3d0-c299-4dcb-8224-4455121ee9b0","trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Loading data","metadata":{}},{"cell_type":"code","source":"train=pd.read_csv('../input/Kannada-MNIST/train.csv')\ntest=pd.read_csv('../input/Kannada-MNIST/test.csv')\nsample_sub=pd.read_csv('../input/Kannada-MNIST/sample_submission.csv')","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Understanding the data ","metadata":{}},{"cell_type":"markdown","source":"Before jumping to all complex stuff about Convolutions and all,we will simply understand our data.We will learn and gain basic understanding about this data.","metadata":{}},{"cell_type":"code","source":"print('The Train dataset has {} rows and {} columns'.format(train.shape[0],train.shape[1]))\nprint('The Test dataset has {} rows and {} columns'.format(test.shape[0],test.shape[1]))\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train.head(3)","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Now you can see that there are 785 columns in the training dataset given.I will describe each one of them here...\n- **Label :** This contains the label which are going to predict.That is our target value.Here it is numbers from 0 to 9.We will plot a bar graph and see the distribution of this target value later.\n- **Pixel0 to Pixel783: **These are the pixel values of the image metrics.That is each row contains 28 * 28 = 784 (0-783 here) values here.Each one of these values indicates the pixel value at i x 28 + j th pixel position in the image metric.Simple !\n","metadata":{}},{"cell_type":"code","source":"test.head(3)\ntest=test.drop('id',axis=1)\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Checking Target class distribution..\n","metadata":{}},{"cell_type":"code","source":"y=train.label.value_counts()\nsns.barplot(y.index,y)","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Now we can see that all of the classes has equal distribution.There are 6000 examples of each numbers in kannada in the the training dataset.Cool !","metadata":{}},{"cell_type":"markdown","source":"## Data preparation ","metadata":{}},{"cell_type":"code","source":"X_train=train.drop('label',axis=1)\nY_train=train.label","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Normalize Pixel Values\n\nFor most image data, the pixel values are integers with values between 0 and 255.\n\nNeural networks process inputs using small weight values, and inputs with large integer values can disrupt or slow down the learning process. As such it is good practice to normalize the pixel values so that each pixel value has a value between 0 and 1.\n\nIt is valid for images to have pixel values in the range 0-1 and images can be viewed normally.\n\nThis can be achieved by dividing all pixels values by the largest pixel value; that is 255. This is performed across all channels, regardless of the actual range of pixel values that are present in the image.","metadata":{}},{"cell_type":"code","source":"X_train=X_train/255\ntest=test/255","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Reshape","metadata":{}},{"cell_type":"code","source":"X_train=X_train.values.reshape(-1,28,28,1)\ntest=test.values.reshape(-1,28,28,1)","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"print('The shape of train set now is',X_train.shape)\nprint('The shape of test set now is',test.shape)\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"All Set,We have our data reshape into 60000 examples of height 28 and width 28 and 1 channel.","metadata":{}},{"cell_type":"markdown","source":"### Encoding Target Values","metadata":{}},{"cell_type":"markdown","source":"Now we will encode our target value.Keras inbuild library to_categorical() is used to do the on-hot encoding.","metadata":{}},{"cell_type":"code","source":"Y_train=to_categorical(Y_train)","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Splitting train and test","metadata":{}},{"cell_type":"markdown","source":"Now we will split out training data into train and validation data.15percent of the training data will be used for validation purpose.","metadata":{}},{"cell_type":"code","source":"X_train,X_test,y_train,y_test=train_test_split(X_train,Y_train,random_state=42,test_size=0.15)","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plt.imshow(X_train[0][:,:,0])","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"It's Nine in Kannada\n","metadata":{}},{"cell_type":"markdown","source":"### More data !","metadata":{}},{"cell_type":"markdown","source":"In order to avoid overfitting problem, we need to expand artificially our handwritten digit dataset. We can make your existing dataset even larger. The idea is to alter the training data with small transformations to reproduce the variations occuring when someone is writing a digit.\n\nFor example, the number is not centered The scale is not the same (some who write with big/small numbers) The image is rotated...\n\nApproaches that alter the training data in ways that change the array representation while keeping the label the same are known as data augmentation techniques. Some popular augmentations people use are grayscales, horizontal flips, vertical flips, random crops, color jitters, translations, rotations, and much more.\n\nBy applying just a couple of these transformations to our training data, we can easily double or triple the number of training examples and create a very robust model.\n\n","metadata":{}},{"cell_type":"code","source":"datagen = ImageDataGenerator(\n featurewise_center=False, # set input mean to 0 over the dataset\n samplewise_center=False, # set each sample mean to 0\n featurewise_std_normalization=False, # divide inputs by std of the dataset\n samplewise_std_normalization=False, # divide each input by its std\n zca_whitening=False, # apply ZCA whitening\n rotation_range=10, # randomly rotate images in the range (degrees, 0 to 180)\n zoom_range = 0.1, # Randomly zoom image \n width_shift_range=0.1, # randomly shift images horizontally (fraction of total width)\n height_shift_range=0.1, # randomly shift images vertically (fraction of total height)\n horizontal_flip=False, # randomly flip images\n vertical_flip=False) # randomly flip images\n\n\ndatagen.fit(X_train)\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"For the data augmentation, i choosed to :\n\n - Randomly rotate some training images by 10 degrees\n - Randomly Zoom by 10% some training images\n - Randomly shift images horizontally by 10% of the width\n - Randomly shift images vertically by 10% of the height\n\nI did not apply a vertical_flip nor horizontal_flip since it could have lead to misclassify symetrical numbers such as 6 and 9.","metadata":{}},{"cell_type":"markdown","source":"## A breif Intro to CNN \n\nWe will first learn about the convolution operation\n**Edge Detection Example**\n\n\nSo, we take the first 3 X 3 matrix from the 6 X 6 image and multiply it with the filter. Now, the first element of the 4 X 4 output will be the sum of the element-wise product of these values, i.e. 10 x 1 + 10 x 0 + 10 x -1 + 10 x 1 + 10 x 0 + 10 x -1 + 10 x 1 + 10 x 0 + 10 x -1 = 0. To calculate the second element of the 4 X 4 output, we will shift our filter one step towards the right and again get the sum of the element-wise product.\nWe can see that after the entire operation the new matrix seperates the edges.\n### Padding\nwe can pad the image with an additional border, i.e., we add one pixel all around the edges. This means that the input will be an 8 X 8 matrix (instead of a 6 X 6 matrix). Applying convolution of 3 X 3 on it will result in a 6 X 6 matrix which is the original shape of the image. This is where padding comes to the fore:\n\n Input: n X n\n Padding: p\n Filter size: f X f\n Output: (n+2p-f+1) X (n+2p-f+1)\n\nThere are two common choices for padding:\n\n Valid: It means no padding. If we are using valid padding, the output will be (n-f+1) X (n-f+1)\n Same: Here, we apply padding so that the output size is the same as the input size, i.e.,\n n+2p-f+1 = n\n So, p = (f-1)/2\n\nWe now know how to use padded convolution. This way we don’t lose a lot of information and the image does not shrink either. Next, we will look at how to implement strided convolutions.\n\n### Pooling Layers\n\nPooling layers are generally used to reduce the size of the inputs and hence speed up the computation. Consider a 4 X 4 matrix as shown below:\n\nApplying max pooling on this matrix will result in a 2 X 2 output.\n\n\n### CNN Example\n\nWe’ll take things up a notch now. Let’s look at how a convolution neural network with convolutional and pooling layer works. Suppose we have an input of shape 32 X 32 X 3:\n\n\n\nThere are a combination of convolution and pooling layers at the beginning, a few fully connected layers at the end and finally a softmax classifier to classify the input into various categories. There are a lot of hyperparameters in this network which we have to specify as well.\n\nGenerally, we take the set of hyperparameters which have been used in proven research and they end up doing well. As seen in the above example, the height and width of the input shrinks as we go deeper into the network (from 32 X 32 to 5 X 5) and the number of channels increases (from 3 to 10).\n","metadata":{}},{"cell_type":"markdown","source":"### CNN\n\nI used the Keras Sequential API, where you have just to add one layer at a time, starting from the input.\n\nThe first is the convolutional (Conv2D) layer. It is like a set of learnable filters. I choosed to set 32 filters for the two firsts conv2D layers and 64 filters for the two last ones. Each filter transforms a part of the image (defined by the kernel size) using the kernel filter. The kernel filter matrix is applied on the whole image. Filters can be seen as a transformation of the image.\n\nThe CNN can isolate features that are useful everywhere from these transformed images (feature maps).\n\nThe second important layer in CNN is the pooling (MaxPool2D) layer. This layer simply acts as a downsampling filter. It looks at the 2 neighboring pixels and picks the maximal value. These are used to reduce computational cost, and to some extent also reduce overfitting. We have to choose the pooling size (i.e the area size pooled each time) more the pooling dimension is high, more the downsampling is important.\n\nCombining convolutional and pooling layers, CNN are able to combine local features and learn more global features of the image.\n\nDropout is a regularization method, where a proportion of nodes in the layer are randomly ignored (setting their wieghts to zero) for each training sample. This drops randomly a propotion of the network and forces the network to learn features in a distributed way. This technique also improves generalization and reduces the overfitting.\n\n'relu' is the rectifier (activation function max(0,x). The rectifier activation function is used to add non linearity to the network.\n\nThe Flatten layer is use to convert the final feature maps into a one single 1D vector. This flattening step is needed so that you can make use of fully connected layers after some convolutional/maxpool layers. It combines all the found local features of the previous convolutional layers.\n\nIn the end i used the features in two fully-connected (Dense) layers which is just artificial an neural networks (ANN) classifier. In the last layer(Dense(10,activation=\"softmax\")) the net outputs distribution of probability of each class.\n\n","metadata":{}},{"cell_type":"markdown","source":"## Modelling ","metadata":{}},{"cell_type":"code","source":"model = Sequential()\n\nmodel.add(Conv2D(filters = 32, kernel_size = (5,5),padding = 'Same', \n activation ='relu', input_shape = (28,28,1)))\nmodel.add(Conv2D(filters = 32, kernel_size = (5,5),padding = 'Same', \n activation ='relu'))\nmodel.add(BatchNormalization(momentum=.15))\nmodel.add(MaxPool2D(pool_size=(2,2)))\nmodel.add(Dropout(0.25))\n\n\nmodel.add(Conv2D(filters = 64, kernel_size = (3,3),padding = 'Same', \n activation ='relu'))\nmodel.add(Conv2D(filters = 64, kernel_size = (3,3),padding = 'Same', \n activation ='relu'))\nmodel.add(BatchNormalization(momentum=0.15))\nmodel.add(MaxPool2D(pool_size=(2,2), strides=(2,2)))\nmodel.add(Dropout(0.25))\n\nmodel.add(Conv2D(filters = 32, kernel_size = (5,5),padding = 'Same', \n activation ='relu', input_shape = (28,28,1)))\nmodel.add(Conv2D(filters = 32, kernel_size = (5,5),padding = 'Same', \n activation ='relu'))\nmodel.add(BatchNormalization(momentum=.15))\nmodel.add(MaxPool2D(pool_size=(2,2)))\nmodel.add(Dropout(0.25))\n\n\nmodel.add(Flatten())\nmodel.add(Dense(256, activation = \"relu\"))\nmodel.add(Dropout(0.5))\nmodel.add(Dense(10, activation = \"softmax\"))","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"model.summary()","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Optimizer\nIn simpler terms, optimizers shape and mold your model into its most accurate possible form by futzing with the weights. The loss function is the guide to the terrain, telling the optimizer when it’s moving in the right or wrong direction.\n\n","metadata":{}},{"cell_type":"code","source":"optimizer=RMSprop(lr=0.001,rho=0.9,decay=0.0)","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"model.compile(optimizer=optimizer,loss=['categorical_crossentropy'],metrics=['accuracy'])","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Learning rate reduction","metadata":{}},{"cell_type":"markdown","source":"In order to make the optimizer converge faster and closest to the global minimum of the loss function, i used an annealing method of the learning rate (LR).\n\nThe LR is the step by which the optimizer walks through the 'loss landscape'. The higher LR, the bigger are the steps and the quicker is the convergence. However the sampling is very poor with an high LR and the optimizer could probably fall into a local minima.\n\nIts better to have a decreasing learning rate during the training to reach efficiently the global minimum of the loss function.\n\nTo keep the advantage of the fast computation time with a high LR, i decreased the LR dynamically every X steps (epochs) depending if it is necessary (when accuracy is not improved).\n\nWith the ReduceLROnPlateau function from Keras.callbacks, i choose to reduce the LR by half if the accuracy is not improved after 3 epochs.","metadata":{}},{"cell_type":"code","source":"# Set a learning rate annealer\nlearning_rate_reduction = ReduceLROnPlateau(monitor='val_acc', \n patience=3, \n verbose=1, \n factor=0.5, \n min_lr=0.00001)","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Fitting our model ","metadata":{}},{"cell_type":"code","source":"epochs=20\nbatch_size=64","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# Fit the model\nhistory = model.fit_generator(datagen.flow(X_train,y_train, batch_size=batch_size),\n epochs = epochs, validation_data = (X_test,y_test),\n verbose = 2, steps_per_epoch=X_train.shape[0] // batch_size\n , callbacks=[learning_rate_reduction])","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Evaluating our approach ","metadata":{}},{"cell_type":"code","source":"fig,ax=plt.subplots(2,1)\nfig.set\nx=range(1,1+epochs)\nax[0].plot(x,history.history['loss'],color='red')\nax[0].plot(x,history.history['val_loss'],color='blue')\n\nax[1].plot(x,history.history['acc'],color='red')\nax[1].plot(x,history.history['val_acc'],color='blue')\nax[0].legend(['trainng loss','validation loss'])\nax[1].legend(['trainng acc','validation acc'])\nplt.xlabel('Number of epochs')\nplt.ylabel('accuracy')\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"We have plotted the performance of our model.We can see the number of epochs in the X axis and change in model performance in Y axis.","metadata":{}},{"cell_type":"markdown","source":"### Confusion matrix\n\nConfusion matrix can be pretty usefull when evaluating multiclass classifications.We can see which are classes are misclassified by our model clearly.","metadata":{}},{"cell_type":"code","source":"y_pre_test=model.predict(X_test)\ny_pre_test=np.argmax(y_pre_test,axis=1)\ny_test=np.argmax(y_test,axis=1)\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"conf=confusion_matrix(y_test,y_pre_test)\nconf=pd.DataFrame(conf,index=range(0,10),columns=range(0,10))\n\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"conf","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plt.figure(figsize=(8,6))\nsns.set(font_scale=1.4)#for label size\nsns.heatmap(conf, annot=True,annot_kws={\"size\": 16},cmap=plt.cm.Blues)# font size","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Here we can see that our model is doing a pretty good job in almost all digits.But it seems to have some confusions between \n- 0 and 1 : we can observe that some 0s and 1s are misclassified.\n- 7 and 6 : we can observe that some 6s and 7s are misclassifies.","metadata":{}},{"cell_type":"markdown","source":"## Further Investigation..\n\nWe will go on to see some of the misclassified images.We will simply inspect them to understand if it was a tough one to predict or not.Let's see...","metadata":{}},{"cell_type":"code","source":"x=(y_pre_test-y_test!=0).tolist()\nx=[i for i,l in enumerate(x) if l!=False]","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"fig,ax=plt.subplots(1,4,sharey=False,figsize=(15,15))\n\nfor i in range(4):\n ax[i].imshow(X_test[x[i]][:,:,0])\n ax[i].set_xlabel('Real {}, Predicted {}'.format(y_test[x[i]],y_pre_test[x[i]]))\n\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"hmm...Not all them,but some of them are a bit tough ones.","metadata":{}},{"cell_type":"markdown","source":"## Making a Submission \n","metadata":{}},{"cell_type":"code","source":"test=pd.read_csv('../input/Kannada-MNIST/test.csv')","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"test_id=test.id\n\ntest=test.drop('id',axis=1)\ntest=test/255\ntest=test.values.reshape(-1,28,28,1)\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"test.shape","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"We will make our prediction using our CNN model.","metadata":{}},{"cell_type":"code","source":"y_pre=model.predict(test) ##making prediction\ny_pre=np.argmax(y_pre,axis=1) ##changing the prediction intro labels","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"sample_sub['label']=y_pre\nsample_sub.to_csv('submission.csv',index=False)\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"sample_sub.head()","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n\n\nIf you like my kernel please consider upvoting it
\nDon't hesitate to give your suggestions in the comment section
\nThank you...
\n\n\n\n","metadata":{}}]}