
Many thanks to the organizers of the competition. Thanks to Vinay Uday Prabhu for providing dataset and an interesting article on arxive.org.
\n\nI used CNN architecture (+RMSProp,+ReduceLROnPlateau) from kernel of FWiktor (thanks a lot to him). This kernel has now ceased to be public. Here is the structure of this network:\n
Data augmentation was performed with these parameters:\n\nImageDataGenerator (rotation_range = 10,\nwidth_shift_range = 0.25,\nheight_shift_range = 0.25,\nshear_range = 0.1,\nzoom_range = 0.25,\nhorizontal_flip = False)\n
At first, three sets of weights w1, w2, w3 were generated:
\n\n1.
\n- 45 epochs, test_size = 0.05 -> w1\n- 60 epochs, test_size = 0.001 -> w2\n- 80 epochs, test_size = 0.0005 -> w3
Next, 2 more sets of weights were generated (w-pseudo, w-pseudo-corr ):
\n\n2a.
\n- ensemble 3 models w1+w2+w3\n- pseudo labelling (thanks a lot to Nandor Balogh) with threshold=0.95*3\n- 100 epochs, test size = 0.0005 -> w-pseudo
2b.\n- ensemble 3 models w1+w2+w3 \n- correction of posterior probabilities:\n\nresults [:, 4] = results [:, 4] - 0.7*3\nresults [:, 9] = results [:, 9] - 0.7*3\nresults [:, 1] = results [:, 1] - 0.7*3\nresults [:, 2] = results [:, 2] - 0.7*3\n\n- pseudo labelling with threshold=0.95*3\n- 100 epochs, test size = 0.0005 -> w-pseudo-corr
And at the end, calculation of two submissions:\n3a. without correction\n - ensemble 2 models: w3 + 3*w-pseudo -> submission -> 0.9918/0.9928
\n\n3b. with correction\n- ensemble 2 models: w-pseudo + w-pseudo_corr\n- correction of posterior probabilities:\n \n results[:,1] = results[:,1]*0.3\n results[:,2] = results[:,2]*0.2 \n- submission - > 0.9936/0.9952
\n results[:,9] = results[:,9]*0.05 \n
Later, I found on the Internet a number of articles where correction of posterior probabilities is applied. Here is one of them: A Posteriori Corrections to Classification Methods https://www.researchgate.net/publication/250423867_A_Posteriori_Corrections_to_Classification_Methods
", "comments": [ { "id": 698175, "author_name": "Solve for Fun", "author_url": "", "post_date": "2019-12-18T22:28:40.907000", "content": "@andreyzotov Thanks for sharing your approach. Congratulations for bagging one of the TOP 1% positions.
", "votes": 1, "replies": [] }, { "id": 698311, "author_name": "Ghost", "author_url": "", "post_date": "2019-12-19T04:00:05.430000", "content": "Thanks for sharing and Congratulations !\nAfter reading the paper and your answer, I still have some confusing part, sorry to bother you.
\n\nIt's about some details in correction of posterior probabilities.\nas I understand,\nif p(class0) = p(class1) = ... = p(class9) = 0.1 in training set\nand we assume pt(class0) = 0.097 ... pt(class9) = 0.105 in testing set.\nthe final correct output should be changed depend on p(class0)/pt(class0), the detail formula is in the paper.
\n\nhow to get these pt(class0~9)? the priority probability of test data? by our train model's output?
\n\nand another point is what does these -0.7 mean, are these related to the 2.2 portion of the paper you attached? the paper is a little hard to understand, I'm worry about I have some misunderstanding points.
", "votes": 2, "replies": [ { "id": 698395, "author_name": "Andrey Zotov", "author_url": "", "post_date": "2019-12-19T07:05:33.703000", "content": "I found corrections to the probabilities by experience, before I found any articles on this subject. It just turned out that such methods are used in real life - this was a discovery for me.
\n\nI assumed that the distribution of classes in train set and in test set should be the same. For example, if the frequency of class \"1\" is 0.1 (6000/60000) in train set,then my hypothesis is that a \"good\" classifier should predict 500 elements of class \"1\" from a public test set. At the same time, the classifier w1 + w2 + w3 predicted 525 elements of class “1”. Therefore, the idea came up to reduce the posterior probability for this class. And then you need to determine by what specific value you need to reduce this probability. I did it this way:\nresults [:,1] = results[:,1] -3 * 0.1 -> submission -> if the score has not decreased then check the new correction: 3 * 0.2, otherwise we stop the correction for class 1.
\n\nIn a sense, these corrections are additional hyperparameters. Of course there was a risk of getting an overfited model on a public test, so I used the 2nd approach \"without corrections\".
", "votes": 4, "replies": [] }, { "id": 698473, "author_name": "Ghost", "author_url": "", "post_date": "2019-12-19T09:41:33.883000", "content": "Oh! I understand, a good idea! Thanks for sharing!
", "votes": 0, "replies": [] }, { "id": 698474, "author_name": "", "author_url": "", "post_date": "2019-12-19T09:47:08.267000", "content": "", "votes": 0, "replies": [] } ] }, { "id": 2095540, "author_name": "Dương Bách", "author_url": "", "post_date": "2023-01-11T12:35:44.777000", "content": "thankiu for your solution
", "votes": 0, "replies": [] }, { "id": 1109851, "author_name": "Sharlto Cope", "author_url": "", "post_date": "2020-12-12T06:27:04.423000", "content": "Congratulation and thank you for sharing
", "votes": 0, "replies": [] }, { "id": 705908, "author_name": "Prince Gupta", "author_url": "", "post_date": "2019-12-29T16:54:19.587000", "content": "How did you figure out this architecture. Please tell me about your approach.
", "votes": 0, "replies": [] }, { "id": 705557, "author_name": "Anatoly Pavlov", "author_url": "", "post_date": "2019-12-29T03:38:54.123000", "content": "Congratulations! Very insightful explanation of the solution, thanks a lot.
", "votes": 0, "replies": [] }, { "id": 700615, "author_name": "corochann", "author_url": "", "post_date": "2019-12-22T10:05:23.983000", "content": "Congrats!
", "votes": 0, "replies": [] }, { "id": 698375, "author_name": "mtszkw", "author_url": "", "post_date": "2019-12-19T06:28:43.480000", "content": "What does 'threshold' stand for in case of pseudo labelling?
", "votes": 0, "replies": [ { "id": 698412, "author_name": "Andrey Zotov", "author_url": "", "post_date": "2019-12-19T07:36:43.097000", "content": "this is the threshold value of posterior probability. if the posterior probability was less than 0.95 (for three models less than 0.95 * 3) for the example from the test set, then such an example was not included in the extended train set.
", "votes": 3, "replies": [] }, { "id": 698432, "author_name": "mtszkw", "author_url": "", "post_date": "2019-12-19T08:09:11.437000", "content": "Oh, now I get it, thanks!
", "votes": 0, "replies": [] } ] }, { "id": 698002, "author_name": "MichaelP", "author_url": "", "post_date": "2019-12-18T16:51:51.537000", "content": "Very nice work Andrey. Even without the correction you were doing really well but the correction gave another big boost. Thanks for sharing.
", "votes": 0, "replies": [] }, { "id": 1368821, "author_name": "pavlovator", "author_url": "", "post_date": "2021-06-28T22:56:12.573000", "content": "Thanks for sharing!
", "votes": 0, "replies": [] }, { "id": 724524, "author_name": "Oliver Soptq", "author_url": "", "post_date": "2020-01-21T08:14:26.643000", "content": "Thanks for sharing!
", "votes": 0, "replies": [] }, { "id": 698262, "author_name": "liaodi", "author_url": "", "post_date": "2019-12-19T01:47:31.360000", "content": "thanks for sharing.
", "votes": 0, "replies": [] } ], "comment_count": 17, "messages": [ { "id": 697985, "postDate": "2019-12-18T16:21:32.190Z", "content": "Many thanks to the organizers of the competition. Thanks to Vinay Uday Prabhu for providing dataset and an interesting article on arxive.org.
\n\nI used CNN architecture (+RMSProp,+ReduceLROnPlateau) from kernel of FWiktor (thanks a lot to him). This kernel has now ceased to be public. Here is the structure of this network:\n
Data augmentation was performed with these parameters:\n\nImageDataGenerator (rotation_range = 10,\nwidth_shift_range = 0.25,\nheight_shift_range = 0.25,\nshear_range = 0.1,\nzoom_range = 0.25,\nhorizontal_flip = False)\n
At first, three sets of weights w1, w2, w3 were generated:
\n\n1.
\n- 45 epochs, test_size = 0.05 -> w1\n- 60 epochs, test_size = 0.001 -> w2\n- 80 epochs, test_size = 0.0005 -> w3
Next, 2 more sets of weights were generated (w-pseudo, w-pseudo-corr ):
\n\n2a.
\n- ensemble 3 models w1+w2+w3\n- pseudo labelling (thanks a lot to Nandor Balogh) with threshold=0.95*3\n- 100 epochs, test size = 0.0005 -> w-pseudo
2b.\n- ensemble 3 models w1+w2+w3 \n- correction of posterior probabilities:\n\nresults [:, 4] = results [:, 4] - 0.7*3\nresults [:, 9] = results [:, 9] - 0.7*3\nresults [:, 1] = results [:, 1] - 0.7*3\nresults [:, 2] = results [:, 2] - 0.7*3\n\n- pseudo labelling with threshold=0.95*3\n- 100 epochs, test size = 0.0005 -> w-pseudo-corr
And at the end, calculation of two submissions:\n3a. without correction\n - ensemble 2 models: w3 + 3*w-pseudo -> submission -> 0.9918/0.9928
\n\n3b. with correction\n- ensemble 2 models: w-pseudo + w-pseudo_corr\n- correction of posterior probabilities:\n \n results[:,1] = results[:,1]*0.3\n results[:,2] = results[:,2]*0.2 \n- submission - > 0.9936/0.9952
\n results[:,9] = results[:,9]*0.05 \n
Later, I found on the Internet a number of articles where correction of posterior probabilities is applied. Here is one of them: A Posteriori Corrections to Classification Methods https://www.researchgate.net/publication/250423867_A_Posteriori_Corrections_to_Classification_Methods
", "rawMarkdown": "Many thanks to the organizers of the competition. Thanks to Vinay Uday Prabhu for providing dataset and an interesting article on arxive.org.\n\n\nI used CNN architecture (+RMSProp,+ReduceLROnPlateau) from kernel of FWiktor (thanks a lot to him). This kernel has now ceased to be public. Here is the structure of this network:\n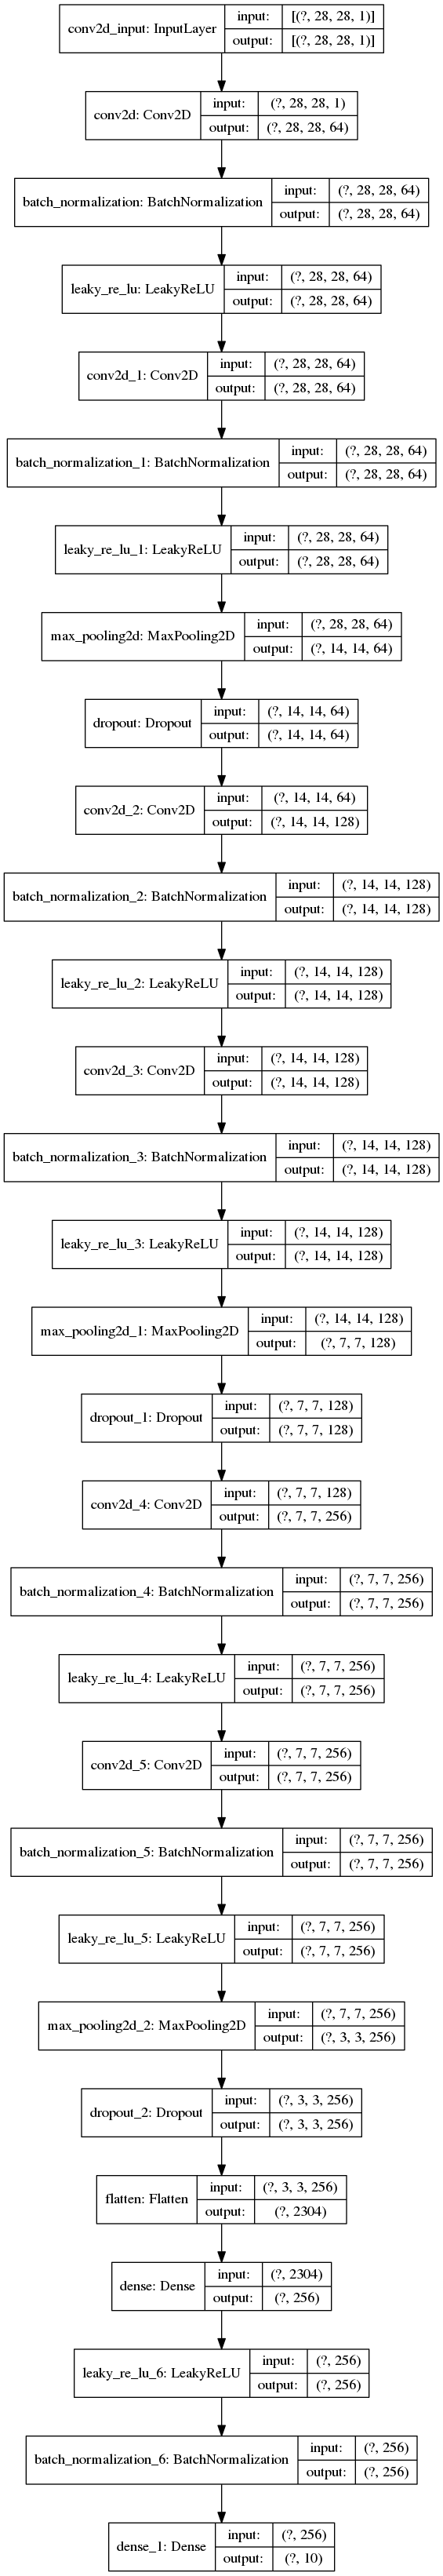\n\n\nData augmentation was performed with these parameters:\n```\nImageDataGenerator (rotation_range = 10,\nwidth_shift_range = 0.25,\nheight_shift_range = 0.25,\nshear_range = 0.1,\nzoom_range = 0.25,\nhorizontal_flip = False)\n```\n\nAt first, three sets of weights w1, w2, w3 were generated:\n\n**1.** \n- 45 epochs, test_size = 0.05 -> w1\n- 60 epochs, test_size = 0.001 -> w2\n- 80 epochs, test_size = 0.0005 -> w3\n\nNext, 2 more sets of weights were generated (w-pseudo, w-pseudo-corr ):\n\n**2a.** \n- ensemble 3 models w1+w2+w3\n- pseudo labelling (thanks a lot to Nandor Balogh) with threshold=0.95*3\n- 100 epochs, test size = 0.0005 -> w-pseudo\n\n\n**2b.**\n- ensemble 3 models w1+w2+w3 \n- correction of posterior probabilities:\n```\nresults [:, 4] = results [:, 4] - 0.7*3\nresults [:, 9] = results [:, 9] - 0.7*3\nresults [:, 1] = results [:, 1] - 0.7*3\nresults [:, 2] = results [:, 2] - 0.7*3\n```\n- pseudo labelling with threshold=0.95*3\n- 100 epochs, test size = 0.0005 -> w-pseudo-corr\n\nAnd at the end, calculation of two submissions:\n**3a.** without correction\n - ensemble 2 models: w3 + 3*w-pseudo -> submission -> 0.9918/0.9928\n\n**3b.** with correction\n- ensemble 2 models: w-pseudo + w-pseudo_corr\n- correction of posterior probabilities:\n ```\n results[:,1] = results[:,1]*0.3\n results[:,2] = results[:,2]*0.2 \n results[:,9] = results[:,9]*0.05 \n```\n- submission - > 0.9936/0.9952\n\n\n\nLater, I found on the Internet a number of articles where correction of posterior probabilities is applied. Here is one of them: A Posteriori Corrections to Classification Methods https://www.researchgate.net/publication/250423867_A_Posteriori_Corrections_to_Classification_Methods", "votes": 24 }, { "id": 698175, "postDate": "2019-12-18T22:28:40.907Z", "content": "@andreyzotov Thanks for sharing your approach. Congratulations for bagging one of the TOP 1% positions.
", "rawMarkdown": "@andreyzotov Thanks for sharing your approach. Congratulations for bagging one of the TOP 1% positions.", "votes": 1 }, { "id": 698311, "postDate": "2019-12-19T04:00:05.430Z", "content": "Thanks for sharing and Congratulations !\nAfter reading the paper and your answer, I still have some confusing part, sorry to bother you.
\n\nIt's about some details in correction of posterior probabilities.\nas I understand,\nif p(class0) = p(class1) = ... = p(class9) = 0.1 in training set\nand we assume pt(class0) = 0.097 ... pt(class9) = 0.105 in testing set.\nthe final correct output should be changed depend on p(class0)/pt(class0), the detail formula is in the paper.
\n\nhow to get these pt(class0~9)? the priority probability of test data? by our train model's output?
\n\nand another point is what does these -0.7 mean, are these related to the 2.2 portion of the paper you attached? the paper is a little hard to understand, I'm worry about I have some misunderstanding points.
", "rawMarkdown": "Thanks for sharing and Congratulations !\nAfter reading the paper and your answer, I still have some confusing part, sorry to bother you.\n\nIt's about some details in correction of posterior probabilities.\nas I understand,\n**if** p(class0) = p(class1) = ... = p(class9) = 0.1 in training set\n**and** we assume pt(class0) = 0.097 ... pt(class9) = 0.105 in testing set.\n**the final correct output** should be changed depend on p(class0)/pt(class0), the detail formula is in the paper.\n\nhow to get these pt(class0~9)? the priority probability of test data? by our train model's output? \n\nand another point is what does these -0.7 mean, are these related to the 2.2 portion of the paper you attached? the paper is a little hard to understand, I'm worry about I have some misunderstanding points.\n\n\n \n\n", "votes": 2, "replies": [ { "id": 698395, "postDate": "2019-12-19T07:05:33.703Z", "content": "I found corrections to the probabilities by experience, before I found any articles on this subject. It just turned out that such methods are used in real life - this was a discovery for me.
\n\nI assumed that the distribution of classes in train set and in test set should be the same. For example, if the frequency of class \"1\" is 0.1 (6000/60000) in train set,then my hypothesis is that a \"good\" classifier should predict 500 elements of class \"1\" from a public test set. At the same time, the classifier w1 + w2 + w3 predicted 525 elements of class “1”. Therefore, the idea came up to reduce the posterior probability for this class. And then you need to determine by what specific value you need to reduce this probability. I did it this way:\nresults [:,1] = results[:,1] -3 * 0.1 -> submission -> if the score has not decreased then check the new correction: 3 * 0.2, otherwise we stop the correction for class 1.
\n\nIn a sense, these corrections are additional hyperparameters. Of course there was a risk of getting an overfited model on a public test, so I used the 2nd approach \"without corrections\".
", "rawMarkdown": "I found corrections to the probabilities by experience, before I found any articles on this subject. It just turned out that such methods are used in real life - this was a discovery for me.\n\nI assumed that the distribution of classes in train set and in test set should be the same. For example, if the frequency of class \"1\" is 0.1 (6000/60000) in train set,then my hypothesis is that a \"good\" classifier should predict 500 elements of class \"1\" from a public test set. At the same time, the classifier w1 + w2 + w3 predicted 525 elements of class “1”. Therefore, the idea came up to reduce the posterior probability for this class. And then you need to determine by what specific value you need to reduce this probability. I did it this way:\nresults [:,1] = results[:,1] -3 * 0.1 -> submission -> if the score has not decreased then check the new correction: 3 * 0.2, otherwise we stop the correction for class 1.\n\nIn a sense, these corrections are additional hyperparameters. Of course there was a risk of getting an overfited model on a public test, so I used the 2nd approach \"without corrections\".", "votes": 4 }, { "id": 698473, "postDate": "2019-12-19T09:41:33.883Z", "content": "Oh! I understand, a good idea! Thanks for sharing!
", "rawMarkdown": "Oh! I understand, a good idea! Thanks for sharing!" }, { "id": 698474, "postDate": "2019-12-19T09:47:08.267Z", "rawMarkdown": "", "isDeleted": true } ] }, { "id": 2095540, "postDate": "2023-01-11T12:35:44.777Z", "content": "thankiu for your solution
", "rawMarkdown": "thankiu for your solution \n" }, { "id": 1109851, "postDate": "2020-12-12T06:27:04.423Z", "content": "Congratulation and thank you for sharing
", "rawMarkdown": "Congratulation and thank you for sharing" }, { "id": 705908, "postDate": "2019-12-29T16:54:19.587Z", "content": "How did you figure out this architecture. Please tell me about your approach.
", "rawMarkdown": "How did you figure out this architecture. Please tell me about your approach." }, { "id": 705557, "postDate": "2019-12-29T03:38:54.123Z", "content": "Congratulations! Very insightful explanation of the solution, thanks a lot.
", "rawMarkdown": "Congratulations! Very insightful explanation of the solution, thanks a lot." }, { "id": 700615, "postDate": "2019-12-22T10:05:23.983Z", "content": "Congrats!
", "rawMarkdown": "Congrats!" }, { "id": 698375, "postDate": "2019-12-19T06:28:43.480Z", "content": "What does 'threshold' stand for in case of pseudo labelling?
", "rawMarkdown": "What does 'threshold' stand for in case of pseudo labelling?", "replies": [ { "id": 698412, "postDate": "2019-12-19T07:36:43.097Z", "content": "this is the threshold value of posterior probability. if the posterior probability was less than 0.95 (for three models less than 0.95 * 3) for the example from the test set, then such an example was not included in the extended train set.
", "rawMarkdown": "this is the threshold value of posterior probability. if the posterior probability was less than 0.95 (for three models less than 0.95 * 3) for the example from the test set, then such an example was not included in the extended train set.", "votes": 3 }, { "id": 698432, "postDate": "2019-12-19T08:09:11.437Z", "content": "Oh, now I get it, thanks!
", "rawMarkdown": "Oh, now I get it, thanks!" } ] }, { "id": 698002, "postDate": "2019-12-18T16:51:51.537Z", "content": "Very nice work Andrey. Even without the correction you were doing really well but the correction gave another big boost. Thanks for sharing.
", "rawMarkdown": "Very nice work Andrey. Even without the correction you were doing really well but the correction gave another big boost. Thanks for sharing." }, { "id": 1368821, "postDate": "2021-06-28T22:56:12.573Z", "content": "Thanks for sharing!
", "rawMarkdown": "Thanks for sharing!" }, { "id": 724524, "postDate": "2020-01-21T08:14:26.643Z", "content": "Thanks for sharing!
", "rawMarkdown": "Thanks for sharing!" }, { "id": 698262, "postDate": "2019-12-19T01:47:31.360Z", "content": "thanks for sharing.
", "rawMarkdown": "thanks for sharing." } ], "complete": true, "source": "live", "fetched_at": "2026-10-19T11:36:01Z", "competition_id": 16017, "competition_slug": "Kannada-MNIST", "team_id": 3976738, "solution_url": "/competitions/Kannada-MNIST/writeups/andrey-zotov-2nd-place-solution" }