{"cells":[{"metadata":{},"cell_type":"markdown","source":"# ASHRAE - Great Energy Predictor III\n### *How much energy will a building consume?*\n\n----\n\n \n\n
\n\n### starter Content:\n\n> IMPORTANT : I will keep updating this starter kernel these days :)\n\n- EDA\n- Feature Engineering\n- Basic LGBM Model\n\n### References:\n\n- My baseline was **[Simple LGBM Solution](https://www.kaggle.com/ryches/simple-lgbm-solution)**, an amazing kernel by @ryches\n- My post [Must read material: similar comps, models, github ...](https://www.kaggle.com/c/ashrae-energy-prediction/discussion/112958#latest-650382)\n\n
"},{"metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"import numpy as np # linear algebra\nimport pandas as pd # data processing, CSV file I/O (e.g. pd.read_csv)\nimport os\nimport seaborn as sns\nimport matplotlib.pyplot as plt\nimport matplotlib.pyplot as pyplot\nimport gc\nfrom sklearn.preprocessing import LabelEncoder\nfrom sklearn.model_selection import KFold\nfrom sklearn.metrics import mean_squared_error, mean_squared_log_error\nimport lightgbm as lgb\nimport math\nfrom tqdm import tqdm_notebook as tqdm\nimport warnings\nwarnings.simplefilter(action='ignore', category=FutureWarning)\n\nPATH = '../input/ashrae-energy-prediction/'\n!ls ../input/ashrae-energy-prediction\n","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**Reduce Memory function**"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"#Based on this great kernel https://www.kaggle.com/arjanso/reducing-dataframe-memory-size-by-65\ndef reduce_mem_usage(df):\n start_mem_usg = df.memory_usage().sum() / 1024**2 \n print(\"Memory usage of properties dataframe is :\",start_mem_usg,\" MB\")\n NAlist = [] # Keeps track of columns that have missing values filled in. \n for col in df.columns:\n if df[col].dtype != object: # Exclude strings \n # Print current column type\n print(\"******************************\")\n print(\"Column: \",col)\n print(\"dtype before: \",df[col].dtype) \n # make variables for Int, max and min\n IsInt = False\n mx = df[col].max()\n mn = df[col].min()\n print(\"min for this col: \",mn)\n print(\"max for this col: \",mx)\n # Integer does not support NA, therefore, NA needs to be filled\n if not np.isfinite(df[col]).all(): \n NAlist.append(col)\n df[col].fillna(mn-1,inplace=True) \n \n # test if column can be converted to an integer\n asint = df[col].fillna(0).astype(np.int64)\n result = (df[col] - asint)\n result = result.sum()\n if result > -0.01 and result < 0.01:\n IsInt = True \n # Make Integer/unsigned Integer datatypes\n if IsInt:\n if mn >= 0:\n if mx < 255:\n df[col] = df[col].astype(np.uint8)\n elif mx < 65535:\n df[col] = df[col].astype(np.uint16)\n elif mx < 4294967295:\n df[col] = df[col].astype(np.uint32)\n else:\n df[col] = df[col].astype(np.uint64)\n else:\n if mn > np.iinfo(np.int8).min and mx < np.iinfo(np.int8).max:\n df[col] = df[col].astype(np.int8)\n elif mn > np.iinfo(np.int16).min and mx < np.iinfo(np.int16).max:\n df[col] = df[col].astype(np.int16)\n elif mn > np.iinfo(np.int32).min and mx < np.iinfo(np.int32).max:\n df[col] = df[col].astype(np.int32)\n elif mn > np.iinfo(np.int64).min and mx < np.iinfo(np.int64).max:\n df[col] = df[col].astype(np.int64) \n # Make float datatypes 32 bit\n else:\n df[col] = df[col].astype(np.float32)\n \n # Print new column type\n print(\"dtype after: \",df[col].dtype)\n print(\"******************************\")\n # Print final result\n print(\"___MEMORY USAGE AFTER COMPLETION:___\")\n mem_usg = df.memory_usage().sum() / 1024**2 \n print(\"Memory usage is: \",mem_usg,\" MB\")\n print(\"This is \",100*mem_usg/start_mem_usg,\"% of the initial size\")\n return df, NAlist","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**RMSLE calculation** "},{"metadata":{"trusted":true},"cell_type":"code","source":"def rmsle(y, y_pred):\n '''\n A function to calculate Root Mean Squared Logarithmic Error (RMSLE)\n source: https://www.kaggle.com/marknagelberg/rmsle-function\n '''\n assert len(y) == len(y_pred)\n terms_to_sum = [(math.log(y_pred[i] + 1) - math.log(y[i] + 1)) ** 2.0 for i,pred in enumerate(y_pred)]\n return (sum(terms_to_sum) * (1.0/len(y))) ** 0.5","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# from: https://www.kaggle.com/bejeweled/ashrae-catboost-regressor\ndef RMSLE(y_true, y_pred, *args, **kwargs):\n return np.sqrt(mean_squared_log_error(y_true, y_pred))","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# Data"},{"metadata":{"_uuid":"d629ff2d2480ee46fbb7e2d37f6b5fab8052498a","_cell_guid":"79c7e3d0-c299-4dcb-8224-4455121ee9b0","trusted":true},"cell_type":"code","source":"building_df = pd.read_csv(PATH+\"building_metadata.csv\")\nweather_train = pd.read_csv(PATH+\"weather_train.csv\")\ntrain = pd.read_csv(PATH+\"train.csv\")","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**building_meta.csv**\n- ```site_id``` - Foreign key for the weather files.\n- ```building_id``` - Foreign key for ```training.csv```\n- ```primary_use``` - Indicator of the primary category of activities for the building based on [EnergyStar property type definitions](https://www.energystar.gov/buildings/facility-owners-and-managers/existing-buildings/use-portfolio-manager/identify-your-property-type)\n- ```square_feet``` - Gross floor area of the building\n- ```year_built``` - Year building was opened\n- ```floor_count``` - Number of floors of the building\n"},{"metadata":{"trusted":true},"cell_type":"code","source":"building_df.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**weather_[train/test].csv**\n- ```site_id```\n- ```air_temperature``` - Degrees Celsius\n- ```cloud_coverage``` - Portion of the sky covered in clouds, in [oktas](https://en.wikipedia.org/wiki/Okta)\n- ```dew_temperature``` - Degrees Celsius\n- ```precip_depth_1_hr``` - Millimeters\n- ```sea_level_pressure``` - Millibar/hectopascals\n- ```wind_direction``` - Compass direction (0-360)\n- ```wind_speed``` - Meters per second\n"},{"metadata":{"trusted":true},"cell_type":"code","source":"weather_train.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**train.csv**\n- ```building_id``` - Foreign key for the building metadata.\n- ```meter``` - The meter id code. Read as ```{0: electricity, 1: chilledwater, 2: steam, hotwater: 3}```. Not every building has all meter types.\n- ```timestamp``` - When the measurement was taken\n- ```meter_reading``` - The target variable. Energy consumption in kWh (or equivalent). Note that this is real data with measurement error, which we expect will impose a baseline level of modeling error.\n"},{"metadata":{"trusted":true},"cell_type":"code","source":"train.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Prepare training and test"},{"metadata":{"trusted":true},"cell_type":"code","source":"train = train.merge(building_df, left_on = \"building_id\", right_on = \"building_id\", how = \"left\")\ntrain = train.merge(weather_train, left_on = [\"site_id\", \"timestamp\"], right_on = [\"site_id\", \"timestamp\"])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"#test = test.merge(weather_test, left_on = [\"timestamp\"], right_on = [\"timestamp\"])\n#del weather_test","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# Simple FE: Timestamp\n\n- **Break** ```timestamp``` into: year, month, day, weekday, hour."},{"metadata":{"trusted":true},"cell_type":"code","source":"train.timestamp[0]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"train[\"timestamp\"] = pd.to_datetime(train[\"timestamp\"])\ntrain[\"hour\"] = train[\"timestamp\"].dt.hour\ntrain[\"day\"] = train[\"timestamp\"].dt.day\ntrain[\"weekend\"] = train[\"timestamp\"].dt.weekday\ntrain[\"month\"] = train[\"timestamp\"].dt.month\ntrain[\"year\"] = train[\"timestamp\"].dt.year\nprint ('TRAIN: ', train.shape)\ntrain.head(3)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# EDA"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"train.head(8)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Dates\n\n**Train:** from ```2016-01-01 00:00:00``` to ```2016-12-31 23:00:00```\n\n**Test:** from ```'2017-01-01 00:00:00'``` to ```'2018-05-09 07:00:00'```"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"print ('START : ', train.timestamp[0] )\nprint ('END : ', train.timestamp[train.shape[0]-1])\nprint ('MONTHS :', train.month.unique())","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Missing data x Column"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"for col in train.columns:\n if train[col].isna().sum()>0:\n print (col,train[col].isna().sum())","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Meter type\n> Not every building has all meter types."},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"sns.countplot(x='meter', data=train).set_title('{0: electricity, 1: chilledwater, 2: steam, hotwater: 3}\\n\\n')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**Buildings with all meter types**: (building, site)\n\n```\n[(1232, 14), (1241, 14), (1249, 14), (1258, 14), (1259, 14), (1293, 14), (1294, 14), (1295, 14), (1296, 14), (1297, 14), (1298, 14), (1301, 14), (1331, 15)]\n```\n\nIf you want to check, just run the code bellow"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"'''\nbuilding_4 = []\nfor b in train.building_id.unique():\n cond = train[train.building_id==b]['meter'].nunique()\n place = train[train.building_id==b]['site_id'].unique()[0]\n if cond == 4:\n building_4.append((b,place))\n \nprint (building_4)\n'''","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Buildings and sites\n\nEach building is at only one site!"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"print ('We have {} buildings'.format(train.building_id.nunique()))\nprint ('We have {} sites'.format(train.site_id.nunique()))\nprint ('More information about each site ...')\nfor s in train.site_id.unique():\n print ('Site ',s, '\\tobservations: ', train[train.site_id == s].shape[0], '\\tNum of buildings: ',train[train.site_id == s].building_id.nunique())","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# Prove that each building is only at one site\nfor b in train.building_id.unique():\n if train[train.building_id == b].site_id.nunique() >1:\n print (train[train.building_id == b].site_id.nunique())","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**Top 5 consuming buildings**"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"top_buildings = train.groupby(\"building_id\")[\"meter_reading\"].mean().sort_values(ascending = False).iloc[:5]\nfor value in top_buildings.index:\n train[train[\"building_id\"] == value][\"meter_reading\"].rolling(window = 24).mean().plot()\n pyplot.title('Building {} at site: {}'.format(value,train[train[\"building_id\"] == value][\"site_id\"].unique()[0]))\n pyplot.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Old buildings\n\nI'm not an expert in the field but probably old buildings consume more!"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"print ('Buildings built before 1900: ', train[train.year_built <1900].building_id.nunique())\nprint ('Buildings built before 2000: ', train[train.year_built <2000].building_id.nunique())\nprint ('Buildings built after 2010: ', train[train.year_built >=2010].building_id.nunique())\nprint ('Buildings built after 2015: ', train[train.year_built >=2015].building_id.nunique())","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"build_corr = train[['building_id','year_built','meter_reading']].corr()\nprint (build_corr)\ndel build_corr","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### primary_use"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"fig, ax = pyplot.subplots(figsize=(10, 8))\nsns.countplot(y='primary_use', data=train)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"fig, ax = pyplot.subplots(figsize=(10, 8))\nsns.countplot(y='primary_use', data=train, hue= 'month')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## is site_id the key?"},{"metadata":{"trusted":true},"cell_type":"code","source":"train.groupby('site_id')['meter_reading'].describe()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**Click ```output``` to see the plots**"},{"metadata":{"trusted":true,"_kg_hide-input":true,"_kg_hide-output":true},"cell_type":"code","source":"for s in train.site_id.unique():\n train[train[\"site_id\"] == s].plot(\"timestamp\", \"meter_reading\")","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Consume x Site"},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"for s in train.site_id.unique():\n np.log1p(train[train['site_id']==s].meter_reading).plot.hist(figsize=(6, 4), bins=10, title='Dist. of Electricity Power Consumption on Site {}'.format(s))\n plt.xlabel('LOG Power (kWh)')\n plt.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Correlation plot"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"fig, ax = plt.subplots(figsize = (17,8))\ncorr = train.corr()\nax = sns.heatmap(corr, annot=True,\n xticklabels = corr.columns.values,\n yticklabels = corr.columns.values)\nplt.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# Understanding the target: meter_reading. \n\n```meter_reading``` - The target variable. Energy consumption in **kWh** (or equivalent). Note that this is real data with measurement error, which we expect will impose a baseline level of modeling error.\n\n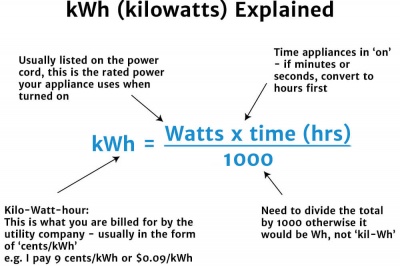\n\n**How do they measure this?**\n\n \n\n
\n### Differences between kWh and KW:\n\n \n\n\n\n
\n\n### Target = 0?\ncommented at the post: [what does 0.0 means in target variable](https://www.kaggle.com/c/ashrae-energy-prediction/discussion/113054#latest-651232)\n\nUnderstanding the difference between kW (Power) and kWh (energy), why don't some buildings consume (meter_reading ==0)? some reasons:\n- Those buildings don't consume energy (weird).\n- The stuff they use for measuring was broken.\n- **Missing data!** See the next example with the building ```0```. Spoiler: They started to measure Building ```0``` at June 2016! (month=6)"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"print ('Dataset with meter_reading = 0')\ndf0 = train[train.meter_reading==0]\nprint (df0.shape, df0.shape[0]/train.shape[0] ,'% of total data')\ndf0.head(3)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"Let's take the 1st day ```2016-01-01``` of the building ```0```"},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"# I only show from 0 to 12 am.\nprint ('Month with no consume: ', df0[(df0.building_id==0)].month.unique())\ndf0[(df0.building_id==0) & (df0.year== 2016) & (df0.month== 1) & (df0.day== 1)].head(12)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"The months: 1 to 5 the building ```0``` didn't consume nothing!\nLet's see the followinf months (6 to 12):"},{"metadata":{"trusted":true},"cell_type":"code","source":"train[(train.building_id==0) & (train.year== 2016) & (train.month== 6) & (train.day== 1)].head(2)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"train[(train.building_id==0) & (train.year== 2016) & (train.month== 12) & (train.day== 1)].head(2)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Conclusion\nThey started to measure Building ```0``` at June 2016! (month=6)\n\nIn my opinion they started to measure the consume of that specific building in June 2016.\nIn order to complete the database from 2016, they filled the other months with 0.\nNote that they can do it because the meteorological variables aren't a problem, you can access to historical data from external sources, and other variables about the building are constant like the year_built, how big is the building, floors etc… And that's why they could create the database and include new buildings since 2016 :)"},{"metadata":{"trusted":true},"cell_type":"code","source":"# dirty and fast\nbuild_info = pd.DataFrame (columns = ['building_id', 'start'])\ninfo = [] # (building, start)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"for b in tqdm(train.building_id.unique()):\n if b in df0.building_id.unique():\n start = df0[(df0.building_id==b) & (df0.meter_reading==0)]['month'].unique()[-1]+1\n info.append((b, start))\n else:\n # those buildings with no metric_reading=0 --> they have measurements from 2016-1-1\n info.append((b, 1))","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-output":false,"trusted":true},"cell_type":"code","source":"build_info ['building_id'] = [x[0] for x in info]\nbuild_info ['start'] = [x[1] for x in info]\nbuild_info.head()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"print (build_info[build_info.start == 1].shape)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"build_info[build_info.start == 13].shape\nbuild_info[build_info.start == 13].head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**This is not right yest!**"},{"metadata":{"trusted":true},"cell_type":"code","source":"build_info.to_csv('build_info.csv', index=False)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**Buildings where the proportion of missing >= 0.5**\n\n> 53, 799, 815 , 817 , 853 , 857 , 1113 , 1221 , 754 , 954 , 1446 , 783\n\n"},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"# Buildings where the proportion of missing >= 0.5\n\n'''\nfor build in tqdm(train.building_id.unique()):\n a = train[(train.building_id==build) & (train.meter_reading==0)].shape[0] \n b = train[(train.building_id==build)].shape[0]\n if a/b >= 0.5:\n print (build)\n'''","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"trusted":true},"cell_type":"code","source":"del df0\ngc.collect()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"
\n# Training"},{"metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"trusted":true},"cell_type":"code","source":"del weather_train, building_df\ngc.collect()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**Delete time stamp and encode ```primary_use```**"},{"metadata":{"trusted":true},"cell_type":"code","source":"train = train.drop(\"timestamp\", axis = 1)\nle = LabelEncoder()\ntrain[\"primary_use\"] = le.fit_transform(train[\"primary_use\"])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"train.head(3)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"\ncategoricals = [\"building_id\", \"primary_use\", \"hour\", \"day\", \"weekend\", \"month\", \"meter\", 'year']\n\ndrop_cols = [\"precip_depth_1_hr\", \"sea_level_pressure\", \"wind_direction\", \"wind_speed\"]\n\nnumericals = [\"square_feet\", \"year_built\", \"air_temperature\", \"cloud_coverage\",\n \"dew_temperature\"]\n\nfeat_cols = categoricals + numericals","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"target = np.log1p(train[\"meter_reading\"])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"train = train.drop(drop_cols + [\"site_id\",\"floor_count\",\"meter_reading\"], axis = 1)\n#train.fillna(-999, inplace=True)\ntrain.head()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_kg_hide-output":true},"cell_type":"code","source":"train, NAlist = reduce_mem_usage(train)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Validation"},{"metadata":{},"cell_type":"markdown","source":"**Initial features**"},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"# Features\nprint (train.shape)\ntrain[feat_cols].head(3)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# target = np.log1p(train[\"meter_reading\"])\n# raw_target = np.expm1(target)","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"num_folds = 5\nkf = KFold(n_splits = num_folds, shuffle = True, random_state = 42)\nerror = 0\n\nfor fold, (train_index, val_index) in enumerate(kf.split(train, target)):\n\n print ('Training FOLD ',fold,'\\n')\n print('Train index:','\\tfrom:',train_index.min(),'\\tto:',train_index.max())\n print('Valid index:','\\tfrom:',val_index.min(),'\\tto:',val_index.max(),'\\n')\n \n train_X = train[feat_cols].iloc[train_index]\n val_X = train[feat_cols].iloc[val_index]\n train_y = target.iloc[train_index]\n val_y = target.iloc[val_index]\n lgb_train = lgb.Dataset(train_X, train_y)\n lgb_eval = lgb.Dataset(val_X, val_y)\n \n params = {\n 'boosting_type': 'gbdt',\n 'objective': 'regression',\n 'metric': {'rmse'},\n 'learning_rate': 0.1,\n 'feature_fraction': 0.9,\n 'bagging_fraction': 0.9\n }\n \n gbm = lgb.train(params,\n lgb_train,\n num_boost_round=2000,\n valid_sets=(lgb_train, lgb_eval),\n early_stopping_rounds=20,\n verbose_eval = 20)\n\n y_pred = gbm.predict(val_X, num_iteration=gbm.best_iteration)\n error += np.sqrt(mean_squared_error(y_pred, (val_y)))/num_folds\n \n print('\\nFold',fold,' Score: ',np.sqrt(mean_squared_error(y_pred, val_y)))\n #print('RMSLE: ', rmsle(y_pred, val_y))\n #print('RMSLE_2: ', np.sqrt(mean_squared_log_error(y_pred, (val_y))))\n\n del train_X, val_X, train_y, val_y, lgb_train, lgb_eval\n gc.collect()\n\n print (20*'---')\n break\n \nprint('CV error: ',error)\n","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"trusted":true},"cell_type":"code","source":"# memory allocation\ndel train, target\ngc.collect()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Plot importance"},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"import matplotlib.pyplot as plt\nfeature_imp = pd.DataFrame(sorted(zip(gbm.feature_importance(), gbm.feature_name()),reverse = True), columns=['Value','Feature'])\nplt.figure(figsize=(10, 5))\nsns.barplot(x=\"Value\", y=\"Feature\", data=feature_imp.sort_values(by=\"Value\", ascending=False))\nplt.title('LightGBM Features (avg over folds)')\nplt.tight_layout()\nplt.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Prepare Test"},{"metadata":{"trusted":true},"cell_type":"code","source":"#preparing test data\nbuilding_df = pd.read_csv(PATH+\"building_metadata.csv\")\ntest = pd.read_csv(\"../input/ashrae-energy-prediction/test.csv\")\ntest = test.merge(building_df, left_on = \"building_id\", right_on = \"building_id\", how = \"left\")\ndel building_df\ngc.collect()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"weather_test = pd.read_csv(\"../input/ashrae-energy-prediction/weather_test.csv\")\nweather_test = weather_test.drop(drop_cols, axis = 1)\ntest = test.merge(weather_test, left_on = [\"site_id\", \"timestamp\"], right_on = [\"site_id\", \"timestamp\"], how = \"left\")\ndel weather_test\ngc.collect()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"test.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**Reduce Memory**"},{"metadata":{"_kg_hide-output":true,"trusted":true},"cell_type":"code","source":"test[\"primary_use\"] = le.transform(test[\"primary_use\"])\ntest, NAlist = reduce_mem_usage(test)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"**Change dates type**"},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"test[\"timestamp\"] = pd.to_datetime(test[\"timestamp\"])\ntest[\"hour\"] = test[\"timestamp\"].dt.hour.astype(np.uint8)\ntest[\"day\"] = test[\"timestamp\"].dt.day.astype(np.uint8)\ntest[\"weekend\"] = test[\"timestamp\"].dt.weekday.astype(np.uint8)\ntest[\"month\"] = test[\"timestamp\"].dt.month.astype(np.uint8)\ntest[\"year\"] = test[\"timestamp\"].dt.year.astype(np.uint8)\ntest = test[feat_cols]\ntest.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Inference"},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"from tqdm import tqdm\ni=0\nres=[]\nstep_size = 50000 \nfor j in tqdm(range(int(np.ceil(test.shape[0]/50000)))):\n res.append(np.expm1(gbm.predict(test.iloc[i:i+step_size])))\n i+=step_size","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_kg_hide-input":true,"_kg_hide-output":true},"cell_type":"code","source":"del test\ngc.collect()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# Submission"},{"metadata":{"trusted":true,"_kg_hide-input":true},"cell_type":"code","source":"res = np.concatenate(res)\nsub = pd.read_csv(PATH+\"sample_submission.csv\")\nsub[\"meter_reading\"] = res\nsub.to_csv(\"submission.csv\", index = False)\nsub.head(10)","execution_count":null,"outputs":[]}],"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat":4,"nbformat_minor":1}