
Our team finished 2nd on private LB (12th on public). The private LB is finally released officially.
\n\nSo happy and pumped up for winning in the money for the first time on Kaggle (after 6 years). Santa has been kind this year :-)\nOur team will be kind too and share our complete solution.
\n\n
XGB: XGBoost\nLGBM: LightGBM\nCB: Catboost\nFFNN: Feed-forward Neural Network
\n\nFinal Ensemble (approximate): 30% XGB-bagging + 50% LGBM-bagging + 15% CB-bagging + 5% FFNN
\n\nMany variations of XGB, LGBM, CB were bagged: at site+meter level, at building+meter level, at building-type+meter level. Bagged XGB gave the best results among the boosting methods.
\n\nFFNN was used only for meter = 0.\nIt gave very poor results for other meters and didn't add value to ensemble.\nAlso, FFNN was very poor for site-14 so we didn't use it and hence that tile is missing from the models section in the architecture diagram :-)
\n\nOur solution was built heavily on @oleg90777 's base XGB/LGBM setup (which scores 1.04 on LB without leak) and our key points were cleaning the data and post-processing the predictions (validated on leaked data and LB). Read more about it here.
\n\nThe final ensemble scores almost the best on public LB, on leaked data as well as private LB, so hopefully it is robust and useful.
\n\nA lot of the low values of the target variable seem to be noise (as discussed multiple times in the forums, specifically for site-0) and removing these rows from the training data gives a good boost in score which has been done by several other competitors too.
\n\nIt was the most time consuming task as we visualized and wrote code to remove these rows for each of the 1449 buildings manually. We could have used a set of heuristics but that is not optimal due to some edge cases so we just decided to spend few minutes on every building and remove the outliers.
\n\nDue to the size of the dataset and difficulty in setting up a robust validation framework, we did not focus much on feature engineering, fearing it might not extrapolate cleanly to the test data. Instead we chose to ensemble as many different models as possible to capture more information and help the predictions to be stable across years.
\n\nOur models barely use any lag features or complex features. We have less than 30 features in our best single model. This was one of the major decisions taken at the beginning of our work. From past experience it is tricky to build good features without a reliable validation framework.
\n\nWe bagged a bunch of boosting models XGB, LGBM, CB at various levels of data: Models for every site+meter, models for every building+meter, models for every building-type+meter and models using entire train data. It was very useful to build a separate model for each site so that the model could capture site-specific patterns and each site could be fitted with a different parameter set suitable for it. It also automatically solved for issues like timestamp alignment and feature measurement scale being different across sites so we didn't have to solve for them separately.
\n\nEnsembling models at different levels were useful to improve score. Just bagging with different seeds didn't help much.
\n\nSite-level FFNN was used only for meter = 0. Each site had a different NN architecture.\nIt gave very poor results for other meters and didn't add value to ensemble.\nAlso, FFNN was very poor for site-14 so we didn't use it and hence that tile is missing from the models section in the architecture diagram :-)
\n\nFor tuning of all models, we used a combination of 4-fold and 5-fold CV on month from training data as well as validation on leaked data.
\n\nWe have shared our post-processing experiments in another thread: https://www.kaggle.com/c/ashrae-energy-prediction/discussion/123528
\n\nSince we remove a lot of low value observations from training data, it artificially increases the mean of the target variable and hence the model's raw predictions on test data also has an inflated mean. Since RMSE is optimal at true mean value, reducing the mean of predictions of test data by a reducing factor helps bring it down to its true mean, thus improving score.
\n\nWe tried a range of post-processing values and finally ended up using 0.8 - 0.85 for most models.
\n\nOur best single type model was XGB but LGBM was very close and CB was not very bad either. All scored in the range of 1.04 - 1.06 on the public LB without leak.
\n\nSince FFNN was built only for meter = 0, we ensembled differently for every site+meter combination using a weighted average where the weights were determined using a combination of CV score, LB score, Leak score and intuition.
\n\nFinal Ensemble (approximate) for meter = 0: 30% XGB-bagging + 50% LGBM-bagging + 15% CB-bagging + 5% FFNN\nFinal Ensemble (approximate) for meters 1, 2, 3: 30% XGB-bagging + 50% LGBM-bagging + 20% CB-bagging
\n\nThe final ensemble scores almost the best on public LB, on leaked data as well as private LB, so hopefully it is robust and useful.
\n\nWe used leak data primarily for local validation and for inserting into the test data as many competitors did. We didn't use any leaks outside of sites 0, 1, 2, 4, 15.
\n\nSince our core models were at site+meter level, we didn't explore leveraging the leaked data as additional train data.
\n\nShout out to my cHaOs team-mates @oleg90777 (one of the best team leaders I've worked with), @berserker408 and @isanton.
\n\nWe will be happy to share our entire code if ASHRAE / Kaggle can confirm if we can. No timeline / commitment on this.
\n\nOur team finished 2nd on private LB (12th on public). The private LB is finally released officially.
\n\nSo happy and pumped up for winning in the money for the first time on Kaggle (after 6 years). Santa has been kind this year :-)\nOur team will be kind too and share our complete solution.
\n\n
XGB: XGBoost\nLGBM: LightGBM\nCB: Catboost\nFFNN: Feed-forward Neural Network
\n\nFinal Ensemble (approximate): 30% XGB-bagging + 50% LGBM-bagging + 15% CB-bagging + 5% FFNN
\n\nMany variations of XGB, LGBM, CB were bagged: at site+meter level, at building+meter level, at building-type+meter level. Bagged XGB gave the best results among the boosting methods.
\n\nFFNN was used only for meter = 0.\nIt gave very poor results for other meters and didn't add value to ensemble.\nAlso, FFNN was very poor for site-14 so we didn't use it and hence that tile is missing from the models section in the architecture diagram :-)
\n\nOur solution was built heavily on @oleg90777 's base XGB/LGBM setup (which scores 1.04 on LB without leak) and our key points were cleaning the data and post-processing the predictions (validated on leaked data and LB). Read more about it here.
\n\nThe final ensemble scores almost the best on public LB, on leaked data as well as private LB, so hopefully it is robust and useful.
\n\nA lot of the low values of the target variable seem to be noise (as discussed multiple times in the forums, specifically for site-0) and removing these rows from the training data gives a good boost in score which has been done by several other competitors too.
\n\nIt was the most time consuming task as we visualized and wrote code to remove these rows for each of the 1449 buildings manually. We could have used a set of heuristics but that is not optimal due to some edge cases so we just decided to spend few minutes on every building and remove the outliers.
\n\nDue to the size of the dataset and difficulty in setting up a robust validation framework, we did not focus much on feature engineering, fearing it might not extrapolate cleanly to the test data. Instead we chose to ensemble as many different models as possible to capture more information and help the predictions to be stable across years.
\n\nOur models barely use any lag features or complex features. We have less than 30 features in our best single model. This was one of the major decisions taken at the beginning of our work. From past experience it is tricky to build good features without a reliable validation framework.
\n\nWe bagged a bunch of boosting models XGB, LGBM, CB at various levels of data: Models for every site+meter, models for every building+meter, models for every building-type+meter and models using entire train data. It was very useful to build a separate model for each site so that the model could capture site-specific patterns and each site could be fitted with a different parameter set suitable for it. It also automatically solved for issues like timestamp alignment and feature measurement scale being different across sites so we didn't have to solve for them separately.
\n\nEnsembling models at different levels were useful to improve score. Just bagging with different seeds didn't help much.
\n\nSite-level FFNN was used only for meter = 0. Each site had a different NN architecture.\nIt gave very poor results for other meters and didn't add value to ensemble.\nAlso, FFNN was very poor for site-14 so we didn't use it and hence that tile is missing from the models section in the architecture diagram :-)
\n\nFor tuning of all models, we used a combination of 4-fold and 5-fold CV on month from training data as well as validation on leaked data.
\n\nWe have shared our post-processing experiments in another thread: https://www.kaggle.com/c/ashrae-energy-prediction/discussion/123528
\n\nSince we remove a lot of low value observations from training data, it artificially increases the mean of the target variable and hence the model's raw predictions on test data also has an inflated mean. Since RMSE is optimal at true mean value, reducing the mean of predictions of test data by a reducing factor helps bring it down to its true mean, thus improving score.
\n\nWe tried a range of post-processing values and finally ended up using 0.8 - 0.85 for most models.
\n\nOur best single type model was XGB but LGBM was very close and CB was not very bad either. All scored in the range of 1.04 - 1.06 on the public LB without leak.
\n\nSince FFNN was built only for meter = 0, we ensembled differently for every site+meter combination using a weighted average where the weights were determined using a combination of CV score, LB score, Leak score and intuition.
\n\nFinal Ensemble (approximate) for meter = 0: 30% XGB-bagging + 50% LGBM-bagging + 15% CB-bagging + 5% FFNN\nFinal Ensemble (approximate) for meters 1, 2, 3: 30% XGB-bagging + 50% LGBM-bagging + 20% CB-bagging
\n\nThe final ensemble scores almost the best on public LB, on leaked data as well as private LB, so hopefully it is robust and useful.
\n\nWe used leak data primarily for local validation and for inserting into the test data as many competitors did. We didn't use any leaks outside of sites 0, 1, 2, 4, 15.
\n\nSince our core models were at site+meter level, we didn't explore leveraging the leaked data as additional train data.
\n\nShout out to my cHaOs team-mates @oleg90777 (one of the best team leaders I've worked with), @berserker408 and @isanton.
\n\nWe will be happy to share our entire code if ASHRAE / Kaggle can confirm if we can. No timeline / commitment on this.
\n\nCongratulations to our second-place team!!!!!! 🙌 💪 👍 👊 Their solution will be organized and added to the other top five winners in a publication and open-source repository. Please stay tuned!
\n\nAlso, for everyone else, we are in the process of curating a directory of Notebooks for building performance engineers and analysts from the competition that will serve as a recipe book for beginners as well as experts who are curious to learn about certain topics. We highly encourage you all to share your solutions as a notebook for this purpose. We will acknowledge the authors of all notebooks in this process, so please annotate your notebook or profile with how you would like to be acknowledged. It would also be helpful if you could indicate whether you are an ASHRAE member.
", "rawMarkdown": "Congratulations to our second-place team!!!!!! 🙌 💪 👍 👊 Their solution will be organized and added to the other top five winners in a publication and open-source repository. Please stay tuned! \n\n**Also, for everyone else, we are in the process of curating a directory of Notebooks for building performance engineers and analysts from the competition that will serve as a recipe book for beginners as well as experts who are curious to learn about certain topics. We highly encourage you all to share your solutions as a notebook for this purpose. We will acknowledge the authors of all notebooks in this process, so please annotate your notebook or profile with how you would like to be acknowledged. It would also be helpful if you could indicate whether you are an ASHRAE member.**", "votes": 3 }, { "id": 705110, "postDate": "2019-12-28T12:50:16.897Z", "content": "Congrats! Nice ensembling :)
", "rawMarkdown": "Congrats! Nice ensembling :) ", "votes": 3 }, { "id": 705036, "postDate": "2019-12-28T10:22:10.923Z", "content": "Congratulations! According to:\nhttps://www.kaggle.com/sohier/ashrae-interim-scores#final_all_scores.csv
\n\nYou had 6 submissions at 1.22 so your team is the best even if you've selected ones at 1.23. Only Btbpanda had one submission better (but they don't selected it).
", "rawMarkdown": "Congratulations! According to:\nhttps://www.kaggle.com/sohier/ashrae-interim-scores#final_all_scores.csv\n\nYou had 6 submissions at 1.22 so your team is the best even if you've selected ones at 1.23. Only Btbpanda had one submission better (but they don't selected it).", "votes": 3 }, { "id": 705706, "postDate": "2019-12-29T10:21:21.263Z", "content": "Congratulations! :D
\n\n\n\n\nRemove noise (Very important)
\n
This time removing the noise got you to the prize zone! 😁
\n\nA little context for everyone, from H2O.ai's GrandMaster Panel
\n\n\n", "rawMarkdown": "Congratulations! :D\n\n> Remove noise (Very important)\n\nThis time removing the noise got you to the prize zone! 😁\n\nA little context for everyone, [from H2O.ai's GrandMaster Panel](https://www.h2o.ai/blog/takeaways-from-the-worlds-largest-kaggle-grandmaster-panel/)\n\n> Q: Any mistakes or Regrets from a competition?\n@rohanrao advises looking at outliers, based on a competition where removing just ONE outlier would have landed him 1st position.\n\n", "votes": 4 }, { "id": 852791, "postDate": "2020-05-18T17:20:10.107Z", "content": "Q: Any mistakes or Regrets from a competition?\n @rohanrao advises looking at outliers, based on a competition where removing just ONE outlier would have landed him 1st position.
\n
Congratulations!\nMany competitors mentioned leak data. I am new for machine learning. Can you explain what's the meaning of 'leak data' in this competition?
", "rawMarkdown": "Congratulations!\nMany competitors mentioned leak data. I am new for machine learning. Can you explain what's the meaning of 'leak data' in this competition?", "votes": 1, "replies": [ { "id": 853618, "postDate": "2020-05-19T10:36:36.567Z", "content": "Hello, that means part of public and private labels were in the internet. So if you take that labels you would have for a part of data accuracy of 100%
", "rawMarkdown": "Hello, that means part of public and private labels were in the internet. So if you take that labels you would have for a part of data accuracy of 100%" } ] }, { "id": 757003, "postDate": "2020-02-26T10:29:41.320Z", "content": "Thank you for the well explained solution and congratulations with the second place!\nHow did you define outliers for each building? Was it an individual and mostly visual approach or a more standardised one like e.g. based on IQR or similar?
", "rawMarkdown": "Thank you for the well explained solution and congratulations with the second place!\nHow did you define outliers for each building? Was it an individual and mostly visual approach or a more standardised one like e.g. based on IQR or similar?", "votes": 1, "replies": [ { "id": 757011, "postDate": "2020-02-26T10:41:15.467Z", "content": "It was mostly an individual and mostly visual approach. A standardised approach is also good, but because of some edge cases not that perfekt like individual.
", "rawMarkdown": "It was mostly an individual and mostly visual approach. A standardised approach is also good, but because of some edge cases not that perfekt like individual. " } ] }, { "id": 916265, "postDate": "2020-07-05T14:17:50.837Z", "content": "Congratulations! 😊
", "rawMarkdown": "Congratulations! 😊 " }, { "id": 743276, "postDate": "2020-02-12T00:34:04.937Z", "content": "Congrats,Great!
", "rawMarkdown": "Congrats,Great!", "votes": 1 }, { "id": 722103, "postDate": "2020-01-18T05:27:06.087Z", "content": "Congratulations!
", "rawMarkdown": "Congratulations!", "votes": 1 }, { "id": 717513, "postDate": "2020-01-13T08:20:41.357Z", "content": "Congratulations! And thanks for sharing!
", "rawMarkdown": "Congratulations! And thanks for sharing!", "votes": 1 }, { "id": 716637, "postDate": "2020-01-12T03:08:09.497Z", "content": "Congratulations!
", "rawMarkdown": "Congratulations!", "votes": 1 }, { "id": 716605, "postDate": "2020-01-12T01:05:00.300Z", "content": "Your idea of thousands of models is incredibly inspiring!
", "rawMarkdown": " Your idea of thousands of models is incredibly inspiring! ", "votes": 1 }, { "id": 716494, "postDate": "2020-01-11T19:22:05.303Z", "content": "Thanks a lot @rohanrao for Sharing this :)
", "rawMarkdown": "Thanks a lot @rohanrao for Sharing this :)", "votes": 1 }, { "id": 716415, "postDate": "2020-01-11T17:29:17.413Z", "content": "Congratulation
", "rawMarkdown": "Congratulation", "votes": 1 }, { "id": 713697, "postDate": "2020-01-08T15:01:37.697Z", "content": "Congratulations and thanks for the write-up.
", "rawMarkdown": "Congratulations and thanks for the write-up. ", "votes": 1 }, { "id": 713213, "postDate": "2020-01-08T02:57:23.993Z", "content": "Congratulations! Awesome solution
", "rawMarkdown": "Congratulations! Awesome solution", "votes": 1 }, { "id": 713123, "postDate": "2020-01-07T23:29:33.443Z", "content": "Congratulations!
", "rawMarkdown": "Congratulations!", "votes": 1 }, { "id": 712971, "postDate": "2020-01-07T19:27:33.527Z", "content": "Congratulations!
", "rawMarkdown": "Congratulations!", "votes": 1 }, { "id": 711751, "postDate": "2020-01-06T14:14:08.570Z", "content": "please let me know how are you stacking the models. I mean can we use the outputs of XGB with CATBOOST and followed by NN. I new to this concept. Please elaborate
", "rawMarkdown": "please let me know how are you stacking the models. I mean can we use the outputs of XGB with CATBOOST and followed by NN. I new to this concept. Please elaborate", "votes": 1, "replies": [ { "id": 711827, "postDate": "2020-01-06T15:04:00.357Z", "content": "We just took a weighted average of different models. The approximate weights are shared in the post.
", "rawMarkdown": "We just took a weighted average of different models. The approximate weights are shared in the post.", "votes": 1 } ] }, { "id": 711178, "postDate": "2020-01-05T19:26:11.360Z", "content": "Congrats, really good job!
", "rawMarkdown": "Congrats, really good job!", "votes": 1 }, { "id": 711145, "postDate": "2020-01-05T18:29:14.650Z", "content": "sweet
", "rawMarkdown": "sweet", "votes": 1 }, { "id": 710972, "postDate": "2020-01-05T13:50:52.137Z", "content": "congrats
", "rawMarkdown": "congrats", "votes": 1 }, { "id": 710739, "postDate": "2020-01-05T06:32:54.177Z", "content": "nice
", "rawMarkdown": "nice", "votes": 1 }, { "id": 710737, "postDate": "2020-01-05T06:28:32.880Z", "content": "nice
", "rawMarkdown": "nice", "votes": 1 }, { "id": 710172, "postDate": "2020-01-04T12:03:10.477Z", "content": "Hi @oleg90777 , did you also optimize \"num_leaves\" for lightgbm in your baysian optimization?\nyou said max_depth was one of the most important parameters. I am wondering whether number of leaves is also important for lightgbm models.
", "rawMarkdown": "Hi @oleg90777 , did you also optimize \"num_leaves\" for lightgbm in your baysian optimization?\nyou said max_depth was one of the most important parameters. I am wondering whether number of leaves is also important for lightgbm models.", "votes": 1, "replies": [ { "id": 710183, "postDate": "2020-01-04T12:21:06.827Z", "content": "Yes, we also optimized numleaves, feature_fraction and subsample.
", "rawMarkdown": "Yes, we also optimized numleaves, feature_fraction and subsample. ", "votes": 2 }, { "id": 710189, "postDate": "2020-01-04T12:33:30.173Z", "content": "Thanks for your reply, that is very helpful.\nI don't know why the upvote button does not work properly, when I click on upvote button, it returns back to 0.. \nWritten upvote then 👍
", "rawMarkdown": "Thanks for your reply, that is very helpful.\nI don't know why the upvote button does not work properly, when I click on upvote button, it returns back to 0.. \nWritten upvote then 👍 ", "votes": 1 } ] }, { "id": 710069, "postDate": "2020-01-04T09:31:31.737Z", "content": "Congratulations and thanks for sharing.\nIt`s very interesting!!
", "rawMarkdown": "Congratulations and thanks for sharing.\nIt`s very interesting!!", "votes": 1 }, { "id": 710055, "postDate": "2020-01-04T09:13:15.180Z", "content": "Great!
", "rawMarkdown": "Great!", "votes": 1 }, { "id": 710046, "postDate": "2020-01-04T09:02:21.217Z", "content": "Great Work !! :)
", "rawMarkdown": "Great Work !! :)", "votes": 1 }, { "id": 709503, "postDate": "2020-01-03T15:37:59.097Z", "content": "Great work and thanks for sharing !!!!!!!!!!!!!!
", "rawMarkdown": "Great work and thanks for sharing !!!!!!!!!!!!!!", "votes": 1 }, { "id": 709421, "postDate": "2020-01-03T13:49:01.753Z", "content": "wow...!! Nice kernel to start 2020 ...!!! Congrats :-)
", "rawMarkdown": "wow...!! Nice kernel to start 2020 ...!!! Congrats :-)", "votes": 1 }, { "id": 709321, "postDate": "2020-01-03T11:11:32.503Z", "content": "wow great n congrates
", "rawMarkdown": "wow great n congrates", "votes": 1 }, { "id": 708606, "postDate": "2020-01-02T13:25:13.917Z", "content": "@rohanrao Thanks for sharing.\nYou used a lot of models. \nDid you use the same hyperparameter?\nHow did you tun the hyperparameter?
", "rawMarkdown": "@rohanrao Thanks for sharing.\nYou used a lot of models. \nDid you use the same hyperparameter?\nHow did you tun the hyperparameter?", "votes": 1, "replies": [ { "id": 708694, "postDate": "2020-01-02T14:59:46.840Z", "content": "My team-mates @oleg90777 and @isanton did all the magic to tune hyperparameters for each model.\nThey were different for different models.
", "rawMarkdown": "My team-mates @oleg90777 and @isanton did all the magic to tune hyperparameters for each model.\nThey were different for different models.", "votes": 2 }, { "id": 708723, "postDate": "2020-01-02T15:36:22.610Z", "content": "For every site_id we optimized the parameters with bayesian optimization. So we had different parameters for each site_id. We also tried to optimize parameters for every meter. However, this has brought nothing.
", "rawMarkdown": "For every site_id we optimized the parameters with bayesian optimization. So we had different parameters for each site_id. We also tried to optimize parameters for every meter. However, this has brought nothing.", "votes": 2 }, { "id": 709098, "postDate": "2020-01-03T03:28:38.917Z", "content": "Thanks a lot.\n@oleg90777 \nI optimized the parameters with bayesian optimization. But I spend two days on each lgbm. Could you give me some tips about tuning the hyperparameter?
", "rawMarkdown": "Thanks a lot.\n@oleg90777 \nI optimized the parameters with bayesian optimization. But I spend two days on each lgbm. Could you give me some tips about tuning the hyperparameter?" }, { "id": 709325, "postDate": "2020-01-03T11:15:10.957Z", "content": "Ultimately, you have to design the code as optimally as possible and throw out everything that is not needed in the calculation. \nSo far, I have found that max_depth and learning_rate are the most important parameters. You could optimize this first and then the rest. \nIf the cv of different folds is approximately the same, you can only optimize the parameters on the basis of one fold (This was hardly possible with this data set, however). It took me about 1 day for lgbm parameter optimization.\nWhat do you mean with \"each lgbm\"? \nSince there were 11 site_id's without leak, i had to find out parameters only for this site_id's one time.
", "rawMarkdown": "Ultimately, you have to design the code as optimally as possible and throw out everything that is not needed in the calculation. \nSo far, I have found that max_depth and learning_rate are the most important parameters. You could optimize this first and then the rest. \nIf the cv of different folds is approximately the same, you can only optimize the parameters on the basis of one fold (This was hardly possible with this data set, however). It took me about 1 day for lgbm parameter optimization.\nWhat do you mean with \"each lgbm\"? \nSince there were 11 site_id's without leak, i had to find out parameters only for this site_id's one time.", "votes": 2 }, { "id": 709472, "postDate": "2020-01-03T14:58:05.487Z", "content": "Thanks again.\nI got it.\nOptimize maxdepth and learningrate with bayesian optimization first.\nIf I have more time, then optimize the rest.\n\"each lgbm\" means my four models are lgbm.
", "rawMarkdown": "Thanks again.\nI got it.\nOptimize maxdepth and learningrate with bayesian optimization first.\nIf I have more time, then optimize the rest.\n\"each lgbm\" means my four models are lgbm." } ] }, { "id": 708540, "postDate": "2020-01-02T12:11:24.060Z", "content": "Congratulations and thank you for the post. Best regards.
", "rawMarkdown": "Congratulations and thank you for the post. Best regards.", "votes": 1 }, { "id": 708516, "postDate": "2020-01-02T11:24:10.257Z", "content": "This is great and very nicely Explained. Thanks. :)
", "rawMarkdown": "This is great and very nicely Explained. Thanks. :)", "votes": 1 }, { "id": 708323, "postDate": "2020-01-02T07:31:11.017Z", "content": "wonderful and very elegant solution, congratz, and thank you for the detailed explanation, the visuals helped a lot!
\n\nAre you planning sharing the modeling part as well like you did for post-processing ?
", "rawMarkdown": "wonderful and very elegant solution, congratz, and thank you for the detailed explanation, the visuals helped a lot!\n\nAre you planning sharing the modeling part as well like you did for post-processing ?", "votes": 1, "replies": [ { "id": 708392, "postDate": "2020-01-02T08:58:25.957Z", "content": "We will be happy to share our entire code if ASHRAE allows us to :-)
", "rawMarkdown": "We will be happy to share our entire code if ASHRAE allows us to :-)", "votes": 3 }, { "id": 708397, "postDate": "2020-01-02T09:02:26.390Z", "content": "Wow, hope you will be allowed ! 😍
", "rawMarkdown": "Wow, hope you will be allowed ! 😍 ", "votes": 1 }, { "id": 708492, "postDate": "2020-01-02T10:55:12.727Z", "content": "thanks again, I keep reading your solution over and over, congrats again
", "rawMarkdown": "thanks again, I keep reading your solution over and over, congrats again" } ] }, { "id": 708003, "postDate": "2020-01-01T20:26:50.317Z", "content": "Great work @rohanrao Thank you for sharing
", "rawMarkdown": "Great work @rohanrao Thank you for sharing", "votes": 1 }, { "id": 707891, "postDate": "2020-01-01T16:37:44.903Z", "content": "This is very helpful for how to approach future competitions. Thank you and congratulations!
", "rawMarkdown": "This is very helpful for how to approach future competitions. Thank you and congratulations!", "votes": 1 }, { "id": 707831, "postDate": "2020-01-01T14:54:23.980Z", "content": "beautiful!upvoted!
", "rawMarkdown": "beautiful!upvoted!", "votes": 1 }, { "id": 707033, "postDate": "2019-12-31T07:41:52.607Z", "content": "awesome
", "rawMarkdown": "awesome", "votes": 1 }, { "id": 706721, "postDate": "2019-12-30T18:19:38.553Z", "content": "Congratulations and thank you for the post!
", "rawMarkdown": "Congratulations and thank you for the post!", "votes": 1 }, { "id": 706148, "postDate": "2019-12-30T01:43:59.587Z", "content": "Congratulations! Is it possible you could share your notebook I am very intrigued to see it!
", "rawMarkdown": "Congratulations! Is it possible you could share your notebook I am very intrigued to see it! ", "votes": 1 }, { "id": 706044, "postDate": "2019-12-29T20:48:52.667Z", "content": "@rohanrao Congratulations Rohan on your first money prize in Kaggle . Wishing you a happy new year 2020
", "rawMarkdown": "@rohanrao Congratulations Rohan on your first money prize in Kaggle . Wishing you a happy new year 2020", "votes": 1 }, { "id": 705906, "postDate": "2019-12-29T16:52:46.570Z", "content": "Congrats!!! Luv to see how the solution was created =)
", "rawMarkdown": "Congrats!!! Luv to see how the solution was created =)", "votes": 1 }, { "id": 705859, "postDate": "2019-12-29T15:33:20.123Z", "content": "Congrats @rohanrao !!🎉 & Thanks for sharing your insights!!😄 👍
", "rawMarkdown": "Congrats @rohanrao !!🎉 & Thanks for sharing your insights!!😄 👍 ", "votes": 1 }, { "id": 705505, "postDate": "2019-12-29T01:18:45.243Z", "content": "Congratulations, Vopani!
", "rawMarkdown": "Congratulations, Vopani!", "votes": 1 }, { "id": 705267, "postDate": "2019-12-28T17:40:47.643Z", "content": "Congratulations
", "rawMarkdown": "Congratulations", "votes": 1 }, { "id": 705204, "postDate": "2019-12-28T16:54:27.250Z", "content": "Congrats to you and your team. Amazing solution for Ensemble Learning and Thanks for sharing @rohanrao !
", "rawMarkdown": "Congrats to you and your team. Amazing solution for Ensemble Learning and Thanks for sharing @rohanrao !", "votes": 1 }, { "id": 705142, "postDate": "2019-12-28T14:11:53.217Z", "content": "Great Solution 💪
", "rawMarkdown": "Great Solution 💪 ", "votes": 1 }, { "id": 705123, "postDate": "2019-12-28T13:20:53.960Z", "content": "Congratulations\nThanks for sharing your Approach & Insights!! @rohanrao
", "rawMarkdown": "Congratulations\nThanks for sharing your Approach & Insights!! @rohanrao ", "votes": 1 }, { "id": 705113, "postDate": "2019-12-28T13:03:41.743Z", "content": "Congratulations!!
", "rawMarkdown": "Congratulations!!", "votes": 1 }, { "id": 705108, "postDate": "2019-12-28T12:41:25.857Z", "content": "Congrats! It seems that removing sites 0,1,2,4,15 may have played a role on private LB.
", "rawMarkdown": "Congrats! It seems that removing sites 0,1,2,4,15 may have played a role on private LB.", "votes": 1 }, { "id": 705075, "postDate": "2019-12-28T11:36:25.103Z", "content": "Congrats :)
", "rawMarkdown": "Congrats :)", "votes": 1 }, { "id": 704942, "postDate": "2019-12-28T07:29:54.060Z", "content": "Congrats Rohan.
", "rawMarkdown": "Congrats Rohan.", "votes": 1 }, { "id": 704885, "postDate": "2019-12-28T06:00:22.890Z", "content": "Congrats @rohanrao for a well deserved 2nd place finish. I hope I do not wait as long as you did for my elusive solo gold medal? I really thought ASHRAE will be the one but the leak happened everything got messed up but I did not want to give up so here we go.
\n\nI look forward to your complete solution.
\n\nHappy holidays.
", "rawMarkdown": "Congrats @rohanrao for a well deserved 2nd place finish. I hope I do not wait as long as you did for my elusive solo gold medal? I really thought ASHRAE will be the one but the leak happened everything got messed up but I did not want to give up so here we go.\n\nI look forward to your complete solution. \n\nHappy holidays.", "votes": 1 }, { "id": 704882, "postDate": "2019-12-28T05:55:29.677Z", "content": "Congratulations. I learn a lot from your kernel too.
", "rawMarkdown": "Congratulations. I learn a lot from your kernel too.", "votes": 1 }, { "id": 704844, "postDate": "2019-12-28T04:26:31.600Z", "content": "Great work !!by the way,I'm curious about what post processing is?
", "rawMarkdown": "Great work !!by the way,I'm curious about what post processing is?", "votes": 1, "replies": [ { "id": 705004, "postDate": "2019-12-28T09:35:53.933Z", "content": "Applying a transformation on the raw predictions by a model based on some heuristic / hypothesis. Example is discussed in this thread: https://www.kaggle.com/c/ashrae-energy-prediction/discussion/122366
\n\nHere's a more detailed write-up: https://www.kaggle.com/c/ashrae-energy-prediction/discussion/123528
", "rawMarkdown": "Applying a transformation on the raw predictions by a model based on some heuristic / hypothesis. Example is discussed in this thread: https://www.kaggle.com/c/ashrae-energy-prediction/discussion/122366\n\nHere's a more detailed write-up: https://www.kaggle.com/c/ashrae-energy-prediction/discussion/123528", "votes": 2 }, { "id": 705006, "postDate": "2019-12-28T09:42:00.283Z", "content": "nice! I knew it!
", "rawMarkdown": "nice! I knew it!" } ] }, { "id": 712891, "postDate": "2020-01-07T17:29:11.317Z", "content": "Congratulations .......
", "rawMarkdown": "Congratulations .......", "votes": 2 }, { "id": 712792, "postDate": "2020-01-07T15:34:56.883Z", "content": "Wow.\nCongratulations!\nI've learned a lot reading your latest posts. Thanks for sharing and for explaining the bases.
", "rawMarkdown": "Wow.\nCongratulations!\nI've learned a lot reading your latest posts. Thanks for sharing and for explaining the bases.", "votes": 2 }, { "id": 710854, "postDate": "2020-01-05T10:34:23.740Z", "content": "Congrats! And thanks a lot for sharing the approach :)
", "rawMarkdown": "Congrats! And thanks a lot for sharing the approach :)", "votes": 2 }, { "id": 709373, "postDate": "2020-01-03T12:36:18.550Z", "content": "Thanks for sharing...........and Happy New Year
", "rawMarkdown": "Thanks for sharing...........and Happy New Year ", "votes": 2 }, { "id": 706521, "postDate": "2019-12-30T14:13:05.517Z", "content": "Congratulations @rohanrao , thanks a lot for sharing.\nHow did you validate the preprocessing and ensembling using leak data of sites 0-1-2-4-15?\nDid you include sites 0-1-2-4-15 (year 2016) as training data then validate leak data (from years 2017-2018)?\nor did you use the models trained on others sites to validate leak data of sites 0-1-2-4-15? \nDid you find that information from other sites could be beneficial in predicting remaining sites 0-1-2-4-15? \nCheers
", "rawMarkdown": "Congratulations @rohanrao , thanks a lot for sharing.\nHow did you validate the preprocessing and ensembling using leak data of sites 0-1-2-4-15?\nDid you include sites 0-1-2-4-15 (year 2016) as training data then validate leak data (from years 2017-2018)?\nor did you use the models trained on others sites to validate leak data of sites 0-1-2-4-15? \nDid you find that information from other sites could be beneficial in predicting remaining sites 0-1-2-4-15? \nCheers", "votes": 2, "replies": [ { "id": 706580, "postDate": "2019-12-30T15:35:33.737Z", "content": "Our core models were built at site+meter level, so we didn't explore / validate too much of cross-site information / ideas.
\n\nTo validate using leak data, we applied the postprocessing or ensembling weights on the model predictions for the leaked sites and validated what reducing factor or weights were optimal. So, something like build model using site-0 train data, predict for site-0 test data, get the true labels for test data from leak and check best reducing factor / ensemble weights that minimizes RMSLE.
\n\nNote that we also validated on CV and generally chose weights which improved CV and leak both.
\n\nWe didn't use leak data as additional training data for models.
", "rawMarkdown": "Our core models were built at site+meter level, so we didn't explore / validate too much of cross-site information / ideas.\n\nTo validate using leak data, we applied the postprocessing or ensembling weights on the model predictions for the leaked sites and validated what reducing factor or weights were optimal. So, something like build model using site-0 train data, predict for site-0 test data, get the true labels for test data from leak and check best reducing factor / ensemble weights that minimizes RMSLE.\n\nNote that we also validated on CV and generally chose weights which improved CV and leak both.\n\nWe didn't use leak data as additional training data for models.", "votes": 2 }, { "id": 706588, "postDate": "2019-12-30T15:49:02.707Z", "content": "Thank you very much :)
", "rawMarkdown": "Thank you very much :) " } ] }, { "id": 705411, "postDate": "2019-12-28T22:43:15.833Z", "content": "Congrats, @rohanrao . May I know how did you draw the architecture figure? What software did you use? Thanks!
", "rawMarkdown": "Congrats, @rohanrao . May I know how did you draw the architecture figure? What software did you use? Thanks!", "votes": 2, "replies": [ { "id": 705503, "postDate": "2019-12-29T01:18:36.547Z", "content": "Nothing fancy, just old school Microsoft PowerPoint.
", "rawMarkdown": "Nothing fancy, just old school Microsoft PowerPoint.", "votes": 6 } ] }, { "id": 716432, "postDate": "2020-01-11T17:46:58.527Z", "content": "Why did your team use very less feature engineering and settled with about 30 features?
", "rawMarkdown": "Why did your team use very less feature engineering and settled with about 30 features?", "replies": [ { "id": 716708, "postDate": "2020-01-12T05:53:56.043Z", "content": "It did not improve our validation scores, nor the public LB.\nValidation itself was quite challenging and we were a bit skeptical that feature engineering would only lead to overfitting.
", "rawMarkdown": "It did not improve our validation scores, nor the public LB.\nValidation itself was quite challenging and we were a bit skeptical that feature engineering would only lead to overfitting.", "votes": 2 } ] }, { "id": 709574, "postDate": "2020-01-03T17:22:23.217Z", "content": "Great Kernel ! Great Work ! Very nicely explained. Thanks for sharing :)
", "rawMarkdown": "Great Kernel ! Great Work ! Very nicely explained. Thanks for sharing :)" }, { "id": 706027, "postDate": "2019-12-29T20:29:52.847Z", "content": "> We bagged a bunch of boosting models XGB, LGBM, CB at various levels of data: Models for every site+meter, models for every building+meter, models for every building-type+meter.
\n\nHow's the performance (lb score) of these 3 types of models? \nAnd what's the 50 features you used? It would be nice if you could share the code ;)
", "rawMarkdown": "> We bagged a bunch of boosting models XGB, LGBM, CB at various levels of data: Models for every site+meter, models for every building+meter, models for every building-type+meter.\n\nHow's the performance (lb score) of these 3 types of models? \nAnd what's the 50 features you used? It would be nice if you could share the code ;)", "replies": [ { "id": 706184, "postDate": "2019-12-30T03:16:03.910Z", "content": "The site+meter models (60% weight) were the best, followed by building+meter (20% weight) and then building-type+meter (20% weight). We don't have the exact scores of each model because after a while we only submitted bagged ones. Maybe I will resubmit and update the post once the LB scores are up again.
\n\nBagged XGB with post processing scored 0.954 on public LB\nBagged LGBM with post processing scored 0.955 on public LB\nBagged CB with post processing scored 0.957 on public LB\nDidn't submit FFNN separately because it was only built for meter = 0\nEnsemble without FFNN scored 0.939 on public LB\nEnsemble with FFNN and post processing scored 0.937 on public LB (2nd in private LB)\nEnsemble with FFNN but without post-processing scored 0.953 on public LB
\n\nOn exact features and code/notebook, we will decide to share it publicly once we get an ok from the organizers/host. But the FE is not one of the key parts of our solution, I doubt we have any feature that isn't already on one of the public kernels.
", "rawMarkdown": "The site+meter models (60% weight) were the best, followed by building+meter (20% weight) and then building-type+meter (20% weight). We don't have the exact scores of each model because after a while we only submitted bagged ones. Maybe I will resubmit and update the post once the LB scores are up again.\n\nBagged XGB with post processing scored **0.954** on public LB\nBagged LGBM with post processing scored **0.955** on public LB\nBagged CB with post processing scored **0.957** on public LB\nDidn't submit FFNN separately because it was only built for meter = 0\nEnsemble without FFNN scored **0.939** on public LB\nEnsemble with FFNN and post processing scored **0.937** on public LB (2nd in private LB)\nEnsemble with FFNN but without post-processing scored **0.953** on public LB\n\nOn exact features and code/notebook, we will decide to share it publicly once we get an ok from the organizers/host. But the FE is not one of the key parts of our solution, I doubt we have any feature that isn't already on one of the public kernels.", "votes": 6 }, { "id": 710428, "postDate": "2020-01-04T18:03:40.290Z", "content": "@Vopani, thank you very much for the sharing!
\n\nJust to understand your solution, since we had:\n- 15 site_ids\n- 4 meters\n- 1448 building_ids\n- 14 building_types
\n\nThe final solution ensembles a total of 19.200 models, right?
\n\n
Thanks once more for the knowledge spread! 😊
", "rawMarkdown": "@Vopani, thank you very much for the sharing!\n\nJust to understand your solution, since we had:\n- 15 site_ids\n- 4 meters\n- 1448 building_ids\n- 14 building_types\n\nThe final solution ensembles a total of 19.200 models, right?\n\n\n\nThanks once more for the knowledge spread! 😊", "votes": 1 } ] }, { "id": 705613, "postDate": "2019-12-29T06:34:32.103Z", "rawMarkdown": "", "votes": 1, "isDeleted": true }, { "id": 707691, "postDate": "2020-01-01T10:07:32.537Z", "content": "Thanks for sharing
", "rawMarkdown": "Thanks for sharing", "votes": 3 }, { "id": 721386, "postDate": "2020-01-17T10:31:58.537Z", "content": "Thanks for this fantastic post.
", "rawMarkdown": "Thanks for this fantastic post.", "votes": 1 }, { "id": 718084, "postDate": "2020-01-14T01:17:37.230Z", "content": "Thanks for sharing~
", "rawMarkdown": "Thanks for sharing~", "votes": 1 }, { "id": 712184, "postDate": "2020-01-06T23:13:19.480Z", "content": "Congrats, and thank you for sharing.
", "rawMarkdown": "Congrats, and thank you for sharing.", "votes": 1 }, { "id": 711299, "postDate": "2020-01-05T22:41:54.267Z", "content": "Thanks for sharing!
", "rawMarkdown": "Thanks for sharing! ", "votes": 1 }, { "id": 710383, "postDate": "2020-01-04T16:59:38.127Z", "content": "Congrats! Thanks for sharing :)
", "rawMarkdown": "Congrats! Thanks for sharing :) ", "votes": 1 }, { "id": 709067, "postDate": "2020-01-03T02:35:57.533Z", "content": "Congratulations!\nThanks for sharing
", "rawMarkdown": "Congratulations!\nThanks for sharing", "votes": 1 }, { "id": 707892, "postDate": "2020-01-01T16:38:45.157Z", "content": "Thanks for sharing ! :)
", "rawMarkdown": "Thanks for sharing ! :)", "votes": 1 }, { "id": 707367, "postDate": "2019-12-31T17:38:08.340Z", "content": "Thanks for sharing. Congratulations🔥
", "rawMarkdown": "Thanks for sharing. Congratulations🔥 ", "votes": 1 }, { "id": 707309, "postDate": "2019-12-31T15:59:05.007Z", "content": "Impressive, thanks for sharing! :)
", "rawMarkdown": "Impressive, thanks for sharing! :)", "votes": 1 }, { "id": 706212, "postDate": "2019-12-30T04:39:27.613Z", "content": "Congratulations...thanks for sharing
", "rawMarkdown": "Congratulations...thanks for sharing", "votes": 1 }, { "id": 705968, "postDate": "2019-12-29T18:24:36.783Z", "content": "Congrats and thanks for sharing :)
", "rawMarkdown": "Congrats and thanks for sharing :)\n", "votes": 1 }, { "id": 705620, "postDate": "2019-12-29T06:57:29.407Z", "content": "congratulation, Thanks for sharing
", "rawMarkdown": "congratulation, Thanks for sharing ", "votes": 1 }, { "id": 711448, "postDate": "2020-01-06T05:41:12.740Z", "content": "Thanks for sharing!!
", "rawMarkdown": "Thanks for sharing!!", "votes": 2 }, { "id": 711440, "postDate": "2020-01-06T05:19:08.053Z", "content": "Congrats! thanks for sharing
", "rawMarkdown": "Congrats! thanks for sharing", "votes": 2 }, { "id": 722211, "postDate": "2020-01-18T09:14:22.873Z", "content": "Good Kernel 👍 Thanks for sharing
", "rawMarkdown": "Good Kernel 👍 Thanks for sharing" } ], "comments": [ { "id": 717354, "author_name": "Clayton Miller", "author_url": "", "post_date": "2020-01-13T03:47:44.440000", "content": "Congratulations to our second-place team!!!!!! 🙌 💪 👍 👊 Their solution will be organized and added to the other top five winners in a publication and open-source repository. Please stay tuned!
\n\nAlso, for everyone else, we are in the process of curating a directory of Notebooks for building performance engineers and analysts from the competition that will serve as a recipe book for beginners as well as experts who are curious to learn about certain topics. We highly encourage you all to share your solutions as a notebook for this purpose. We will acknowledge the authors of all notebooks in this process, so please annotate your notebook or profile with how you would like to be acknowledged. It would also be helpful if you could indicate whether you are an ASHRAE member.
", "votes": 3, "replies": [] }, { "id": 705110, "author_name": "Giba", "author_url": "", "post_date": "2019-12-28T12:50:16.897000", "content": "Congrats! Nice ensembling :)
", "votes": 3, "replies": [] }, { "id": 705036, "author_name": "MPWARE", "author_url": "", "post_date": "2019-12-28T10:22:10.923000", "content": "Congratulations! According to:\nhttps://www.kaggle.com/sohier/ashrae-interim-scores#final_all_scores.csv
\n\nYou had 6 submissions at 1.22 so your team is the best even if you've selected ones at 1.23. Only Btbpanda had one submission better (but they don't selected it).
", "votes": 3, "replies": [] }, { "id": 705706, "author_name": "Sanyam Bhutani", "author_url": "", "post_date": "2019-12-29T10:21:21.263000", "content": "Congratulations! :D
\n\n\n\n\nRemove noise (Very important)
\n
This time removing the noise got you to the prize zone! 😁
\n\nA little context for everyone, from H2O.ai's GrandMaster Panel
\n\n\n", "votes": 4, "replies": [] }, { "id": 852791, "author_name": "LittleShiny", "author_url": "", "post_date": "2020-05-18T17:20:10.107000", "content": "Q: Any mistakes or Regrets from a competition?\n @rohanrao advises looking at outliers, based on a competition where removing just ONE outlier would have landed him 1st position.
\n
Congratulations!\nMany competitors mentioned leak data. I am new for machine learning. Can you explain what's the meaning of 'leak data' in this competition?
", "votes": 1, "replies": [ { "id": 853618, "author_name": "Oleg Knaub", "author_url": "", "post_date": "2020-05-19T10:36:36.567000", "content": "Hello, that means part of public and private labels were in the internet. So if you take that labels you would have for a part of data accuracy of 100%
", "votes": 0, "replies": [] } ] }, { "id": 757003, "author_name": "AnaLyze", "author_url": "", "post_date": "2020-02-26T10:29:41.320000", "content": "Thank you for the well explained solution and congratulations with the second place!\nHow did you define outliers for each building? Was it an individual and mostly visual approach or a more standardised one like e.g. based on IQR or similar?
", "votes": 1, "replies": [ { "id": 757011, "author_name": "Oleg Knaub", "author_url": "", "post_date": "2020-02-26T10:41:15.467000", "content": "It was mostly an individual and mostly visual approach. A standardised approach is also good, but because of some edge cases not that perfekt like individual.
", "votes": 0, "replies": [] } ] }, { "id": 916265, "author_name": "Narendra Singh Parihar", "author_url": "", "post_date": "2020-07-05T14:17:50.837000", "content": "Congratulations! 😊
", "votes": 0, "replies": [] }, { "id": 743276, "author_name": "Muhammet Ikbal Elek", "author_url": "", "post_date": "2020-02-12T00:34:04.937000", "content": "Congrats,Great!
", "votes": 1, "replies": [] }, { "id": 722103, "author_name": "Taner Sekmen", "author_url": "", "post_date": "2020-01-18T05:27:06.087000", "content": "Congratulations!
", "votes": 1, "replies": [] }, { "id": 717513, "author_name": "Stefania Rana", "author_url": "", "post_date": "2020-01-13T08:20:41.357000", "content": "Congratulations! And thanks for sharing!
", "votes": 1, "replies": [] }, { "id": 716637, "author_name": "", "author_url": "", "post_date": "2020-01-12T03:08:09.497000", "content": "Congratulations!
", "votes": 1, "replies": [] }, { "id": 716605, "author_name": "Yixinchen", "author_url": "", "post_date": "2020-01-12T01:05:00.300000", "content": "Your idea of thousands of models is incredibly inspiring!
", "votes": 1, "replies": [] }, { "id": 716494, "author_name": "Risab Biswas", "author_url": "", "post_date": "2020-01-11T19:22:05.303000", "content": "Thanks a lot @rohanrao for Sharing this :)
", "votes": 1, "replies": [] }, { "id": 716415, "author_name": "Kurian Benoy", "author_url": "", "post_date": "2020-01-11T17:29:17.413000", "content": "Congratulation
", "votes": 1, "replies": [] }, { "id": 713697, "author_name": "Ved", "author_url": "", "post_date": "2020-01-08T15:01:37.697000", "content": "Congratulations and thanks for the write-up.
", "votes": 1, "replies": [] }, { "id": 713213, "author_name": "liuze", "author_url": "", "post_date": "2020-01-08T02:57:23.993000", "content": "Congratulations! Awesome solution
", "votes": 1, "replies": [] }, { "id": 713123, "author_name": "WangYong", "author_url": "", "post_date": "2020-01-07T23:29:33.443000", "content": "Congratulations!
", "votes": 1, "replies": [] }, { "id": 712971, "author_name": "Ben Fan", "author_url": "", "post_date": "2020-01-07T19:27:33.527000", "content": "Congratulations!
", "votes": 1, "replies": [] }, { "id": 711751, "author_name": "rackson3861", "author_url": "", "post_date": "2020-01-06T14:14:08.570000", "content": "please let me know how are you stacking the models. I mean can we use the outputs of XGB with CATBOOST and followed by NN. I new to this concept. Please elaborate
", "votes": 1, "replies": [ { "id": 711827, "author_name": "Vopani", "author_url": "", "post_date": "2020-01-06T15:04:00.357000", "content": "We just took a weighted average of different models. The approximate weights are shared in the post.
", "votes": 1, "replies": [] } ] }, { "id": 711178, "author_name": "Vasileios Tsakalos", "author_url": "", "post_date": "2020-01-05T19:26:11.360000", "content": "Congrats, really good job!
", "votes": 1, "replies": [] }, { "id": 711145, "author_name": "Arjun Kathuria", "author_url": "", "post_date": "2020-01-05T18:29:14.650000", "content": "sweet
", "votes": 1, "replies": [] }, { "id": 710972, "author_name": "Anwar Alam", "author_url": "", "post_date": "2020-01-05T13:50:52.137000", "content": "congrats
", "votes": 1, "replies": [] }, { "id": 710739, "author_name": "Vishwanath Poojari", "author_url": "", "post_date": "2020-01-05T06:32:54.177000", "content": "nice
", "votes": 1, "replies": [] }, { "id": 710737, "author_name": "Soumyajit Karmakar", "author_url": "", "post_date": "2020-01-05T06:28:32.880000", "content": "nice
", "votes": 1, "replies": [] }, { "id": 710172, "author_name": "Nono", "author_url": "", "post_date": "2020-01-04T12:03:10.477000", "content": "Hi @oleg90777 , did you also optimize \"num_leaves\" for lightgbm in your baysian optimization?\nyou said max_depth was one of the most important parameters. I am wondering whether number of leaves is also important for lightgbm models.
", "votes": 1, "replies": [ { "id": 710183, "author_name": "Oleg Knaub", "author_url": "", "post_date": "2020-01-04T12:21:06.827000", "content": "Yes, we also optimized numleaves, feature_fraction and subsample.
", "votes": 2, "replies": [] }, { "id": 710189, "author_name": "Nono", "author_url": "", "post_date": "2020-01-04T12:33:30.173000", "content": "Thanks for your reply, that is very helpful.\nI don't know why the upvote button does not work properly, when I click on upvote button, it returns back to 0.. \nWritten upvote then 👍
", "votes": 1, "replies": [] } ] }, { "id": 710069, "author_name": "Artem Vazhentsev", "author_url": "", "post_date": "2020-01-04T09:31:31.737000", "content": "Congratulations and thanks for sharing.\nIt`s very interesting!!
", "votes": 1, "replies": [] }, { "id": 710055, "author_name": "Arjun", "author_url": "", "post_date": "2020-01-04T09:13:15.180000", "content": "Great!
", "votes": 1, "replies": [] }, { "id": 710046, "author_name": "Prateek Ralhan", "author_url": "", "post_date": "2020-01-04T09:02:21.217000", "content": "Great Work !! :)
", "votes": 1, "replies": [] }, { "id": 709503, "author_name": "ask9", "author_url": "", "post_date": "2020-01-03T15:37:59.097000", "content": "Great work and thanks for sharing !!!!!!!!!!!!!!
", "votes": 1, "replies": [] }, { "id": 709421, "author_name": "", "author_url": "", "post_date": "2020-01-03T13:49:01.753000", "content": "", "votes": 1, "replies": [] }, { "id": 709321, "author_name": "", "author_url": "", "post_date": "2020-01-03T11:11:32.503000", "content": "", "votes": 1, "replies": [] }, { "id": 708606, "author_name": "", "author_url": "", "post_date": "2020-01-02T13:25:13.917000", "content": "", "votes": 1, "replies": [ { "id": 708694, "author_name": "", "author_url": "", "post_date": "2020-01-02T14:59:46.840000", "content": "", "votes": 2, "replies": [] }, { "id": 708723, "author_name": "", "author_url": "", "post_date": "2020-01-02T15:36:22.610000", "content": "", "votes": 2, "replies": [] }, { "id": 709098, "author_name": "", "author_url": "", "post_date": "2020-01-03T03:28:38.917000", "content": "", "votes": 0, "replies": [] }, { "id": 709325, "author_name": "", "author_url": "", "post_date": "2020-01-03T11:15:10.957000", "content": "", "votes": 2, "replies": [] }, { "id": 709472, "author_name": "", "author_url": "", "post_date": "2020-01-03T14:58:05.487000", "content": "", "votes": 0, "replies": [] } ] }, { "id": 708540, "author_name": "", "author_url": "", "post_date": "2020-01-02T12:11:24.060000", "content": "", "votes": 1, "replies": [] }, { "id": 708516, "author_name": "", "author_url": "", "post_date": "2020-01-02T11:24:10.257000", "content": "", "votes": 1, "replies": [] }, { "id": 708323, "author_name": "", "author_url": "", "post_date": "2020-01-02T07:31:11.017000", "content": "", "votes": 1, "replies": [ { "id": 708392, "author_name": "", "author_url": "", "post_date": "2020-01-02T08:58:25.957000", "content": "", "votes": 3, "replies": [] }, { "id": 708397, "author_name": "", "author_url": "", "post_date": "2020-01-02T09:02:26.390000", "content": "", "votes": 1, "replies": [] }, { "id": 708492, "author_name": "", "author_url": "", "post_date": "2020-01-02T10:55:12.727000", "content": "", "votes": 0, "replies": [] } ] }, { "id": 708003, "author_name": "", "author_url": "", "post_date": "2020-01-01T20:26:50.317000", "content": "", "votes": 1, "replies": [] }, { "id": 707891, "author_name": "", "author_url": "", "post_date": "2020-01-01T16:37:44.903000", "content": "", "votes": 1, "replies": [] }, { "id": 707831, "author_name": "", "author_url": "", "post_date": "2020-01-01T14:54:23.980000", "content": "", "votes": 1, "replies": [] }, { "id": 707033, "author_name": "", "author_url": "", "post_date": "2019-12-31T07:41:52.607000", "content": "", "votes": 1, "replies": [] }, { "id": 706721, "author_name": "", "author_url": "", "post_date": "2019-12-30T18:19:38.553000", "content": "", "votes": 1, "replies": [] }, { "id": 706148, "author_name": "", "author_url": "", "post_date": "2019-12-30T01:43:59.587000", "content": "", "votes": 1, "replies": [] }, { "id": 706044, "author_name": "", "author_url": "", "post_date": "2019-12-29T20:48:52.667000", "content": "", "votes": 1, "replies": [] }, { "id": 705906, "author_name": "", "author_url": "", "post_date": "2019-12-29T16:52:46.570000", "content": "", "votes": 1, "replies": [] }, { "id": 705859, "author_name": "", "author_url": "", "post_date": "2019-12-29T15:33:20.123000", "content": "", "votes": 1, "replies": [] }, { "id": 705505, "author_name": "", "author_url": "", "post_date": "2019-12-29T01:18:45.243000", "content": "", "votes": 1, "replies": [] }, { "id": 705267, "author_name": "", "author_url": "", "post_date": "2019-12-28T17:40:47.643000", "content": "", "votes": 1, "replies": [] }, { "id": 705204, "author_name": "", "author_url": "", "post_date": "2019-12-28T16:54:27.250000", "content": "", "votes": 1, "replies": [] }, { "id": 705142, "author_name": "", "author_url": "", "post_date": "2019-12-28T14:11:53.217000", "content": "", "votes": 1, "replies": [] }, { "id": 705123, "author_name": "", "author_url": "", "post_date": "2019-12-28T13:20:53.960000", "content": "", "votes": 1, "replies": [] }, { "id": 705113, "author_name": "", "author_url": "", "post_date": "2019-12-28T13:03:41.743000", "content": "", "votes": 1, "replies": [] }, { "id": 705108, "author_name": "", "author_url": "", "post_date": "2019-12-28T12:41:25.857000", "content": "", "votes": 1, "replies": [] }, { "id": 705075, "author_name": "", "author_url": "", "post_date": "2019-12-28T11:36:25.103000", "content": "", "votes": 1, "replies": [] }, { "id": 704942, "author_name": "", "author_url": "", "post_date": "2019-12-28T07:29:54.060000", "content": "", "votes": 1, "replies": [] }, { "id": 704885, "author_name": "", "author_url": "", "post_date": "2019-12-28T06:00:22.890000", "content": "", "votes": 1, "replies": [] }, { "id": 704882, "author_name": "", "author_url": "", "post_date": "2019-12-28T05:55:29.677000", "content": "", "votes": 1, "replies": [] }, { "id": 704844, "author_name": "", "author_url": "", "post_date": "2019-12-28T04:26:31.600000", "content": "", "votes": 1, "replies": [ { "id": 705004, "author_name": "", "author_url": "", "post_date": "2019-12-28T09:35:53.933000", "content": "", "votes": 2, "replies": [] }, { "id": 705006, "author_name": "", "author_url": "", "post_date": "2019-12-28T09:42:00.283000", "content": "", "votes": 0, "replies": [] } ] }, { "id": 712891, "author_name": "", "author_url": "", "post_date": "2020-01-07T17:29:11.317000", "content": "", "votes": 2, "replies": [] }, { "id": 712792, "author_name": "", "author_url": "", "post_date": "2020-01-07T15:34:56.883000", "content": "", "votes": 2, "replies": [] }, { "id": 710854, "author_name": "", "author_url": "", "post_date": "2020-01-05T10:34:23.740000", "content": "", "votes": 2, "replies": [] }, { "id": 709373, "author_name": "", "author_url": "", "post_date": "2020-01-03T12:36:18.550000", "content": "", "votes": 2, "replies": [] }, { "id": 706521, "author_name": "", "author_url": "", "post_date": "2019-12-30T14:13:05.517000", "content": "", "votes": 2, "replies": [ { "id": 706580, "author_name": "", "author_url": "", "post_date": "2019-12-30T15:35:33.737000", "content": "", "votes": 2, "replies": [] }, { "id": 706588, "author_name": "", "author_url": "", "post_date": "2019-12-30T15:49:02.707000", "content": "", "votes": 0, "replies": [] } ] }, { "id": 705411, "author_name": "", "author_url": "", "post_date": "2019-12-28T22:43:15.833000", "content": "", "votes": 2, "replies": [ { "id": 705503, "author_name": "", "author_url": "", "post_date": "2019-12-29T01:18:36.547000", "content": "", "votes": 6, "replies": [] } ] }, { "id": 716432, "author_name": "", "author_url": "", "post_date": "2020-01-11T17:46:58.527000", "content": "", "votes": 0, "replies": [ { "id": 716708, "author_name": "", "author_url": "", "post_date": "2020-01-12T05:53:56.043000", "content": "", "votes": 2, "replies": [] } ] }, { "id": 709574, "author_name": "", "author_url": "", "post_date": "2020-01-03T17:22:23.217000", "content": "", "votes": 0, "replies": [] }, { "id": 706027, "author_name": "", "author_url": "", "post_date": "2019-12-29T20:29:52.847000", "content": "", "votes": 0, "replies": [ { "id": 706184, "author_name": "", "author_url": "", "post_date": "2019-12-30T03:16:03.910000", "content": "", "votes": 6, "replies": [] }, { "id": 710428, "author_name": "", "author_url": "", "post_date": "2020-01-04T18:03:40.290000", "content": "", "votes": 1, "replies": [] } ] }, { "id": 705613, "author_name": "", "author_url": "", "post_date": "2019-12-29T06:34:32.103000", "content": "", "votes": 1, "replies": [] }, { "id": 707691, "author_name": "", "author_url": "", "post_date": "2020-01-01T10:07:32.537000", "content": "", "votes": 3, "replies": [] }, { "id": 721386, "author_name": "", "author_url": "", "post_date": "2020-01-17T10:31:58.537000", "content": "", "votes": 1, "replies": [] }, { "id": 718084, "author_name": "", "author_url": "", "post_date": "2020-01-14T01:17:37.230000", "content": "", "votes": 1, "replies": [] }, { "id": 712184, "author_name": "", "author_url": "", "post_date": "2020-01-06T23:13:19.480000", "content": "", "votes": 1, "replies": [] }, { "id": 711299, "author_name": "", "author_url": "", "post_date": "2020-01-05T22:41:54.267000", "content": "", "votes": 1, "replies": [] }, { "id": 710383, "author_name": "", "author_url": "", "post_date": "2020-01-04T16:59:38.127000", "content": "", "votes": 1, "replies": [] }, { "id": 709067, "author_name": "", "author_url": "", "post_date": "2020-01-03T02:35:57.533000", "content": "", "votes": 1, "replies": [] }, { "id": 707892, "author_name": "", "author_url": "", "post_date": "2020-01-01T16:38:45.157000", "content": "", "votes": 1, "replies": [] }, { "id": 707367, "author_name": "", "author_url": "", "post_date": "2019-12-31T17:38:08.340000", "content": "", "votes": 1, "replies": [] }, { "id": 707309, "author_name": "", "author_url": "", "post_date": "2019-12-31T15:59:05.007000", "content": "", "votes": 1, "replies": [] }, { "id": 706212, "author_name": "", "author_url": "", "post_date": "2019-12-30T04:39:27.613000", "content": "", "votes": 1, "replies": [] }, { "id": 705968, "author_name": "", "author_url": "", "post_date": "2019-12-29T18:24:36.783000", "content": "", "votes": 1, "replies": [] }, { "id": 705620, "author_name": "", "author_url": "", "post_date": "2019-12-29T06:57:29.407000", "content": "", "votes": 1, "replies": [] }, { "id": 711448, "author_name": "", "author_url": "", "post_date": "2020-01-06T05:41:12.740000", "content": "", "votes": 2, "replies": [] }, { "id": 711440, "author_name": "", "author_url": "", "post_date": "2020-01-06T05:19:08.053000", "content": "", "votes": 2, "replies": [] }, { "id": 722211, "author_name": "", "author_url": "", "post_date": "2020-01-18T09:14:22.873000", "content": "", "votes": 0, "replies": [] } ], "raw_markdown_by_id": { "704834": "Our team finished 2nd on private LB (12th on public). The private LB is finally released officially.\n\nSo happy and pumped up for winning in the money for the first time on Kaggle (after 6 years). Santa has been kind this year :-)\nOur team will be kind too and share our complete solution.\n\n## Solution Architecture:\n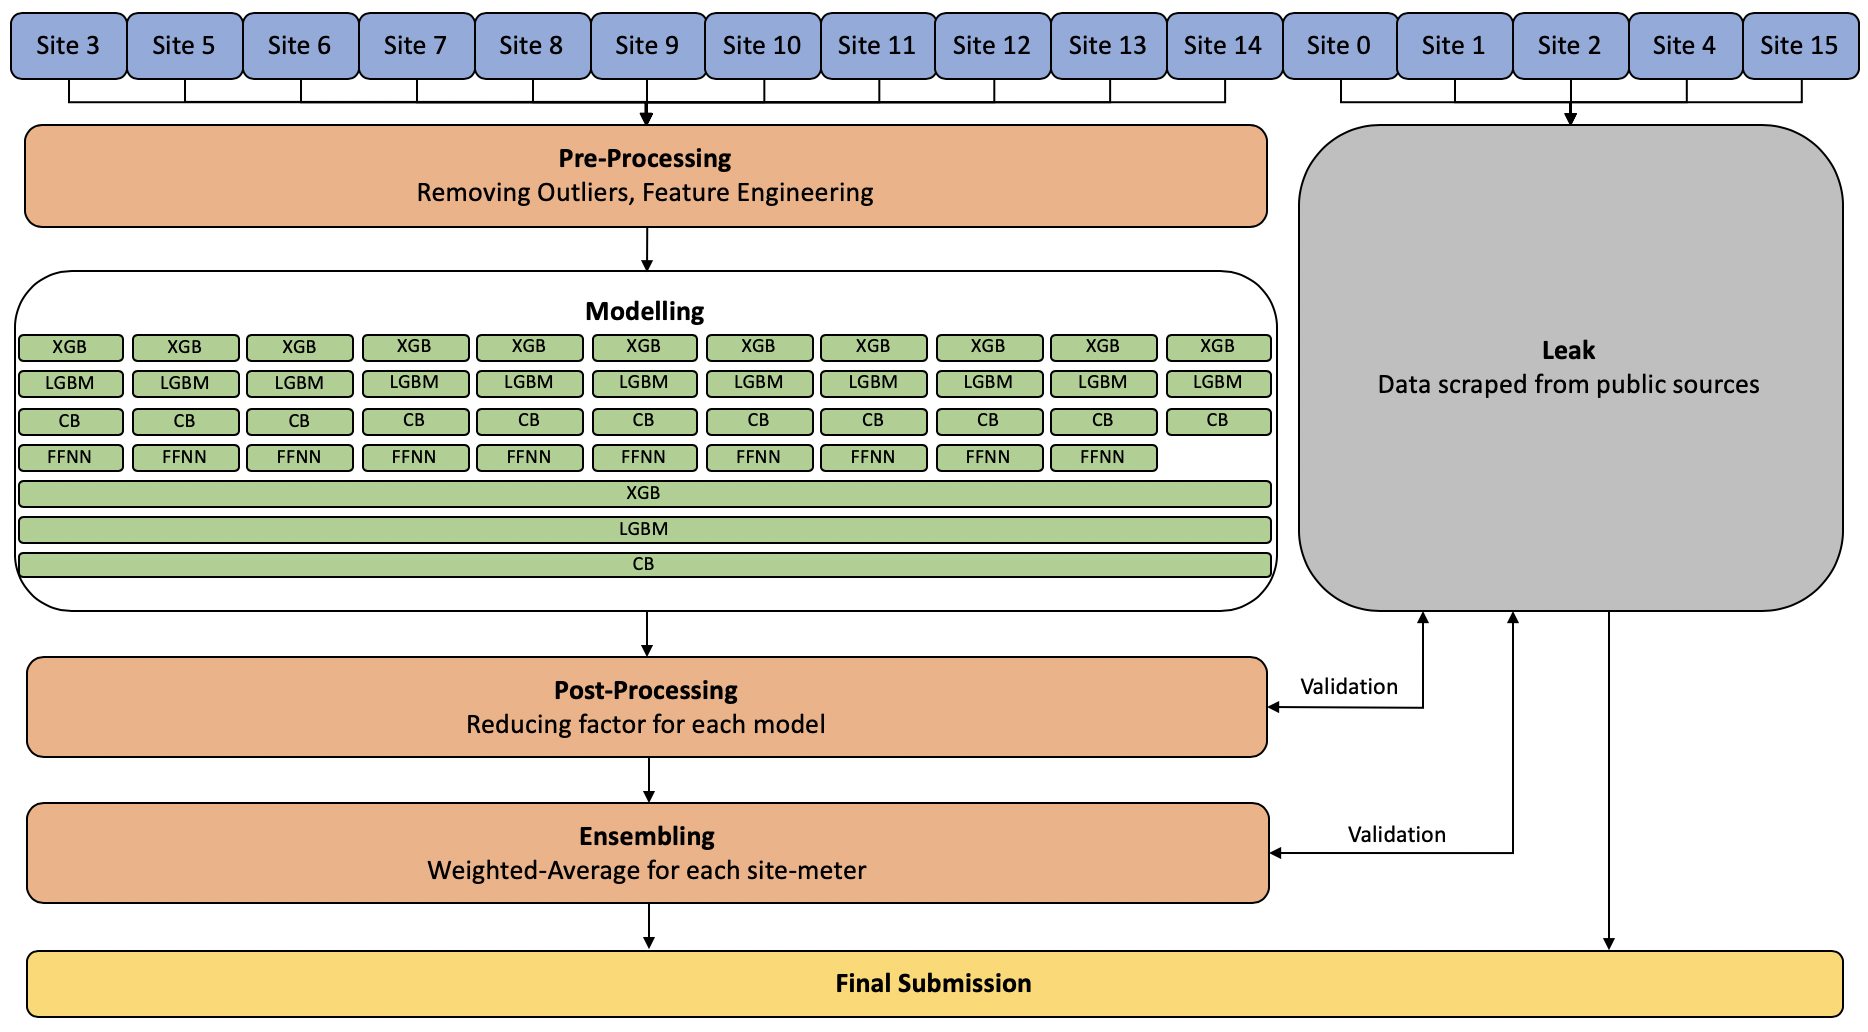\n\n**XGB:** XGBoost\n**LGBM:** LightGBM\n**CB:** Catboost\n**FFNN:** Feed-forward Neural Network\n\n## Short version\n\n- **Remove noise (Very important)**\n- Very few and basic features (For stability)\n- Optimize models for each site+meter (For site-specific patterns)\n- Ensemble of XGBoost, LightGBM, CatBoost, NeuralNetwork (To reduce variance)\n- **Postprocessing (Very critical)**\n- Leak insertion (Sucks, but probably doesn't matter)\n\n**Final Ensemble (approximate):** 30% XGB-bagging + 50% LGBM-bagging + 15% CB-bagging + 5% FFNN\n\nMany variations of XGB, LGBM, CB were bagged: at site+meter level, at building+meter level, at building-type+meter level. Bagged XGB gave the best results among the boosting methods.\n\nFFNN was used only for meter = 0.\nIt gave very poor results for other meters and didn't add value to ensemble.\nAlso, FFNN was very poor for site-14 so we didn't use it and hence that tile is missing from the models section in the architecture diagram :-)\n\nOur solution was built heavily on @oleg90777 's base XGB/LGBM setup (which scores 1.04 on LB without leak) and our key points were cleaning the data and post-processing the predictions (validated on leaked data and LB). Read more about it [here](https://www.kaggle.com/c/ashrae-energy-prediction/discussion/123528).\n\nThe final ensemble scores almost the best on public LB, on leaked data as well as private LB, so hopefully it is robust and useful.\n\n## Long version\n\n### Pre-Processing\nA lot of the low values of the target variable seem to be noise (as discussed multiple times in the forums, specifically for site-0) and removing these rows from the training data gives a good boost in score which has been done by several other competitors too.\n\nIt was the most time consuming task as we visualized and wrote code to remove these rows for each of the 1449 buildings manually. We could have used a set of heuristics but that is not optimal due to some edge cases so we just decided to spend few minutes on every building and remove the outliers.\n\n### Feature Engineering\nDue to the size of the dataset and difficulty in setting up a robust validation framework, we did not focus much on feature engineering, fearing it might not extrapolate cleanly to the test data. Instead we chose to ensemble as many different models as possible to capture more information and help the predictions to be stable across years.\n\nOur models barely use any lag features or complex features. We have less than 30 features in our best single model. This was one of the major decisions taken at the beginning of our work. From past experience it is tricky to build good features without a reliable validation framework.\n\n### Modelling\nWe bagged a bunch of boosting models XGB, LGBM, CB at various levels of data: Models for every site+meter, models for every building+meter, models for every building-type+meter and models using entire train data. It was very useful to build a separate model for each site so that the model could capture site-specific patterns and each site could be fitted with a different parameter set suitable for it. It also automatically solved for issues like timestamp alignment and feature measurement scale being different across sites so we didn't have to solve for them separately.\n\nEnsembling models at different levels were useful to improve score. Just bagging with different seeds didn't help much.\n\nSite-level FFNN was used only for meter = 0. Each site had a different NN architecture.\nIt gave very poor results for other meters and didn't add value to ensemble.\nAlso, FFNN was very poor for site-14 so we didn't use it and hence that tile is missing from the models section in the architecture diagram :-)\n\nFor tuning of all models, we used a combination of 4-fold and 5-fold CV on month from training data as well as validation on leaked data.\n\n### Post-Processing\nWe have shared our post-processing experiments in another thread: https://www.kaggle.com/c/ashrae-energy-prediction/discussion/123528\n\nSince we remove a lot of low value observations from training data, it artificially increases the mean of the target variable and hence the model's raw predictions on test data also has an inflated mean. Since RMSE is optimal at true mean value, reducing the mean of predictions of test data by a reducing factor helps bring it down to its true mean, thus improving score.\n\nWe tried a range of post-processing values and finally ended up using 0.8 - 0.85 for most models.\n\n### Ensembling\nOur best single type model was XGB but LGBM was very close and CB was not very bad either. All scored in the range of 1.04 - 1.06 on the public LB without leak.\n\nSince FFNN was built only for meter = 0, we ensembled differently for every site+meter combination using a weighted average where the weights were determined using a combination of CV score, LB score, Leak score and intuition.\n\n**Final Ensemble (approximate) for meter = 0:** 30% XGB-bagging + 50% LGBM-bagging + 15% CB-bagging + 5% FFNN\n**Final Ensemble (approximate) for meters 1, 2, 3:** 30% XGB-bagging + 50% LGBM-bagging + 20% CB-bagging\n\nThe final ensemble scores almost the best on public LB, on leaked data as well as private LB, so hopefully it is robust and useful.\n\n### Leak\nWe used leak data primarily for local validation and for inserting into the test data as many competitors did. We didn't use any leaks outside of sites 0, 1, 2, 4, 15.\n\nSince our core models were at site+meter level, we didn't explore leveraging the leaked data as additional train data.\n\n### Team\nShout out to my **cHaOs** team-mates @oleg90777 (one of the best team leaders I've worked with), @berserker408 and @isanton.\n\n### Code\nWe will be happy to share our entire code if ASHRAE / Kaggle can confirm if we can. No timeline / commitment on this.\n\n### Credits\n* ASHRAE and Kaggle for hosting this competition.\n* Competitors who scraped data and made it public. You are winners too.\n* Kaggle admins for working hard to make the best out of the leak situation.", "717354": "Congratulations to our second-place team!!!!!! 🙌 💪 👍 👊 Their solution will be organized and added to the other top five winners in a publication and open-source repository. Please stay tuned! \n\n**Also, for everyone else, we are in the process of curating a directory of Notebooks for building performance engineers and analysts from the competition that will serve as a recipe book for beginners as well as experts who are curious to learn about certain topics. We highly encourage you all to share your solutions as a notebook for this purpose. We will acknowledge the authors of all notebooks in this process, so please annotate your notebook or profile with how you would like to be acknowledged. It would also be helpful if you could indicate whether you are an ASHRAE member.**", "705110": "Congrats! Nice ensembling :) ", "705036": "Congratulations! According to:\nhttps://www.kaggle.com/sohier/ashrae-interim-scores#final_all_scores.csv\n\nYou had 6 submissions at 1.22 so your team is the best even if you've selected ones at 1.23. Only Btbpanda had one submission better (but they don't selected it).", "705706": "Congratulations! :D\n\n> Remove noise (Very important)\n\nThis time removing the noise got you to the prize zone! 😁\n\nA little context for everyone, [from H2O.ai's GrandMaster Panel](https://www.h2o.ai/blog/takeaways-from-the-worlds-largest-kaggle-grandmaster-panel/)\n\n> Q: Any mistakes or Regrets from a competition?\n@rohanrao advises looking at outliers, based on a competition where removing just ONE outlier would have landed him 1st position.\n\n", "852791": "Congratulations!\nMany competitors mentioned leak data. I am new for machine learning. Can you explain what's the meaning of 'leak data' in this competition?", "757003": "Thank you for the well explained solution and congratulations with the second place!\nHow did you define outliers for each building? Was it an individual and mostly visual approach or a more standardised one like e.g. based on IQR or similar?", "916265": "Congratulations! 😊 ", "743276": "Congrats,Great!", "722103": "Congratulations!", "717513": "Congratulations! And thanks for sharing!", "716637": "Congratulations!", "716605": " Your idea of thousands of models is incredibly inspiring! ", "716494": "Thanks a lot @rohanrao for Sharing this :)", "716415": "Congratulation", "713697": "Congratulations and thanks for the write-up. ", "713213": "Congratulations! Awesome solution", "713123": "Congratulations!", "712971": "Congratulations!", "711751": "please let me know how are you stacking the models. I mean can we use the outputs of XGB with CATBOOST and followed by NN. I new to this concept. Please elaborate", "711178": "Congrats, really good job!", "711145": "sweet", "710972": "congrats", "710739": "nice", "710737": "nice", "710172": "Hi @oleg90777 , did you also optimize \"num_leaves\" for lightgbm in your baysian optimization?\nyou said max_depth was one of the most important parameters. I am wondering whether number of leaves is also important for lightgbm models.", "710069": "Congratulations and thanks for sharing.\nIt`s very interesting!!", "710055": "Great!", "710046": "Great Work !! :)", "709503": "Great work and thanks for sharing !!!!!!!!!!!!!!", "709421": "wow...!! Nice kernel to start 2020 ...!!! Congrats :-)", "709321": "wow great n congrates", "708606": "@rohanrao Thanks for sharing.\nYou used a lot of models. \nDid you use the same hyperparameter?\nHow did you tun the hyperparameter?", "708540": "Congratulations and thank you for the post. Best regards.", "708516": "This is great and very nicely Explained. Thanks. :)", "708323": "wonderful and very elegant solution, congratz, and thank you for the detailed explanation, the visuals helped a lot!\n\nAre you planning sharing the modeling part as well like you did for post-processing ?", "708003": "Great work @rohanrao Thank you for sharing", "707891": "This is very helpful for how to approach future competitions. Thank you and congratulations!", "707831": "beautiful!upvoted!", "707033": "awesome", "706721": "Congratulations and thank you for the post!", "706148": "Congratulations! Is it possible you could share your notebook I am very intrigued to see it! ", "706044": "@rohanrao Congratulations Rohan on your first money prize in Kaggle . Wishing you a happy new year 2020", "705906": "Congrats!!! Luv to see how the solution was created =)", "705859": "Congrats @rohanrao !!🎉 & Thanks for sharing your insights!!😄 👍 ", "705505": "Congratulations, Vopani!", "705267": "Congratulations", "705204": "Congrats to you and your team. Amazing solution for Ensemble Learning and Thanks for sharing @rohanrao !", "705142": "Great Solution 💪 ", "705123": "Congratulations\nThanks for sharing your Approach & Insights!! @rohanrao ", "705113": "Congratulations!!", "705108": "Congrats! It seems that removing sites 0,1,2,4,15 may have played a role on private LB.", "705075": "Congrats :)", "704942": "Congrats Rohan.", "704885": "Congrats @rohanrao for a well deserved 2nd place finish. I hope I do not wait as long as you did for my elusive solo gold medal? I really thought ASHRAE will be the one but the leak happened everything got messed up but I did not want to give up so here we go.\n\nI look forward to your complete solution. \n\nHappy holidays.", "704882": "Congratulations. I learn a lot from your kernel too.", "704844": "Great work !!by the way,I'm curious about what post processing is?", "712891": "Congratulations .......", "712792": "Wow.\nCongratulations!\nI've learned a lot reading your latest posts. Thanks for sharing and for explaining the bases.", "710854": "Congrats! And thanks a lot for sharing the approach :)", "709373": "Thanks for sharing...........and Happy New Year ", "706521": "Congratulations @rohanrao , thanks a lot for sharing.\nHow did you validate the preprocessing and ensembling using leak data of sites 0-1-2-4-15?\nDid you include sites 0-1-2-4-15 (year 2016) as training data then validate leak data (from years 2017-2018)?\nor did you use the models trained on others sites to validate leak data of sites 0-1-2-4-15? \nDid you find that information from other sites could be beneficial in predicting remaining sites 0-1-2-4-15? \nCheers", "705411": "Congrats, @rohanrao . May I know how did you draw the architecture figure? What software did you use? Thanks!", "716432": "Why did your team use very less feature engineering and settled with about 30 features?", "709574": "Great Kernel ! Great Work ! Very nicely explained. Thanks for sharing :)", "706027": "> We bagged a bunch of boosting models XGB, LGBM, CB at various levels of data: Models for every site+meter, models for every building+meter, models for every building-type+meter.\n\nHow's the performance (lb score) of these 3 types of models? \nAnd what's the 50 features you used? It would be nice if you could share the code ;)", "705613": "", "707691": "Thanks for sharing", "721386": "Thanks for this fantastic post.", "718084": "Thanks for sharing~", "712184": "Congrats, and thank you for sharing.", "711299": "Thanks for sharing! ", "710383": "Congrats! Thanks for sharing :) ", "709067": "Congratulations!\nThanks for sharing", "707892": "Thanks for sharing ! :)", "707367": "Thanks for sharing. Congratulations🔥 ", "707309": "Impressive, thanks for sharing! :)", "706212": "Congratulations...thanks for sharing", "705968": "Congrats and thanks for sharing :)\n", "705620": "congratulation, Thanks for sharing ", "711448": "Thanks for sharing!!", "711440": "Congrats! thanks for sharing", "722211": "Good Kernel 👍 Thanks for sharing" } }