{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"\n# Predict winning probabilities with LightGBM \n\n\n\n## Content\n\n\n\n\n- [1. Import packages and Load data](#1)\n - Key packages: \n - Data processing: pandas, numpy\n - Hyperparameter tunning: hyperopt\n - Maching learning packages: \n - LightGBM: lightgbm\n - scikit-learn\n - Model interpretation: \n - SHapley Additive exPlanations: shap\n - Decision tree visualization: dtreeviz\n - Visualization: matplotlib, seaborn\n \n \n- [2. Data Preprocessing](#2)\n - remove dates (race_date) on which there were less than 8 races\n - remove races in which there were less than 5 horses or more than 12 horses\n - remove 'Hurdle' races\n - remove races with track condition 'Soft'\n - remove races with distance_id>1200\n - remove race_type in Waiver Maiden Claiming, Starter Handicap, Waiver Claiming\n\n- [3. Target Engineering](#3)\n - Use `position_at_finish` (An integer of the horse's finishing position) to engineer a binary target to indicate if a jockey won a race or not. \n\n\n- [4. Feature Engineering](#4)\n - create dummy features for categorical features\n - create features from race_date and post_time\n - create descriptive statistical features\n - jockey: create id for jockey\n - jockey's previous win rate and place rate\n \n \n\n- [5. Hyperparamter Tuning](#5)\n - create training and testing data\n - for training data: create kfold with `rolling-origin forward-validation` method\n - define hyperparameter search space for LightGBM\n - using hyperopt to run TPE search (instead of random search or grid search)\n\n- [6. Feature selection with feature importance and VIF](#6)\n - feature selection based on LightGBM feature importance\n - remove colinearity using VIF\n\n\n- [7. Visualize LightGBM models with dtreeviz](#7)\n - visualize LightGBM models with dtreeviz\n\n- [8. Interpret machine learning models with SHAP](#8)\n - visualize the feature iterations with SHAP\n - visualize each feature's contribution to prediction with SHAP\n\n\n\n \n","metadata":{}},{"cell_type":"markdown","source":"\n\n# Import packages and Load data\n\n[back to top](#toc)\n\n","metadata":{}},{"cell_type":"code","source":"import numpy as np \nimport pandas as pd \nimport matplotlib.pyplot as plt\nimport matplotlib.lines as mlines\nimport pandas as pd\nimport statsmodels.api as sm\nimport seaborn as sns\n\nimport copy\nimport gc\nimport json\nfrom pathlib import Path\nimport sys\nimport os\nimport pickle\nimport joblib\n\nimport pyarrow.parquet as pq\nimport pyarrow as pa\n\n\nfrom datetime import datetime, date, time\n\n\nfrom sklearn.metrics import mean_squared_error, roc_auc_score\nfrom sklearn.metrics import f1_score\nfrom sklearn.model_selection import StratifiedKFold, KFold\n\npd.options.display.max_rows = 100\npd.options.display.max_columns = 100\n\nimport warnings\nwarnings.filterwarnings(\"ignore\")\n\nimport pytorch_lightning as pl\nrandom_seed=1234\npl.seed_everything(random_seed)","metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","_kg_hide-input":true,"_kg_hide-output":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:00.649900Z","iopub.execute_input":"2022-10-04T11:35:00.650381Z","iopub.status.idle":"2022-10-04T11:35:08.363088Z","shell.execute_reply.started":"2022-10-04T11:35:00.650290Z","shell.execute_reply":"2022-10-04T11:35:08.361802Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#/kaggle/input/derby-2022-merge-and-convert-data-to-parquet-file/nyra_2019_complete.parquet\n\nrace_table = pd.read_csv('/kaggle/input/big-data-derby-2022/nyra_race_table.csv')\nstart_table = pd.read_csv('/kaggle/input/big-data-derby-2022/nyra_start_table.csv', header=None)\n# tracking_table = pd.read_csv('/kaggle/input/big-data-derby-2022/nyra_tracking_table.csv')\nstart_table.columns=['track_id', 'race_date', 'race_number', 'program_number', 'weight_carried', 'jockey', 'odds', 'position_at_finish']\n\nstart_table = start_table.merge(race_table, on=['track_id','race_date', 'race_number'], how='inner')","metadata":{"_kg_hide-input":false,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.365257Z","iopub.execute_input":"2022-10-04T11:35:08.366201Z","iopub.status.idle":"2022-10-04T11:35:08.452777Z","shell.execute_reply.started":"2022-10-04T11:35:08.366161Z","shell.execute_reply":"2022-10-04T11:35:08.451379Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n# Data Preprocessing\n\n[back to top](#toc)\n\n\n#### Base on the EDA [here](https://www.kaggle.com/code/xxxxyyyy80008/derby-2022-eda), the following data processing is done:\n\n- remove dates (race_date) on which there were less than 8 races\n- remove races in which there were less than 5 horses or more than 12 horses\n- remove 'Hurdle' races\n- remove races with track condition 'Soft'\n- remove races with distance_id>1200\n- remove race_type in Waiver Maiden Claiming, Starter Handicap, Waiver Claiming","metadata":{}},{"cell_type":"code","source":"race_type_dict = { 'STK': 'Stakes', \n 'WCL': 'Waiver Claiming', \n 'WMC': 'Waiver Maiden Claiming', \n 'SST': 'Starter Stakes', \n 'SHP': 'Starter Handicap',\n 'CLM': 'Claiming', \n 'STR': 'Starter Allowance', \n 'AOC': 'Allowance Optionl Claimer', \n 'SOC': 'Starter Optional Claimer', \n 'MCL': 'Maiden Claiming', \n 'ALW': 'Allowance', \n 'MSW': 'Maiden Special Weight'\n }\n\ntrack_id_dict = dict(AQU = 'Aqueduct', BEL = 'Belmont', SAR = 'Saratoga')\ncourse_type_dict = dict(M = 'Hurdle', D = 'Dirt', O = 'Outer turf', I = 'Inner turf', T = 'turf')\ntrack_condition_dict = dict(YL = 'Yielding', FM ='Firm', SY = 'Sloppy', GD = 'Good', FT = 'Fast', MY = 'Muddy', SF = 'Soft')\n\nstart_table.sort_values(by=['track_id', 'race_date', 'race_number', 'program_number'], ascending=[True]*4, inplace=True)\nstart_table['id'] = range(1, start_table.shape[0] +1)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.454184Z","iopub.execute_input":"2022-10-04T11:35:08.454604Z","iopub.status.idle":"2022-10-04T11:35:08.479214Z","shell.execute_reply.started":"2022-10-04T11:35:08.454571Z","shell.execute_reply":"2022-10-04T11:35:08.478299Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"p=race_table[['race_date', 'race_number']].groupby('race_date').count()\nremove_dates = p[p['race_number']<8].index.tolist()\nprint(remove_dates)\nprint(start_table.shape)\nstart_table.drop(index = start_table[start_table['race_date'].isin(remove_dates)].index, inplace=True)\nprint(start_table.shape)","metadata":{"_kg_hide-input":false,"_kg_hide-output":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.481197Z","iopub.execute_input":"2022-10-04T11:35:08.482240Z","iopub.status.idle":"2022-10-04T11:35:08.502826Z","shell.execute_reply.started":"2022-10-04T11:35:08.482203Z","shell.execute_reply":"2022-10-04T11:35:08.501375Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"p = start_table[['race_date', 'race_number', 'program_number']].groupby(['race_date', 'race_number',]).count()\ncs = p[(p['program_number']<6) | (p['program_number']>12)].reset_index().iloc[:, :2]\ncs = start_table.merge(cs, on=['race_date', 'race_number'], how='inner')\n\n\nprint(start_table.shape)\nstart_table.drop(index = start_table[start_table['id'].isin(cs['id'].values)].index, inplace=True)\nprint(start_table.shape)\n\nprint(start_table.shape)\nstart_table.drop(index = start_table[start_table['distance_id']>1200].index, inplace=True)\nprint(start_table.shape)\n\nprint(start_table.shape)\nstart_table.drop(index = start_table[start_table['track_condition'].isin(['SF',])].index, inplace=True)\nprint(start_table.shape)\n\nrace_types_to_remove = []\nfor k, v in race_type_dict.items():\n if v in ['Waiver Maiden Claiming', 'Starter Handicap', 'Waiver Claiming']:\n race_types_to_remove.append(k)\n \nprint(race_types_to_remove)\n\nprint(start_table.shape)\nstart_table.drop(index = start_table[start_table['race_type'].isin(['WCL', 'WMC', 'SHP'])].index, inplace=True)\n\nprint(start_table.shape)\n\nstart_table.drop(index = start_table[start_table['course_type'].isin(['M',])].index, inplace=True)\nprint(start_table.shape)","metadata":{"_kg_hide-input":false,"_kg_hide-output":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.504853Z","iopub.execute_input":"2022-10-04T11:35:08.505315Z","iopub.status.idle":"2022-10-04T11:35:08.557467Z","shell.execute_reply.started":"2022-10-04T11:35:08.505274Z","shell.execute_reply":"2022-10-04T11:35:08.556173Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n# 3. Target Engineering\n\n[back to top](#toc)\n\n\nUse `position_at_finish` (An integer of the horse's finishing position) to engineer a binary target to indicate if a jockey won a race or not. \n\nIf `position_at_finish == 1` , it means the jockey won a race, the target is 1; otherwise the target is 0.","metadata":{}},{"cell_type":"code","source":"start_table.sort_values(by=['track_id', 'race_date', 'race_number', 'program_number'], ascending=[True]*4, inplace=True)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.559000Z","iopub.execute_input":"2022-10-04T11:35:08.559503Z","iopub.status.idle":"2022-10-04T11:35:08.575171Z","shell.execute_reply.started":"2022-10-04T11:35:08.559472Z","shell.execute_reply":"2022-10-04T11:35:08.574247Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"start_table['target'] = (start_table['position_at_finish']==1).astype(int)\nstart_table['target'].value_counts()","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:08.576449Z","iopub.execute_input":"2022-10-04T11:35:08.577001Z","iopub.status.idle":"2022-10-04T11:35:08.586605Z","shell.execute_reply.started":"2022-10-04T11:35:08.576967Z","shell.execute_reply":"2022-10-04T11:35:08.585368Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"start_table['target'].value_counts()/start_table.shape[0]","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:08.588119Z","iopub.execute_input":"2022-10-04T11:35:08.588467Z","iopub.status.idle":"2022-10-04T11:35:08.599136Z","shell.execute_reply.started":"2022-10-04T11:35:08.588427Z","shell.execute_reply":"2022-10-04T11:35:08.597919Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n# 4. Feature Engineering\n\n[back to top](#toc)\n\n\n#### Feature engineering includes the following:\n\n1. create dummy features for categorical features\n1. create features from race_date and post_time\n1. create descriptive statistical features\n1. jockey: create id for jockey\n1. jockey's previous win rate and place rate","metadata":{}},{"cell_type":"markdown","source":"### create dummy features from categorical features\n\n","metadata":{}},{"cell_type":"code","source":"def post_time_(x):\n #morning: before 1200, -1\n #noon: 1200-1430, 0\n #afternoon: 1430-1830, 1\n #evening: 1830-2400, 2\n v = '1200'\n \n if (x is None)|(x is np.nan):\n v = '1200'\n else:\n x = str(x)\n x1_ = int(x[:-2])\n x2_ = int(x[-2:])\n if x1_<10:\n x1_ = x1_ + 12\n\n v = int(f'{x1_}{x2_}')\n r = -1\n if v<1200:\n r = -1\n elif v<1430:\n r = 0\n elif v<1830:\n r = 1\n else:\n r = 2\n return r","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.600642Z","iopub.execute_input":"2022-10-04T11:35:08.601092Z","iopub.status.idle":"2022-10-04T11:35:08.611025Z","shell.execute_reply.started":"2022-10-04T11:35:08.601051Z","shell.execute_reply":"2022-10-04T11:35:08.609728Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"start_table['race_date'] = pd.to_datetime(start_table['race_date'])\n\nstart_table['weekday'] = start_table['race_date'].dt.weekday\nstart_table['month'] = start_table['race_date'].dt.month\nstart_table['post_time2'] = start_table['post_time'].apply(post_time_)\n\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.615939Z","iopub.execute_input":"2022-10-04T11:35:08.616666Z","iopub.status.idle":"2022-10-04T11:35:08.664799Z","shell.execute_reply.started":"2022-10-04T11:35:08.616615Z","shell.execute_reply":"2022-10-04T11:35:08.663693Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"for column in ['track_id', 'course_type', 'track_condition', 'race_type']:\n dummies_ = pd.get_dummies(start_table[column])\n dummy_feats_ = [f'{column}={cc}' for cc in dummies_.columns]\n dummies_.columns = dummy_feats_\n start_table[dummy_feats_] = dummies_.values","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.666729Z","iopub.execute_input":"2022-10-04T11:35:08.667175Z","iopub.status.idle":"2022-10-04T11:35:08.694193Z","shell.execute_reply.started":"2022-10-04T11:35:08.667132Z","shell.execute_reply":"2022-10-04T11:35:08.693070Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"jockeys = start_table['jockey'].unique().tolist()\njockey_ids = pd.DataFrame(index=jockeys, data={'jockey_id': range(1, len(jockeys)+1)}).to_dict()['jockey_id']\nstart_table['jockey_id'] = start_table['jockey'].map(jockey_ids)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.695739Z","iopub.execute_input":"2022-10-04T11:35:08.696199Z","iopub.status.idle":"2022-10-04T11:35:08.708177Z","shell.execute_reply.started":"2022-10-04T11:35:08.696153Z","shell.execute_reply":"2022-10-04T11:35:08.706530Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### create descriptive statistical features\n\n#### the descriptive statistical features of jockey's performances\n\n- win rate before current rate_date\n- place rate before current rate_date\n- race count before current rate_date\n- win rate/place rate of current course type/track","metadata":{}},{"cell_type":"code","source":"cnt = start_table[['jockey', 'race_date', 'position_at_finish']].groupby(['jockey', 'race_date']).count()\ncnt.columns=['cnt']\n\nwins = start_table.loc[start_table['position_at_finish']<2, \n ['jockey', 'race_date', 'position_at_finish']].groupby(['jockey', 'race_date']).count()\nwins.columns=['win_cnt']\n\nplaces = start_table.loc[start_table['position_at_finish']<4, \n ['jockey', 'race_date', 'position_at_finish']].groupby(['jockey', 'race_date']).count()\nplaces.columns=['place_cnt']\n\n\ncnt = cnt.reset_index()\nwins = wins.reset_index()\nplaces = places.reset_index()\n\n\ncnt.sort_values(by=['jockey', 'race_date'], ascending=[True]*2, inplace=True)\nwins.sort_values(by=['jockey', 'race_date'], ascending=[True]*2, inplace=True)\nplaces.sort_values(by=['jockey', 'race_date'], ascending=[True]*2, inplace=True)\n\ncnt = cnt.merge(wins, on=['jockey', 'race_date'], how='left')\ncnt = cnt.merge(places, on=['jockey', 'race_date'], how='left')\ncnt.fillna(0, inplace=True)\n\n\ncumsum = cnt.groupby('jockey').cumsum()\ncnt['cnt_cumsum'] = cumsum['cnt']\ncnt['win_rate'] = cumsum['win_cnt']/cumsum['cnt']\ncnt['place_rate'] = cumsum['place_cnt']/cumsum['cnt']\n\ncnt_ = cnt.groupby('jockey').shift(1)\n\nfor column in cnt_.columns:\n cnt[f'pre_{column}'] = cnt_[column]\n \ncnt.fillna(0, inplace=True)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.709807Z","iopub.execute_input":"2022-10-04T11:35:08.710203Z","iopub.status.idle":"2022-10-04T11:35:08.839553Z","shell.execute_reply.started":"2022-10-04T11:35:08.710171Z","shell.execute_reply":"2022-10-04T11:35:08.838371Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"print(start_table.shape)\nstart_table = start_table.merge(cnt, on=['jockey', 'race_date'], how='left')\nprint(start_table.shape)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.841125Z","iopub.execute_input":"2022-10-04T11:35:08.841590Z","iopub.status.idle":"2022-10-04T11:35:08.881114Z","shell.execute_reply.started":"2022-10-04T11:35:08.841544Z","shell.execute_reply":"2022-10-04T11:35:08.879890Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"start_table['win'] = (start_table['position_at_finish']<2).astype(int)\nstart_table['place'] = (start_table['position_at_finish']<4).astype(int)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.882637Z","iopub.execute_input":"2022-10-04T11:35:08.883758Z","iopub.status.idle":"2022-10-04T11:35:08.893222Z","shell.execute_reply.started":"2022-10-04T11:35:08.883711Z","shell.execute_reply":"2022-10-04T11:35:08.891846Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"jockeys = start_table['jockey'].value_counts()[start_table['jockey'].value_counts()>=10].index.values.tolist()\n#print(len(jockeys))\nrace_days = race_table['race_date'].unique().tolist()\nrace_days.sort()\n\n\ndata = pd.pivot_table(start_table, index=['race_date'], columns=['jockey'], \n values=['win', 'place'], \n aggfunc={'win': [np.sum, np.size], 'place': np.sum} )\ndata.sort_index(ascending=True, inplace=True)\n\ndfs_pre = []\nfor jk in jockeys:\n\n data_i = data[[('place', 'sum', jk), \n ( 'win', 'size', jk), \n ( 'win', 'sum', jk)]].fillna(0)\n data_i.columns=['place', 'run', 'win']\n\n data_i['plc_sum']=data_i['place'].rolling(31).apply(lambda x: x[:-1].sum())\n data_i['win_sum']=data_i['win'].rolling(31).apply(lambda x: x[:-1].sum())\n data_i['run_sum']=data_i['run'].rolling(31).apply(lambda x: x[:-1].sum())\n\n data_i['plc_rate'] = data_i['plc_sum']/data_i['run_sum']\n data_i['win_rate'] = data_i['win_sum']/data_i['run_sum']\n data_i['jockey']=jk\n \n for col in [ 'plc_rate', 'win_rate']:\n for i in [3, 5, 10]:\n data_i[f'{col}_diff{i}'] = data_i[col].diff(i)\n #dfs_pre.append(data_i.reset_index()[['jockey', 'race_date', 'win_sum', 'plc_sum', 'run_sum', 'plc_rate', 'win_rate']])\n dfs_pre.append(data_i.reset_index())\n \n\ndf_pre = pd.concat(dfs_pre)\n\n","metadata":{"_kg_hide-input":false,"execution":{"iopub.status.busy":"2022-10-04T11:35:08.895034Z","iopub.execute_input":"2022-10-04T11:35:08.895424Z","iopub.status.idle":"2022-10-04T11:35:16.835127Z","shell.execute_reply.started":"2022-10-04T11:35:08.895381Z","shell.execute_reply":"2022-10-04T11:35:16.833823Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"new_cols = []\nfor col in df_pre.columns:\n if col in ['jockey', 'race_date']:\n new_cols.append(col)\n else:\n new_cols.append(f'pre31_{col}')\ndf_pre.columns = new_cols","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:16.836628Z","iopub.execute_input":"2022-10-04T11:35:16.837124Z","iopub.status.idle":"2022-10-04T11:35:16.843335Z","shell.execute_reply.started":"2022-10-04T11:35:16.837089Z","shell.execute_reply":"2022-10-04T11:35:16.842097Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"start_table = start_table.merge(df_pre, on=['jockey', 'race_date'], how='left')","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:16.845094Z","iopub.execute_input":"2022-10-04T11:35:16.845890Z","iopub.status.idle":"2022-10-04T11:35:16.888390Z","shell.execute_reply.started":"2022-10-04T11:35:16.845793Z","shell.execute_reply":"2022-10-04T11:35:16.886884Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"start_table.replace([-np.inf, np.inf], np.nan, inplace=True)\n\nstart_table.isna().sum()[start_table.isna().sum()>0]","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:16.889894Z","iopub.execute_input":"2022-10-04T11:35:16.890803Z","iopub.status.idle":"2022-10-04T11:35:16.950166Z","shell.execute_reply.started":"2022-10-04T11:35:16.890767Z","shell.execute_reply":"2022-10-04T11:35:16.948715Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"start_table.fillna(0, inplace=True)\nstart_table.isna().sum()[start_table.isna().sum()>0]","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:16.951956Z","iopub.execute_input":"2022-10-04T11:35:16.952454Z","iopub.status.idle":"2022-10-04T11:35:17.051151Z","shell.execute_reply.started":"2022-10-04T11:35:16.952407Z","shell.execute_reply":"2022-10-04T11:35:17.050039Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n\n# 5. Hyperparamter Tuning\n\n[back to top](#toc)\n\n\n### The training setup\n\n- train data: From Jan to Jul\n- validation data: From Aug to Sep\n- testing data: From Oct to Dec\n\n\n### Hyperparameter tuning via hyperopt\n\nHyperparameter tunning is done on `train data` and data is split into 3-kfold. The kfold setup is called `rolling-origin forward-validation` based on this paper: [\"A comparison of machine learning model validation schemes for non-stationary time series data,\" FAU Discussion Papers in Economics 11/2019, Friedrich-Alexander University Erlangen-Nuremberg, Institute for Economics.](https://www.econstor.eu/bitstream/10419/209136/1/1684440068.pdf)\n\n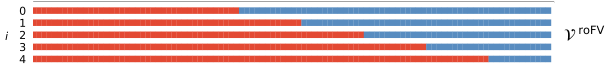\n\n\n### Hyperparameter tuning metrics - AUC\n\nAUC is selected given the imbalanced nature of the dataset.\n\n### Hyperparameter search space\n\n\n\n- max_depth: set the depth very small in order to build very shallow trees (instead of deep trees)\n- n_estimators: set the range to be 600 to 1k+. Larger boosting rounds to gradually improve over shallow trees.","metadata":{}},{"cell_type":"code","source":"feats = [\n 'weight_carried', 'odds', 'distance_id',\n 'run_up_distance', \n 'purse', 'weekday', 'month', 'post_time2',\n 'track_id=AQU', 'track_id=BEL', 'track_id=SAR', 'course_type=D',\n 'course_type=I', 'course_type=O', 'course_type=T',\n 'track_condition=FM ', 'track_condition=FT ', 'track_condition=GD ',\n 'track_condition=MY ', 'track_condition=SF ', 'track_condition=SY ',\n 'track_condition=YL ', 'race_type=ALW', 'race_type=AOC',\n 'race_type=CLM', 'race_type=MCL', 'race_type=MSW', 'race_type=SOC',\n 'race_type=SST', 'race_type=STK', 'race_type=STR', 'jockey_id', \n 'pre_cnt', 'pre_win_cnt', 'pre_place_cnt',\n 'pre_cnt_cumsum', 'pre_win_rate', 'pre_place_rate',\n 'pre31_place', 'pre31_run', 'pre31_win', 'pre31_plc_sum',\n 'pre31_win_sum', 'pre31_run_sum', 'pre31_plc_rate', 'pre31_win_rate',\n 'pre31_plc_rate_diff3', 'pre31_plc_rate_diff5', 'pre31_plc_rate_diff10',\n 'pre31_win_rate_diff3', 'pre31_win_rate_diff5',\n 'pre31_win_rate_diff10',\n]\nlen(feats)","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:17.052438Z","iopub.execute_input":"2022-10-04T11:35:17.053080Z","iopub.status.idle":"2022-10-04T11:35:17.063698Z","shell.execute_reply.started":"2022-10-04T11:35:17.053044Z","shell.execute_reply":"2022-10-04T11:35:17.062770Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"start_table['race_date'].max()","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:17.064868Z","iopub.execute_input":"2022-10-04T11:35:17.065673Z","iopub.status.idle":"2022-10-04T11:35:17.081277Z","shell.execute_reply.started":"2022-10-04T11:35:17.065623Z","shell.execute_reply":"2022-10-04T11:35:17.080155Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train_start, train_end = '2019-02-01', '2019-10-15'\ntest_start, test_end = '2019-10-15', '2020-01-01'","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:17.084975Z","iopub.execute_input":"2022-10-04T11:35:17.085447Z","iopub.status.idle":"2022-10-04T11:35:17.092109Z","shell.execute_reply.started":"2022-10-04T11:35:17.085409Z","shell.execute_reply":"2022-10-04T11:35:17.090977Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"df_train = start_table[(start_table['race_date']>=train_start) & (start_table['race_date']=test_start) & (start_table['race_date']0]","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:17.122311Z","iopub.execute_input":"2022-10-04T11:35:17.122827Z","iopub.status.idle":"2022-10-04T11:35:17.147231Z","shell.execute_reply.started":"2022-10-04T11:35:17.122780Z","shell.execute_reply":"2022-10-04T11:35:17.145936Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"kfold = []\nfor i in [5, 7, 9]: \n X_train = df_train.loc[(df_train['race_date']>=train_start) & (df_train['race_date']=train_start) & (df_train['race_date']=f'2019-0{i}-01') & (df_train['race_date']=f'2019-0{i}-01') & (df_train['race_date']=0.9).astype(int))\n losses.append(loss)\n #-----end: train trees---------------------------------------\n \n loss = np.mean(losses)\n #print(loss)\n loss_dict.append({'params': params, 'losses': losses, 'mean_loss': loss})\n return {'loss': -loss, 'status': STATUS_OK}","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:18.358918Z","iopub.execute_input":"2022-10-04T11:35:18.359838Z","iopub.status.idle":"2022-10-04T11:35:18.370605Z","shell.execute_reply.started":"2022-10-04T11:35:18.359787Z","shell.execute_reply":"2022-10-04T11:35:18.369429Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"from hyperopt import hp\nfrom hyperopt import fmin, tpe, hp, STATUS_OK, Trials, anneal, rand\nfrom hyperopt import space_eval\nfrom functools import partial\ndef optimize(space, evals, cores, trials, optimizer=tpe.suggest, random_state=1234, n_startup_jobs=10):\n algo = partial(optimizer, n_startup_jobs=n_startup_jobs)\n best = fmin(score, space, algo=algo, max_evals=evals, trials = trials)\n bestparams = space_eval(space, best)\n print(bestparams)\n return bestparams","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:18.372737Z","iopub.execute_input":"2022-10-04T11:35:18.373534Z","iopub.status.idle":"2022-10-04T11:35:18.389008Z","shell.execute_reply.started":"2022-10-04T11:35:18.373484Z","shell.execute_reply":"2022-10-04T11:35:18.387723Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"iter_dict = {}\nfor iter_i in range(10):\n print(datetime.now(), iter_i)\n cores = 8\n n_trials = 100\n n_rand_trials = 20\n verbose = False\n trials = Trials()\n\n best_param = optimize(space,\n evals = n_trials,\n optimizer=tpe.suggest,\n cores = cores,\n trials = trials, random_state=1234, \n n_startup_jobs=n_rand_trials)\n \n iter_dict[iter_i] = best_param","metadata":{"execution":{"iopub.status.busy":"2022-10-04T11:35:18.390335Z","iopub.execute_input":"2022-10-04T11:35:18.390765Z","iopub.status.idle":"2022-10-04T12:05:57.132824Z","shell.execute_reply.started":"2022-10-04T11:35:18.390733Z","shell.execute_reply":"2022-10-04T12:05:57.131501Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"df_params = pd.DataFrame(iter_dict).T\ndf_params","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:05:57.134182Z","iopub.execute_input":"2022-10-04T12:05:57.134524Z","iopub.status.idle":"2022-10-04T12:05:57.167177Z","shell.execute_reply.started":"2022-10-04T12:05:57.134493Z","shell.execute_reply":"2022-10-04T12:05:57.166103Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"from tabulate import tabulate\nprint(tabulate(df_params, showindex=False,#headers=df_params.columns, \n tablefmt='github'))","metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"execution":{"iopub.status.busy":"2022-10-04T12:05:57.168409Z","iopub.execute_input":"2022-10-04T12:05:57.168756Z","iopub.status.idle":"2022-10-04T12:05:57.183909Z","shell.execute_reply.started":"2022-10-04T12:05:57.168725Z","shell.execute_reply":"2022-10-04T12:05:57.183016Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Feature Importance\n\n#### Use the best hyperparameter set from tuning process on whole train dataset and check the feature importance.","metadata":{}},{"cell_type":"code","source":"def bar(data, caption, sub_title='', figsize=(12, 6)):\n if data.index.dtype in ['int64', 'int32', 'float64', 'float32']:\n data.index = data.index.astype(str)\n\n plt.figure(figsize=figsize)\n plt.style.use('seaborn-whitegrid')\n plt.barh(data.index.values, data.values, color=\"lightseagreen\")\n for i, v in enumerate(data.values):\n plt.text(v + 3.9, i + .025, f'{v:.0f}', fontsize=12, color=\"teal\",fontweight='bold')#deepskyblue#dodgerblue\n \n \n plt.suptitle(caption,fontsize=15, y=0.89, x=0.2)\n plt.title(sub_title,fontsize=13, y=0.96, loc='left') \n #plt.xlabel(data.name, fontsize=13)\n plt.xlabel('', fontsize=13)\n plt.xticks([])\n plt.grid(visible=True, which='major', axis='both', color='lightgray', linestyle='-', linewidth=0.2)\n plt.gca().spines[['top', 'right']].set_visible(False)\n plt.gca().spines[['bottom', 'left']].set_edgecolor('whitesmoke')\n plt.rc('ytick', labelsize=13, ) \n \n plt.show()\n ","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:05:57.185905Z","iopub.execute_input":"2022-10-04T12:05:57.186775Z","iopub.status.idle":"2022-10-04T12:05:57.198578Z","shell.execute_reply.started":"2022-10-04T12:05:57.186728Z","shell.execute_reply":"2022-10-04T12:05:57.197270Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"models_dict = {}\n\nfor iter_i, params in iter_dict.items():\n\n params = copy.deepcopy(params)\n num_boost_round = params['n_estimators']\n del params['n_estimators']\n\n\n tree_model = train_trees(df_train[feats], df_train['target'].values,\n num_round=num_boost_round, \n params=params\n )\n\n y_preds = tree_model.predict(df_test[feats], num_iteration=tree_model.best_iteration)\n loss = roc_auc_score(df_test['target'], y_preds)\n models_dict[iter_i] = tree_model\n print(f'{iter_i}: auc on testing data: {loss: .04f}')\n ","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:05:57.200816Z","iopub.execute_input":"2022-10-04T12:05:57.201285Z","iopub.status.idle":"2022-10-04T12:06:06.892283Z","shell.execute_reply.started":"2022-10-04T12:05:57.201238Z","shell.execute_reply":"2022-10-04T12:06:06.891337Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"scores_dfs = []\n\nfor iter_i, tree_model in models_dict.items():\n scores_ = pd.DataFrame(data = {'feat': feats, 'gain': tree_model.feature_importance()})\n gain_cut = 0.01*scores_['gain'].sort_values(ascending=False).head(5).mean()\n \n ss = scores_[scores_['gain']>gain_cut].sort_values(by='gain')\n ss['gain_z'] = (ss['gain'] - ss['gain'].min())/(ss['gain'].quantile(q=0.95)-ss['gain'].quantile(q=0.05))\n\n ss.reset_index(drop=True, inplace=True)\n ss['rank']=range(ss.shape[0], 0, -1)\n scores_dfs.append(ss)","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:06.896567Z","iopub.execute_input":"2022-10-04T12:06:06.897520Z","iopub.status.idle":"2022-10-04T12:06:06.958693Z","shell.execute_reply.started":"2022-10-04T12:06:06.897478Z","shell.execute_reply":"2022-10-04T12:06:06.957548Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"all_scores = pd.concat(scores_dfs, axis=0)","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:06.960360Z","iopub.execute_input":"2022-10-04T12:06:06.961102Z","iopub.status.idle":"2022-10-04T12:06:06.969846Z","shell.execute_reply.started":"2022-10-04T12:06:06.961055Z","shell.execute_reply":"2022-10-04T12:06:06.968223Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"imp = pd.pivot_table(all_scores, \n index='feat', \n values=['gain_z'], \n aggfunc={'gain_z':[np.mean, np.size],\n }\n )\nimp.columns = ['score', 'cnt']\nimp.sort_values(by='score', ascending=True, inplace=True)\n\nimp['score'] = 100*imp['score']","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:06.971230Z","iopub.execute_input":"2022-10-04T12:06:06.971563Z","iopub.status.idle":"2022-10-04T12:06:06.992706Z","shell.execute_reply.started":"2022-10-04T12:06:06.971535Z","shell.execute_reply":"2022-10-04T12:06:06.991325Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"bar(imp[imp['score']>1]['score'], caption='Feature importance', \n sub_title=\"\", \n figsize=(12, 14))","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:15:27.937823Z","iopub.execute_input":"2022-10-04T12:15:27.938291Z","iopub.status.idle":"2022-10-04T12:15:28.426855Z","shell.execute_reply.started":"2022-10-04T12:15:27.938254Z","shell.execute_reply":"2022-10-04T12:15:28.425677Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n\n# 6. Feature selection with feature importance and VIF\n\n[back to top](#toc)\n\nAfter removing the colinear featurs using VIF, the final set of features is fit into data before the testing period on the best hyperparameters. Model is then used to predict the probability of winning in testing data.","metadata":{}},{"cell_type":"markdown","source":"### Variance Inflation Factor (VIF)\n\nVariance inflation factor (VIF) is a measure of the amount of multicollinearity in a set of multiple regression variables. Mathematically, the VIF for a regression model variable is equal to the ratio of the overall model variance to the variance of a model that includes only that single independent variable. This ratio is calculated for each independent variable. A high VIF indicates that the associated independent variable is highly collinear with the other variables in the model.","metadata":{}},{"cell_type":"code","source":"#https://www.kaggle.com/code/aryansharma19/kernel155859d423\n#https://www.kaggle.com/code/remilpm/logistics-regression-on-heart-attack\n#https://www.kaggle.com/code/remilpm/how-to-remove-multicollinearity\n#https://www.kaggle.com/code/tilii7/removing-colinearity-0-5878-with-5-features\n#https://www.kaggle.com/code/ffisegydd/sklearn-multicollinearity-class\n##https://www.kaggle.com/code/derekpisner/fast-reduce-vif-transformer-for-sklearn\n#https://stats.stackexchange.com/a/253620/53565\n\n \n# The statsmodel function will fail with NaN values, as such we have to impute them.\n\nfrom statsmodels.stats.outliers_influence import variance_inflation_factor\nfrom sklearn.base import BaseEstimator, TransformerMixin\n\nclass ReduceVIF(BaseEstimator, TransformerMixin):\n def __init__(self, thresh=5.0):\n\n self.thresh = thresh\n\n \n\n def fit(self, X):\n print('ReduceVIF fit')\n\n return self\n\n def transform(self, X):\n print('ReduceVIF transform')\n columns = X.columns.tolist()\n\n return ReduceVIF.calculate_vif(X, self.thresh)\n\n @staticmethod\n def calculate_vif(X, thresh=5.0):\n # Taken from https://stats.stackexchange.com/a/253620/53565 and modified\n dropped=True\n while dropped:\n variables = X.columns\n dropped = False\n vif = [variance_inflation_factor(X[variables].values, X.columns.get_loc(var)) for var in X.columns]\n vif = np.array(vif)\n max_vif = max(vif)\n if max_vif > thresh:\n maxloc = list(vif).index(vif[vif>thresh][0])\n print(f'Dropping {X.columns[maxloc]} with vif={max_vif}')\n X = X.drop([X.columns.tolist()[maxloc]], axis=1)\n dropped=True\n return X\n","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:07.512164Z","iopub.execute_input":"2022-10-04T12:06:07.512701Z","iopub.status.idle":"2022-10-04T12:06:07.530116Z","shell.execute_reply.started":"2022-10-04T12:06:07.512632Z","shell.execute_reply":"2022-10-04T12:06:07.528506Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"transformer = ReduceVIF(thresh=20)\n\n\nX = transformer.fit_transform(df_train[imp[imp['score']>1].sort_values(by='score', ascending=True).index.values])\n\nfinal_feats = X.columns.tolist()\nprint(X.shape)\nX.head()","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:07.531533Z","iopub.execute_input":"2022-10-04T12:06:07.531939Z","iopub.status.idle":"2022-10-04T12:06:13.765561Z","shell.execute_reply.started":"2022-10-04T12:06:07.531904Z","shell.execute_reply":"2022-10-04T12:06:13.764389Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"bar(imp.loc[final_feats,'score'], caption='Feature importance of selected features after VIF', \n sub_title=\"\", \n figsize=(12, 14))","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:13.767059Z","iopub.execute_input":"2022-10-04T12:06:13.767882Z","iopub.status.idle":"2022-10-04T12:06:14.158258Z","shell.execute_reply.started":"2022-10-04T12:06:13.767835Z","shell.execute_reply":"2022-10-04T12:06:14.156908Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n# 7. Visualize LightGBM Trees with dtreeviz\n\n[back to top](#toc)","metadata":{}},{"cell_type":"code","source":"test_models_dict = {}\ndf_pred = pd.DataFrame(data={'target': df_test['target'].values})\n\nfor iter_i, params in iter_dict.items():\n \n params = copy.deepcopy(params)\n num_boost_round = params['n_estimators']\n del params['n_estimators']\n\n\n tree_model = train_trees(df_train[final_feats], df_train['target'].values,\n num_round=num_boost_round, \n params=params\n )\n\n y_preds = tree_model.predict(df_test[final_feats], num_iteration=tree_model.best_iteration)\n loss = roc_auc_score(df_test['target'], y_preds)\n test_models_dict[iter_i] = tree_model\n df_pred[f'pred{iter_i}'] = y_preds\n print(f'{iter_i}: auc on testing data: {loss: .04f}')","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:14.159810Z","iopub.execute_input":"2022-10-04T12:06:14.160173Z","iopub.status.idle":"2022-10-04T12:06:21.609419Z","shell.execute_reply.started":"2022-10-04T12:06:14.160139Z","shell.execute_reply":"2022-10-04T12:06:21.608269Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#https://github.com/parrt/dtreeviz/blob/master/notebooks/dtreeviz_lightgbm_visualisations.ipynb\nlgb.create_tree_digraph(test_models_dict[0], tree_index=1, orientation = \"vertical\", show_info=['internal_count', 'leaf_count', 'internal_value'])\n","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:21.610787Z","iopub.execute_input":"2022-10-04T12:06:21.611146Z","iopub.status.idle":"2022-10-04T12:06:22.848595Z","shell.execute_reply.started":"2022-10-04T12:06:21.611113Z","shell.execute_reply":"2022-10-04T12:06:22.847189Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#https://github.com/parrt/dtreeviz/blob/master/notebooks/dtreeviz_lightgbm_visualisations.ipynb\nlgb.create_tree_digraph(test_models_dict[9], tree_index=100, orientation = \"vertical\", show_info=['internal_count', 'leaf_count', 'internal_value'])\n","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:22.850458Z","iopub.execute_input":"2022-10-04T12:06:22.850894Z","iopub.status.idle":"2022-10-04T12:06:22.924314Z","shell.execute_reply.started":"2022-10-04T12:06:22.850850Z","shell.execute_reply":"2022-10-04T12:06:22.923251Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#https://github.com/parrt/dtreeviz/blob/master/notebooks/dtreeviz_lightgbm_visualisations.ipynb\nlgb.create_tree_digraph(test_models_dict[9], tree_index=600, orientation = \"vertical\", show_info=['internal_count', 'leaf_count', 'internal_value'])\n","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:22.926736Z","iopub.execute_input":"2022-10-04T12:06:22.927820Z","iopub.status.idle":"2022-10-04T12:06:23.000157Z","shell.execute_reply.started":"2022-10-04T12:06:22.927776Z","shell.execute_reply":"2022-10-04T12:06:22.998746Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#https://github.com/parrt/dtreeviz\n!pip uninstall python-graphviz\n!pip install dtreeviz # install dtreeviz for sklearn\n# pip install dtreeviz[xgboost] # install XGBoost related dependency\n# pip install dtreeviz[pyspark] # install pyspark related dependency\n!pip install dtreeviz[lightgbm] # install LightGBM related dependency","metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"scrolled":true,"execution":{"iopub.status.busy":"2022-10-04T12:06:23.002781Z","iopub.execute_input":"2022-10-04T12:06:23.003631Z","iopub.status.idle":"2022-10-04T12:06:52.943301Z","shell.execute_reply.started":"2022-10-04T12:06:23.003576Z","shell.execute_reply":"2022-10-04T12:06:52.941538Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"from dtreeviz import trees\nfrom dtreeviz.models.lightgbm_decision_tree import ShadowLightGBMTree","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:52.946285Z","iopub.execute_input":"2022-10-04T12:06:52.946799Z","iopub.status.idle":"2022-10-04T12:06:53.151028Z","shell.execute_reply.started":"2022-10-04T12:06:52.946753Z","shell.execute_reply":"2022-10-04T12:06:53.149722Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"light_dtree = ShadowLightGBMTree(test_models_dict[9], tree_index=1, x_data=df_train[final_feats], \n y_data=df_train['target'].values, feature_names=final_feats, \n target_name='target', class_names=[0,1] )\n","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:53.152864Z","iopub.execute_input":"2022-10-04T12:06:53.153265Z","iopub.status.idle":"2022-10-04T12:06:53.189789Z","shell.execute_reply.started":"2022-10-04T12:06:53.153228Z","shell.execute_reply":"2022-10-04T12:06:53.188229Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"raw","source":"trees.dtreeviz(light_dtree)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T12:15:51.369510Z","iopub.execute_input":"2022-10-04T12:15:51.369998Z","iopub.status.idle":"2022-10-04T12:15:51.979269Z","shell.execute_reply.started":"2022-10-04T12:15:51.369943Z","shell.execute_reply":"2022-10-04T12:15:51.977671Z"}}},{"cell_type":"code","source":"trees.viz_leaf_samples(light_dtree)","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:53.191213Z","iopub.execute_input":"2022-10-04T12:06:53.192123Z","iopub.status.idle":"2022-10-04T12:06:53.396785Z","shell.execute_reply.started":"2022-10-04T12:06:53.192084Z","shell.execute_reply":"2022-10-04T12:06:53.395378Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"trees.ctreeviz_leaf_samples(light_dtree)","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:53.398396Z","iopub.execute_input":"2022-10-04T12:06:53.398821Z","iopub.status.idle":"2022-10-04T12:06:53.673968Z","shell.execute_reply.started":"2022-10-04T12:06:53.398783Z","shell.execute_reply":"2022-10-04T12:06:53.672729Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"trees.describe_node_sample(light_dtree, node_id=5)","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:53.675572Z","iopub.execute_input":"2022-10-04T12:06:53.676139Z","iopub.status.idle":"2022-10-04T12:06:53.762903Z","shell.execute_reply.started":"2022-10-04T12:06:53.676102Z","shell.execute_reply":"2022-10-04T12:06:53.761644Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"x_ = df_train[final_feats].iloc[-10]\nprint(x_)","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:16:17.313517Z","iopub.execute_input":"2022-10-04T12:16:17.314037Z","iopub.status.idle":"2022-10-04T12:16:17.324273Z","shell.execute_reply.started":"2022-10-04T12:16:17.314000Z","shell.execute_reply":"2022-10-04T12:16:17.322849Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"print(trees.explain_prediction_path(light_dtree, x=x_))\n","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:16:18.774703Z","iopub.execute_input":"2022-10-04T12:16:18.775097Z","iopub.status.idle":"2022-10-04T12:16:18.781329Z","shell.execute_reply.started":"2022-10-04T12:16:18.775066Z","shell.execute_reply":"2022-10-04T12:16:18.780204Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n\n# 8. Interpret machine learning models with SHAP\n\n[back to top](#toc)\n\nAfter removing the colinear featurs using VIF, the final set of features is fit into data before the testing period on the best hyperparameters. Model is then used to predict the probability of winning in testing data.","metadata":{}},{"cell_type":"code","source":"df_pred['mean_pred'] = df_pred[[f'pred{i}' for i in test_models_dict.keys()]].mean(axis=1)","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:27:38.067118Z","iopub.execute_input":"2022-10-04T12:27:38.067491Z","iopub.status.idle":"2022-10-04T12:27:38.075554Z","shell.execute_reply.started":"2022-10-04T12:27:38.067461Z","shell.execute_reply":"2022-10-04T12:27:38.074416Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"df_pred['mean_pred'].hist()","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:27:38.453775Z","iopub.execute_input":"2022-10-04T12:27:38.454181Z","iopub.status.idle":"2022-10-04T12:27:38.696575Z","shell.execute_reply.started":"2022-10-04T12:27:38.454149Z","shell.execute_reply":"2022-10-04T12:27:38.695452Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"import shap","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:27:41.061039Z","iopub.execute_input":"2022-10-04T12:27:41.061464Z","iopub.status.idle":"2022-10-04T12:27:41.066220Z","shell.execute_reply.started":"2022-10-04T12:27:41.061431Z","shell.execute_reply":"2022-10-04T12:27:41.065418Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"tree_model = test_models_dict[0]\nexplainer = shap.TreeExplainer(tree_model, num_iteration=tree_model.best_iteration)\nshap_values = explainer.shap_values(df_test[final_feats])\n\nexpected_value = explainer.expected_value\nif isinstance(expected_value, list):\n expected_value = expected_value[1]\nprint(f\"Explainer expected value: {expected_value}\")","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:27:42.955166Z","iopub.execute_input":"2022-10-04T12:27:42.956017Z","iopub.status.idle":"2022-10-04T12:27:43.179993Z","shell.execute_reply.started":"2022-10-04T12:27:42.955968Z","shell.execute_reply":"2022-10-04T12:27:43.178975Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"#### SHAP feature importance\n\nThe following stacked bar chart generated by SHAP shows how each feature played its role in making the predictions of probability of winning on testing dataset.\n\nAs clearly shown in the chart, `odds` is most important in prediction the label (i.e. target) to be 0 or 1.\n\nJockey and jockey's previous performances such as win rate and place rate are also very important.","metadata":{}},{"cell_type":"code","source":"shap.summary_plot(shap_values, df_test[final_feats])","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:27:45.414415Z","iopub.execute_input":"2022-10-04T12:27:45.415071Z","iopub.status.idle":"2022-10-04T12:27:45.944393Z","shell.execute_reply.started":"2022-10-04T12:27:45.415035Z","shell.execute_reply":"2022-10-04T12:27:45.942962Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"#### Feature dependence/interactions \n\nThe following scatter plot shows how `odds` feature and `pre_win_rate` (a jockey's previous winning rate prior to the current race date) interact with each other in making the final probabilities.\n\nThe first graph shows that when a jockey has a low `pre_win_rate` (i.e. not very good track record of winning races), the odds of the jockey winning are typically high (meaning not much chance of winning) and the changes in odds do not really have much impact on final predictions.\n\nHowever, when a jockey has a good track record - namely high previous win rate, the lower the odds, the higher the predicted probability of winning.\n","metadata":{}},{"cell_type":"code","source":"for name in ['odds', 'pre_win_rate', 'pre31_win']:\n shap.dependence_plot(name, shap_values[1], df_test[final_feats])","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:27:47.208012Z","iopub.execute_input":"2022-10-04T12:27:47.208577Z","iopub.status.idle":"2022-10-04T12:27:48.495882Z","shell.execute_reply.started":"2022-10-04T12:27:47.208395Z","shell.execute_reply":"2022-10-04T12:27:48.494424Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"#### Interpret model predictions\n\nThe following charts are showing two cases: 1. Model correctly predicted a hockey's winning (True Positive). 2. Model incorrectly predicted a hockey's winning (False Positive).\n\nSuccessfully predicting a winning and making bets based on such predictions can potentially render financial gain; while making bets on predictions that eventually proves to be incorrect can cause financial losses. \n","metadata":{}},{"cell_type":"code","source":"def diverge_bar(data, caption='', value_column='shap_z', color_column='color', label_coloumn='feat', figsize=(12, 6)):\n # Draw plot\n plt.figure(figsize=figsize, dpi= 100)\n plt.hlines(y=data.index, xmin=0, xmax=data[value_column], color=data[color_column].values, alpha=0.9, linewidth=6)\n \n for x, y, tex in zip(data[value_column], data.index, data[value_column]):\n t = plt.text(x, y, round(tex, 2), horizontalalignment='right' if x < 0 else 'left',\n verticalalignment='center', fontdict={'color':'red' if x > 0 else 'green', 'size':10})\n\n plt.title(caption, fontsize=13, loc='left')\n\n plt.grid(visible=True, which='major', axis='both', color='lightgray', linestyle='-', linewidth=0.2)\n plt.gca().spines[['top', 'right']].set_visible(False)\n plt.gca().spines[['bottom', 'left']].set_edgecolor('whitesmoke')\n \n plt.yticks(data.index, data[label_coloumn], fontsize=10)#rotation=90\n plt.xticks(fontsize=9, )#rotation=90\n plt.tight_layout()\n plt.show()\n ","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T12:28:02.039389Z","iopub.execute_input":"2022-10-04T12:28:02.040229Z","iopub.status.idle":"2022-10-04T12:28:02.051440Z","shell.execute_reply.started":"2022-10-04T12:28:02.040188Z","shell.execute_reply":"2022-10-04T12:28:02.050153Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:06:53.812218Z","iopub.execute_input":"2022-10-04T12:06:53.813505Z","iopub.status.idle":"2022-10-04T12:06:53.827127Z","shell.execute_reply.started":"2022-10-04T12:06:53.813458Z","shell.execute_reply":"2022-10-04T12:06:53.825813Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"prob_cut = 0.9\n\ntrue_pos = df_pred[(df_pred['mean_pred']>prob_cut) & (df_pred['target']==1)].index[0]\nfalse_pos = df_pred[(df_pred['mean_pred']>prob_cut) & (df_pred['target']==0)].index[0]\ntrue_pos, false_pos","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:28:55.475530Z","iopub.execute_input":"2022-10-04T12:28:55.475980Z","iopub.status.idle":"2022-10-04T12:28:55.491412Z","shell.execute_reply.started":"2022-10-04T12:28:55.475943Z","shell.execute_reply":"2022-10-04T12:28:55.490096Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"#### First we look at a True Positive case. \n","metadata":{}},{"cell_type":"code","source":"df_test.iloc[true_pos].head(15)","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:29:08.162782Z","iopub.execute_input":"2022-10-04T12:29:08.163191Z","iopub.status.idle":"2022-10-04T12:29:08.173504Z","shell.execute_reply.started":"2022-10-04T12:29:08.163161Z","shell.execute_reply":"2022-10-04T12:29:08.171708Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"true_pos_by = (start_table['track_id']==df_test.iloc[true_pos]['track_id'])\ntrue_pos_by = true_pos_by & (start_table['race_date']==df_test.iloc[true_pos]['race_date'].strftime('%Y-%m-%d'))\ntrue_pos_by = true_pos_by & (start_table['race_number']==df_test.iloc[true_pos]['race_number'])\n\nstart_table[true_pos_by].iloc[:,:15]","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:29:08.618201Z","iopub.execute_input":"2022-10-04T12:29:08.619023Z","iopub.status.idle":"2022-10-04T12:29:08.644766Z","shell.execute_reply.started":"2022-10-04T12:29:08.618981Z","shell.execute_reply":"2022-10-04T12:29:08.643535Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"X_display = df_test[final_feats].iloc[true_pos:(true_pos+1)] #examine one date. this is a data frame\nshap_values = explainer.shap_values(X_display)[1] #shap values for the row\nshap_interaction_values = explainer.shap_interaction_values(X_display)\n \nif isinstance(shap_interaction_values, list):\n shap_interaction_values = shap_interaction_values[1]\n\ndis = [f'{a} ({b})' for a, b in zip(X_display.columns, X_display.values[0].round(3))]\n\nshap_bar = pd.DataFrame(data={'feat': dis, 'shap': shap_values[0]})\n\nx_ = shap_bar['shap']\nshap_bar['shap_z'] = (x_ - x_.mean())/x_.std()\nshap_bar['colors'] = ['red' if x_ > 0 else 'green' for x_ in shap_bar['shap_z']]\n# shap_bar = shap_bar[shap_bar['shap_z'].abs()>0.4]\nshap_bar.sort_values('shap_z', inplace=True, ascending=False)\nshap_bar.reset_index(inplace=True)\n","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:29:09.110122Z","iopub.execute_input":"2022-10-04T12:29:09.110544Z","iopub.status.idle":"2022-10-04T12:29:09.130563Z","shell.execute_reply.started":"2022-10-04T12:29:09.110509Z","shell.execute_reply":"2022-10-04T12:29:09.129424Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"diverge_bar(shap_bar, caption='Normalized SHAP values for a True Positive case (model correctly predicted win)', \n value_column='shap_z', color_column='colors', label_coloumn='feat', figsize=(10, 5))","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:29:09.428004Z","iopub.execute_input":"2022-10-04T12:29:09.428801Z","iopub.status.idle":"2022-10-04T12:29:09.960249Z","shell.execute_reply.started":"2022-10-04T12:29:09.428760Z","shell.execute_reply":"2022-10-04T12:29:09.959085Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"#### Then we look at a False Positive case. \n","metadata":{}},{"cell_type":"code","source":"df_test.iloc[false_pos].head(15)","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:29:10.418635Z","iopub.execute_input":"2022-10-04T12:29:10.419267Z","iopub.status.idle":"2022-10-04T12:29:10.428404Z","shell.execute_reply.started":"2022-10-04T12:29:10.419224Z","shell.execute_reply":"2022-10-04T12:29:10.427013Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"false_pos_by = (start_table['track_id']==df_test.iloc[false_pos]['track_id'])\nfalse_pos_by = false_pos_by & (start_table['race_date']==df_test.iloc[false_pos]['race_date'].strftime('%Y-%m-%d'))\nfalse_pos_by = false_pos_by & (start_table['race_number']==df_test.iloc[false_pos]['race_number'])\n\nstart_table[false_pos_by].iloc[:,:15]","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:29:11.425251Z","iopub.execute_input":"2022-10-04T12:29:11.425687Z","iopub.status.idle":"2022-10-04T12:29:11.450631Z","shell.execute_reply.started":"2022-10-04T12:29:11.425639Z","shell.execute_reply":"2022-10-04T12:29:11.449423Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"X_display = df_test[final_feats].iloc[false_pos:(false_pos+1)] #examine one date. this is a data frame\nshap_values = explainer.shap_values(X_display)[1] #shap values for the row\nshap_interaction_values = explainer.shap_interaction_values(X_display)\n \nif isinstance(shap_interaction_values, list):\n shap_interaction_values = shap_interaction_values[1]\n\ndis = [f'{a} ({b})' for a, b in zip(X_display.columns, X_display.values[0].round(3))]\n\nshap_bar = pd.DataFrame(data={'feat': dis, 'shap': shap_values[0]})\n\nx_ = shap_bar['shap']\nshap_bar['shap_z'] = (x_ - x_.mean())/x_.std()\nshap_bar['colors'] = ['red' if x_ > 0 else 'green' for x_ in shap_bar['shap_z']]\n# shap_bar = shap_bar[shap_bar['shap_z'].abs()>0.4]\nshap_bar.sort_values('shap_z', inplace=True, ascending=False)\nshap_bar.reset_index(inplace=True)\n","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:29:12.062146Z","iopub.execute_input":"2022-10-04T12:29:12.063120Z","iopub.status.idle":"2022-10-04T12:29:12.089097Z","shell.execute_reply.started":"2022-10-04T12:29:12.063066Z","shell.execute_reply":"2022-10-04T12:29:12.088026Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"diverge_bar(shap_bar, caption='Normalized SHAP values for a False Positive case (model incorrectly predicted win)', \n value_column='shap_z', color_column='colors', label_coloumn='feat', figsize=(10, 5))","metadata":{"execution":{"iopub.status.busy":"2022-10-04T12:29:12.783057Z","iopub.execute_input":"2022-10-04T12:29:12.783447Z","iopub.status.idle":"2022-10-04T12:29:13.323151Z","shell.execute_reply.started":"2022-10-04T12:29:12.783414Z","shell.execute_reply":"2022-10-04T12:29:13.322187Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"prediction summary","metadata":{}},{"cell_type":"code","source":"tp = ((df_pred['mean_pred']>prob_cut) & (df_pred['target']==1) ).sum() #true positive \nfp = ((df_pred['mean_pred']>prob_cut) & (df_pred['target']==0) ).sum() #false positive\nfn = ((df_pred['mean_pred']<=prob_cut) & (df_pred['target']==1) ).sum() #false negative\ntn = ((df_pred['mean_pred']<=prob_cut) & (df_pred['target']==0) ).sum() #true negative\n\ncm = pd.DataFrame(data=[[tp, fp, ], [fn, tn,]], \n index=['Predict: Win', 'Predict: No Win'], \n columns=['Actual: Win', 'Actual: No Win', ],\n )\nprecision = tp/(tp+fp)\ncm","metadata":{"_kg_hide-input":false,"_kg_hide-output":true,"execution":{"iopub.status.busy":"2022-10-04T12:44:47.912758Z","iopub.execute_input":"2022-10-04T12:44:47.913978Z","iopub.status.idle":"2022-10-04T12:44:47.934208Z","shell.execute_reply.started":"2022-10-04T12:44:47.913933Z","shell.execute_reply":"2022-10-04T12:44:47.933067Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"colors = [\"lightgray\", \"lightgray\",\"lightgray\",]\n\n\nbackground_color = \"#fbfbfb\"\n\nfig, ax = plt.subplots(1, 1, figsize=(6,2), dpi=100,facecolor=background_color)\n\n\nsns.heatmap(cm, cmap=colors,annot=True,fmt=\"d\", linewidths=5,cbar=False,ax=ax,\n yticklabels=cm.index,vmax=500,vmin=0,\n xticklabels=cm.columns,annot_kws={\"fontsize\":12})\nax.tick_params(axis=u'both', which=u'both',length=0)\n\nax.set_facecolor(background_color) \nax.set_yticklabels(ax.get_yticklabels(), rotation = 0, fontfamily='monospace', fontsize=10)#\nax.set_xticklabels(ax.get_xticklabels(), rotation = 0, fontfamily='monospace', fontsize=10)#\n#ax.tick_params(axis=u'both', which=u'both',length=0, )\nax.tick_params(axis='both', which='major', labelsize=12, labelbottom = False, bottom=False, top = False, labeltop=True)\nfig.text(.012, 1., f'''\nOverview: Precision of Predicted win {precision:.2f}\n''', fontfamily='monospace',fontweight='bold',fontsize=13,color='#323232', ha='left')\n\n\nplt.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-10-04T12:44:48.849757Z","iopub.execute_input":"2022-10-04T12:44:48.850223Z","iopub.status.idle":"2022-10-04T12:44:49.060017Z","shell.execute_reply.started":"2022-10-04T12:44:48.850185Z","shell.execute_reply":"2022-10-04T12:44:49.058418Z"},"trusted":true},"execution_count":null,"outputs":[]}]}