{
  "id": 459703,
  "title": "13th place solution [team summary]",
  "url": "/competitions/child-mind-institute-detect-sleep-states/writeups/ricchan-13th-place-solution-team-summary",
  "author_name": "",
  "post_date": "2023-12-11T14:31:07.627Z",
  "votes": 45,
  "comment_count": 2,
  "views": 0,
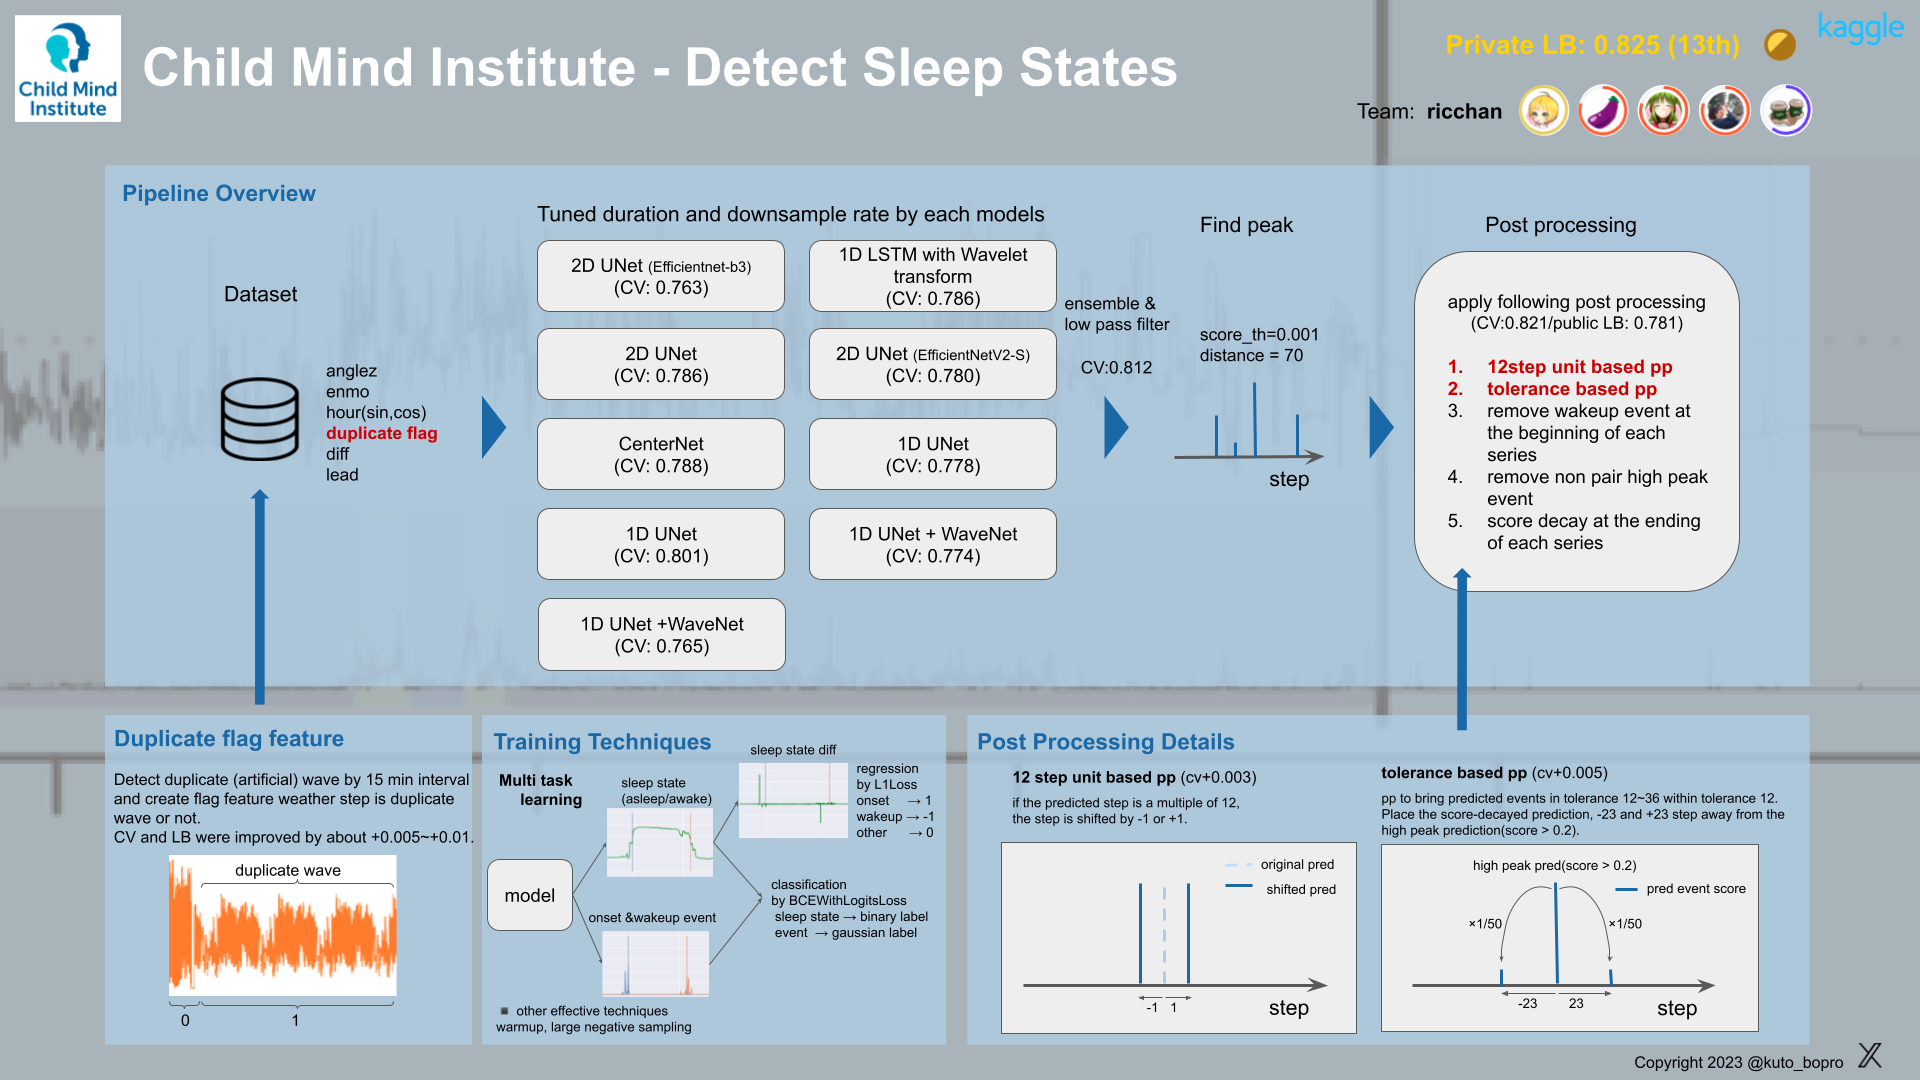
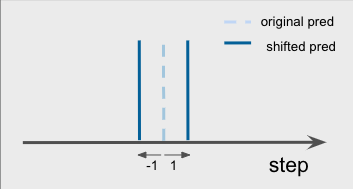
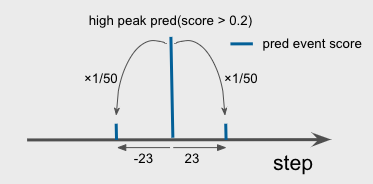
  "content": "<p>First of all, I would like to thank everyone involved in organizing this competition, all the participants, and my teammates <a href=\"https://www.kaggle.com/ktakita\" target=\"_blank\">@ktakita</a> <a href=\"https://www.kaggle.com/stgkrtua\" target=\"_blank\">@stgkrtua</a> <a href=\"https://www.kaggle.com/copasta\" target=\"_blank\">@copasta</a> <a href=\"https://www.kaggle.com/masatomatsui\" target=\"_blank\">@masatomatsui</a> <br>\nIn this topic, I write up the summary of our team solution. The details of these models will be written by each member.<br>\n<a href=\"https://www.kaggle.com/competitions/child-mind-institute-detect-sleep-states/discussion/460499\" target=\"_blank\">13th place solution [K.T. part]</a></p>\n<h2>Summary</h2>\n<ul>\n<li>multi task learning (sleep state binary prediction &amp; onset/wakeup event prediction)</li>\n<li>ensemble (9 model)</li>\n<li>duplicate flag feature</li>\n<li>multi post processing<br>\n<img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F61656908611bdc0b3b2f299e930f12c7%2FSleep%20Solution%20(2).png?generation=1701862054954560&amp;alt=media\" alt=\"\"></li>\n</ul>\n<h2>Model</h2>\n<p>simple average ensemble by following 9 models<br>\nduration and downsampling_rate are tuned by each models<br>\nOur models is based tubo's public code. Many Thanks!</p>\n<ul>\n<li><p>kuto</p>\n<ul>\n<li>2D UNet (cv:0.763)<ul>\n<li>backbone: efficientnet-b3</li>\n<li>duration: 5760</li>\n<li>down sample: 2</li></ul></li>\n<li>1D LSTM (cv: 0.786)<ul>\n<li>feature_extractor: 1DCNN+Wavelet transform</li>\n<li>decoder: 1DCNN+LSTM</li>\n<li>duration: 17280</li>\n<li>down sample: 4</li></ul></li></ul></li>\n<li><p>copasta</p>\n<ul>\n<li>2D UNet (cv: 0.786)<ul>\n<li>duration: 17280</li>\n<li>down sample: 6</li></ul></li>\n<li>2D UNet (cv: 0.780)<ul>\n<li>backbone: EfficientNetV2-S</li>\n<li>duration: 17280</li>\n<li>down sample: 6</li></ul></li>\n<li>CenterNet (cv:0.788)<ul>\n<li>duration: 17280</li>\n<li>down sample: 6</li></ul></li></ul></li>\n<li><p>K.T</p>\n<ul>\n<li>1D UNet (cv: 0.778)<ul>\n<li>Network: 4 Encoder and 4 Decoder with SE Block</li>\n<li>duration: 11440</li>\n<li>down sample 2</li></ul></li>\n<li>1D UNet (cv: 0.801)<ul>\n<li>Network: 4 Encoder and 4 Decoder with SE Block</li>\n<li>duration: 17280</li>\n<li>down sample 4</li></ul></li></ul></li>\n<li><p>toppo</p>\n<ul>\n<li>1D UNet (cv: 0.774)<ul>\n<li>feature_extractor:Wavenet</li>\n<li>decoder:LSTM</li>\n<li>duration: 11440</li>\n<li>down sample 4</li></ul></li>\n<li>1D UNet (cv: 0.765)<ul>\n<li>feature_extractor:Wavenet</li>\n<li>decoder:LSTM</li>\n<li>duration: 5760</li>\n<li>down sample 2</li></ul></li></ul></li>\n</ul>\n<p>The following techniques were effective in some models.</p>\n<ul>\n<li>add L1Loss for sleep state prediction diff</li>\n<li>warmup</li>\n<li>negative sampling (bg_sampling_rate greater than 0.5)</li>\n</ul>\n<h2>Dataset</h2>\n<p>features used by all models</p>\n<ul>\n<li>anglez, enmo</li>\n<li>hour(sin, cos transform)</li>\n<li>duplicate flag feature (<strong>important</strong>)</li>\n</ul>\n<p>features used by some models</p>\n<ul>\n<li>anglez, enmo diff</li>\n<li>anglez, enmo lead</li>\n</ul>\n<h3>duplicate flag feature</h3>\n<p>Some non-wear cases were filled with artificial data. These were created by duplicating the wave in 15-minute steps.<br>\nTherefore, we added a flag as a feature to determine if each step is a duplicated wave. This was effective for all models and improved CV and LB by about +0.005~+0.01.<br>\nAdding to the model as feature tended to improve it more than removing artificial data by post process.</p>\n<h2>Post processing(pp)</h2>\n<p>apply following post processing after scipy.signal.find_peak.<br>\n1 and 2 pp are more important.</p>\n<ol>\n<li>12step(1 min) unit based pp</li>\n<li>tolerance based pp</li>\n<li>remove wakeup event at the beginning of each series</li>\n<li>remove non pair event</li>\n<li>score decay at the ending of each series</li>\n</ol>\n<h3>pp details</h3>\n<ul>\n<li><p>12 step(1min) unit based pp (cv + 0.003)<br>\n<img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F17cf56ec24eb0167915ee5d9c1e80df5%2F2023-12-06%2018.29.18.png?generation=1701855024213569&amp;alt=media\" alt=\"\"><br>\nMetric is evaluated in units of 1min (12 steps), and it is wasteful to use a step that is a multiple of 12 as the predicted value. Therefore, if the predicted step is a multiple of 12, the step is shifted by +-1.</p></li>\n<li><p>tolerance based pp (cv+ 0.005)<br>\n<img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F77465796a3083dd7284821d051133291%2F2023-12-06%2018.29.35.png?generation=1701855050816438&amp;alt=media\" alt=\"\"><br>\npost process to bring predicted events in tolerance 12-36 within tolerance 12.<br>\nPlace the score-decayed prediction, +-23 steps away from the high peak prediction(score &gt; 0.2).</p></li>\n</ul>",
  "messages": [
    {
      "id": "2550809",
      "postDate": "12/06/2023 09:38:27",
      "content": "<p>First of all, I would like to thank everyone involved in organizing this competition, all the participants, and my teammates <a href=\"https://www.kaggle.com/ktakita\" target=\"_blank\">@ktakita</a> <a href=\"https://www.kaggle.com/stgkrtua\" target=\"_blank\">@stgkrtua</a> <a href=\"https://www.kaggle.com/copasta\" target=\"_blank\">@copasta</a> <a href=\"https://www.kaggle.com/masatomatsui\" target=\"_blank\">@masatomatsui</a> <br>\nIn this topic, I write up the summary of our team solution. The details of these models will be written by each member.<br>\n<a href=\"https://www.kaggle.com/competitions/child-mind-institute-detect-sleep-states/discussion/460499\" target=\"_blank\">13th place solution [K.T. part]</a></p>\n<h2>Summary</h2>\n<ul>\n<li>multi task learning (sleep state binary prediction &amp; onset/wakeup event prediction)</li>\n<li>ensemble (9 model)</li>\n<li>duplicate flag feature</li>\n<li>multi post processing<br>\n<img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F61656908611bdc0b3b2f299e930f12c7%2FSleep%20Solution%20(2).png?generation=1701862054954560&amp;alt=media\" alt=\"\"></li>\n</ul>\n<h2>Model</h2>\n<p>simple average ensemble by following 9 models<br>\nduration and downsampling_rate are tuned by each models<br>\nOur models is based tubo's public code. Many Thanks!</p>\n<ul>\n<li><p>kuto</p>\n<ul>\n<li>2D UNet (cv:0.763)<ul>\n<li>backbone: efficientnet-b3</li>\n<li>duration: 5760</li>\n<li>down sample: 2</li></ul></li>\n<li>1D LSTM (cv: 0.786)<ul>\n<li>feature_extractor: 1DCNN+Wavelet transform</li>\n<li>decoder: 1DCNN+LSTM</li>\n<li>duration: 17280</li>\n<li>down sample: 4</li></ul></li></ul></li>\n<li><p>copasta</p>\n<ul>\n<li>2D UNet (cv: 0.786)<ul>\n<li>duration: 17280</li>\n<li>down sample: 6</li></ul></li>\n<li>2D UNet (cv: 0.780)<ul>\n<li>backbone: EfficientNetV2-S</li>\n<li>duration: 17280</li>\n<li>down sample: 6</li></ul></li>\n<li>CenterNet (cv:0.788)<ul>\n<li>duration: 17280</li>\n<li>down sample: 6</li></ul></li></ul></li>\n<li><p>K.T</p>\n<ul>\n<li>1D UNet (cv: 0.778)<ul>\n<li>Network: 4 Encoder and 4 Decoder with SE Block</li>\n<li>duration: 11440</li>\n<li>down sample 2</li></ul></li>\n<li>1D UNet (cv: 0.801)<ul>\n<li>Network: 4 Encoder and 4 Decoder with SE Block</li>\n<li>duration: 17280</li>\n<li>down sample 4</li></ul></li></ul></li>\n<li><p>toppo</p>\n<ul>\n<li>1D UNet (cv: 0.774)<ul>\n<li>feature_extractor:Wavenet</li>\n<li>decoder:LSTM</li>\n<li>duration: 11440</li>\n<li>down sample 4</li></ul></li>\n<li>1D UNet (cv: 0.765)<ul>\n<li>feature_extractor:Wavenet</li>\n<li>decoder:LSTM</li>\n<li>duration: 5760</li>\n<li>down sample 2</li></ul></li></ul></li>\n</ul>\n<p>The following techniques were effective in some models.</p>\n<ul>\n<li>add L1Loss for sleep state prediction diff</li>\n<li>warmup</li>\n<li>negative sampling (bg_sampling_rate greater than 0.5)</li>\n</ul>\n<h2>Dataset</h2>\n<p>features used by all models</p>\n<ul>\n<li>anglez, enmo</li>\n<li>hour(sin, cos transform)</li>\n<li>duplicate flag feature (<strong>important</strong>)</li>\n</ul>\n<p>features used by some models</p>\n<ul>\n<li>anglez, enmo diff</li>\n<li>anglez, enmo lead</li>\n</ul>\n<h3>duplicate flag feature</h3>\n<p>Some non-wear cases were filled with artificial data. These were created by duplicating the wave in 15-minute steps.<br>\nTherefore, we added a flag as a feature to determine if each step is a duplicated wave. This was effective for all models and improved CV and LB by about +0.005~+0.01.<br>\nAdding to the model as feature tended to improve it more than removing artificial data by post process.</p>\n<h2>Post processing(pp)</h2>\n<p>apply following post processing after scipy.signal.find_peak.<br>\n1 and 2 pp are more important.</p>\n<ol>\n<li>12step(1 min) unit based pp</li>\n<li>tolerance based pp</li>\n<li>remove wakeup event at the beginning of each series</li>\n<li>remove non pair event</li>\n<li>score decay at the ending of each series</li>\n</ol>\n<h3>pp details</h3>\n<ul>\n<li><p>12 step(1min) unit based pp (cv + 0.003)<br>\n<img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F17cf56ec24eb0167915ee5d9c1e80df5%2F2023-12-06%2018.29.18.png?generation=1701855024213569&amp;alt=media\" alt=\"\"><br>\nMetric is evaluated in units of 1min (12 steps), and it is wasteful to use a step that is a multiple of 12 as the predicted value. Therefore, if the predicted step is a multiple of 12, the step is shifted by +-1.</p></li>\n<li><p>tolerance based pp (cv+ 0.005)<br>\n<img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F77465796a3083dd7284821d051133291%2F2023-12-06%2018.29.35.png?generation=1701855050816438&amp;alt=media\" alt=\"\"><br>\npost process to bring predicted events in tolerance 12-36 within tolerance 12.<br>\nPlace the score-decayed prediction, +-23 steps away from the high peak prediction(score &gt; 0.2).</p></li>\n</ul>",
      "rawMarkdown": "First of all, I would like to thank everyone involved in organizing this competition, all the participants, and my teammates @ktakita @stgkrtua @copasta @masatomatsui \nIn this topic, I write up the summary of our team solution. The details of these models will be written by each member.\n[13th place solution [K.T. part]](https://www.kaggle.com/competitions/child-mind-institute-detect-sleep-states/discussion/460499)\n\n## Summary\n- multi task learning (sleep state binary prediction & onset/wakeup event prediction)\n- ensemble (9 model)\n- duplicate flag feature\n- multi post processing\n![](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F61656908611bdc0b3b2f299e930f12c7%2FSleep%20Solution%20(2).png?generation=1701862054954560&alt=media)\n\n## Model\nsimple average ensemble by following 9 models\nduration and downsampling_rate are tuned by each models\nOur models is based tubo's public code. Many Thanks!\n\n- kuto\n  - 2D UNet (cv:0.763)\n      - backbone: efficientnet-b3\n      - duration: 5760\n      - down sample: 2\n  - 1D LSTM (cv: 0.786)\n      - feature_extractor: 1DCNN+Wavelet transform\n      - decoder: 1DCNN+LSTM\n      - duration: 17280\n      - down sample: 4\n\n- copasta\n  - 2D UNet (cv: 0.786)\n      - duration: 17280\n      - down sample: 6\n  - 2D UNet (cv: 0.780)\n      - backbone: EfficientNetV2-S\n      - duration: 17280\n      - down sample: 6\n  - CenterNet (cv:0.788)\n      - duration: 17280\n      - down sample: 6\n\n- K.T\n  - 1D UNet (cv: 0.778)\n      - Network: 4 Encoder and 4 Decoder with SE Block\n      - duration: 11440\n      - down sample 2\n  - 1D UNet (cv: 0.801)\n      - Network: 4 Encoder and 4 Decoder with SE Block\n      - duration: 17280\n      - down sample 4\n\n- toppo\n  - 1D UNet (cv: 0.774)\n      - feature_extractor:Wavenet\n      - decoder:LSTM\n      - duration: 11440\n      - down sample 4\n  - 1D UNet (cv: 0.765)\n      - feature_extractor:Wavenet\n      - decoder:LSTM\n      - duration: 5760\n      - down sample 2\n\nThe following techniques were effective in some models.\n- add L1Loss for sleep state prediction diff\n- warmup\n- negative sampling (bg_sampling_rate greater than 0.5)\n\n## Dataset\nfeatures used by all models\n- anglez, enmo\n- hour(sin, cos transform)\n- duplicate flag feature (**important**)\n\nfeatures used by some models\n- anglez, enmo diff\n- anglez, enmo lead\n\n### duplicate flag feature\nSome non-wear cases were filled with artificial data. These were created by duplicating the wave in 15-minute steps.\nTherefore, we added a flag as a feature to determine if each step is a duplicated wave. This was effective for all models and improved CV and LB by about +0.005~+0.01.\nAdding to the model as feature tended to improve it more than removing artificial data by post process.\n\n## Post processing(pp)\napply following post processing after scipy.signal.find_peak.\n1 and 2 pp are more important.\n\n1. 12step(1 min) unit based pp\n2. tolerance based pp\n3. remove wakeup event at the beginning of each series\n4. remove non pair event\n5. score decay at the ending of each series\n\n\n### pp details\n- 12 step(1min) unit based pp (cv + 0.003)\n![](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F17cf56ec24eb0167915ee5d9c1e80df5%2F2023-12-06%2018.29.18.png?generation=1701855024213569&alt=media)\nMetric is evaluated in units of 1min (12 steps), and it is wasteful to use a step that is a multiple of 12 as the predicted value. Therefore, if the predicted step is a multiple of 12, the step is shifted by +-1.\n\n- tolerance based pp (cv+ 0.005)\n![](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F77465796a3083dd7284821d051133291%2F2023-12-06%2018.29.35.png?generation=1701855050816438&alt=media)\npost process to bring predicted events in tolerance 12-36 within tolerance 12.\nPlace the score-decayed prediction, +-23 steps away from the high peak prediction(score > 0.2).",
      "votes": null
    },
    {
      "id": "2551092",
      "postDate": "12/06/2023 13:56:40",
      "content": "<p>Well structured summary,  Congratulations! <a href=\"https://www.kaggle.com/KUTO\" target=\"_blank\">@KUTO</a></p>",
      "rawMarkdown": "Well structured summary,  Congratulations! @KUTO",
      "votes": null
    },
    {
      "id": "2551891",
      "postDate": "12/07/2023 03:34:48",
      "content": "<p>Very clean schematics!</p>",
      "rawMarkdown": "Very clean schematics!",
      "votes": null
    }
  ],
  "comments": [
    {
      "id": 2551092,
      "author_name": "abhasmalguri",
      "author_url": "",
      "post_date": "12/06/2023 13:56:40",
      "content": "<p>Well structured summary,  Congratulations! <a href=\"https://www.kaggle.com/KUTO\" target=\"_blank\">@KUTO</a></p>",
      "votes": null,
      "replies": []
    },
    {
      "id": 2551891,
      "author_name": "dongyk",
      "author_url": "",
      "post_date": "12/07/2023 03:34:48",
      "content": "<p>Very clean schematics!</p>",
      "votes": null,
      "replies": []
    }
  ],
  "raw_markdown_by_id": {
    "2550809": "First of all, I would like to thank everyone involved in organizing this competition, all the participants, and my teammates @ktakita @stgkrtua @copasta @masatomatsui \nIn this topic, I write up the summary of our team solution. The details of these models will be written by each member.\n[13th place solution [K.T. part]](https://www.kaggle.com/competitions/child-mind-institute-detect-sleep-states/discussion/460499)\n\n## Summary\n- multi task learning (sleep state binary prediction & onset/wakeup event prediction)\n- ensemble (9 model)\n- duplicate flag feature\n- multi post processing\n![](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F61656908611bdc0b3b2f299e930f12c7%2FSleep%20Solution%20(2).png?generation=1701862054954560&alt=media)\n\n## Model\nsimple average ensemble by following 9 models\nduration and downsampling_rate are tuned by each models\nOur models is based tubo's public code. Many Thanks!\n\n- kuto\n  - 2D UNet (cv:0.763)\n      - backbone: efficientnet-b3\n      - duration: 5760\n      - down sample: 2\n  - 1D LSTM (cv: 0.786)\n      - feature_extractor: 1DCNN+Wavelet transform\n      - decoder: 1DCNN+LSTM\n      - duration: 17280\n      - down sample: 4\n\n- copasta\n  - 2D UNet (cv: 0.786)\n      - duration: 17280\n      - down sample: 6\n  - 2D UNet (cv: 0.780)\n      - backbone: EfficientNetV2-S\n      - duration: 17280\n      - down sample: 6\n  - CenterNet (cv:0.788)\n      - duration: 17280\n      - down sample: 6\n\n- K.T\n  - 1D UNet (cv: 0.778)\n      - Network: 4 Encoder and 4 Decoder with SE Block\n      - duration: 11440\n      - down sample 2\n  - 1D UNet (cv: 0.801)\n      - Network: 4 Encoder and 4 Decoder with SE Block\n      - duration: 17280\n      - down sample 4\n\n- toppo\n  - 1D UNet (cv: 0.774)\n      - feature_extractor:Wavenet\n      - decoder:LSTM\n      - duration: 11440\n      - down sample 4\n  - 1D UNet (cv: 0.765)\n      - feature_extractor:Wavenet\n      - decoder:LSTM\n      - duration: 5760\n      - down sample 2\n\nThe following techniques were effective in some models.\n- add L1Loss for sleep state prediction diff\n- warmup\n- negative sampling (bg_sampling_rate greater than 0.5)\n\n## Dataset\nfeatures used by all models\n- anglez, enmo\n- hour(sin, cos transform)\n- duplicate flag feature (**important**)\n\nfeatures used by some models\n- anglez, enmo diff\n- anglez, enmo lead\n\n### duplicate flag feature\nSome non-wear cases were filled with artificial data. These were created by duplicating the wave in 15-minute steps.\nTherefore, we added a flag as a feature to determine if each step is a duplicated wave. This was effective for all models and improved CV and LB by about +0.005~+0.01.\nAdding to the model as feature tended to improve it more than removing artificial data by post process.\n\n## Post processing(pp)\napply following post processing after scipy.signal.find_peak.\n1 and 2 pp are more important.\n\n1. 12step(1 min) unit based pp\n2. tolerance based pp\n3. remove wakeup event at the beginning of each series\n4. remove non pair event\n5. score decay at the ending of each series\n\n\n### pp details\n- 12 step(1min) unit based pp (cv + 0.003)\n![](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F17cf56ec24eb0167915ee5d9c1e80df5%2F2023-12-06%2018.29.18.png?generation=1701855024213569&alt=media)\nMetric is evaluated in units of 1min (12 steps), and it is wasteful to use a step that is a multiple of 12 as the predicted value. Therefore, if the predicted step is a multiple of 12, the step is shifted by +-1.\n\n- tolerance based pp (cv+ 0.005)\n![](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F2603247%2F77465796a3083dd7284821d051133291%2F2023-12-06%2018.29.35.png?generation=1701855050816438&alt=media)\npost process to bring predicted events in tolerance 12-36 within tolerance 12.\nPlace the score-decayed prediction, +-23 steps away from the high peak prediction(score > 0.2).",
    "2551092": "Well structured summary,  Congratulations! @KUTO",
    "2551891": "Very clean schematics!"
  },
  "source": "meta"
}