{"cells":[{"metadata":{"_uuid":"2105771f0037fb6dff2e575963e57ce49f6ee4b7","_cell_guid":"c992dac3-5dd9-49ba-9561-90f14934372e"},"cell_type":"markdown","source":"## contents \n1. [Intro](#1-anchor)\n2. [Get the data](#2-anchor)\n3. [Create Keras metrics ](#3-anchor)\n4. [Build neural network](#4-anchor)\n5. [Train neural network](#5-anchor)\n6. [Make predictions](#6-anchor)\n7. [Encode and submit our results](#7-anchor)\n8. [__main__](#8-anchor)\n9. [LB score history](#9-anchor)","execution_count":null},{"metadata":{"_uuid":"1677fddbb95f7545b6540e9201f3339a0fdbfc5d","_cell_guid":"e61ef2d8-f315-4f7f-b07e-1de0f4e8441a"},"cell_type":"markdown","source":"# Intro \n* see [Keras U-Net starter - LB 0.277](https://www.kaggle.com/keegil/keras-u-net-starter-lb-0-277)\n* see also https://github.com/kamalkraj/DATA-SCIENCE-BOWL-2018/blob/master/Data_Science_Bowl_2018.ipynb\nThis kernel shows how to get started on segmenting nuclei using a neural network in `Keras`. \n\nThe architecture used is the so-called __ [U-Net](https://arxiv.org/abs/1505.04597)__, which is very common for image segmentation problems such as this. \n","execution_count":null},{"metadata":{"_uuid":"0ee84968345cb5e07309e9a2dbe12de7e523c335","_cell_guid":"511efb88-f4d8-4a98-9d02-dd44c85bb455","trusted":true},"cell_type":"code","source":"import os\nimport sys\nimport random\nimport warnings\n\nimport numpy as np\nimport pandas as pd\n\nimport matplotlib.pyplot as plt\nfrom IPython.display import clear_output\n\nfrom tqdm import tqdm\nfrom itertools import chain\nfrom skimage.io import imread, imshow, imread_collection, concatenate_images\nfrom skimage.transform import resize\nfrom skimage.morphology import label","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"ff5515d640d3eb7913542fccc80722cbd0eb5627","_cell_guid":"9a0b4762-8150-4392-8cb4-4468c3058c59","trusted":true},"cell_type":"code","source":"from keras.models import Model, load_model\nfrom keras.layers import Input\nfrom keras.layers.core import Dropout, Lambda\nfrom keras.layers.convolutional import Conv2D, Conv2DTranspose\nfrom keras.layers.pooling import MaxPooling2D\nfrom keras.layers.merge import concatenate\nfrom keras.callbacks import EarlyStopping, ModelCheckpoint\nfrom keras import backend as K\n\nimport tensorflow as tf","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"5c38504af3a84bee68c66d3cde74443c58df422f","_cell_guid":"c332549b-8d23-4bb5-8497-e7a8eb8b21d2","trusted":true},"cell_type":"code","source":"# Set some parameters\nIMG_WIDTH = 256\nIMG_HEIGHT = 256\nIMG_CHANNELS = 3\nTRAIN_PATH = '../input/stage1_train/'\nTEST_PATH = '../input/stage1_test/'\n\nwarnings.filterwarnings('ignore', category=UserWarning, module='skimage')\nseed = 242\nrandom.seed = seed\nnp.random.seed = seed","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"3fb9d6530fbbd0e22e41fc4fd9fd9fc0bff027ac","_cell_guid":"ffa0caf0-2d1b-40f2-865b-8e6db88526b6","trusted":true},"cell_type":"code","source":"# Get train and test IDs\ntrain_ids = next(os.walk(TRAIN_PATH))[1]\ntest_ids = next(os.walk(TEST_PATH))[1]\n\"train = \" + str(len(train_ids)) +\" | test = \" + str(len(test_ids))","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"875af74f980236825de3a650825b46e25632422c","_cell_guid":"59c4a25d-645f-4b74-9c53-145ac78cc481"},"cell_type":"markdown","source":"# Get the data \nLet's first import all the images and associated masks. I downsample both the training and test images to keep things light and manageable, but we need to keep a record of the original sizes of the test images to upsample our predicted masks and create correct run-length encodings later on. There are definitely better ways to handle this, but it works fine for now!","execution_count":null},{"metadata":{"_uuid":"9e389ba8bdb5b6fc03b231b6a6c84a8bde634053","_cell_guid":"ca0cc34b-c26f-41ee-88d7-975aebdb634e","trusted":true},"cell_type":"code","source":"X_train = None\nY_train = None\n# Get and resize train images and masks\ndef loadTrainImagesAndMasks():\n global X_train\n global Y_train\n X_train = np.zeros((len(train_ids), IMG_HEIGHT, IMG_WIDTH, IMG_CHANNELS), dtype=np.uint8)\n Y_train = np.zeros((len(train_ids), IMG_HEIGHT, IMG_WIDTH, 1), dtype=np.bool)\n print('Getting and resizing train images and masks ... ')\n sys.stdout.flush()\n minMask=99999\n maxMask=0\n for n, id_ in tqdm(enumerate(train_ids), total=len(train_ids)):\n path = TRAIN_PATH + id_\n img = imread(path + '/images/' + id_ + '.png')[:,:,:IMG_CHANNELS]\n img = resize(img, (IMG_HEIGHT, IMG_WIDTH), mode='constant', preserve_range=True)\n X_train[n] = img\n mask = np.zeros((IMG_HEIGHT, IMG_WIDTH, 1), dtype=np.bool)\n i = 0\n for mask_file in next(os.walk(path + '/masks/'))[2]:\n i += 1\n mask_ = imread(path + '/masks/' + mask_file)\n mask_ = np.expand_dims(resize(mask_, (IMG_HEIGHT, IMG_WIDTH), mode='constant', \n preserve_range=True), axis=-1)\n mask = np.maximum(mask, mask_)\n #print( str(n) +':' + str(i) +':')\n if i < minMask: minMask = i\n if i > maxMask: maxMask = i \n Y_train[n] = mask\n\n print( 'minMask = ' + str(minMask) +'| maxMask = ' + str(maxMask) +':')\n","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"fa29291ac4071f3a039dcbccbea02f024174141b","_cell_guid":"70d1c774-322b-4f0b-965b-dfa4a5da4b87","trusted":true},"cell_type":"code","source":"# Get and resize test images\ndef getTestData():\n X_test = np.zeros((len(test_ids), IMG_HEIGHT, IMG_WIDTH, IMG_CHANNELS), dtype=np.uint8)\n sizes_test = []\n print('Getting and resizing test images ... ')\n sys.stdout.flush()\n for n, id_ in tqdm(enumerate(test_ids), total=len(test_ids)):\n path = TEST_PATH + id_\n #img = imread(path + '/images/' + id_ + '.png')[:,:,:IMG_CHANNELS]\n img = imread(path + '/images/' + id_ + '.png')\n if len(img.shape) == 2: # gray\n max_ = np.max(img)\n print(n,img.shape,'max:', max_,id_) # ,np.min(img),np.max(img)\n if max_ > 256: # not \"uint8\"\n img = img/max_ # normalize \n img = (img * 255).round().astype(np.uint8)\n img = np.stack([img,img,img], axis=2).astype(\"uint8\") \n elif img.shape[2] == 4: # remove alpha channel\n img = img[:,:,:IMG_CHANNELS] \n sizes_test.append([img.shape[0], img.shape[1]])\n img = resize(img, (IMG_HEIGHT, IMG_WIDTH), mode='constant', preserve_range=True)\n X_test[n] = img\n print('Loaded test images', len(X_test))\n return X_test,sizes_test ","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"d4f8327802a1ec6139ce0585953986272ba62ce1","_cell_guid":"c0523b03-1fc5-4505-a1b8-eb35ee617c8a"},"cell_type":"markdown","source":"Let's see if things look all right by drawing some random images and their associated masks.","execution_count":null},{"metadata":{"_uuid":"283af26f0860b7069bdfd133c746e5d20971542c","_cell_guid":"88829b53-50ce-45d9-9540-77dd7384ad4c","trusted":true},"cell_type":"code","source":"# Check if training data looks all right\ndef CheckTrainData():\n ix = random.randint(0, len(train_ids))\n imshow(X_train[ix])\n plt.show()\n imshow(np.squeeze(Y_train[ix]))\n plt.show()\n# CheckTrainData()","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"938648da705689a0f940ff462477c801db3f0737","_cell_guid":"2574ffe9-b911-4bfd-a00f-9ba5c25f45de"},"cell_type":"markdown","source":"# Create our Keras metric \n\nNow we try to define the *mean average precision at different intersection over union (IoU) thresholds* metric in Keras. TensorFlow has a mean IoU metric, but it doesn't have any native support for the mean over multiple thresholds, so I tried to implement this. **I'm by no means certain that this implementation is correct, though!** Any assistance in verifying this would be most welcome! \n\n*Update: This implementation is most definitely not correct due to the very large discrepancy between the results reported here and the LB results. It also seems to just increase over time no matter what when you train ... *","execution_count":null},{"metadata":{"_uuid":"5abd38950ae99b60f8afec7656eb654a48d449fe","_cell_guid":"c1df6f3a-d58f-434b-9216-ef7be38637d4","trusted":true},"cell_type":"code","source":"# Define IoU metric\ndef mean_iou(y_true, y_pred):\n prec = []\n for t in np.arange(0.5, 1.0, 0.05):\n y_pred_ = tf.to_int32(y_pred > t)\n score, up_opt = tf.metrics.mean_iou(y_true, y_pred_, 2, y_true)\n K.get_session().run(tf.local_variables_initializer())\n with tf.control_dependencies([up_opt]):\n score = tf.identity(score)\n prec.append(score)\n return K.mean(K.stack(prec), axis=0)\n# Dice coefficient\ndef dice_coef(y_true, y_pred, smooth=1.0):\n y_true_f = K.flatten(y_true)\n y_pred_f = K.flatten(y_pred)\n intersection = K.sum(y_true_f * y_pred_f)\n return (2. * intersection + K.epsilon()) / (K.sum(y_true_f) + K.sum(y_pred_f) + smooth)","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"d71b2f624adf01050484452b4363bf0f6f134710","_cell_guid":"e9b368fa-d0d0-4bd9-8d7a-d5c13e897d60","trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"986488a4c5223576be370e224426a30431911eb2","_cell_guid":"c3b9f148-1dba-4b6a-981b-6cdbf394fc3c"},"cell_type":"markdown","source":"# Build our neural network \nNext we build our U-Net model, loosely based on [U-Net: Convolutional Networks for Biomedical Image Segmentation](https://arxiv.org/pdf/1505.04597.pdf) and very similar to [this repo](https://github.com/jocicmarko/ultrasound-nerve-segmentation) from the Kaggle Ultrasound Nerve Segmentation competition.\n\n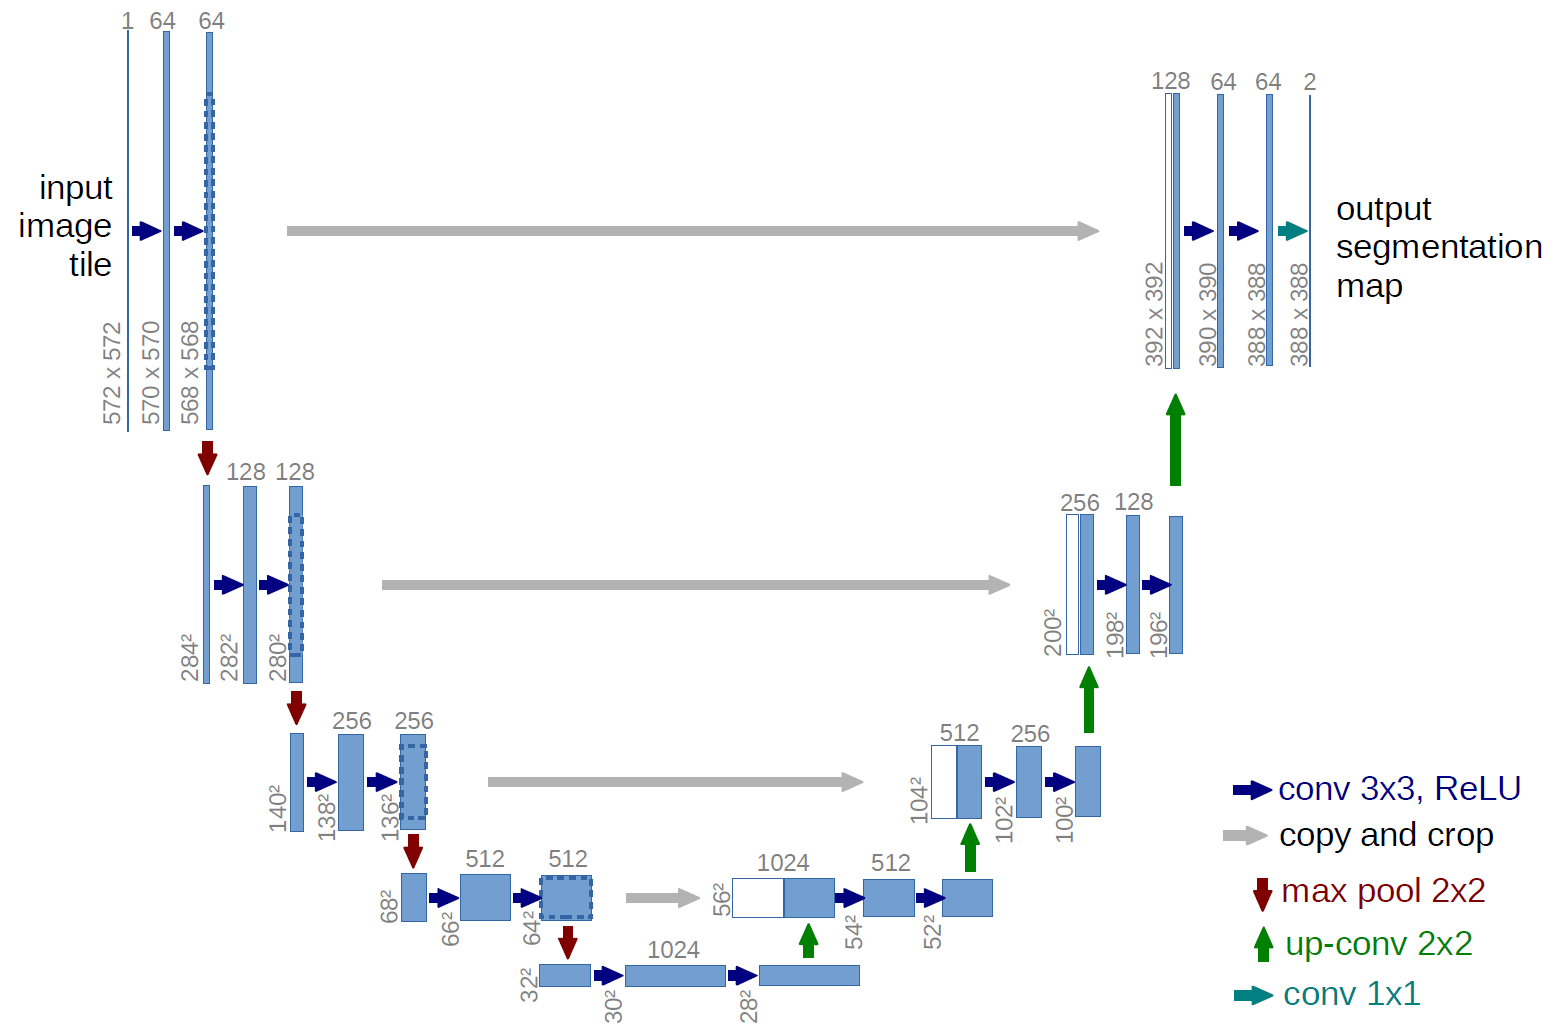","execution_count":null},{"metadata":{"_kg_hide-output":true,"_uuid":"0aa97d66c29f45dfac9b0f45fcf74ba0e778ba5d","_cell_guid":"c1dbc57c-b497-4ccb-b077-2053203ab7ed","_kg_hide-input":true,"trusted":true},"cell_type":"code","source":"# Build U-Net model\ndef BuildModel(bg2 = 4,_Height=256, _Width=256, _Channels=3, outCannels = 1):\n sAct = 'elu' # activation ['relu','elu'][1]\n sK_init = 'he_normal' # kernel_initializer\n sPad = 'same' # padding\n input_name = 'input_h_w'\n \n inputs = Input((_Height, _Width, _Channels),name=input_name)\n s = Lambda(lambda x: x / 255) (inputs)\n \n c1 = Conv2D(2**(bg2+0), (3, 3), activation=sAct, kernel_initializer=sK_init, \n padding=sPad, name='cv1_1') (s)\n c1 = Dropout(0.1, name='do1_2') (c1)\n c1 = Conv2D(2**(bg2+0), (3, 3), activation=sAct, kernel_initializer=sK_init, \n padding=sPad, name='cv1_3') (c1)\n p1 = MaxPooling2D((2, 2), name='mp1_4') (c1)\n #p1 = BatchNormalization()(p1)\n \n c2 = Conv2D(2**(bg2+1), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv2_1') (p1)\n c2 = Dropout(0.1, name='do2_2') (c2)\n c2 = Conv2D(2**(bg2+1), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv2_3') (c2)\n p2 = MaxPooling2D((2, 2), name='mp2_4') (c2)\n #p2 = BatchNormalization()(p2)\n \n c3 = Conv2D(2**(bg2+2), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv3_1') (p2)\n c3 = Dropout(0.2, name='do3_2') (c3)\n c3 = Conv2D(2**(bg2+2), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv3_3') (c3)\n p3 = MaxPooling2D((2, 2), name='mp3_4') (c3)\n #p3 = BatchNormalization()(p3)\n \n c4 = Conv2D(2**(bg2+3), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv4_1') (p3)\n c4 = Dropout(0.2, name='do4_2') (c4)\n c4 = Conv2D(2**(bg2+3), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv4_3') (c4)\n p4 = MaxPooling2D(pool_size=(2, 2), name='mp4_4') (c4)\n #p4 = BatchNormalization()(p4)\n ####=======================================================================\n c5 = Conv2D(2**(bg2+4), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv5_1') (p4)\n c5 = Dropout(0.3, name='do5_2') (c5)\n c5 = Conv2D(2**(bg2+4), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv5_3') (c5)\n ####=======================================================================\n u6 = Conv2DTranspose(2**(bg2+3), (2, 2), strides=(2, 2),\n padding=sPad, name='up6_1') (c5)\n u6 = concatenate([u6, c4], name='up6_2')\n c6 = Conv2D(2**(bg2+3), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv6_3') (u6)\n c6 = Dropout(0.2, name='do6_4') (c6)\n c6 = Conv2D(2**(bg2+3), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv6_5') (c6)\n \n u7 = Conv2DTranspose(2**(bg2+2), (2, 2), strides=(2, 2),\n padding=sPad, name='up7_1') (c6)\n u7 = concatenate([u7, c3], name='up7_2')\n c7 = Conv2D(2**(bg2+2), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv7_3') (u7)\n c7 = Dropout(0.2, name='do7_4') (c7)\n c7 = Conv2D(2**(bg2+2), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv7_5') (c7)\n #c7 = BatchNormalization()(c7)\n \n u8 = Conv2DTranspose(2**(bg2+1), (2, 2), strides=(2, 2),\n padding=sPad, name='up8_1') (c7)\n u8 = concatenate([u8, c2], name='up8_2')\n c8 = Conv2D(2**(bg2+1), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv8_3') (u8)\n c8 = Dropout(0.1, name='do8_4') (c8)\n c8 = Conv2D(2**(bg2+1), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv8_5') (c8)\n #c8 = BatchNormalization()(c8)\n \n u9 = Conv2DTranspose(2**(bg2+0), (2, 2), strides=(2, 2),\n padding=sPad, name='up9_1') (c8)\n u9 = concatenate([u9, c1], axis=3, name='up9_2')\n c9 = Conv2D(2**(bg2+0), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv9_3') (u9)\n c9 = Dropout(0.1, name='do9_4') (c9)\n c9 = Conv2D(2**(bg2+0), (3, 3), activation=sAct, kernel_initializer=sK_init,\n padding=sPad, name='cv9_5') (c9)\n #c9 = BatchNormalization()(c9)\n \n outputs = Conv2D(outCannels, (1, 1), activation='sigmoid',name='outputs') (c9)\n return Model(inputs=[inputs], outputs=[outputs], name='U-Net' + str(2**(bg2)))","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"92350b6e18cc50f3fa7b6e9a02d39fcbff8238f7","_cell_guid":"72330944-6ce7-4070-b276-c3c4b20c4fe5"},"cell_type":"markdown","source":"","execution_count":null},{"metadata":{"_uuid":"8b926be0362bf03c405fcb92267ebb594d79ccb1","_cell_guid":"e07c90d8-6f3a-4d6d-9713-29f1419e8ea2"},"cell_type":"markdown","source":"# Train our neural network ","execution_count":null},{"metadata":{"_uuid":"41ceddc665d707f13d09c321c85e26f0dd90eada","_cell_guid":"0c1a98ef-3a81-4f0d-a8fd-797e4a851607","trusted":true},"cell_type":"code","source":"def polt_train(results,lbl_trn):\n lbl_val = 'val_'+lbl_trn\n plt.plot(results.epoch, results.history[lbl_trn], label=\"trn_\" + lbl_trn + \\\n \" {0:.4f}\".format(results.history[lbl_trn][-1]))\n plt.plot(results.epoch, results.history[lbl_val], label=lbl_val + \\\n \" {0:.4f}\".format(results.history[lbl_val][-1]))\n plt.xlabel('Epochs')\n plt.ylabel(lbl_trn)\n plt.legend()\n plt.show()\ndef polt_train2(results,lbl_trn0,lbl_trn1):\n fig, axes = plt.subplots(1, 2, figsize=(16, 4))\n\n lbl_val0 = 'val_'+lbl_trn0\n lbl_val1 = 'val_'+lbl_trn1\n axes[0].plot(results.epoch, results.history[lbl_trn0], label=\"trn_\" + lbl_trn0 + \\\n \" {0:.4f}\".format(results.history[lbl_trn0][-1]))\n axes[0].plot(results.epoch, results.history[lbl_val0], label=lbl_val0 + \\\n \" {0:.4f}\".format(results.history[lbl_val0][-1]))\n #axes[0].set_title(\"<{}>\".format(lbl_val0))\n axes[0].set_xlabel('Epochs')\n axes[0].set_ylabel(lbl_trn0)\n axes[1].plot(results.epoch, results.history[lbl_trn1], label=\"trn_\" + lbl_trn1 + \\\n \" {0:.4f}\".format(results.history[lbl_trn1][-1]))\n axes[1].plot(results.epoch, results.history[lbl_val1], label=lbl_val1 + \\\n \" {0:.4f}\".format(results.history[lbl_val1][-1]))\n axes[1].set_xlabel('Epochs')\n axes[1].set_ylabel(lbl_trn1)\n plt.legend()\n plt.show() ","execution_count":null,"outputs":[]},{"metadata":{"scrolled":true,"_uuid":"c060db22daa2abf12b28240cd81bbcbf1ce1bf87","_cell_guid":"9415b1c4-aa69-41b9-a1e3-d6053dbd4f64","trusted":true},"cell_type":"code","source":"# Fit model\ndef processFit(model, sModelCheckpoint='model-dsbowl2018-0.h5'):\n earlystopper = EarlyStopping(patience=10, verbose=1)\n checkpointer = ModelCheckpoint(sModelCheckpoint, verbose=1, save_best_only=True)\n for batch_size in (64,32,16):\n # load last model\n if os.path.isfile(sModelCheckpoint)==True:\n print(\" LOAD model: \",sModelCheckpoint,'Batch Size:',batch_size)\n model = load_model(sModelCheckpoint, custom_objects={'mean_iou': mean_iou,\n 'dice_coef': dice_coef,})\n print('Start. Fit Model => Epochs:',iEpochs, 'batch_size:', batch_size)\n # ==========\n results = model.fit(X_train, Y_train, validation_split=validationSplit, \n batch_size=batch_size, epochs=iEpochs,\n callbacks=[earlystopper, checkpointer],\n verbose=2,\n )\n # ==========\n sModelMidle = sModelCheckpoint+'-'+str(iEpochs) \\\n + 'vl=' + str(results.history['val_loss'][-1]) \\\n + '-minVL=' + str(min(results.history['val_loss'])) \\\n + '.h5'\n model.save(sModelMidle)\n clear_output()\n polt_train(results,'mean_iou')\n polt_train2(results,'loss','dice_coef') ","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"bb15226ea617cf91ed8f43179fccb5a15809e5a0","_cell_guid":"1f381f5b-1b71-4daa-a417-e02f4894540b"},"cell_type":"markdown","source":"Loss seems to be a bit erratic, though. I'll leave it to you to improve the model architecture and parameters! \n\n# Make predictions \n\nLet's make predictions both on the test set, the val set and the train set (as a sanity check). Remember to load the best saved model if you've used early stopping and checkpointing.","execution_count":null},{"metadata":{"_uuid":"0314003e43a7dbb1623adbfe9b90e1e898a95335","_cell_guid":"fa3c0441-08c3-468d-8c27-6fc53f447f69","trusted":true},"cell_type":"code","source":"# Threshold predictions\nthreshold = 0.62\nfrom skimage import morphology\ndef imagePostProcessing(img,_threshold = threshold):\n img = (img > _threshold).astype(np.uint8)\n eroded = morphology.erosion(img, morphology.square(3))\n dilated = morphology.dilation(eroded, morphology.square(3))\n return dilated","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"f841760b4abca1a25cb750822f88268bd79bf2ce","_cell_guid":"2daa48d5-ac98-4e18-af3f-a582baaa44f0","trusted":true},"cell_type":"code","source":"# Threshold predictions\nthreshold = 0.60\n\n# Create list of upsampled test masks (threshold)\ndef makeUpsampledPostProcessingResizeMasks(thhd = threshold): # -> list[numpy.ndarray]\n '''Create list of upsampled test masks'''\n # global preds_test\n # global sizes_test\n preds_test_upsampled = []\n for i in range(len(preds_test)):\n preds_test_upsampled.append(resize(\n imagePostProcessing(np.squeeze(preds_test[i]),thhd), \n (sizes_test[i][0], sizes_test[i][1]), \n mode='constant', preserve_range=True)\n )\n return preds_test_upsampled\n# Create list of upsampled test masks\ndef makeUpsampledResizeMasks(preds_test): # -> list[numpy.ndarray]\n preds_test_upsampled = []\n # global preds_test\n # global sizes_test\n for i in range(len(preds_test)):\n preds_test_upsampled.append(resize(np.squeeze(preds_test[i]), \n (sizes_test[i][0], sizes_test[i][1]), \n mode='constant', preserve_range=True))\n return preds_test_upsampled ","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"5fcee2b9aee2fba5c60d43ad48a14139e9c1318c","_cell_guid":"af602aea-5e56-42a8-9331-54b4b2650593"},"cell_type":"markdown","source":"The model is at least able to fit to the training data! Certainly a lot of room for improvement even here, but a decent start. How about the validation data?","execution_count":null},{"metadata":{"_uuid":"6a34c98de7c6ae473f676a34fe7e099b46764eca","_cell_guid":"a6690535-b2e4-49ac-98d9-7191bfabfb6f"},"cell_type":"markdown","source":"## Encode and submit our results \n\nNow it's time to submit our results. I've stolen [this](https://www.kaggle.com/rakhlin/fast-run-length-encoding-python) excellent implementation of run-length encoding.","execution_count":null},{"metadata":{"_uuid":"4f99c1bf852e82b60bd4f982ca0df293f712cdf0","_cell_guid":"59a0af60-a7d7-41ef-a6fe-9e3c72defa07","trusted":true},"cell_type":"code","source":"# Run-length encoding stolen from https://www.kaggle.com/rakhlin/fast-run-length-encoding-python\ndef rle_encoding(x):\n dots = np.where(x.T.flatten() == 1)[0]\n run_lengths = []\n prev = -2\n for b in dots:\n if (b>prev+1): run_lengths.extend((b + 1, 0))\n run_lengths[-1] += 1\n prev = b\n return run_lengths\n\ndef prob_to_rles(x, cutoff=0.5):\n lab_img = label(x > cutoff)\n for i in range(1, lab_img.max() + 1):\n yield rle_encoding(lab_img == i)","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"2e07f6afc4787b068ba714428145dcb3951d718f","_cell_guid":"31133f8c-3f40-4dff-8e1d-898d56672332"},"cell_type":"markdown","source":"Let's iterate over the test IDs and generate run-length encodings for each seperate mask identified by skimage ...","execution_count":null},{"metadata":{"_uuid":"ba589f56f5be1e6886bc88f5bf9e7d0a408e4048","_cell_guid":"1ba0ee3a-cca0-4349-83f6-09a1ac6fcb44","trusted":true},"cell_type":"code","source":"# Create submission DataFrame\ndef submission(fileCSV='sub-dsbowl2018-1.csv'):\n sub = pd.DataFrame()\n sub['ImageId'] = new_test_ids\n sub['EncodedPixels'] = pd.Series(rles).apply(lambda x: ' '.join(str(y) for y in x))\n sub.to_csv(fileCSV, index=False)","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"a9ac1ebf438268a93c96b630715ff973075c59b4","_cell_guid":"f99c2e82-b485-4535-8aa8-1d12275d547d"},"cell_type":"markdown","source":"## __main__ ","execution_count":null},{"metadata":{"_uuid":"c1641c3a64c82aca89dbdcc04f90723ed2b42ee8","_cell_guid":"9e5b867f-505f-45f1-96be-b53c1a50a8e2","trusted":true},"cell_type":"code","source":"%%time\nloadTrainImagesAndMasks()\nX_test,sizes_test = getTestData()\n\nmodel = BuildModel()\nmodel.compile(optimizer='adam', loss='binary_crossentropy', metrics=[mean_iou,dice_coef])","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"26fbc1386d609a6d8fb9decee2ad722c0aaeec2a","_cell_guid":"1934cfd7-04f6-4665-8749-79e9addf6f89","trusted":true},"cell_type":"code","source":"print(model.summary)","execution_count":null,"outputs":[]},{"metadata":{"scrolled":false,"_uuid":"8c9c234369249eeb8a8bf7aa6ab23325b9d92b81","_cell_guid":"aeeeb3a7-b131-406a-b2cb-dc787fb92a86","trusted":true},"cell_type":"code","source":"%%time\n# Fit model\nvalidationSplit = 0.1 # validation split\niEpochs = 12\nsModelCheckpoint ='model-dsbowl2018.h5'# 'model-dsbowl2018-351.h5'\n\nprocessFit(model, sModelCheckpoint)","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"2722157a25a3dcbede9b8d958e4209f5b87d7807","_cell_guid":"db03a900-2fa0-437e-8013-8cb655a3d758","trusted":true},"cell_type":"code","source":"%ls -l","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"d9ce1d89d65988f2cda5284d990b43331f215129","_cell_guid":"d64ea855-dd88-45f6-8a7b-e15bc06c1d0d","trusted":true},"cell_type":"code","source":"# load last model\nif os.path.isfile(sModelCheckpoint)==True:\n print(\" LOAD model: \",sModelCheckpoint)\n model = load_model(sModelCheckpoint, custom_objects={'mean_iou': mean_iou, 'dice_coef': dice_coef,})\nscore = model.evaluate(X_train, Y_train, verbose=1, batch_size=16)\nprint('Test loss:', score[0],'Test accuracy:', score[1])\nprc = 1 - validationSplit","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"8b4705d6f06c79f086296282de371a93962e1ec7","_cell_guid":"e32c0f39-f3d1-4735-b191-adf81d501a46","trusted":true},"cell_type":"code","source":"val_count=int(X_train.shape[0]*prc)\nscore = model.evaluate(X_train[:val_count], Y_train[:val_count], verbose=1, batch_size=16)\nprint('Val loss:', score[0],'Val accuracy:', score[1])\n# Predict on Valid\npreds_train = model.predict(X_train[:val_count], verbose=1)\n# Perform a sanity check on some random training samples\nix = random.randint(0, len(preds_train))\nimshow(X_train[ix]); plt.show()\nimshow(np.squeeze(Y_train[ix]));plt.show()\nimshow(np.squeeze(preds_train[ix]));plt.show()","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"a8d13d072015f5ed3ebbd2e0629b7a3614fbdfe5","_cell_guid":"baf8086f-162b-401f-bd6c-03d67c175063","trusted":true},"cell_type":"code","source":"val_count=int(X_train.shape[0]*prc)\n# Predict on val\npreds_val = model.predict(X_train[val_count:], verbose=1)\n# Perform a sanity check on some random validation samples\nix = random.randint(0, len(preds_val))\nimshow(X_train[val_count:][ix])\nplt.show()\nimshow(np.squeeze(Y_train[val_count:][ix]))\nplt.show()\nimshow(np.squeeze(preds_val[ix]))\nplt.show()","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"27a883f97767c98c6aefefc84a38fcc338eee306","_cell_guid":"508a12ae-38ee-4c9a-b2cf-299d4827dd18"},"cell_type":"markdown","source":"### Predict test","execution_count":null},{"metadata":{"_uuid":"b3cfd38cab5eb3b594ab18ef8b55fec0dfeb3755","_cell_guid":"590c30ee-39c3-49a4-8860-88d72414bab2","trusted":true},"cell_type":"code","source":"\n# Predict test\npreds_test = model.predict(X_test, verbose=1)\n# Create list of upsampled test masks\nbPostProcessing=True\nif bPostProcessing:\n preds_test_upsampled = makeUpsampledPostProcessingResizeMasks()\nelse: \n preds_test_upsampled = makeUpsampledResizeMasks(preds_test)","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"0c401fedba136b8aefb55d0f58fbe1b242fdb90b","_cell_guid":"050374c6-4207-47d6-bb3a-d0c97466b1d9","trusted":true},"cell_type":"code","source":"new_test_ids = []\nrles = []\nfor n, id_ in enumerate(test_ids):\n rle = list(prob_to_rles(preds_test_upsampled[n]))\n rles.extend(rle)\n new_test_ids.extend([id_] * len(rle))","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-output":false,"_uuid":"ef094ea28600a9b04bf4efdbc543d16628b7c576","_cell_guid":"b4c575e6-cb10-4307-909c-7a1e866ac29c","_kg_hide-input":false,"trusted":true},"cell_type":"code","source":"submission('sub351.csv')","execution_count":null,"outputs":[]},{"metadata":{"collapsed":true,"_uuid":"fb5e6f8cca872f1bd7036f6d9ac2ed2cab615536","_cell_guid":"222475b9-3171-461a-90f0-a820a6bd2634"},"cell_type":"markdown","source":"### LB score history: \n- 0.233 LB\n- 0.277 LB\n- 0.283 LB\n- 0.351 LB\n- 0.384 LB","execution_count":null},{"metadata":{"_kg_hide-output":true,"_uuid":"2a83eab66bf55194f300953bea5534b6a043130f","_cell_guid":"3f5e5a47-6133-4870-976a-a8e4fa7bf46c","_kg_hide-input":false,"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]}],"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat":4,"nbformat_minor":4}