{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"\n# Table of Contents\n* [Introduction](#section-intro)\n* [1) Unzip Datasets](#section-one)\n* [2) Sample Images](#section-two)\n\n\n* [3) VGG-16](#section-three)\n * [Paper](#section-three1)\n * [Architecture](#section-three2)\n * [Keras Implementation](#section-three3)\n \n\n* [4) Data Preparation & Augmentation](#section-four)\n * [Sample Augmentation](#section-four1)\n \n\n* [5) Pre-Trained VGG-16 Model & Transfer Learning](#section-five)\n * [Build Model](#section-five1)\n * [Callbacks](#section-five2)\n * [Fit](#section-five3)\n \n\n* [6) Interpreting Results and Error Analysis](#section-six)\n * [Learning Curve](#section-six1)\n * [Confusion Matrix & Classification Report](#section-six2)\n * [Error Analysis](#section-six3)\n\n\n* [7) Predict Test Set](#section-seven)\n\n\n* [Conclusion](#section-conc)\n* [Readings, Resources](#section-read)","metadata":{}},{"cell_type":"markdown","source":"\n\n# Introduction\n\nIn this notebook, my main goal is;\n\n- Implementing VGG-16 model from scratch with using Keras\n\n- Transfer Learning with pre-trained VGG-16 model","metadata":{}},{"cell_type":"code","source":"import pandas as pd\nimport numpy as np\nimport seaborn as sns\nimport matplotlib.pyplot as plt\nimport os\nimport random\nimport zipfile\nfrom sklearn.model_selection import train_test_split\nfrom sklearn.metrics import ConfusionMatrixDisplay, confusion_matrix, classification_report \nimport tensorflow as tf\nfrom keras.preprocessing.image import load_img, ImageDataGenerator\nfrom keras.models import Sequential, Model\nfrom keras.layers import Conv2D, MaxPool2D, Flatten, Dense, GlobalAveragePooling2D, Dropout, BatchNormalization, Input\nfrom keras.callbacks import ReduceLROnPlateau, EarlyStopping, ModelCheckpoint\nfrom keras.applications.vgg16 import VGG16, preprocess_input\n\nbatch_size = 128","metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-07-16T06:01:59.856302Z","iopub.execute_input":"2022-07-16T06:01:59.856687Z","iopub.status.idle":"2022-07-16T06:02:06.711401Z","shell.execute_reply.started":"2022-07-16T06:01:59.856641Z","shell.execute_reply":"2022-07-16T06:02:06.710424Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"seed = 666\ntf.random.set_seed(seed)\nnp.random.seed(seed)\nos.environ[\"PYTHONHASHSEED\"] = str(seed) \nrandom.seed(666)","metadata":{"execution":{"iopub.status.busy":"2022-07-16T06:02:06.713599Z","iopub.execute_input":"2022-07-16T06:02:06.713948Z","iopub.status.idle":"2022-07-16T06:02:06.720168Z","shell.execute_reply.started":"2022-07-16T06:02:06.713905Z","shell.execute_reply":"2022-07-16T06:02:06.719177Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"[take me to the top](#section-top)","metadata":{}},{"cell_type":"markdown","source":"\n\n# 1) Unzip Datasets","metadata":{}},{"cell_type":"code","source":"os.listdir(\"../input/dogs-vs-cats/\")","metadata":{"execution":{"iopub.status.busy":"2022-07-16T06:02:06.721716Z","iopub.execute_input":"2022-07-16T06:02:06.722248Z","iopub.status.idle":"2022-07-16T06:02:06.750119Z","shell.execute_reply.started":"2022-07-16T06:02:06.722203Z","shell.execute_reply":"2022-07-16T06:02:06.749219Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"TRAIN_PATH = \"../input/dogs-vs-cats/train.zip\"\nTEST_PATH = \"../input/dogs-vs-cats/test1.zip\"\n\nFILES = \"/kaggle/files/unzipped/\"\n\nwith zipfile.ZipFile(TRAIN_PATH, 'r') as zipp:\n zipp.extractall(FILES)\n \nwith zipfile.ZipFile(TEST_PATH, 'r') as zipp:\n zipp.extractall(FILES)","metadata":{"execution":{"iopub.status.busy":"2022-07-16T06:02:06.752703Z","iopub.execute_input":"2022-07-16T06:02:06.753096Z","iopub.status.idle":"2022-07-16T06:02:30.252435Z","shell.execute_reply.started":"2022-07-16T06:02:06.753054Z","shell.execute_reply":"2022-07-16T06:02:30.251451Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train_df = pd.DataFrame({\"file\": os.listdir(\"/kaggle/files/unzipped/train\")})\ntrain_df[\"label\"] = train_df[\"file\"].apply(lambda x: x.split(\".\")[0])\n\ntrain_df","metadata":{"execution":{"iopub.status.busy":"2022-07-16T06:02:30.254243Z","iopub.execute_input":"2022-07-16T06:02:30.254600Z","iopub.status.idle":"2022-07-16T06:02:30.317121Z","shell.execute_reply.started":"2022-07-16T06:02:30.254556Z","shell.execute_reply":"2022-07-16T06:02:30.316135Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"test_df = pd.DataFrame({\"file\": os.listdir(\"/kaggle/files/unzipped/test1\")})\n\ntest_df.head()","metadata":{"execution":{"iopub.status.busy":"2022-07-16T06:02:30.318797Z","iopub.execute_input":"2022-07-16T06:02:30.319297Z","iopub.status.idle":"2022-07-16T06:02:30.341445Z","shell.execute_reply.started":"2022-07-16T06:02:30.319250Z","shell.execute_reply":"2022-07-16T06:02:30.340473Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"fig, ax = plt.subplots(figsize = (6, 6), facecolor = \"#e5e5e5\")\nax.set_facecolor(\"#e5e5e5\")\n\nsns.countplot(x = \"label\", data = train_df, ax = ax)\n\nax.set_title(\"Distribution of Class Labels\")\nsns.despine()\nplt.show()","metadata":{"execution":{"iopub.status.busy":"2022-07-16T06:02:30.342940Z","iopub.execute_input":"2022-07-16T06:02:30.343478Z","iopub.status.idle":"2022-07-16T06:02:30.590838Z","shell.execute_reply.started":"2022-07-16T06:02:30.343434Z","shell.execute_reply":"2022-07-16T06:02:30.589906Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"[take me to the top](#section-top)","metadata":{}},{"cell_type":"markdown","source":"\n\n# 2) Sample Images","metadata":{}},{"cell_type":"code","source":"fig = plt.figure(1, figsize = (8, 8))\nfig.suptitle(\"Training Set Images (Sample)\")\n\nfor i in range(25):\n\n plt.subplot(5, 5, i + 1)\n image = load_img(FILES + \"train/\" + train_df[\"file\"][i])\n plt.imshow(image)\n plt.axis(\"off\")\n \nplt.tight_layout()\nplt.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-07-16T06:02:30.592300Z","iopub.execute_input":"2022-07-16T06:02:30.593215Z","iopub.status.idle":"2022-07-16T06:02:33.123045Z","shell.execute_reply.started":"2022-07-16T06:02:30.593168Z","shell.execute_reply":"2022-07-16T06:02:33.121684Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"fig = plt.figure(1, figsize = (8, 8))\nfig.suptitle(\"Sample Dog images from Training Set\")\n\nfor i in range(25):\n \n plt.subplot(5, 5, i + 1)\n image = load_img(FILES + \"train/\" + train_df.query(\"label == 'dog'\").file.values[i])\n plt.imshow(image)\n plt.axis(\"off\")\n \nplt.tight_layout()\nplt.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-07-16T06:02:33.124179Z","iopub.execute_input":"2022-07-16T06:02:33.124463Z","iopub.status.idle":"2022-07-16T06:02:36.544734Z","shell.execute_reply.started":"2022-07-16T06:02:33.124410Z","shell.execute_reply":"2022-07-16T06:02:36.543691Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"fig = plt.figure(1, figsize = (8, 8))\nfig.suptitle(\"Sample Cat images from Training Set\")\n\nfor i in range(25):\n \n plt.subplot(5, 5, i + 1)\n image = load_img(FILES + \"train/\" + train_df.query(\"label == 'cat'\").file.values[i])\n plt.imshow(image)\n plt.axis(\"off\")\n \nplt.tight_layout()\nplt.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-07-16T06:02:36.547812Z","iopub.execute_input":"2022-07-16T06:02:36.552975Z","iopub.status.idle":"2022-07-16T06:02:40.166710Z","shell.execute_reply.started":"2022-07-16T06:02:36.552929Z","shell.execute_reply":"2022-07-16T06:02:40.165827Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"[take me to the top](#section-top)","metadata":{}},{"cell_type":"markdown","source":"\n\n# 3) VGG-16","metadata":{}},{"cell_type":"markdown","source":"\n\n## Paper \n\n> In this work we investigate the effect of the convolutional network depth on its accuracy in the large-scale image recognition setting. Our main contribution is a thorough evaluation of networks of increasing depth using an architecture with very small (3x3) convolution filters, which shows that a significant improvement on the prior-art configurations can be achieved by pushing the depth to 16-19 weight layers. These findings were the basis of our ImageNet Challenge 2014 submission, where our team secured the first and the second places in the localisation and classification tracks respectively. We also show that our representations generalise well to other datasets, where they achieve state-of-the-art results. We have made our two best-performing ConvNet models publicly available to facilitate further research on the use of deep visual representations in computer vision.\n> \n\nhttps://arxiv.org/abs/1409.1556","metadata":{}},{"cell_type":"markdown","source":"\n\n## Architecture\n\n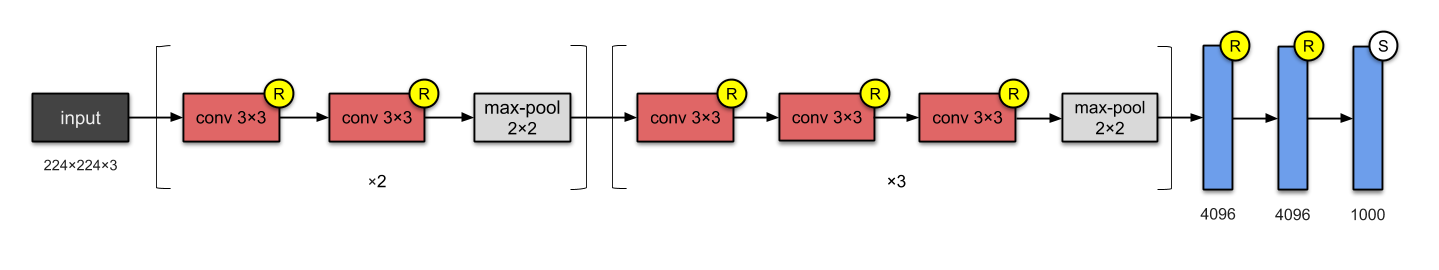\n\n> *https://towardsdatascience.com/illustrated-10-cnn-architectures-95d78ace614d","metadata":{}},{"cell_type":"markdown","source":"VGG-16 has nearly 138M parameters. It is more than EfficientNet, ResNext, etc.\n\nIt also has 75% accuracy on ImageNet data, that is a poor result wrt other architectures.","metadata":{}},{"cell_type":"markdown","source":"\n\n## Keras Implementation","metadata":{}},{"cell_type":"code","source":"def VGG_16(input_shape = (224, 224, 3), n_classes = 1000):\n \n model = Sequential(\n [\n Conv2D(filters = 64, kernel_size = (3, 3), padding = \"same\", activation = \"relu\", input_shape = input_shape),\n Conv2D(filters = 64, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n MaxPool2D(pool_size = (2, 2), strides = (2, 2)),\n \n Conv2D(filters = 128, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n Conv2D(filters = 128, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n MaxPool2D(pool_size = (2, 2), strides = (2, 2)),\n \n Conv2D(filters = 256, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n Conv2D(filters = 256, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n Conv2D(filters = 256, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n MaxPool2D(pool_size = (2, 2), strides = (2, 2)),\n \n Conv2D(filters = 512, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n Conv2D(filters = 512, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n Conv2D(filters = 512, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n MaxPool2D(pool_size = (2, 2), strides = (2, 2)),\n \n Conv2D(filters = 512, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n Conv2D(filters = 512, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n Conv2D(filters = 512, kernel_size = (3, 3), padding = \"same\", activation = \"relu\"),\n MaxPool2D(pool_size = (2, 2), strides = (2, 2)),\n \n Flatten(),\n Dense(units = 4096, activation = \"relu\"),\n Dense(units = 4096, activation = \"relu\"),\n Dense(units = n_classes, activation = \"softmax\")\n ]\n )\n \n return model","metadata":{"execution":{"iopub.status.busy":"2021-11-17T15:21:01.121865Z","iopub.execute_input":"2021-11-17T15:21:01.122115Z","iopub.status.idle":"2021-11-17T15:21:01.149804Z","shell.execute_reply.started":"2021-11-17T15:21:01.122069Z","shell.execute_reply":"2021-11-17T15:21:01.147875Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"[take me to the top](#section-top)","metadata":{}},{"cell_type":"markdown","source":"\n\n# 4) Data Preparation & Augmentation","metadata":{}},{"cell_type":"code","source":"train_data, val_data = train_test_split(train_df, \n test_size = 0.2, \n stratify = train_df[\"label\"], \n random_state = 666)","metadata":{"execution":{"iopub.status.busy":"2021-11-17T15:21:01.154065Z","iopub.execute_input":"2021-11-17T15:21:01.154773Z","iopub.status.idle":"2021-11-17T15:21:01.672609Z","shell.execute_reply.started":"2021-11-17T15:21:01.154738Z","shell.execute_reply":"2021-11-17T15:21:01.671887Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n## Sample Augmentation","metadata":{}},{"cell_type":"code","source":"datagen = ImageDataGenerator(\n rotation_range = 30, \n width_shift_range = 0.1,\n height_shift_range = 0.1, \n brightness_range = (0.5, 1), \n zoom_range = 0.2,\n horizontal_flip = True, \n rescale = 1./255,\n)\n\nsample_df = train_data.sample(1)\n\nsample_generator = datagen.flow_from_dataframe(\n dataframe = sample_df,\n directory = FILES + \"train/\",\n x_col = \"file\",\n y_col = \"label\",\n class_mode = \"categorical\",\n target_size = (224, 224),\n seed = 666\n)\n\nplt.figure(figsize = (14, 8))\n\nfor i in range(50):\n \n plt.subplot(5, 10, i + 1)\n \n for X, y in sample_generator:\n\n plt.imshow(X[0])\n plt.axis(\"off\")\n break\n \nplt.tight_layout()\nplt.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-11-17T15:21:01.674001Z","iopub.execute_input":"2021-11-17T15:21:01.674275Z","iopub.status.idle":"2021-11-17T15:21:05.383755Z","shell.execute_reply.started":"2021-11-17T15:21:01.674238Z","shell.execute_reply":"2021-11-17T15:21:05.383142Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"I just set simple options for generation. More options increase training time and we probably wait more until model converge.","metadata":{}},{"cell_type":"code","source":"train_datagen = ImageDataGenerator(\n rotation_range = 15, \n# width_shift_range = 0.1,\n# height_shift_range = 0.1, \n# brightness_range = (0.5, 1), \n# zoom_range = 0.1,\n horizontal_flip = True,\n preprocessing_function = preprocess_input\n)\n\nval_datagen = ImageDataGenerator(preprocessing_function = preprocess_input)","metadata":{"execution":{"iopub.status.busy":"2021-11-17T15:21:05.384928Z","iopub.execute_input":"2021-11-17T15:21:05.385341Z","iopub.status.idle":"2021-11-17T15:21:05.395672Z","shell.execute_reply.started":"2021-11-17T15:21:05.385308Z","shell.execute_reply":"2021-11-17T15:21:05.395124Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train_generator = train_datagen.flow_from_dataframe(\n dataframe = train_data,\n directory = FILES + \"train/\",\n x_col = \"file\",\n y_col = \"label\",\n class_mode = \"categorical\",\n target_size = (224, 224),\n batch_size = batch_size,\n seed = 666,\n)\n\nval_generator = val_datagen.flow_from_dataframe(\n dataframe = val_data,\n directory = FILES + \"train/\",\n x_col = \"file\",\n y_col = \"label\",\n class_mode = \"categorical\",\n target_size = (224, 224),\n batch_size = batch_size,\n seed = 666,\n shuffle = False\n)","metadata":{"execution":{"iopub.status.busy":"2021-11-17T15:21:05.396989Z","iopub.execute_input":"2021-11-17T15:21:05.398376Z","iopub.status.idle":"2021-11-17T15:21:05.670222Z","shell.execute_reply.started":"2021-11-17T15:21:05.39833Z","shell.execute_reply":"2021-11-17T15:21:05.669385Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"[take me to the top](#section-top)","metadata":{}},{"cell_type":"markdown","source":"\n\n# 5) Pre-Trained VGG-16 Model & Transfer Learning","metadata":{}},{"cell_type":"markdown","source":"\n## Build Model","metadata":{}},{"cell_type":"code","source":"base_model = VGG16(\n weights = \"imagenet\", \n input_shape = (224, 224, 3),\n include_top = False\n)\n\n\nfor layers in base_model.layers:\n layers.trainable = False\n\n\ndef vgg16_pretrained():\n \n model = Sequential(\n [\n base_model,\n GlobalAveragePooling2D(),\n Dense(100, activation = \"relu\"),\n Dropout(0.4),\n Dense(64, activation = \"relu\"),\n Dense(2, activation = \"softmax\")\n ]\n )\n \n return model\n\ntf.keras.backend.clear_session()","metadata":{"_kg_hide-output":true,"execution":{"iopub.status.busy":"2021-11-17T15:21:05.671591Z","iopub.execute_input":"2021-11-17T15:21:05.671915Z","iopub.status.idle":"2021-11-17T15:21:08.828658Z","shell.execute_reply.started":"2021-11-17T15:21:05.671878Z","shell.execute_reply":"2021-11-17T15:21:08.827944Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"model = vgg16_pretrained()\n\nmodel.compile(loss = \"categorical_crossentropy\", optimizer = \"adam\", metrics = \"accuracy\")\n\nmodel.summary()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-11-17T15:21:08.829811Z","iopub.execute_input":"2021-11-17T15:21:08.83005Z","iopub.status.idle":"2021-11-17T15:21:08.921724Z","shell.execute_reply.started":"2021-11-17T15:21:08.830018Z","shell.execute_reply":"2021-11-17T15:21:08.921061Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n## Callbacks","metadata":{}},{"cell_type":"code","source":"reduce_lr = ReduceLROnPlateau(\n monitor = \"val_accuracy\", \n patience = 2,\n verbose = 1, \n factor = 0.5, \n min_lr = 0.000000001\n)\n\nearly_stopping = EarlyStopping(\n monitor = \"val_accuracy\",\n patience = 5,\n verbose = 1,\n mode = \"max\",\n)\n\ncheckpoint = ModelCheckpoint(\n monitor = \"val_accuracy\",\n filepath = \"catdog_vgg16_.{epoch:02d}-{val_accuracy:.6f}.hdf5\",\n verbose = 1,\n save_best_only = True, \n save_weights_only = True\n)","metadata":{"execution":{"iopub.status.busy":"2021-11-17T15:21:08.922886Z","iopub.execute_input":"2021-11-17T15:21:08.923888Z","iopub.status.idle":"2021-11-17T15:21:08.929734Z","shell.execute_reply.started":"2021-11-17T15:21:08.923849Z","shell.execute_reply":"2021-11-17T15:21:08.928998Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n## Fit","metadata":{}},{"cell_type":"code","source":"history = model.fit(\n train_generator,\n epochs = 10, \n validation_data = val_generator,\n validation_steps = val_data.shape[0] // batch_size,\n steps_per_epoch = train_data.shape[0] // batch_size,\n callbacks = [reduce_lr, early_stopping, checkpoint]\n)","metadata":{"_kg_hide-output":true,"execution":{"iopub.status.busy":"2021-11-17T15:21:08.930722Z","iopub.execute_input":"2021-11-17T15:21:08.93139Z","iopub.status.idle":"2021-11-17T16:09:46.61678Z","shell.execute_reply.started":"2021-11-17T15:21:08.931352Z","shell.execute_reply":"2021-11-17T16:09:46.616004Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"[take me to the top](#section-top)","metadata":{}},{"cell_type":"markdown","source":"I didn't use excessive data augmentation or I didn't set large epochs for concerning time. In this notebook, score is not main goal.","metadata":{}},{"cell_type":"code","source":"tf.keras.backend.clear_session()\n\nmodel = vgg16_pretrained()\n\nmodel.load_weights(\"./catdog_vgg16_.10-0.983774.hdf5\")","metadata":{"execution":{"iopub.status.busy":"2021-11-17T16:09:46.620108Z","iopub.execute_input":"2021-11-17T16:09:46.620375Z","iopub.status.idle":"2021-11-17T16:09:46.767862Z","shell.execute_reply.started":"2021-11-17T16:09:46.620342Z","shell.execute_reply":"2021-11-17T16:09:46.767119Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n\n# 6) Interpreting Results and Error Analysis","metadata":{}},{"cell_type":"markdown","source":"\n\n## Learning Curve ","metadata":{}},{"cell_type":"code","source":"fig, axes = plt.subplots(1, 2, figsize = (12, 4))\n\nsns.lineplot(x = range(len(history.history[\"loss\"])), y = history.history[\"loss\"], ax = axes[0], label = \"Training Loss\")\nsns.lineplot(x = range(len(history.history[\"loss\"])), y = history.history[\"val_loss\"], ax = axes[0], label = \"Validation Loss\")\n\nsns.lineplot(x = range(len(history.history[\"accuracy\"])), y = history.history[\"accuracy\"], ax = axes[1], label = \"Training Accuracy\")\nsns.lineplot(x = range(len(history.history[\"accuracy\"])), y = history.history[\"val_accuracy\"], ax = axes[1], label = \"Validation Accuracy\")\naxes[0].set_title(\"Loss\"); axes[1].set_title(\"Accuracy\")\n\nsns.despine()\nplt.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-11-17T16:09:46.769043Z","iopub.execute_input":"2021-11-17T16:09:46.769316Z","iopub.status.idle":"2021-11-17T16:09:47.158315Z","shell.execute_reply.started":"2021-11-17T16:09:46.769282Z","shell.execute_reply":"2021-11-17T16:09:47.157589Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"val_pred = model.predict(val_generator, steps = np.ceil(val_data.shape[0] / batch_size))\nval_data.loc[:, \"val_pred\"] = np.argmax(val_pred, axis = 1)\n\nlabels = dict((v, k) for k, v in val_generator.class_indices.items())\n\nval_data.loc[:, \"val_pred\"] = val_data.loc[:, \"val_pred\"].map(labels)","metadata":{"_kg_hide-input":false,"execution":{"iopub.status.busy":"2021-11-17T16:09:47.159397Z","iopub.execute_input":"2021-11-17T16:09:47.160194Z","iopub.status.idle":"2021-11-17T16:10:08.352711Z","shell.execute_reply.started":"2021-11-17T16:09:47.160141Z","shell.execute_reply":"2021-11-17T16:10:08.351932Z"},"_kg_hide-output":true,"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"labels","metadata":{"execution":{"iopub.status.busy":"2021-11-17T16:10:08.354209Z","iopub.execute_input":"2021-11-17T16:10:08.354692Z","iopub.status.idle":"2021-11-17T16:10:08.360665Z","shell.execute_reply.started":"2021-11-17T16:10:08.354655Z","shell.execute_reply":"2021-11-17T16:10:08.359854Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"[take me to the top](#section-top)","metadata":{}},{"cell_type":"markdown","source":"\n## Confusion Matrix & Classification Report","metadata":{}},{"cell_type":"code","source":"fig, ax = plt.subplots(figsize = (9, 6))\n\ncm = confusion_matrix(val_data[\"label\"], val_data[\"val_pred\"])\n\ndisp = ConfusionMatrixDisplay(confusion_matrix = cm, display_labels = [\"cat\", \"dog\"])\ndisp.plot(cmap = plt.cm.Blues, ax = ax)\n\nax.set_title(\"Validation Set\")\nplt.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-11-17T16:10:08.362153Z","iopub.execute_input":"2021-11-17T16:10:08.362776Z","iopub.status.idle":"2021-11-17T16:10:08.610647Z","shell.execute_reply.started":"2021-11-17T16:10:08.362738Z","shell.execute_reply":"2021-11-17T16:10:08.609982Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"print(classification_report(val_data[\"label\"], val_data[\"val_pred\"]))","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-11-17T16:10:08.612029Z","iopub.execute_input":"2021-11-17T16:10:08.612594Z","iopub.status.idle":"2021-11-17T16:10:08.91601Z","shell.execute_reply.started":"2021-11-17T16:10:08.612544Z","shell.execute_reply":"2021-11-17T16:10:08.914933Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n## Error Analysis","metadata":{}},{"cell_type":"code","source":"val_errors = val_data[(val_data.label) != (val_data.val_pred)].reset_index(drop = True)\nval_errors","metadata":{"execution":{"iopub.status.busy":"2021-11-17T16:10:08.917321Z","iopub.execute_input":"2021-11-17T16:10:08.91756Z","iopub.status.idle":"2021-11-17T16:10:08.933454Z","shell.execute_reply.started":"2021-11-17T16:10:08.917527Z","shell.execute_reply":"2021-11-17T16:10:08.93179Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"fig = plt.figure(1, figsize = (24, 20))\n\nfor i in range(81):\n \n plt.subplot(9, 9, i + 1)\n image = load_img(\"/kaggle/files/unzipped/train/\" + val_errors.file[i])\n plt.imshow(image)\n plt.axis(\"off\")\n plt.title(f\"True Value: {val_errors['label'][i]} \\nPrediction: {val_errors['val_pred'][i]}\") \n \nplt.tight_layout()\nplt.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-11-17T16:12:31.877984Z","iopub.execute_input":"2021-11-17T16:12:31.878265Z","iopub.status.idle":"2021-11-17T16:12:37.958937Z","shell.execute_reply.started":"2021-11-17T16:12:31.878234Z","shell.execute_reply":"2021-11-17T16:12:37.95822Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"[take me to the top](#section-top)","metadata":{}},{"cell_type":"markdown","source":"\n# 7) Predict Test Set","metadata":{}},{"cell_type":"code","source":"test_datagen = ImageDataGenerator(preprocessing_function = preprocess_input)\n\ntest_generator = test_datagen.flow_from_dataframe(\n dataframe = test_df,\n directory = FILES + \"test1/\",\n x_col = \"file\",\n y_col = None,\n class_mode = None,\n target_size = (224, 224),\n batch_size = batch_size,\n seed = 666,\n shuffle = False\n)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-11-17T16:10:11.000842Z","iopub.execute_input":"2021-11-17T16:10:11.001262Z","iopub.status.idle":"2021-11-17T16:10:11.139981Z","shell.execute_reply.started":"2021-11-17T16:10:11.001227Z","shell.execute_reply":"2021-11-17T16:10:11.139248Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"test_preds = model.predict(test_generator, steps = np.ceil(test_df.shape[0] / batch_size))\n\ntest_df[\"test_preds\"] = np.argmax(test_preds, axis = 1)\nlabels = dict((v,k) for k,v in train_generator.class_indices.items())\n\ntest_df['test_preds'] = test_df['test_preds'].map(labels)","metadata":{"execution":{"iopub.status.busy":"2021-11-17T16:10:11.141215Z","iopub.execute_input":"2021-11-17T16:10:11.14189Z","iopub.status.idle":"2021-11-17T16:11:05.280676Z","shell.execute_reply.started":"2021-11-17T16:10:11.141852Z","shell.execute_reply":"2021-11-17T16:11:05.279751Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"sample_test = test_df.sample(64).reset_index(drop = True)\n\nfig = plt.figure(1, figsize = (24, 20))\nfig.suptitle(\"Sample Predictions\")\n\nfor i in range(len(sample_test)):\n \n plt.subplot(8, 8, i + 1)\n image = load_img(\"/kaggle/files/unzipped/test1/\" + sample_test.file[i])\n plt.imshow(image)\n plt.axis(\"off\")\n plt.title(f\"Predicted as {sample_test['test_preds'][i]}\")\n \nplt.tight_layout()\nplt.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-11-17T16:11:05.282203Z","iopub.execute_input":"2021-11-17T16:11:05.282466Z","iopub.status.idle":"2021-11-17T16:11:11.335643Z","shell.execute_reply.started":"2021-11-17T16:11:05.282432Z","shell.execute_reply":"2021-11-17T16:11:11.333228Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n# Conclusion","metadata":{}},{"cell_type":"markdown","source":"There are lots of architectures about image classification and you can easily reach their trained parameters. You can use that parameters for transfer learning and fine tuning. You don't need to know an algorithm's architecture, but having knowledge about architectures and reading its papers probably gives you an advantage.\n\n\nAlso, I saw lots of notebook about this topic with a few upvotes and much more forks. Please upvote notebooks if you find it useful.","metadata":{}},{"cell_type":"markdown","source":"\n\n# Readings, Resources","metadata":{}},{"cell_type":"markdown","source":"https://towardsdatascience.com/illustrated-10-cnn-architectures-95d78ace614d#c5a6\n\nhttps://keras.io/guides/transfer_learning/\n\nhttps://paperswithcode.com/sota/image-classification-on-imagenet\n\nhttps://viso.ai/deep-learning/vgg-very-deep-convolutional-networks/\n\nhttps://medium.com/mini-distill/effect-of-batch-size-on-training-dynamics-21c14f7a716e\n\nhttps://ai.stackexchange.com/a/4413\n\nhttps://www.kaggle.com/rajmehra03/a-comprehensive-guide-to-transfer-learning\n\nhttps://www.kaggle.com/dansbecker/transfer-learning\n\n\nGood notebooks about this dataset\n\nhttps://www.kaggle.com/uysimty/keras-cnn-dog-or-cat-classification\n\nhttps://www.kaggle.com/bhuvanchennoju/hey-siri-is-it-a-or-class-f1-0-992\n\n\nYou can also look at\n\nhttps://www.kaggle.com/mustafacicek/mnist-cnn-data-augmentation","metadata":{}}]}