
I want to thank the organizers for providing such an interesting and challenging competition, especially since the metric is really tricky and so much thought had to be put into it.
\nMy final solution is based on generating a bunch of images with SDXL-turbo, converting them to SVGs, and then adding an optimized patch to significantly improve the aesthetic score. After that, I use a proxy function for the VQA model to find the best SVG to use in the end.
\nAdding this to the end of your SVG file will improve the average aesthetic score to around 0.7, almost independently of the background:
\n
The VQA score will suffer by adding this patch, partly because it uses around 3.5k bytes which cannot be used further in the original image conversion and also because it is a big chunk of noise in your image. However, the overall final score will be higher by quite a bit, especially when you can select which image to use in order to not hurt the VQA score too much.
\nFinal solution here and Github with all the codebase here.
\nExample:
\n
Nothing special here, I just used SDXL-turbo to generate a bunch of images. I tried multiple other models, finetuning SDXL-turbo to a preference dataset using the competition score, finetuning using REFL with image-reward, DPO with VQA as reward, etc.
\nThe best overall generation I could get was using SDXL-turbo with a set of prompts I selected via beam search in a generated dataset. Basically, I ran around 200 different prompts in a dataset and picked the subset that generated the best images when ensembled together. The more prompts I added, the better the results, even when using 20+ prompts.
\nMost prompts focus on simple, SVG-like images that can be readily converted to SVG using Vtracer. Also, explicitly adding no text and no other colors to my negative prompts consistently improved the results a little bit.
Initially, I was using primitive to convert the images to SVGs. I still believe the images generated by primitive can be much better than Vtracer when tuned properly, but the CPUs on Kaggle are not good enough to run it on time: it took over 30 seconds to generate 50 SVG <paths> for a single image using all cores (primitive is written in GO and is heavily parallelized).
On the other hand, Vtracer was able to convert an image using a single core in less than 2 seconds, while the results were almost as good. After adding some polygon simplification, size clipping, and tuning the parameters a bit, I was able to generate good enough SVGs with around 6k bytes per image. Finally, I added a small white OCR decoy with a black background, so it could not be missed.
\nAfter generating all the SVGs, the selection of the best one is done using a proxy function over the VQA score. I simply followed the method described in this paper and used the \"Yes\" vs \"No\" probability for this question: \"f<image>answer en Question: Does this image contain {description}? Answer Yes or No.\\nAnswer:\".
This actually turned out to work better than generating questions, choices, and answers using Qwen-2.5 and running the original VQA score. I believe this is because the proxy function is much more robust when we can only evaluate a few questions, but I could be wrong and my question generation model was just bad.
\nAlthough using other model versions (3b 224, 10b 224 and 3b 448) also correlated with the main metric, the original VQA model (10b 448) was always better, even if much slower and using less prompts because of that.
\nAfter I noticed ensembling would be quite powerful, I had to find a way to efficiently use all Kaggle resources. I was heavily underusing GPUs because Vtracer is CPU bound, and Kaggle machines have really slow CPUs. For example, generating images with SDXL-turbo was actually faster than running Vtracer on a single thread.
\nIn the end, I was able to use almost 100% of the resources by running three processes in the background:
\ncuda:0cpucuda:1and then controlling the flow within the main notebook. For example, whenever a few images are ready from SDXL, we can start converting while we keep generating more images in parallel. The same for scoring when a few SVGs are ready.
\nThis way, I was able to run 28 different SVGs, but I believe I could push this a bit more because my solution was running in around 55 seconds per example on average.
\nIn order to find the patch, I built a fully differentiable version of every step of the preprocessing, aesthetic model, and VQA. With this differentiable pipeline, I tried so many things:
\nAll of those solutions do work, but they are either too slow, require too much GPU memory to run on Kaggle, generate SVGs way over 10kb, or are just too unstable to make sure they will work every time. In the end, I tried to do something similar to what other people did in optimizing directly over the generated SVG, but could not get a proxy function over the VQA score to work well unfortunately =/
\nThe best solution I could find was to just search a small subset of paths that, when added over the background of the actual scene, will improve the average aesthetic score in a dataset. Due to all the preprocessing and especially cropping, the aesthetic score varies quite a bit from image to image, but the average over a significant amount of images will improve measurably. Also, because of the cropping, the position of the patch cannot be so close to the edges; otherwise, the score will be much lower.
\nBecause the patch uses a lot of bytes, I had to balance patch size and VQA score. The bigger the patch, the less information VTracer could use to convert the SVG. I was able to get patches with over 0.8 aesthetic score by using much more bytes, but then the VQA hit would be too high.
\nMy final patch has around 100x100 pixels and was found using a simple gradient ascent over the aesthetic score on a small dataset of 150 images. I selected a bunch of background from a previous submission, started the SVG from scratch in a grid like pattern of 96x96 pixels, and run gradient ascent. This notebook shows the process, it took a few hours to find a good aesthetic patch and it is extremely sensitive on where in the image it is.
\nI think the nicest thing I tried was to plug the differentiable pipeline into ReNO and optimize the diffusion process directly against the full loss. It generated some really nice images and was actually significantly better than a single run of SDXL-turbo, but it was very inefficient and did not work as well as the simple ensembling I did in the end. Also, I could only use the 3B-224 version of the VQA, since the bigger one would not run with gradients enabled on a T4 with 16GB of memory, so the loss did not perfectly correlate with the competition score.
\nThis notebook shows the improvement from the first generated image from SDXL and the images in between, optimizing the metric alongside the way on the diffusion process itself.
", "comments": [ { "id": 3213648, "author_name": "BeaKaggle", "author_url": "", "post_date": "2025-05-30T09:31:22.563000", "content": "Nice work and explanation @tomirol Thanks. The link to your notebook for gradient ascent finding aesthetic patch does not work. Would you provide that notebook? Thank you
", "votes": 1, "replies": [ { "id": 3213772, "author_name": "matheus", "author_url": "", "post_date": "2025-05-30T12:21:07.657000", "content": "Hey thanks for pointing it out, just made it public now.
", "votes": 0, "replies": [ { "id": 3214024, "author_name": "BeaKaggle", "author_url": "", "post_date": "2025-05-30T19:07:34.513000", "content": "Thanks @tomirol
", "votes": 1, "replies": [] } ] } ] }, { "id": 3213344, "author_name": "Blansteinia454", "author_url": "", "post_date": "2025-05-29T21:00:07.970000", "content": "now i try make something similar, thnx 4 this
", "votes": 1, "replies": [] }, { "id": 3212256, "author_name": "Md Feroz Ahmed", "author_url": "", "post_date": "2025-05-29T15:03:49.940000", "content": "A very interesting solution .
", "votes": 1, "replies": [] }, { "id": 3211745, "author_name": "Mikhail Golubchik", "author_url": "", "post_date": "2025-05-28T19:14:56.137000", "content": "A very interesting solution with excelent scor. And thank you for sharing the notebook. The girl in the picture turned out very nice.
\nI also tried to somehow improve the aesthetic score. I was trying to pick out certain shapes within a broad frame of the image, but it didn’t work out well. The VQA score dropped significantly, and the increase in AES didn’t make up for it.
\nYour approach to increasing aesthetic score is great
Hey thanks man! It was quite tricky finding the position to put the patch, because it gets a low score on the borders (due to cropping augmentation) but will lower the VQA score on the center.
", "votes": 1, "replies": [] } ] }, { "id": 3217666, "author_name": "BeaKaggle", "author_url": "", "post_date": "2025-06-05T09:26:41.110000", "content": "Hi @tomirol in order to run your diffvg optimization notebook https://www.kaggle.com/code/tomirol/sdxl-turbo-vtracer-aest-opt?scriptVersionId=242366685 , would you mind to make the private datasets public? Thank you
", "votes": 0, "replies": [ { "id": 3217962, "author_name": "matheus", "author_url": "", "post_date": "2025-06-05T15:41:41.487000", "content": "Hey sorry for the trouble - all datasets should be public now. Thanks for letting me know!
", "votes": 0, "replies": [] } ] } ], "comment_count": 9, "messages": [ { "id": 3211481, "postDate": "2025-05-28T13:33:35.333Z", "content": "I want to thank the organizers for providing such an interesting and challenging competition, especially since the metric is really tricky and so much thought had to be put into it.
\nMy final solution is based on generating a bunch of images with SDXL-turbo, converting them to SVGs, and then adding an optimized patch to significantly improve the aesthetic score. After that, I use a proxy function for the VQA model to find the best SVG to use in the end.
\nAdding this to the end of your SVG file will improve the average aesthetic score to around 0.7, almost independently of the background:
\n
The VQA score will suffer by adding this patch, partly because it uses around 3.5k bytes which cannot be used further in the original image conversion and also because it is a big chunk of noise in your image. However, the overall final score will be higher by quite a bit, especially when you can select which image to use in order to not hurt the VQA score too much.
\nFinal solution here and Github with all the codebase here.
\nExample:
\n
Nothing special here, I just used SDXL-turbo to generate a bunch of images. I tried multiple other models, finetuning SDXL-turbo to a preference dataset using the competition score, finetuning using REFL with image-reward, DPO with VQA as reward, etc.
\nThe best overall generation I could get was using SDXL-turbo with a set of prompts I selected via beam search in a generated dataset. Basically, I ran around 200 different prompts in a dataset and picked the subset that generated the best images when ensembled together. The more prompts I added, the better the results, even when using 20+ prompts.
\nMost prompts focus on simple, SVG-like images that can be readily converted to SVG using Vtracer. Also, explicitly adding no text and no other colors to my negative prompts consistently improved the results a little bit.
Initially, I was using primitive to convert the images to SVGs. I still believe the images generated by primitive can be much better than Vtracer when tuned properly, but the CPUs on Kaggle are not good enough to run it on time: it took over 30 seconds to generate 50 SVG <paths> for a single image using all cores (primitive is written in GO and is heavily parallelized).
On the other hand, Vtracer was able to convert an image using a single core in less than 2 seconds, while the results were almost as good. After adding some polygon simplification, size clipping, and tuning the parameters a bit, I was able to generate good enough SVGs with around 6k bytes per image. Finally, I added a small white OCR decoy with a black background, so it could not be missed.
\nAfter generating all the SVGs, the selection of the best one is done using a proxy function over the VQA score. I simply followed the method described in this paper and used the \"Yes\" vs \"No\" probability for this question: \"f<image>answer en Question: Does this image contain {description}? Answer Yes or No.\\nAnswer:\".
This actually turned out to work better than generating questions, choices, and answers using Qwen-2.5 and running the original VQA score. I believe this is because the proxy function is much more robust when we can only evaluate a few questions, but I could be wrong and my question generation model was just bad.
\nAlthough using other model versions (3b 224, 10b 224 and 3b 448) also correlated with the main metric, the original VQA model (10b 448) was always better, even if much slower and using less prompts because of that.
\nAfter I noticed ensembling would be quite powerful, I had to find a way to efficiently use all Kaggle resources. I was heavily underusing GPUs because Vtracer is CPU bound, and Kaggle machines have really slow CPUs. For example, generating images with SDXL-turbo was actually faster than running Vtracer on a single thread.
\nIn the end, I was able to use almost 100% of the resources by running three processes in the background:
\ncuda:0cpucuda:1and then controlling the flow within the main notebook. For example, whenever a few images are ready from SDXL, we can start converting while we keep generating more images in parallel. The same for scoring when a few SVGs are ready.
\nThis way, I was able to run 28 different SVGs, but I believe I could push this a bit more because my solution was running in around 55 seconds per example on average.
\nIn order to find the patch, I built a fully differentiable version of every step of the preprocessing, aesthetic model, and VQA. With this differentiable pipeline, I tried so many things:
\nAll of those solutions do work, but they are either too slow, require too much GPU memory to run on Kaggle, generate SVGs way over 10kb, or are just too unstable to make sure they will work every time. In the end, I tried to do something similar to what other people did in optimizing directly over the generated SVG, but could not get a proxy function over the VQA score to work well unfortunately =/
\nThe best solution I could find was to just search a small subset of paths that, when added over the background of the actual scene, will improve the average aesthetic score in a dataset. Due to all the preprocessing and especially cropping, the aesthetic score varies quite a bit from image to image, but the average over a significant amount of images will improve measurably. Also, because of the cropping, the position of the patch cannot be so close to the edges; otherwise, the score will be much lower.
\nBecause the patch uses a lot of bytes, I had to balance patch size and VQA score. The bigger the patch, the less information VTracer could use to convert the SVG. I was able to get patches with over 0.8 aesthetic score by using much more bytes, but then the VQA hit would be too high.
\nMy final patch has around 100x100 pixels and was found using a simple gradient ascent over the aesthetic score on a small dataset of 150 images. I selected a bunch of background from a previous submission, started the SVG from scratch in a grid like pattern of 96x96 pixels, and run gradient ascent. This notebook shows the process, it took a few hours to find a good aesthetic patch and it is extremely sensitive on where in the image it is.
\nI think the nicest thing I tried was to plug the differentiable pipeline into ReNO and optimize the diffusion process directly against the full loss. It generated some really nice images and was actually significantly better than a single run of SDXL-turbo, but it was very inefficient and did not work as well as the simple ensembling I did in the end. Also, I could only use the 3B-224 version of the VQA, since the bigger one would not run with gradients enabled on a T4 with 16GB of memory, so the loss did not perfectly correlate with the competition score.
\nThis notebook shows the improvement from the first generated image from SDXL and the images in between, optimizing the metric alongside the way on the diffusion process itself.
", "rawMarkdown": "I want to thank the organizers for providing such an interesting and challenging competition, especially since the metric is really tricky and so much thought had to be put into it.\n\nMy final solution is based on generating a bunch of images with SDXL-turbo, converting them to SVGs, and then adding an optimized patch to significantly improve the aesthetic score. After that, I use a proxy function for the VQA model to find the best SVG to use in the end.\n\nAdding this to the end of your SVG file will improve the *average* aesthetic score to around **0.7**, almost independently of the background:\n\n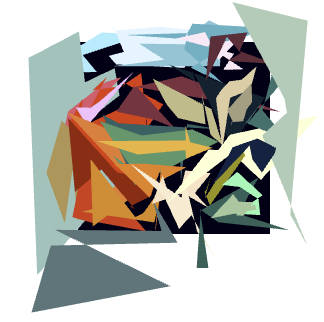\n\nThe VQA score will suffer by adding this patch, partly because it uses around 3.5k bytes which cannot be used further in the original image conversion and also because it is a big chunk of noise in your image. However, the overall final score will be higher by quite a bit, especially when you can select which image to use in order to not hurt the VQA score too much.\n\nFinal solution [here](https://www.kaggle.com/code/tomirol/fork-of-sdxl-turbo-vtracer-multi-gpu-10b-448-24x?scriptVersionId=242123343) and Github with all the codebase [here](https://github.com/matheuspf/draw).\n\nExample:\n\n\n\n#### Generating images\n\nNothing special here, I just used SDXL-turbo to generate a bunch of images. I tried multiple other models, finetuning SDXL-turbo to a preference dataset using the competition score, finetuning using REFL with [image-reward](https://github.com/THUDM/ImageReward), DPO with VQA as reward, etc.\n\nThe best overall generation I could get was using SDXL-turbo with a set of prompts I selected via beam search in a generated dataset. Basically, I ran around 200 different prompts in a dataset and picked the subset that generated the best images when ensembled together. The more prompts I added, the better the results, even when using 20+ prompts.\n\nMost prompts focus on simple, SVG-like images that can be readily converted to SVG using Vtracer. Also, explicitly adding `no text` and `no other colors` to my negative prompts consistently improved the results a little bit.\n\n#### Raster to vector\n\nInitially, I was using [primitive](https://github.com/fogleman/primitive) to convert the images to SVGs. I still believe the images generated by primitive can be much better than Vtracer when tuned properly, but the CPUs on Kaggle are not good enough to run it on time: it took over 30 seconds to generate 50 SVG `Nice work and explanation @tomirol Thanks. The link to your notebook for gradient ascent finding aesthetic patch does not work. Would you provide that notebook? Thank you
", "rawMarkdown": "Nice work and explanation @tomirol Thanks. The link to your notebook for gradient ascent finding aesthetic patch does not work. Would you provide that notebook? Thank you", "votes": 1, "replies": [ { "id": 3213772, "postDate": "2025-05-30T12:21:07.657Z", "content": "Hey thanks for pointing it out, just made it public now.
", "rawMarkdown": "Hey thanks for pointing it out, just made it public now.", "replies": [ { "id": 3214024, "postDate": "2025-05-30T19:07:34.513Z", "content": "Thanks @tomirol
", "rawMarkdown": "Thanks @tomirol ", "votes": 1 } ] } ] }, { "id": 3213344, "postDate": "2025-05-29T21:00:07.970Z", "content": "now i try make something similar, thnx 4 this
", "rawMarkdown": "now i try make something similar, thnx 4 this", "votes": 1 }, { "id": 3212256, "postDate": "2025-05-29T15:03:49.940Z", "content": "A very interesting solution .
", "rawMarkdown": "A very interesting solution .\n", "votes": 1 }, { "id": 3211745, "postDate": "2025-05-28T19:14:56.137Z", "content": "A very interesting solution with excelent scor. And thank you for sharing the notebook. The girl in the picture turned out very nice.
\nI also tried to somehow improve the aesthetic score. I was trying to pick out certain shapes within a broad frame of the image, but it didn’t work out well. The VQA score dropped significantly, and the increase in AES didn’t make up for it.
\nYour approach to increasing aesthetic score is great
Hey thanks man! It was quite tricky finding the position to put the patch, because it gets a low score on the borders (due to cropping augmentation) but will lower the VQA score on the center.
", "rawMarkdown": "Hey thanks man! It was quite tricky finding the position to put the patch, because it gets a low score on the borders (due to cropping augmentation) but will lower the VQA score on the center.", "votes": 1 } ] }, { "id": 3217666, "postDate": "2025-06-05T09:26:41.110Z", "content": "Hi @tomirol in order to run your diffvg optimization notebook https://www.kaggle.com/code/tomirol/sdxl-turbo-vtracer-aest-opt?scriptVersionId=242366685 , would you mind to make the private datasets public? Thank you
", "rawMarkdown": "Hi @tomirol in order to run your diffvg optimization notebook https://www.kaggle.com/code/tomirol/sdxl-turbo-vtracer-aest-opt?scriptVersionId=242366685 , would you mind to make the private datasets public? Thank you", "replies": [ { "id": 3217962, "postDate": "2025-06-05T15:41:41.487Z", "content": "Hey sorry for the trouble - all datasets should be public now. Thanks for letting me know!
", "rawMarkdown": "Hey sorry for the trouble - all datasets should be public now. Thanks for letting me know!" } ] } ], "complete": true, "source": "live", "fetched_at": "2026-10-20T09:10:26Z", "competition_id": 89659, "competition_slug": "drawing-with-llms", "team_id": 13404672, "solution_url": "/competitions/drawing-with-llms/writeups/tomirol-5th-place-solution-vtracer-and-diffvg-opti" }