
First of all, I want to thank my teammates for this fun ride.
\n
Since we knew that the data is synthetic and how it was produced, we had a look at the SurvivalGAN paper. As you can see in this image, TimeRegressor is trained together with features and class information. Therefore we split the problem into two:
\nFor the regression part, we have trained and ensembled 2 models providing efs as an extra feature. Then for the test and validation sets, we make inference by setting efs=1. With this trick, we estimate how long efs time can be if there is efs. Our models are xgboost and histgbm.
\nFor classification, we use RealMLP, HistGBM and Catboost models with no feature engineering. We ensemble these models by the weights tuned on CV. We then combine it with regression predictions to calculate the risk scores:
\nR = p(efs=1) * p(efs_time | efs=1)
\np(efs_time | efs=1) is sigmoid(-regression_prediction) in our case.
Additionally, we train a neural network which approximates the competition metric and directly predicts the risk scores. It uses regression prediction from tree models and optimizes the approximate competition metric and auxiliary binary classification loss.
\n ():\n y_risk, y_time, y_efs = y_risk.ravel(), y_time.ravel(), y_efs.ravel()\n\n loss = []\n i ((y_risk)):\n y_efs[i] == :\n filt = y_time[i] < y_time\n s = (y_risk - y_risk[i]).tanh()\n loss.append(s[filt])\n\n loss = torch.cat(loss).mean()\n loss\nWe rank ensemble it with our main pipeline.
\nHere is our inference notebook: https://www.kaggle.com/code/karakasatarik/2nd-place-solution-inference
\nOnce the problem is split into two like we did, it was possible to get a gold medal even with automated machine learning.
\nHere are our experiments using AutoGluon:
\n| AutoGluon Setting | \nOOF Score | \nPublic LB | \nPrivate LB | \n
|---|---|---|---|
| Medium Quality | \n0.6884 | \n0.694 | \n0.697 | \n
| High Quality | \n0.6910 | \n0.694 | \n0.698 | \n
| Best Quality | \n0.6921 | \n0.695 | \n0.699 | \n
Anil attempted to improve the efs-classifier model's outputs by tuning a custom sigmoid function on the OOF predictions:
\ncalibrated_proba = 1 / (1 + np.exp(-beta * (raw_proba - gamma)))
This calibration led to a ~0.002 improvement in OOF but resulted in a 0.001 decrease on the public LB and a 0.001 improvement on the private LB.
", "comments": [ { "id": 3141837, "author_name": "Sergey Bryansky", "author_url": "", "post_date": "2025-03-06T00:19:10.330000", "content": "similar approach, tried to solve ranking and classification tasks independently in extreme cases then combine using magic formula p(efs=1) * p(efs_time | efs=1) 😄
Congratulations!🎊
\nThis is my first time using a ranking model. I have tried to use ranking models xgb, cab, lgbm, but all failed for various reasons. Among them lgbm reported error: \"LightGBMError: Number of rows 25920 exceeds upper limit of 10000 for a query.\"
\nMay I ask you what ranking model you are using? Is this type of modeling time consuming?
", "votes": 0, "replies": [] } ] }, { "id": 3141820, "author_name": "minerppdy", "author_url": "", "post_date": "2025-03-06T00:10:53.230000", "content": "haha,quite similar solution with you!
", "votes": 8, "replies": [ { "id": 3141841, "author_name": "Herra Huu", "author_url": "", "post_date": "2025-03-06T00:22:17.613000", "content": "I will join the club as well :D
", "votes": 4, "replies": [] }, { "id": 3141948, "author_name": "Robert Hatch", "author_url": "", "post_date": "2025-03-06T01:53:42.907000", "content": "Might be everyone in top5, lol. Seems like a critical trick, even for the one of us without as good a public LB score, haha.
", "votes": 1, "replies": [] }, { "id": 3142055, "author_name": "Gunes Evitan", "author_url": "", "post_date": "2025-03-06T04:07:11.843000", "content": "Looks like this was the magic. I was working on survival analysis 4 years ago and now I wonder if it would work on those organic datasets :D
", "votes": 0, "replies": [] } ] }, { "id": 3144359, "author_name": "Ahmet Erdem Pamuk", "author_url": "", "post_date": "2025-03-08T08:52:39.310000", "content": "Awesome solution, thanks for providing this valuable insight, congratulations to your team!
", "votes": 3, "replies": [] }, { "id": 3141846, "author_name": "Siddhant Chaudhary", "author_url": "", "post_date": "2025-03-06T00:28:36.603000", "content": "Congratulations to you and the team. Impressive work!
", "votes": 3, "replies": [ { "id": 3141858, "author_name": "", "author_url": "", "post_date": "2025-03-06T00:40:30.993000", "content": "", "votes": 0, "replies": [] } ] }, { "id": 3143624, "author_name": "Oluwatobi Betiku", "author_url": "", "post_date": "2025-03-07T12:11:14.870000", "content": "Awesome solution, thanks for providing this valuable insight, congratulations to your team!
", "votes": 1, "replies": [] }, { "id": 3141974, "author_name": "guo dashuai", "author_url": "", "post_date": "2025-03-06T02:26:23.573000", "content": "When I heard your teammate mention that you got a CV of 0.7 using synthetic data, I was quite worried for you. But as it turns out, you did exceptionally well with very meticulous thinking. My best wishes to you all.
", "votes": 1, "replies": [ { "id": 3142258, "author_name": "Gunes Evitan", "author_url": "", "post_date": "2025-03-06T08:38:00.720000", "content": "I remember that I said \"the winners team cv score would probably be around 0.7\" and you inferred rest of it lol. I also don't remember mentioning anything about using synthetic data. I'm sorry if I mislead you.
", "votes": 0, "replies": [ { "id": 3142269, "author_name": "guo dashuai", "author_url": "", "post_date": "2025-03-06T08:52:16.033000", "content": "You've done a fantastic job, congratulations!
", "votes": 0, "replies": [] } ] } ] }, { "id": 3141859, "author_name": "Aleksandr Larko", "author_url": "", "post_date": "2025-03-06T00:41:12.913000", "content": "Good job!Congratulations!
", "votes": 1, "replies": [] }, { "id": 3141818, "author_name": "Cody_Null", "author_url": "", "post_date": "2025-03-06T00:10:30.873000", "content": "Elegant solution! Great work, seems I should have given more attention to the synthetic data part!
", "votes": 1, "replies": [] }, { "id": 3146761, "author_name": "Davut Polat", "author_url": "", "post_date": "2025-03-11T08:11:50.757000", "content": "gc.collect()
", "votes": 0, "replies": [] }, { "id": 3147292, "author_name": "salyer_0", "author_url": "", "post_date": "2025-03-11T21:52:26.640000", "content": "Very good idea
", "votes": 0, "replies": [] }, { "id": 3145545, "author_name": "coderyuto", "author_url": "", "post_date": "2025-03-10T00:51:11.623000", "content": "great sol
", "votes": 0, "replies": [] }, { "id": 3143817, "author_name": "Thiraput01", "author_url": "", "post_date": "2025-03-07T16:28:45.750000", "content": "Congratulations, Very insightful solution!
", "votes": 0, "replies": [] }, { "id": 3143587, "author_name": "Samith Chimminiyan", "author_url": "", "post_date": "2025-03-07T11:13:40.843000", "content": "Congrats!!! Good Job!!
", "votes": 0, "replies": [] }, { "id": 3143358, "author_name": "Davide Stenner", "author_url": "", "post_date": "2025-03-07T06:39:18.787000", "content": "Congratulation!!
\n@aerdem4 how was the cv score of the real mlp compared to gbm?
\ni read the paper when it come out and im curious
Thanks! RealMLP OOF score was 0.694 (7 folds), which was actually better than the GBM models in my trials. We were surprised when we saw the score 😄
", "votes": 1, "replies": [] } ] }, { "id": 3142288, "author_name": "Vasilis", "author_url": "", "post_date": "2025-03-06T09:18:09.920000", "content": "Congratulations, amazing work!
", "votes": 0, "replies": [] }, { "id": 3142080, "author_name": "malaxg", "author_url": "", "post_date": "2025-03-06T04:40:52.220000", "content": "Congrats, great work!
", "votes": 0, "replies": [] }, { "id": 3142065, "author_name": "pencil red", "author_url": "", "post_date": "2025-03-06T04:21:33.387000", "content": "Congratulations! Great solution!
", "votes": 0, "replies": [] }, { "id": 3141934, "author_name": "dexterxin", "author_url": "", "post_date": "2025-03-06T01:44:55.013000", "content": "Congratulations! The idea of getting inspiration from paper is fantastic!🎊
\nMy solution is also a two-stage model: “efs” classification and “y” regression, but it's a lot rougher than yours. The “y” is fitted by LogNormalFitter. Regression model is trained for efs=0 and efs=1 respectively.
\nIn the beginning I used this:
\nR = p(efs=0) * model_0.predict + p(efs=1) * model_1.predict
\nThen I realized that \"model_0.predict\" was all zeros and the model didn't learn anything。
\nSo I use this directly:
\nR = p(efs=1) * model_1.predict
I have a question:
\nCongrats, Good Work @aerdem4
", "votes": 0, "replies": [] }, { "id": 3141893, "author_name": "Robert Hatch", "author_url": "", "post_date": "2025-03-06T01:12:40.150000", "content": "Congrats, great work!
", "votes": 0, "replies": [] }, { "id": 3141882, "author_name": "kk.sky.9k", "author_url": "", "post_date": "2025-03-06T01:03:36.467000", "content": "Great solution, congratulations!
", "votes": 0, "replies": [] }, { "id": 3141877, "author_name": "Bill Fan", "author_url": "", "post_date": "2025-03-06T00:58:31.593000", "content": "Congratulations to you and the team. Impressive work! would you like to share you code
", "votes": 0, "replies": [] }, { "id": 3141861, "author_name": "emararayan", "author_url": "", "post_date": "2025-03-06T00:43:37.267000", "content": "Patiently waiting for this !
", "votes": 0, "replies": [] }, { "id": 3141850, "author_name": "Adam Logman", "author_url": "", "post_date": "2025-03-06T00:33:14.103000", "content": "Congratulations, I followed different path which was risky , but now in the medal zone not bad
", "votes": 0, "replies": [] }, { "id": 3141831, "author_name": "jiahaopengX", "author_url": "", "post_date": "2025-03-06T00:17:14.760000", "content": "Good job!Congratulations!
", "votes": 0, "replies": [] }, { "id": 3141814, "author_name": "John Payne", "author_url": "", "post_date": "2025-03-06T00:09:12.350000", "content": "Congratulations! I had a very similar approach, but unfortunately didn't have much time to work on this competition, cool to see that it worked out for you!
", "votes": 0, "replies": [ { "id": 3141825, "author_name": "minerppdy", "author_url": "", "post_date": "2025-03-06T00:13:23.377000", "content": "@johnpayne0 yeah ,i saw your comments, with more complicated combine function, you will be surprised
", "votes": 1, "replies": [] } ] }, { "id": 3147268, "author_name": "", "author_url": "", "post_date": "2025-03-11T20:56:30.880000", "content": "", "votes": 0, "replies": [] }, { "id": 3147267, "author_name": "", "author_url": "", "post_date": "2025-03-11T20:54:57.597000", "content": "", "votes": 0, "replies": [] }, { "id": 3143255, "author_name": "Jaydev", "author_url": "", "post_date": "2025-03-07T03:52:15.840000", "content": "Congratulations 🥳
", "votes": 0, "replies": [] }, { "id": 3141823, "author_name": "", "author_url": "", "post_date": "2025-03-06T00:11:33.127000", "content": "", "votes": 0, "replies": [] } ], "comment_count": 39, "messages": [ { "id": 3141804, "postDate": "2025-03-06T00:02:29.633Z", "content": "First of all, I want to thank my teammates for this fun ride.
\n
Since we knew that the data is synthetic and how it was produced, we had a look at the SurvivalGAN paper. As you can see in this image, TimeRegressor is trained together with features and class information. Therefore we split the problem into two:
\nFor the regression part, we have trained and ensembled 2 models providing efs as an extra feature. Then for the test and validation sets, we make inference by setting efs=1. With this trick, we estimate how long efs time can be if there is efs. Our models are xgboost and histgbm.
\nFor classification, we use RealMLP, HistGBM and Catboost models with no feature engineering. We ensemble these models by the weights tuned on CV. We then combine it with regression predictions to calculate the risk scores:
\nR = p(efs=1) * p(efs_time | efs=1)
\np(efs_time | efs=1) is sigmoid(-regression_prediction) in our case.
Additionally, we train a neural network which approximates the competition metric and directly predicts the risk scores. It uses regression prediction from tree models and optimizes the approximate competition metric and auxiliary binary classification loss.
\n ():\n y_risk, y_time, y_efs = y_risk.ravel(), y_time.ravel(), y_efs.ravel()\n\n loss = []\n i ((y_risk)):\n y_efs[i] == :\n filt = y_time[i] < y_time\n s = (y_risk - y_risk[i]).tanh()\n loss.append(s[filt])\n\n loss = torch.cat(loss).mean()\n loss\nWe rank ensemble it with our main pipeline.
\nHere is our inference notebook: https://www.kaggle.com/code/karakasatarik/2nd-place-solution-inference
\nOnce the problem is split into two like we did, it was possible to get a gold medal even with automated machine learning.
\nHere are our experiments using AutoGluon:
\n| AutoGluon Setting | \nOOF Score | \nPublic LB | \nPrivate LB | \n
|---|---|---|---|
| Medium Quality | \n0.6884 | \n0.694 | \n0.697 | \n
| High Quality | \n0.6910 | \n0.694 | \n0.698 | \n
| Best Quality | \n0.6921 | \n0.695 | \n0.699 | \n
Anil attempted to improve the efs-classifier model's outputs by tuning a custom sigmoid function on the OOF predictions:
\ncalibrated_proba = 1 / (1 + np.exp(-beta * (raw_proba - gamma)))
This calibration led to a ~0.002 improvement in OOF but resulted in a 0.001 decrease on the public LB and a 0.001 improvement on the private LB.
", "rawMarkdown": "First of all, I want to thank my teammates for this fun ride.\n\n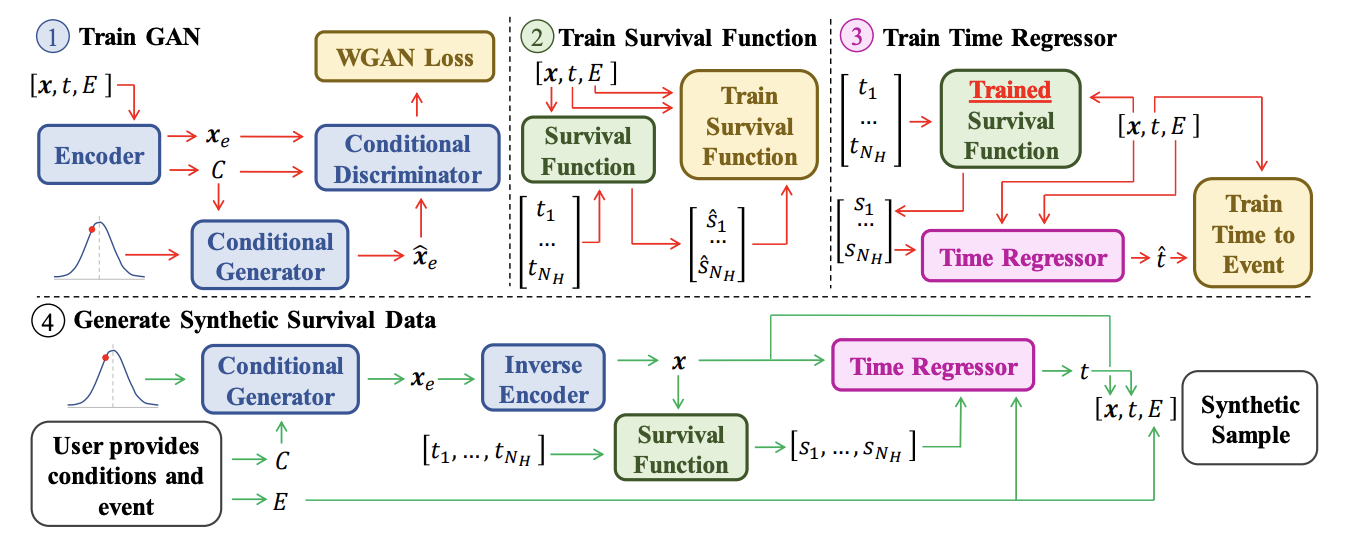\n\nSince we knew that the data is synthetic and how it was produced, we had a look at the SurvivalGAN paper. As you can see in this image, TimeRegressor is trained together with features and class information. Therefore we split the problem into two:\n* efs classification\n* efs_time regression\n\nFor the regression part, we have trained and ensembled 2 models providing efs as an extra feature. Then for the test and validation sets, we make inference by setting efs=1. With this trick, we estimate how long efs time can be if there is efs. Our models are xgboost and histgbm.\n\n\nFor classification, we use RealMLP, HistGBM and Catboost models with no feature engineering. We ensemble these models by the weights tuned on CV. We then combine it with regression predictions to calculate the risk scores:\nR = p(efs=1) * p(efs_time | efs=1)\np(efs_time | efs=1) is sigmoid(-regression_prediction) in our case.\n\nAdditionally, we train a neural network which approximates the competition metric and directly predicts the risk scores. It uses regression prediction from tree models and optimizes the approximate competition metric and auxiliary binary classification loss. \n\n```python\ndef loss_func(y_risk, y_time, y_efs):\n y_risk, y_time, y_efs = y_risk.ravel(), y_time.ravel(), y_efs.ravel()\n \n loss = []\n for i in range(len(y_risk)):\n if y_efs[i] == 1:\n filt = y_time[i] < y_time\n s = (y_risk - y_risk[i]).tanh()\n loss.append(s[filt])\n \n loss = torch.cat(loss).mean()\n return loss\n```\n\nWe rank ensemble it with our main pipeline.\n\n**Here is our inference notebook:** https://www.kaggle.com/code/karakasatarik/2nd-place-solution-inference\n\n# Appendix\n\n## AutoGluon\nOnce the problem is split into two like we did, it was possible to get a gold medal even with automated machine learning.\n\nHere are our experiments using AutoGluon:\n\n| AutoGluon Setting | OOF Score | Public LB | Private LB |\n|--------------------|---------|----------|-----------|\n| Medium Quality | 0.6884 | 0.694 | 0.697 |\n| High Quality | 0.6910 | 0.694 | 0.698 |\n| Best Quality | 0.6921 | 0.695 | 0.699 |\n\n## Postprocess\nAnil attempted to improve the efs-classifier model's outputs by tuning a custom sigmoid function on the OOF predictions:\n\n`calibrated_proba = 1 / (1 + np.exp(-beta * (raw_proba - gamma)))`\n\nThis calibration led to a ~0.002 improvement in OOF but resulted in a 0.001 decrease on the public LB and a 0.001 improvement on the private LB.\n", "votes": 115 }, { "id": 3141837, "postDate": "2025-03-06T00:19:10.330Z", "content": "similar approach, tried to solve ranking and classification tasks independently in extreme cases then combine using magic formula p(efs=1) * p(efs_time | efs=1) 😄
Congratulations!🎊
\nThis is my first time using a ranking model. I have tried to use ranking models xgb, cab, lgbm, but all failed for various reasons. Among them lgbm reported error: \"LightGBMError: Number of rows 25920 exceeds upper limit of 10000 for a query.\"
\nMay I ask you what ranking model you are using? Is this type of modeling time consuming?
", "rawMarkdown": "Congratulations!🎊\n\nThis is my first time using a ranking model. I have tried to use ranking models xgb, cab, lgbm, but all failed for various reasons. Among them lgbm reported error: \"LightGBMError: Number of rows 25920 exceeds upper limit of 10000 for a query.\"\n\nMay I ask you what ranking model you are using? Is this type of modeling time consuming?" } ] }, { "id": 3141820, "postDate": "2025-03-06T00:10:53.230Z", "content": "haha,quite similar solution with you!
", "rawMarkdown": "haha,quite similar solution with you!", "votes": 8, "replies": [ { "id": 3141841, "postDate": "2025-03-06T00:22:17.613Z", "content": "I will join the club as well :D
", "rawMarkdown": "I will join the club as well :D", "votes": 4 }, { "id": 3141948, "postDate": "2025-03-06T01:53:42.907Z", "content": "Might be everyone in top5, lol. Seems like a critical trick, even for the one of us without as good a public LB score, haha.
", "rawMarkdown": "Might be everyone in top5, lol. Seems like a critical trick, even for the one of us without as good a public LB score, haha.", "votes": 1 }, { "id": 3142055, "postDate": "2025-03-06T04:07:11.843Z", "content": "Looks like this was the magic. I was working on survival analysis 4 years ago and now I wonder if it would work on those organic datasets :D
", "rawMarkdown": "Looks like this was the magic. I was working on survival analysis 4 years ago and now I wonder if it would work on those organic datasets :D" } ] }, { "id": 3144359, "postDate": "2025-03-08T08:52:39.310Z", "content": "Awesome solution, thanks for providing this valuable insight, congratulations to your team!
", "rawMarkdown": "Awesome solution, thanks for providing this valuable insight, congratulations to your team!", "votes": 3 }, { "id": 3141846, "postDate": "2025-03-06T00:28:36.603Z", "content": "Congratulations to you and the team. Impressive work!
", "rawMarkdown": "Congratulations to you and the team. Impressive work!", "votes": 3, "replies": [ { "id": 3141858, "postDate": "2025-03-06T00:40:30.993Z", "rawMarkdown": "", "isDeleted": true } ] }, { "id": 3143624, "postDate": "2025-03-07T12:11:14.870Z", "content": "Awesome solution, thanks for providing this valuable insight, congratulations to your team!
", "rawMarkdown": "Awesome solution, thanks for providing this valuable insight, congratulations to your team!", "votes": 1 }, { "id": 3141974, "postDate": "2025-03-06T02:26:23.573Z", "content": "When I heard your teammate mention that you got a CV of 0.7 using synthetic data, I was quite worried for you. But as it turns out, you did exceptionally well with very meticulous thinking. My best wishes to you all.
", "rawMarkdown": "When I heard your teammate mention that you got a CV of 0.7 using synthetic data, I was quite worried for you. But as it turns out, you did exceptionally well with very meticulous thinking. My best wishes to you all.", "votes": 1, "replies": [ { "id": 3142258, "postDate": "2025-03-06T08:38:00.720Z", "content": "I remember that I said \"the winners team cv score would probably be around 0.7\" and you inferred rest of it lol. I also don't remember mentioning anything about using synthetic data. I'm sorry if I mislead you.
", "rawMarkdown": "I remember that I said \"the winners team cv score would probably be around 0.7\" and you inferred rest of it lol. I also don't remember mentioning anything about using synthetic data. I'm sorry if I mislead you.", "replies": [ { "id": 3142269, "postDate": "2025-03-06T08:52:16.033Z", "content": "You've done a fantastic job, congratulations!
", "rawMarkdown": "You've done a fantastic job, congratulations!" } ] } ] }, { "id": 3141859, "postDate": "2025-03-06T00:41:12.913Z", "content": "Good job!Congratulations!
", "rawMarkdown": "Good job!Congratulations!", "votes": 1 }, { "id": 3141818, "postDate": "2025-03-06T00:10:30.873Z", "content": "Elegant solution! Great work, seems I should have given more attention to the synthetic data part!
", "rawMarkdown": "Elegant solution! Great work, seems I should have given more attention to the synthetic data part! ", "votes": 1 }, { "id": 3146761, "postDate": "2025-03-11T08:11:50.757Z", "content": "gc.collect()
", "rawMarkdown": "gc.collect()" }, { "id": 3147292, "postDate": "2025-03-11T21:52:26.640Z", "content": "Very good idea
", "rawMarkdown": "Very good idea" }, { "id": 3145545, "postDate": "2025-03-10T00:51:11.623Z", "content": "great sol
", "rawMarkdown": "great sol\n" }, { "id": 3143817, "postDate": "2025-03-07T16:28:45.750Z", "content": "Congratulations, Very insightful solution!
", "rawMarkdown": "Congratulations, Very insightful solution!" }, { "id": 3143587, "postDate": "2025-03-07T11:13:40.843Z", "content": "Congrats!!! Good Job!!
", "rawMarkdown": "Congrats!!! Good Job!!" }, { "id": 3143358, "postDate": "2025-03-07T06:39:18.787Z", "content": "Congratulation!!
\n@aerdem4 how was the cv score of the real mlp compared to gbm?
\ni read the paper when it come out and im curious
Thanks! RealMLP OOF score was 0.694 (7 folds), which was actually better than the GBM models in my trials. We were surprised when we saw the score 😄
", "rawMarkdown": "Thanks! RealMLP OOF score was 0.694 (7 folds), which was actually better than the GBM models in my trials. We were surprised when we saw the score 😄", "votes": 1 } ] }, { "id": 3142288, "postDate": "2025-03-06T09:18:09.920Z", "content": "Congratulations, amazing work!
", "rawMarkdown": "Congratulations, amazing work!" }, { "id": 3142080, "postDate": "2025-03-06T04:40:52.220Z", "content": "Congrats, great work!
", "rawMarkdown": "Congrats, great work!" }, { "id": 3142065, "postDate": "2025-03-06T04:21:33.387Z", "content": "Congratulations! Great solution!
", "rawMarkdown": "Congratulations! Great solution! " }, { "id": 3141934, "postDate": "2025-03-06T01:44:55.013Z", "content": "Congratulations! The idea of getting inspiration from paper is fantastic!🎊
\nMy solution is also a two-stage model: “efs” classification and “y” regression, but it's a lot rougher than yours. The “y” is fitted by LogNormalFitter. Regression model is trained for efs=0 and efs=1 respectively.
\nIn the beginning I used this:
\nR = p(efs=0) * model_0.predict + p(efs=1) * model_1.predict
\nThen I realized that \"model_0.predict\" was all zeros and the model didn't learn anything。
\nSo I use this directly:
\nR = p(efs=1) * model_1.predict
I have a question:
\nCongrats, Good Work @aerdem4
", "rawMarkdown": "Congrats, Good Work @aerdem4 " }, { "id": 3141893, "postDate": "2025-03-06T01:12:40.150Z", "content": "Congrats, great work!
", "rawMarkdown": "Congrats, great work!" }, { "id": 3141882, "postDate": "2025-03-06T01:03:36.467Z", "content": "Great solution, congratulations!
", "rawMarkdown": "Great solution, congratulations!" }, { "id": 3141877, "postDate": "2025-03-06T00:58:31.593Z", "content": "Congratulations to you and the team. Impressive work! would you like to share you code
", "rawMarkdown": "Congratulations to you and the team. Impressive work! would you like to share you code" }, { "id": 3141861, "postDate": "2025-03-06T00:43:37.267Z", "content": "Patiently waiting for this !
", "rawMarkdown": "Patiently waiting for this ! " }, { "id": 3141850, "postDate": "2025-03-06T00:33:14.103Z", "content": "Congratulations, I followed different path which was risky , but now in the medal zone not bad
", "rawMarkdown": "Congratulations, I followed different path which was risky , but now in the medal zone not bad " }, { "id": 3141831, "postDate": "2025-03-06T00:17:14.760Z", "content": "Good job!Congratulations!
", "rawMarkdown": "Good job!Congratulations!" }, { "id": 3141814, "postDate": "2025-03-06T00:09:12.350Z", "content": "Congratulations! I had a very similar approach, but unfortunately didn't have much time to work on this competition, cool to see that it worked out for you!
", "rawMarkdown": "Congratulations! I had a very similar approach, but unfortunately didn't have much time to work on this competition, cool to see that it worked out for you!", "replies": [ { "id": 3141825, "postDate": "2025-03-06T00:13:23.377Z", "content": "@johnpayne0 yeah ,i saw your comments, with more complicated combine function, you will be surprised
", "rawMarkdown": "@johnpayne0 yeah ,i saw your comments, with more complicated combine function, you will be surprised", "votes": 1 } ] }, { "id": 3147268, "postDate": "2025-03-11T20:56:30.880Z", "rawMarkdown": "", "isDeleted": true }, { "id": 3147267, "postDate": "2025-03-11T20:54:57.597Z", "rawMarkdown": "", "isDeleted": true }, { "id": 3143255, "postDate": "2025-03-07T03:52:15.840Z", "content": "Congratulations 🥳
", "rawMarkdown": "Congratulations 🥳" }, { "id": 3141823, "postDate": "2025-03-06T00:11:33.127Z", "content": "Good! Thanks in advance!
", "rawMarkdown": "Good! Thanks in advance!" } ], "complete": true, "source": "live", "fetched_at": "2026-10-19T19:44:38Z", "competition_id": 70942, "competition_slug": "equity-post-HCT-survival-predictions", "team_id": 13173983, "solution_url": "/competitions/equity-post-HCT-survival-predictions/writeups/agalar-2nd-place-solution" }