
First of all, I would like to thank kaggle and the hosting staff for hosting such an interesting competition. And I would like to say congrats to all winner. I could not get the solo-gold, but I learned a lot from this competition.
\nMy solution is weight average ensemble with 21 models Nealder-mead with pseudo labeling. This is almost the same as other solutions. My originality is the replacement \\n to [Chapter]. This improved the cv 0.0015. And in this discussion, I show the my CV and Private LB relationship in detail.
\n

※ pseudo1 and 2 are explained on next chapter
\n ※ The order is the order with the best private lb score
| EXP | \nmodel | \npseudo1 | \npseudo2 | \npseudo dataset | \nkfold | \ncv | \nprivate lb | \npublic lb | \n
|---|---|---|---|---|---|---|---|---|
| 214 | \ndeberta v3 large | \n〇 | \n- | \nFB1 only | \n4 | \n0.4467 | \n0.4378 | \n0.4404 | \n
| 123 | \ndeberta v3 large | \n〇 | \n- | \nFB1 + Commonlit | \n4 | \n0.4467 | \n0.4379 | \n0.4402 | \n
| 200 | \ndeberta v3 large | \n- | \n〇 | \nFB1 only | \n4 | \n0.4471 | \n0.4381 | \n0.4396 | \n
| 250 | \ndeberta v3 large | \n- | \n- | \n- | \n15 | \n0.4470 | \n0.4382 | \n0.4410 | \n
| 161 | \ndeberta v3 large | \n- | \n〇 | \nFB1 + Commonlit | \n4 | \n0.4472 | \n0.4383 | \n0.4401 | \n
| 102 | \ndeberta base | \n〇 | \n- | \nFB1 + Commonlit | \n4 | \n0.4483 | \n0.4387 | \n0.4386 | \n
| 201 | \ndeberta base | \n- | \n〇 | \nFB1 only | \n4 | \n0.4503 | \n0.4390 | \n0.4399 | \n
| 163 | \ndeberta base | \n- | \n〇 | \nFB1 + Commonlit | \n4 | \n0.4505 | \n0.4390 | \n0.4403 | \n
| 215 | \ndeberta base | \n〇 | \n- | \nFB1 only | \n4 | \n0.4486 | \n0.4391 | \n0.4389 | \n
| 190 | \ndeberta base | \n- | \n- | \n- | \n10 | \n0.4508 | \n0.4393 | \n0.4393 | \n
| 777 | \ndeberta v3 large | \n- | \n- | \n- | \n10 | \n0.4479 | \n0.4398 | \n0.4413 | \n
| 1 | \ndeberta v3 large | \n- | \n- | \n- | \n4 | \n0.4486 | \n0.4400 | \n0.4421 | \n
| 170 | \ndeberta base | \n- | \n- | \n- | \n4 | \n0.4517 | \n0.4402 | \n0.4401 | \n
| 20 | \ndeberta v3 large | \n- | \n- | \n- | \n15 | \n0.4485 | \n0.4403 | \n0.4413 | \n
| 18 | \ndeberta base | \n- | \n- | \n- | \n4 | \n0.4516 | \n0.4405 | \n0.4393 | \n
| 131 | \ndeberta v1 large | \n- | \n- | \n- | \n4 | \n0.4515 | \n0.4413 | \n0.4431 | \n
| 164 | \nelectra-large | \n- | \n〇 | \nFB1 + Commonlit | \n4 | \n0.4544 | \n0.4415 | \n0.4455 | \n
| 216 | \nelectra-large | \n〇 | \n- | \nFB1 only | \n4 | \n0.4507 | \n0.4416 | \n0.4454 | \n
| 202 | \nelectra-large | \n- | \n〇 | \nFB1 only | \n4 | \n0.4550 | \n0.4418 | \n0.4457 | \n
| 114 | \nelectra-large | \n〇 | \n- | \nFB1 + Commonlit | \n4 | \n0.4516 | \n0.4419 | \n0.4458 | \n
| 17 | \ndeberta v3 large | \n- | \n- | \n- | \n4 | \n0.4502 | \n0.4419 | \n0.4430 | \n
| 30 | \ndeberta v1 xlarge | \n- | \n- | \n- | \n4 | \n0.4522 | \n0.4420 | \n0.4423 | \n
| 33 | \ndeberta v2 xlarge | \n- | \n- | \n- | \n4 | \n0.4540 | \n0.4425 | \n0.4432 | \n
| 29 | \nelectra-large | \n- | \n- | \n- | \n4 | \n0.4546 | \n0.4432 | \n0.4494 | \n
At first, I converted the sentence to lower. But this was no good. In this competition, we need to predict the grammer etc… So Upper word may be important.
\nAs shown in other solution, target name concatenated with space separators and added by [SEP] (cv 0.0005 improvement). After that, I replaced further line breaks with [Chapter] (cv 0.0015 improvement). Here is a concrete example.
\nCohesion Syntax Vocabulary Phraseology Grammar Conventions [SEP] I think that students would benefit from learning at home,because they wont have to change and get up early in the morning to shower and do there hair. taking only classes helps them because at there house they'll be pay more attention. they will be comfortable at home. [Chapter] The hardest part of school is getting ready. you wake up go brush your teeth and go to your closet and look at your cloths. …\nI used nealder-mead ensebmle in each target. This could jump the public lb from 600th to about 130 th at that time by changing from the mean ensemble.
\nAt first, about the leakage of pseudo labeling, I have experienced in NBME competition. So I could avoid the leakage. my solution on NBME
\nAs shown in other discussions, at first, I trained the 5 models using the train.csv and inferred the the feedback 1 ( and commonlit) dataset in each. By ensembling it, the pseudo label data was made. At second, I pretrained the pseudo label data. At last, I re-trained the train.csv from the pretrained models. For example, this could make the cv 0.447060 of deberta v3 large model.
\nThis is the simple pseudo labeling. I added the pseudo labeled data (as explained pseudo labeling 1) to the train.csv, and training it. I could make the cv 0.446743 of deberta v3 large model.
\nWe were allowed to use Commonlit data reference. The ensemble improved the cv a little, but only slightly.
\nChanging the seed and ensemble improved the cv a bit, but I think it was overfitting.
\nFor various reasons, I started 11 days before the deadline. At this point, the various public notebooks were out and I was able to incorporate them into my pipeline and improve my score. @nakama and @Mozattt deserve my deepest thanks.
\nAlso, I learned a lot from this competition, especially the Efficiency Prize Evaluation, which was very practical. In real work, it is often costly and time-consuming to prepare a GPU, and this initiative helped my work a lot. Finally, I would like to say thank you again to my host, kaggle, for organizing such a competition.
\nchumajin
", "comments": [ { "id": 2059035, "author_name": "DJ_Xia", "author_url": "", "post_date": "2022-12-08T12:14:22.777000", "content": "Great writeup.congrats to your strong silver,can you explain why replacement \\n to [Chapter]?
", "votes": 1, "replies": [ { "id": 2059054, "author_name": "chumajin", "author_url": "", "post_date": "2022-12-08T12:42:13.147000", "content": "@tonymarkchris Thank you for comment ! In this competition, one of the target is grammar. So I looked for ways to clarify things like paragraph breaks. As a result, I arrived at the word [Chapter]. The 8th team seems to have improved their score by replacing it with [PARAGRAPH] link here
", "votes": 0, "replies": [] } ] }, { "id": 2058283, "author_name": "Marília Prata", "author_url": "", "post_date": "2022-12-07T19:10:55.943000", "content": "You did great, as always. Congrats for your position and thank you for sharing this embracing solution Chumajin san.
", "votes": 1, "replies": [ { "id": 2058436, "author_name": "chumajin", "author_url": "", "post_date": "2022-12-08T00:17:02.357000", "content": "@mpwolke Hi, my friend. Always thank you for comment. It always motivates me👍
", "votes": 1, "replies": [] } ] }, { "id": 2058126, "author_name": "Julien Mouchnino", "author_url": "", "post_date": "2022-12-07T16:22:10.190000", "content": "What is a Feedback dataset ?
", "votes": 1, "replies": [ { "id": 2058437, "author_name": "chumajin", "author_url": "", "post_date": "2022-12-08T00:18:52.627000", "content": "@julienmouchnino This one (past feedback competition data).
\nhttps://www.kaggle.com/competitions/feedback-prize-english-language-learning/data
", "votes": 1, "replies": [] } ] }, { "id": 2057841, "author_name": "Olqa_842", "author_url": "", "post_date": "2022-12-07T11:36:55.613000", "content": "Good result for your short period @chumajin
", "votes": 1, "replies": [ { "id": 2057848, "author_name": "chumajin", "author_url": "", "post_date": "2022-12-07T11:39:48.750000", "content": "@zvr842 Thank you very much !! I needed another week for gold medal… 😂
", "votes": 0, "replies": [] } ] }, { "id": 2058115, "author_name": "Julien Mouchnino", "author_url": "", "post_date": "2022-12-07T16:16:46.313000", "content": "Could you show how you fine-tuned the BERT models?
\nNobody explains this, is it assumed to be common knowledge?
", "votes": 2, "replies": [ { "id": 2058440, "author_name": "chumajin", "author_url": "", "post_date": "2022-12-08T00:20:33.370000", "content": "@julienmouchnino Yes, common knowledge.
\nYou can learn from here.
https://www.kaggle.com/code/yasufuminakama/fb3-deberta-v3-base-baseline-train
\nhttps://www.kaggle.com/code/mozattt/fgm-fb3-deberta-v3-base-train
", "votes": 0, "replies": [] }, { "id": 2058807, "author_name": "Julien Mouchnino", "author_url": "", "post_date": "2022-12-08T08:12:00.693000", "content": "The first link : there is code but not so much explanation.
\nI know the basics of fine-tuning and tranfer learning, but I would appreciate a more detailed breakdown of the process
", "votes": 0, "replies": [] }, { "id": 2059057, "author_name": "chumajin", "author_url": "", "post_date": "2022-12-08T12:46:17.147000", "content": "@julienmouchnino how about this one (my notebook on the past competition)?
\nhttps://www.kaggle.com/code/chumajin/pytorch-bert-beginner-s-room
\nIf you want to learn more, you can search by other kaggle notebooks, google or studying by a book/youtube etc… Maybe most people do it including me.
", "votes": 0, "replies": [] } ] } ], "comment_count": 12, "messages": [ { "id": 2057809, "postDate": "2022-12-07T11:08:06.913Z", "content": "First of all, I would like to thank kaggle and the hosting staff for hosting such an interesting competition. And I would like to say congrats to all winner. I could not get the solo-gold, but I learned a lot from this competition.
\nMy solution is weight average ensemble with 21 models Nealder-mead with pseudo labeling. This is almost the same as other solutions. My originality is the replacement \\n to [Chapter]. This improved the cv 0.0015. And in this discussion, I show the my CV and Private LB relationship in detail.
\n
※ pseudo1 and 2 are explained on next chapter
\n ※ The order is the order with the best private lb score
| EXP | \nmodel | \npseudo1 | \npseudo2 | \npseudo dataset | \nkfold | \ncv | \nprivate lb | \npublic lb | \n
|---|---|---|---|---|---|---|---|---|
| 214 | \ndeberta v3 large | \n〇 | \n- | \nFB1 only | \n4 | \n0.4467 | \n0.4378 | \n0.4404 | \n
| 123 | \ndeberta v3 large | \n〇 | \n- | \nFB1 + Commonlit | \n4 | \n0.4467 | \n0.4379 | \n0.4402 | \n
| 200 | \ndeberta v3 large | \n- | \n〇 | \nFB1 only | \n4 | \n0.4471 | \n0.4381 | \n0.4396 | \n
| 250 | \ndeberta v3 large | \n- | \n- | \n- | \n15 | \n0.4470 | \n0.4382 | \n0.4410 | \n
| 161 | \ndeberta v3 large | \n- | \n〇 | \nFB1 + Commonlit | \n4 | \n0.4472 | \n0.4383 | \n0.4401 | \n
| 102 | \ndeberta base | \n〇 | \n- | \nFB1 + Commonlit | \n4 | \n0.4483 | \n0.4387 | \n0.4386 | \n
| 201 | \ndeberta base | \n- | \n〇 | \nFB1 only | \n4 | \n0.4503 | \n0.4390 | \n0.4399 | \n
| 163 | \ndeberta base | \n- | \n〇 | \nFB1 + Commonlit | \n4 | \n0.4505 | \n0.4390 | \n0.4403 | \n
| 215 | \ndeberta base | \n〇 | \n- | \nFB1 only | \n4 | \n0.4486 | \n0.4391 | \n0.4389 | \n
| 190 | \ndeberta base | \n- | \n- | \n- | \n10 | \n0.4508 | \n0.4393 | \n0.4393 | \n
| 777 | \ndeberta v3 large | \n- | \n- | \n- | \n10 | \n0.4479 | \n0.4398 | \n0.4413 | \n
| 1 | \ndeberta v3 large | \n- | \n- | \n- | \n4 | \n0.4486 | \n0.4400 | \n0.4421 | \n
| 170 | \ndeberta base | \n- | \n- | \n- | \n4 | \n0.4517 | \n0.4402 | \n0.4401 | \n
| 20 | \ndeberta v3 large | \n- | \n- | \n- | \n15 | \n0.4485 | \n0.4403 | \n0.4413 | \n
| 18 | \ndeberta base | \n- | \n- | \n- | \n4 | \n0.4516 | \n0.4405 | \n0.4393 | \n
| 131 | \ndeberta v1 large | \n- | \n- | \n- | \n4 | \n0.4515 | \n0.4413 | \n0.4431 | \n
| 164 | \nelectra-large | \n- | \n〇 | \nFB1 + Commonlit | \n4 | \n0.4544 | \n0.4415 | \n0.4455 | \n
| 216 | \nelectra-large | \n〇 | \n- | \nFB1 only | \n4 | \n0.4507 | \n0.4416 | \n0.4454 | \n
| 202 | \nelectra-large | \n- | \n〇 | \nFB1 only | \n4 | \n0.4550 | \n0.4418 | \n0.4457 | \n
| 114 | \nelectra-large | \n〇 | \n- | \nFB1 + Commonlit | \n4 | \n0.4516 | \n0.4419 | \n0.4458 | \n
| 17 | \ndeberta v3 large | \n- | \n- | \n- | \n4 | \n0.4502 | \n0.4419 | \n0.4430 | \n
| 30 | \ndeberta v1 xlarge | \n- | \n- | \n- | \n4 | \n0.4522 | \n0.4420 | \n0.4423 | \n
| 33 | \ndeberta v2 xlarge | \n- | \n- | \n- | \n4 | \n0.4540 | \n0.4425 | \n0.4432 | \n
| 29 | \nelectra-large | \n- | \n- | \n- | \n4 | \n0.4546 | \n0.4432 | \n0.4494 | \n
At first, I converted the sentence to lower. But this was no good. In this competition, we need to predict the grammer etc… So Upper word may be important.
\nAs shown in other solution, target name concatenated with space separators and added by [SEP] (cv 0.0005 improvement). After that, I replaced further line breaks with [Chapter] (cv 0.0015 improvement). Here is a concrete example.
\nCohesion Syntax Vocabulary Phraseology Grammar Conventions [SEP] I think that students would benefit from learning at home,because they wont have to change and get up early in the morning to shower and do there hair. taking only classes helps them because at there house they'll be pay more attention. they will be comfortable at home. [Chapter] The hardest part of school is getting ready. you wake up go brush your teeth and go to your closet and look at your cloths. …\nI used nealder-mead ensebmle in each target. This could jump the public lb from 600th to about 130 th at that time by changing from the mean ensemble.
\nAt first, about the leakage of pseudo labeling, I have experienced in NBME competition. So I could avoid the leakage. my solution on NBME
\nAs shown in other discussions, at first, I trained the 5 models using the train.csv and inferred the the feedback 1 ( and commonlit) dataset in each. By ensembling it, the pseudo label data was made. At second, I pretrained the pseudo label data. At last, I re-trained the train.csv from the pretrained models. For example, this could make the cv 0.447060 of deberta v3 large model.
\nThis is the simple pseudo labeling. I added the pseudo labeled data (as explained pseudo labeling 1) to the train.csv, and training it. I could make the cv 0.446743 of deberta v3 large model.
\nWe were allowed to use Commonlit data reference. The ensemble improved the cv a little, but only slightly.
\nChanging the seed and ensemble improved the cv a bit, but I think it was overfitting.
\nFor various reasons, I started 11 days before the deadline. At this point, the various public notebooks were out and I was able to incorporate them into my pipeline and improve my score. @nakama and @Mozattt deserve my deepest thanks.
\nAlso, I learned a lot from this competition, especially the Efficiency Prize Evaluation, which was very practical. In real work, it is often costly and time-consuming to prepare a GPU, and this initiative helped my work a lot. Finally, I would like to say thank you again to my host, kaggle, for organizing such a competition.
\nchumajin
", "rawMarkdown": "# 18 th place Solution\n\nFirst of all, I would like to thank kaggle and the hosting staff for hosting such an interesting competition. And I would like to say congrats to all winner. I could not get the solo-gold, but I learned a lot from this competition.\n\n# 1. Overview (Almost the same as others)\n\nMy solution is weight average ensemble with 21 models Nealder-mead with pseudo labeling. This is almost the same as other solutions. My originality is the replacement \\n to [Chapter]. This improved the cv 0.0015. And in this discussion, I show the my CV and Private LB relationship in detail.\n\n# 1.1 Configuration\n\n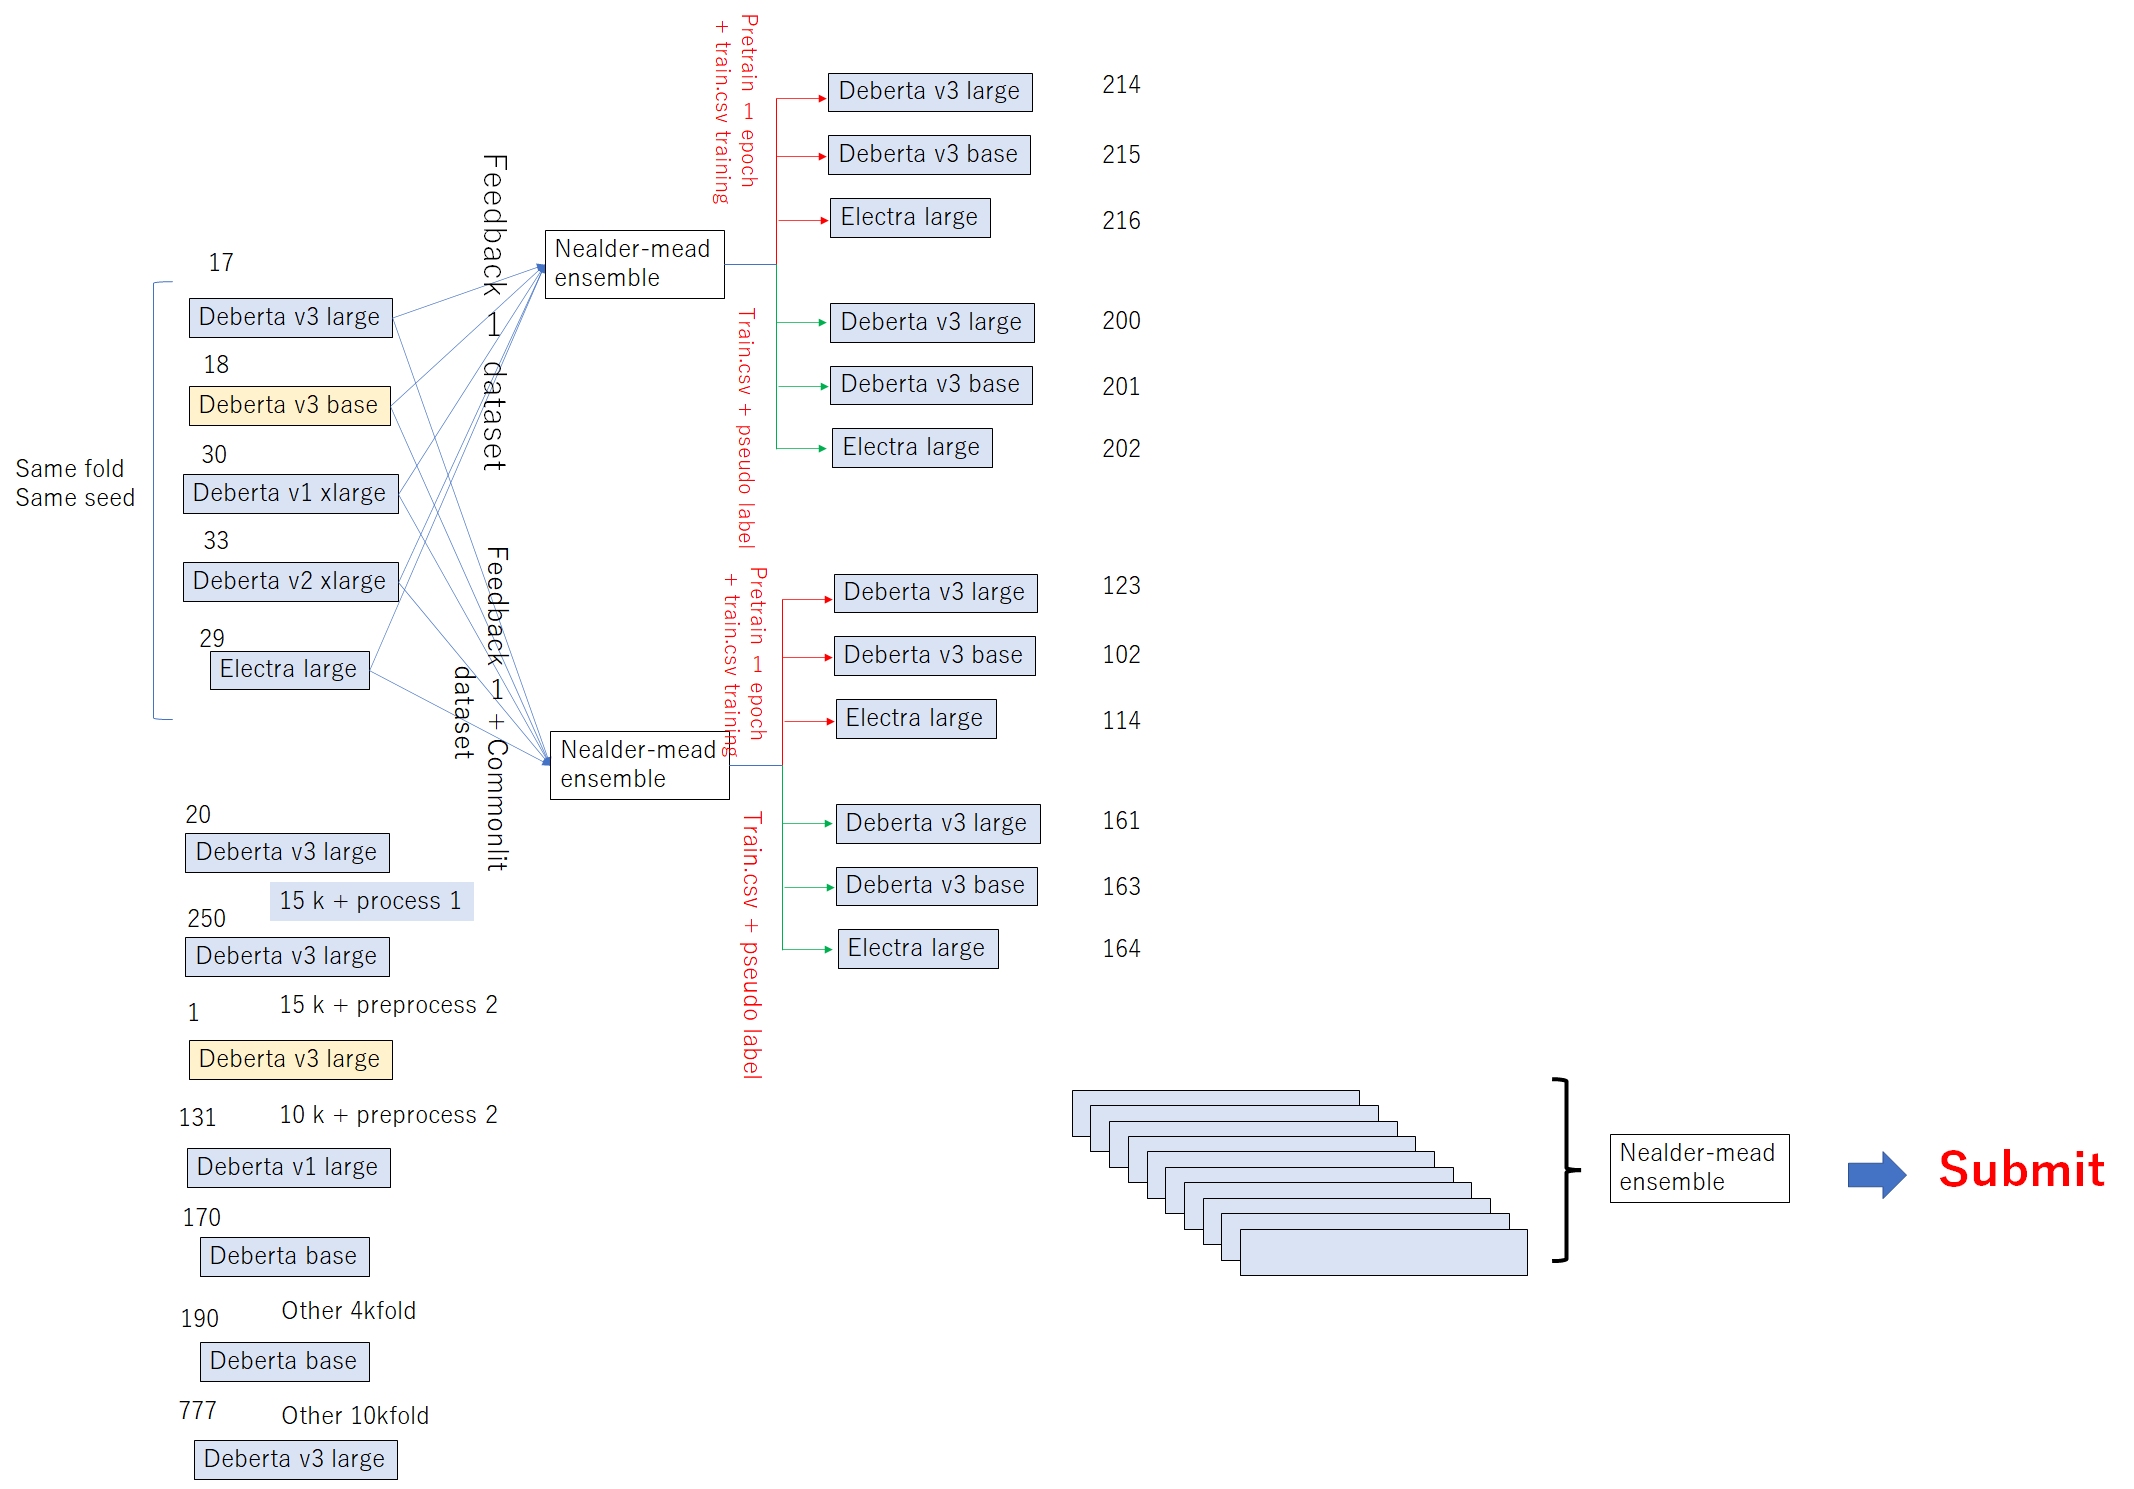\n\n\n\n# 1.2 Relationship of cv and lb \n\n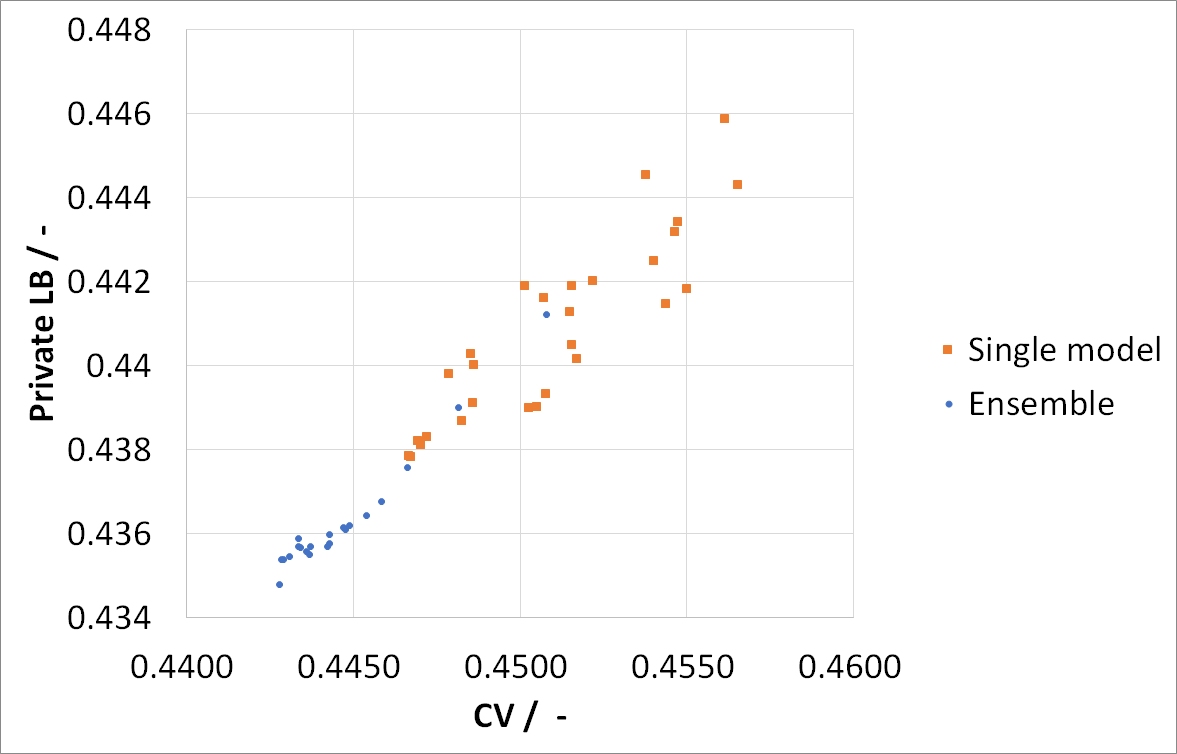\n\n\n\n\n\n\n# 1.3 cv and score in each model\n ※ pseudo1 and 2 are explained on next chapter\n ※ The order is the order with the best private lb score\n\n\n| EXP | model | pseudo1| pseudo2 | pseudoGreat writeup.congrats to your strong silver,can you explain why replacement \\n to [Chapter]?
", "rawMarkdown": "Great writeup.congrats to your strong silver,can you explain why **replacement \\n to [Chapter]**?", "votes": 1, "replies": [ { "id": 2059054, "postDate": "2022-12-08T12:42:13.147Z", "content": "@tonymarkchris Thank you for comment ! In this competition, one of the target is grammar. So I looked for ways to clarify things like paragraph breaks. As a result, I arrived at the word [Chapter]. The 8th team seems to have improved their score by replacing it with [PARAGRAPH] link here
", "rawMarkdown": "@tonymarkchris Thank you for comment ! In this competition, one of the target is grammar. So I looked for ways to clarify things like paragraph breaks. As a result, I arrived at the word [Chapter]. The 8th team seems to have improved their score by replacing it with [PARAGRAPH] [link here](https://www.kaggle.com/competitions/feedback-prize-english-language-learning/discussion/369524)" } ] }, { "id": 2058283, "postDate": "2022-12-07T19:10:55.943Z", "content": "You did great, as always. Congrats for your position and thank you for sharing this embracing solution Chumajin san.
", "rawMarkdown": "You did great, as always. Congrats for your position and thank you for sharing this embracing solution Chumajin san.", "votes": 1, "replies": [ { "id": 2058436, "postDate": "2022-12-08T00:17:02.357Z", "content": "@mpwolke Hi, my friend. Always thank you for comment. It always motivates me👍
", "rawMarkdown": "@mpwolke Hi, my friend. Always thank you for comment. It always motivates me👍", "votes": 1 } ] }, { "id": 2058126, "postDate": "2022-12-07T16:22:10.190Z", "content": "What is a Feedback dataset ?
", "rawMarkdown": "What is a Feedback dataset ?", "votes": 1, "replies": [ { "id": 2058437, "postDate": "2022-12-08T00:18:52.627Z", "content": "@julienmouchnino This one (past feedback competition data).
\nhttps://www.kaggle.com/competitions/feedback-prize-english-language-learning/data
", "rawMarkdown": "@julienmouchnino This one (past feedback competition data). \n\nhttps://www.kaggle.com/competitions/feedback-prize-english-language-learning/data", "votes": 1 } ] }, { "id": 2057841, "postDate": "2022-12-07T11:36:55.613Z", "content": "Good result for your short period @chumajin
", "rawMarkdown": "Good result for your short period @chumajin ", "votes": 1, "replies": [ { "id": 2057848, "postDate": "2022-12-07T11:39:48.750Z", "content": "@zvr842 Thank you very much !! I needed another week for gold medal… 😂
", "rawMarkdown": "@zvr842 Thank you very much !! I needed another week for gold medal... 😂" } ] }, { "id": 2058115, "postDate": "2022-12-07T16:16:46.313Z", "content": "Could you show how you fine-tuned the BERT models?
\nNobody explains this, is it assumed to be common knowledge?
", "rawMarkdown": "Could you show how you fine-tuned the BERT models?\n\nNobody explains this, is it assumed to be common knowledge?\n ", "votes": 2, "replies": [ { "id": 2058440, "postDate": "2022-12-08T00:20:33.370Z", "content": "@julienmouchnino Yes, common knowledge.
\nYou can learn from here.
https://www.kaggle.com/code/yasufuminakama/fb3-deberta-v3-base-baseline-train
\nhttps://www.kaggle.com/code/mozattt/fgm-fb3-deberta-v3-base-train
", "rawMarkdown": "@julienmouchnino Yes, common knowledge. \nYou can learn from here.\n\nhttps://www.kaggle.com/code/yasufuminakama/fb3-deberta-v3-base-baseline-train\n\nhttps://www.kaggle.com/code/mozattt/fgm-fb3-deberta-v3-base-train" }, { "id": 2058807, "postDate": "2022-12-08T08:12:00.693Z", "content": "The first link : there is code but not so much explanation.
\nI know the basics of fine-tuning and tranfer learning, but I would appreciate a more detailed breakdown of the process
", "rawMarkdown": "The first link : there is code but not so much explanation. \n\nI know the basics of fine-tuning and tranfer learning, but I would appreciate a more detailed breakdown of the process\n" }, { "id": 2059057, "postDate": "2022-12-08T12:46:17.147Z", "content": "@julienmouchnino how about this one (my notebook on the past competition)?
\nhttps://www.kaggle.com/code/chumajin/pytorch-bert-beginner-s-room
\nIf you want to learn more, you can search by other kaggle notebooks, google or studying by a book/youtube etc… Maybe most people do it including me.
", "rawMarkdown": "@julienmouchnino how about this one (my notebook on the past competition)?\n\n https://www.kaggle.com/code/chumajin/pytorch-bert-beginner-s-room\n\nIf you want to learn more, you can search by other kaggle notebooks, google or studying by a book/youtube etc... Maybe most people do it including me." } ] } ], "complete": true, "source": "live", "fetched_at": "2026-10-19T20:06:00Z", "competition_id": 38321, "competition_slug": "feedback-prize-english-language-learning", "team_id": 9255874, "solution_url": "/competitions/feedback-prize-english-language-learning/writeups/chumajin-18th-place-solution" }