
\n
 \n\n### CycleGAN architecture\n\nLooking at the code below may be hard to get what is happening, this image will help the understanding\n\n
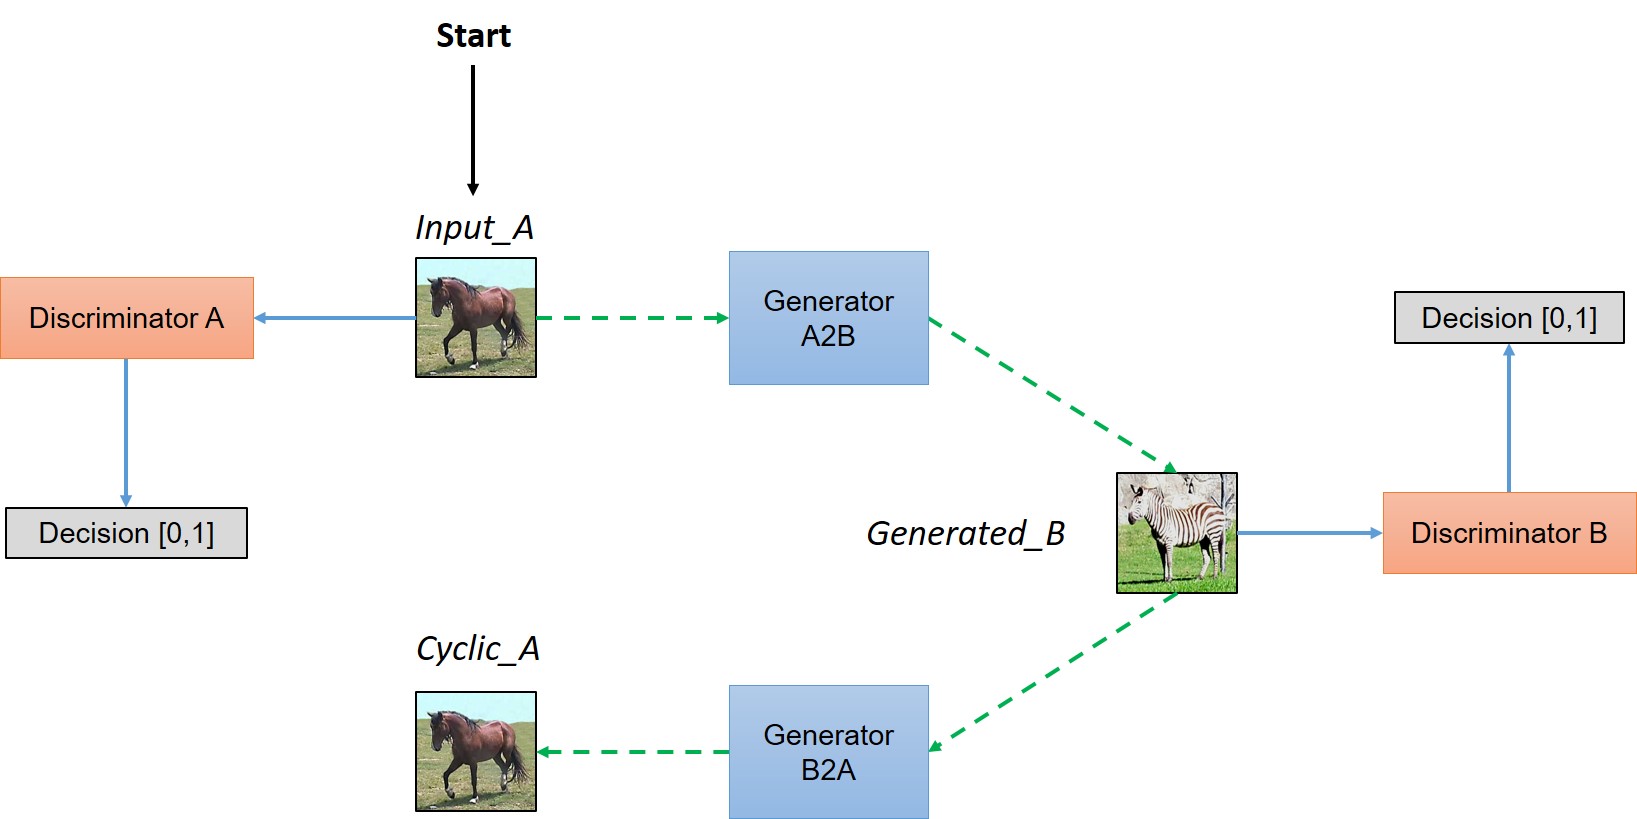 \n\nFirst, we get the regular generator discriminator thing, where the generator tries to generate images that seem to be drawn to the given domain (in the example will be creating zebra images), but it would be possible that the generator generates only the same zebra image or zebra images that do not look like the imputed horse image, this is why the model has a second generator, this second generator uses the first generated image and tries to recreate the original imputed horse image, this way the first generator has to generate zebra images that look like the imputed horse image.\n\n#### In the end, you will get 4 sub-models:\n- A generator that can generate zebras images\n- A generator that can generate horses images\n- A discriminator that can identify real zebras images\n- A discriminator that can identify real horses images\n\n\n#### Let's get to the code","metadata":{}},{"cell_type":"markdown","source":"## Dependencies","metadata":{}},{"cell_type":"code","source":"import os, random, json, PIL, shutil, re\nimport numpy as np\nimport pandas as pd\nimport seaborn as sns\nimport matplotlib.pyplot as plt\nfrom kaggle_datasets import KaggleDatasets\nimport tensorflow as tf\nimport tensorflow.keras.layers as L\nimport tensorflow_addons as tfa\nfrom tensorflow.keras import Model, losses, optimizers","metadata":{"_uuid":"d629ff2d2480ee46fbb7e2d37f6b5fab8052498a","_cell_guid":"79c7e3d0-c299-4dcb-8224-4455121ee9b0","_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-04-03T09:03:53.070235Z","iopub.execute_input":"2024-04-03T09:03:53.071323Z","iopub.status.idle":"2024-04-03T09:03:53.077752Z","shell.execute_reply.started":"2024-04-03T09:03:53.071286Z","shell.execute_reply":"2024-04-03T09:03:53.076721Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"import os, random, json, PIL, shutil, re\nimport numpy as np\nimport pandas as pd\nimport seaborn as sns\nimport matplotlib.pyplot as plt\n","metadata":{"execution":{"iopub.status.busy":"2024-04-03T09:03:53.079465Z","iopub.execute_input":"2024-04-03T09:03:53.079821Z","iopub.status.idle":"2024-04-03T09:03:53.088688Z","shell.execute_reply.started":"2024-04-03T09:03:53.079782Z","shell.execute_reply":"2024-04-03T09:03:53.087876Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"from kaggle_datasets import KaggleDatasets\nimport tensorflow as tf","metadata":{"execution":{"iopub.status.busy":"2024-04-03T09:03:53.08979Z","iopub.execute_input":"2024-04-03T09:03:53.090127Z","iopub.status.idle":"2024-04-03T09:03:53.098215Z","shell.execute_reply.started":"2024-04-03T09:03:53.0901Z","shell.execute_reply":"2024-04-03T09:03:53.097393Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"import tensorflow.keras.layers as L\nimport tensorflow_addons as tfa\nfrom tensorflow.keras import Model, losses, optimizers","metadata":{"execution":{"iopub.status.busy":"2024-04-03T09:03:53.10086Z","iopub.execute_input":"2024-04-03T09:03:53.101248Z","iopub.status.idle":"2024-04-03T09:03:53.107128Z","shell.execute_reply.started":"2024-04-03T09:03:53.101212Z","shell.execute_reply":"2024-04-03T09:03:53.106127Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## TPU configuration","metadata":{}},{"cell_type":"code","source":"try:\n tpu = tf.distribute.cluster_resolver.TPUClusterResolver()\n print(f'Running on TPU {tpu.master()}')\nexcept ValueError:\n tpu = None\n\nif tpu:\n tf.config.experimental_connect_to_cluster(tpu)\n tf.tpu.experimental.initialize_tpu_system(tpu)\n strategy = tf.distribute.experimental.TPUStrategy(tpu)\nelse:\n strategy = tf.distribute.get_strategy()\n\n\nREPLICAS = strategy.num_replicas_in_sync\nprint(f'REPLICAS: {REPLICAS}')\nAUTO = tf.data.experimental.AUTOTUNE","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-04-03T09:03:53.108271Z","iopub.execute_input":"2024-04-03T09:03:53.10863Z","iopub.status.idle":"2024-04-03T09:03:53.119706Z","shell.execute_reply.started":"2024-04-03T09:03:53.108595Z","shell.execute_reply":"2024-04-03T09:03:53.118804Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# Model parameters","metadata":{}},{"cell_type":"code","source":"HEIGHT = 256\nWIDTH = 256\nCHANNELS = 3\nEPOCHS = 50\nBATCH_SIZE = 1","metadata":{"_kg_hide-input":false,"execution":{"iopub.status.busy":"2024-04-03T09:03:53.120969Z","iopub.execute_input":"2024-04-03T09:03:53.121588Z","iopub.status.idle":"2024-04-03T09:03:53.129873Z","shell.execute_reply.started":"2024-04-03T09:03:53.121552Z","shell.execute_reply":"2024-04-03T09:03:53.128904Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# Load data","metadata":{}},{"cell_type":"code","source":"GCS_PATH = KaggleDatasets().get_gcs_path('monet-gan-getting-started')\n\nMONET_FILENAMES = tf.io.gfile.glob(str(GCS_PATH + '/monet_tfrec/*.tfrec'))\nPHOTO_FILENAMES = tf.io.gfile.glob(str(GCS_PATH + '/photo_tfrec/*.tfrec'))\n\ndef count_data_items(filenames):\n n = [int(re.compile(r\"-([0-9]*)\\.\").search(filename).group(1)) for filename in filenames]\n return np.sum(n)\n\nn_monet_samples = count_data_items(MONET_FILENAMES)\nn_photo_samples = count_data_items(PHOTO_FILENAMES)\n\nprint(f'Monet TFRecord files: {len(MONET_FILENAMES)}')\nprint(f'Monet image files: {n_monet_samples}')\nprint(f'Photo TFRecord files: {len(PHOTO_FILENAMES)}')\nprint(f'Photo image files: {n_photo_samples}')","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-04-03T09:03:53.131094Z","iopub.execute_input":"2024-04-03T09:03:53.131378Z","iopub.status.idle":"2024-04-03T09:03:54.992344Z","shell.execute_reply.started":"2024-04-03T09:03:53.131353Z","shell.execute_reply":"2024-04-03T09:03:54.991318Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Auxiliar functions","metadata":{}},{"cell_type":"code","source":"def decode_image(image):\n image = tf.image.decode_jpeg(image, channels=CHANNELS)\n image = (tf.cast(image, tf.float32) / 127.5) - 1\n image = tf.reshape(image, [HEIGHT, WIDTH, CHANNELS])\n return image\n\ndef read_tfrecord(example):\n tfrecord_format = {\n 'image_name': tf.io.FixedLenFeature([], tf.string),\n 'image': tf.io.FixedLenFeature([], tf.string),\n 'target': tf.io.FixedLenFeature([], tf.string)\n }\n example = tf.io.parse_single_example(example, tfrecord_format)\n image = decode_image(example['image'])\n return image\n\ndef load_dataset(filenames):\n dataset = tf.data.TFRecordDataset(filenames)\n dataset = dataset.map(read_tfrecord, num_parallel_calls=AUTO)\n return dataset\n\ndef get_gan_dataset(monet_files, photo_files, augment=None, repeat=True, shuffle=True, batch_size=1):\n\n monet_ds = load_dataset(monet_files)\n photo_ds = load_dataset(photo_files)\n\n if repeat:\n monet_ds = monet_ds.repeat()\n photo_ds = photo_ds.repeat()\n if shuffle:\n monet_ds = monet_ds.shuffle(2048)\n photo_ds = photo_ds.shuffle(2048)\n \n monet_ds = monet_ds.batch(batch_size, drop_remainder=True)\n photo_ds = photo_ds.batch(batch_size, drop_remainder=True)\n monet_ds = monet_ds.cache()\n photo_ds = photo_ds.cache()\n monet_ds = monet_ds.prefetch(AUTO)\n photo_ds = photo_ds.prefetch(AUTO)\n \n gan_ds = tf.data.Dataset.zip((monet_ds, photo_ds))\n \n return gan_ds\n\ndef display_samples(ds, row, col):\n ds_iter = iter(ds)\n plt.figure(figsize=(15, int(15*row/col)))\n for j in range(row*col):\n example_sample = next(ds_iter)\n plt.subplot(row,col,j+1)\n plt.axis('off')\n plt.imshow(example_sample[0] * 0.5 + 0.5)\n plt.show()\n \ndef display_generated_samples(ds, model, n_samples):\n ds_iter = iter(ds)\n for n_sample in range(n_samples):\n example_sample = next(ds_iter)\n generated_sample = model.predict(example_sample)\n \n plt.subplot(121)\n plt.title(\"input image\")\n plt.imshow(example_sample[0] * 0.5 + 0.5)\n plt.axis('off')\n \n plt.subplot(122)\n plt.title(\"Generated image\")\n plt.imshow(generated_sample[0] * 0.5 + 0.5)\n plt.axis('off')\n plt.show()\n \ndef predict_and_save(input_ds, generator_model, output_path):\n i = 1\n for img in input_ds:\n prediction = generator_model(img, training=False)[0].numpy() # make predition\n prediction = (prediction * 127.5 + 127.5).astype(np.uint8) # re-scale\n im = PIL.Image.fromarray(prediction)\n im.save(f'{output_path}{str(i)}.jpg')\n i += 1\n \n\n# Model functions\ndef downsample(filters, size, apply_instancenorm=True, strides=2):\n initializer = tf.random_normal_initializer(0., 0.02)\n gamma_init = tf.keras.initializers.RandomNormal(mean=0.0, stddev=0.02)\n\n result = tf.keras.Sequential()\n result.add(L.Conv2D(filters, size, strides=strides, padding='same',\n kernel_initializer=initializer, use_bias=False))\n\n if apply_instancenorm:\n result.add(tfa.layers.InstanceNormalization(gamma_initializer=gamma_init))\n\n result.add(L.LeakyReLU())\n\n return result\n\ndef upsample(filters, size, apply_dropout=False, strides=2):\n initializer = tf.random_normal_initializer(0., 0.02)\n gamma_init = tf.keras.initializers.RandomNormal(mean=0.0, stddev=0.02)\n\n result = tf.keras.Sequential()\n result.add(L.Conv2DTranspose(filters, size, strides=strides, padding='same',\n kernel_initializer=initializer, use_bias=False))\n\n result.add(tfa.layers.InstanceNormalization(gamma_initializer=gamma_init))\n\n if apply_dropout:\n result.add(L.Dropout(0.5))\n\n result.add(L.ReLU())\n\n return result","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-04-03T09:03:54.993886Z","iopub.execute_input":"2024-04-03T09:03:54.994231Z","iopub.status.idle":"2024-04-03T09:03:55.021227Z","shell.execute_reply.started":"2024-04-03T09:03:54.994202Z","shell.execute_reply":"2024-04-03T09:03:55.020166Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Looking at a few Monet paintings","metadata":{}},{"cell_type":"code","source":"display_samples(load_dataset(MONET_FILENAMES).batch(1), 4, 6)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-04-03T09:03:55.02236Z","iopub.execute_input":"2024-04-03T09:03:55.022709Z","iopub.status.idle":"2024-04-03T09:04:01.580621Z","shell.execute_reply.started":"2024-04-03T09:03:55.022655Z","shell.execute_reply":"2024-04-03T09:04:01.579627Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Looking at a few photo samples","metadata":{}},{"cell_type":"code","source":"display_samples(load_dataset(PHOTO_FILENAMES).batch(1), 4, 6)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-04-03T09:04:01.584711Z","iopub.execute_input":"2024-04-03T09:04:01.585417Z","iopub.status.idle":"2024-04-03T09:04:06.003138Z","shell.execute_reply.started":"2024-04-03T09:04:01.585379Z","shell.execute_reply":"2024-04-03T09:04:06.002231Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# Generator model","metadata":{}},{"cell_type":"code","source":"OUTPUT_CHANNELS = 3\n\ndef generator_fn():\n inputs = L.Input(shape=[HEIGHT, WIDTH, CHANNELS])\n\n down_stack = [\n downsample(64, 4, apply_instancenorm=False), # (bs, 128, 128, 64)\n downsample(128, 4), # (bs, 64, 64, 128)\n downsample(256, 4), # (bs, 32, 32, 256)\n downsample(512, 4), # (bs, 16, 16, 512)\n downsample(512, 4), # (bs, 8, 8, 512)\n downsample(512, 4), # (bs, 4, 4, 512)\n downsample(512, 4), # (bs, 2, 2, 512)\n downsample(512, 4), # (bs, 1, 1, 512)\n ]\n\n up_stack = [\n upsample(512, 4, apply_dropout=True), # (bs, 2, 2, 1024)\n upsample(512, 4, apply_dropout=True), # (bs, 4, 4, 1024)\n upsample(512, 4, apply_dropout=True), # (bs, 8, 8, 1024)\n upsample(512, 4), # (bs, 16, 16, 1024)\n upsample(256, 4), # (bs, 32, 32, 512)\n upsample(128, 4), # (bs, 64, 64, 256)\n upsample(64, 4), # (bs, 128, 128, 128)\n ]\n\n initializer = tf.random_normal_initializer(0., 0.02)\n last = L.Conv2DTranspose(OUTPUT_CHANNELS, 4,\n strides=2,\n padding='same',\n kernel_initializer=initializer,\n activation='tanh') # (bs, 256, 256, 3)\n\n x = inputs\n\n # Downsampling through the model\n skips = []\n for down in down_stack:\n x = down(x)\n skips.append(x)\n\n skips = reversed(skips[:-1])\n\n # Upsampling and establishing the skip connections\n for up, skip in zip(up_stack, skips):\n x = up(x)\n x = L.Concatenate()([x, skip])\n\n x = last(x)\n\n return Model(inputs=inputs, outputs=x)","metadata":{"_kg_hide-input":false,"execution":{"iopub.status.busy":"2024-04-03T09:04:06.005009Z","iopub.execute_input":"2024-04-03T09:04:06.005513Z","iopub.status.idle":"2024-04-03T09:04:06.021306Z","shell.execute_reply.started":"2024-04-03T09:04:06.005476Z","shell.execute_reply":"2024-04-03T09:04:06.020302Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# Discriminator model","metadata":{}},{"cell_type":"code","source":"def discriminator_fn():\n initializer = tf.random_normal_initializer(0., 0.02)\n gamma_init = tf.keras.initializers.RandomNormal(mean=0.0, stddev=0.02)\n\n inp = L.Input(shape=[HEIGHT, WIDTH, CHANNELS], name='input_image')\n\n x = inp\n\n down1 = downsample(64, 4, False)(x) # (bs, 128, 128, 64)\n down2 = downsample(128, 4)(down1) # (bs, 64, 64, 128)\n down3 = downsample(256, 4)(down2) # (bs, 32, 32, 256)\n\n zero_pad1 = L.ZeroPadding2D()(down3) # (bs, 34, 34, 256)\n conv = L.Conv2D(512, 4, strides=1,\n kernel_initializer=initializer,\n use_bias=False)(zero_pad1) # (bs, 31, 31, 512)\n\n norm1 = tfa.layers.InstanceNormalization(gamma_initializer=gamma_init)(conv)\n\n leaky_relu = L.LeakyReLU()(norm1)\n\n zero_pad2 = L.ZeroPadding2D()(leaky_relu) # (bs, 33, 33, 512)\n\n last = L.Conv2D(1, 4, strides=1,\n kernel_initializer=initializer)(zero_pad2) # (bs, 30, 30, 1)\n\n return Model(inputs=inp, outputs=last)","metadata":{"_kg_hide-input":false,"execution":{"iopub.status.busy":"2024-04-03T09:04:06.022413Z","iopub.execute_input":"2024-04-03T09:04:06.022669Z","iopub.status.idle":"2024-04-03T09:04:06.036006Z","shell.execute_reply.started":"2024-04-03T09:04:06.022645Z","shell.execute_reply":"2024-04-03T09:04:06.03515Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# Build model (CycleGAN)","metadata":{}},{"cell_type":"code","source":"with strategy.scope():\n monet_generator = generator_fn() # transforms photos to Monet-esque paintings\n photo_generator = generator_fn() # transforms Monet paintings to be more like photos\n\n monet_discriminator = discriminator_fn() # differentiates real Monet paintings and generated Monet paintings\n photo_discriminator = discriminator_fn() # differentiates real photos and generated photos\n\n\nclass CycleGan(Model):\n def __init__(\n self,\n monet_generator,\n photo_generator,\n monet_discriminator,\n photo_discriminator,\n lambda_cycle=10,\n ):\n super(CycleGan, self).__init__()\n self.m_gen = monet_generator\n self.p_gen = photo_generator\n self.m_disc = monet_discriminator\n self.p_disc = photo_discriminator\n self.lambda_cycle = lambda_cycle\n \n def compile(\n self,\n m_gen_optimizer,\n p_gen_optimizer,\n m_disc_optimizer,\n p_disc_optimizer,\n gen_loss_fn,\n disc_loss_fn,\n cycle_loss_fn,\n identity_loss_fn\n ):\n super(CycleGan, self).compile()\n self.m_gen_optimizer = m_gen_optimizer\n self.p_gen_optimizer = p_gen_optimizer\n self.m_disc_optimizer = m_disc_optimizer\n self.p_disc_optimizer = p_disc_optimizer\n self.gen_loss_fn = gen_loss_fn\n self.disc_loss_fn = disc_loss_fn\n self.cycle_loss_fn = cycle_loss_fn\n self.identity_loss_fn = identity_loss_fn\n \n def train_step(self, batch_data):\n real_monet, real_photo = batch_data\n \n with tf.GradientTape(persistent=True) as tape:\n # photo to monet back to photo\n fake_monet = self.m_gen(real_photo, training=True)\n cycled_photo = self.p_gen(fake_monet, training=True)\n\n # monet to photo back to monet\n fake_photo = self.p_gen(real_monet, training=True)\n cycled_monet = self.m_gen(fake_photo, training=True)\n\n # generating itself\n same_monet = self.m_gen(real_monet, training=True)\n same_photo = self.p_gen(real_photo, training=True)\n\n # discriminator used to check, inputing real images\n disc_real_monet = self.m_disc(real_monet, training=True)\n disc_real_photo = self.p_disc(real_photo, training=True)\n\n # discriminator used to check, inputing fake images\n disc_fake_monet = self.m_disc(fake_monet, training=True)\n disc_fake_photo = self.p_disc(fake_photo, training=True)\n\n # evaluates generator loss\n monet_gen_loss = self.gen_loss_fn(disc_fake_monet)\n photo_gen_loss = self.gen_loss_fn(disc_fake_photo)\n\n # evaluates total cycle consistency loss\n total_cycle_loss = self.cycle_loss_fn(real_monet, cycled_monet, self.lambda_cycle) + self.cycle_loss_fn(real_photo, cycled_photo, self.lambda_cycle)\n\n # evaluates total generator loss\n total_monet_gen_loss = monet_gen_loss + total_cycle_loss + self.identity_loss_fn(real_monet, same_monet, self.lambda_cycle)\n total_photo_gen_loss = photo_gen_loss + total_cycle_loss + self.identity_loss_fn(real_photo, same_photo, self.lambda_cycle)\n\n # evaluates discriminator loss\n monet_disc_loss = self.disc_loss_fn(disc_real_monet, disc_fake_monet)\n photo_disc_loss = self.disc_loss_fn(disc_real_photo, disc_fake_photo)\n\n # Calculate the gradients for generator and discriminator\n monet_generator_gradients = tape.gradient(total_monet_gen_loss,\n self.m_gen.trainable_variables)\n photo_generator_gradients = tape.gradient(total_photo_gen_loss,\n self.p_gen.trainable_variables)\n\n monet_discriminator_gradients = tape.gradient(monet_disc_loss,\n self.m_disc.trainable_variables)\n photo_discriminator_gradients = tape.gradient(photo_disc_loss,\n self.p_disc.trainable_variables)\n\n # Apply the gradients to the optimizer\n self.m_gen_optimizer.apply_gradients(zip(monet_generator_gradients,\n self.m_gen.trainable_variables))\n\n self.p_gen_optimizer.apply_gradients(zip(photo_generator_gradients,\n self.p_gen.trainable_variables))\n\n self.m_disc_optimizer.apply_gradients(zip(monet_discriminator_gradients,\n self.m_disc.trainable_variables))\n\n self.p_disc_optimizer.apply_gradients(zip(photo_discriminator_gradients,\n self.p_disc.trainable_variables))\n \n return {\n 'monet_gen_loss': total_monet_gen_loss,\n 'photo_gen_loss': total_photo_gen_loss,\n 'monet_disc_loss': monet_disc_loss,\n 'photo_disc_loss': photo_disc_loss\n }","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-04-03T09:04:06.037097Z","iopub.execute_input":"2024-04-03T09:04:06.037363Z","iopub.status.idle":"2024-04-03T09:04:08.726046Z","shell.execute_reply.started":"2024-04-03T09:04:06.037339Z","shell.execute_reply":"2024-04-03T09:04:08.72515Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# Loss functions","metadata":{}},{"cell_type":"code","source":"with strategy.scope():\n # Discriminator loss {0: fake, 1: real} (The discriminator loss outputs the average of the real and generated loss)\n def discriminator_loss(real, generated):\n real_loss = losses.BinaryCrossentropy(from_logits=True, reduction=losses.Reduction.NONE)(tf.ones_like(real), real)\n\n generated_loss = losses.BinaryCrossentropy(from_logits=True, reduction=losses.Reduction.NONE)(tf.zeros_like(generated), generated)\n\n total_disc_loss = real_loss + generated_loss\n\n return total_disc_loss * 0.5\n \n # Generator loss\n def generator_loss(generated):\n return losses.BinaryCrossentropy(from_logits=True, reduction=losses.Reduction.NONE)(tf.ones_like(generated), generated)\n \n \n # Cycle consistency loss (measures if original photo and the twice transformed photo to be similar to one another)\n with strategy.scope():\n def calc_cycle_loss(real_image, cycled_image, LAMBDA):\n loss1 = tf.reduce_mean(tf.abs(real_image - cycled_image))\n\n return LAMBDA * loss1\n\n # Identity loss (compares the image with its generator (i.e. photo with photo generator))\n with strategy.scope():\n def identity_loss(real_image, same_image, LAMBDA):\n loss = tf.reduce_mean(tf.abs(real_image - same_image))\n return LAMBDA * 0.5 * loss","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-04-03T09:04:08.727232Z","iopub.execute_input":"2024-04-03T09:04:08.727537Z","iopub.status.idle":"2024-04-03T09:04:08.738185Z","shell.execute_reply.started":"2024-04-03T09:04:08.727509Z","shell.execute_reply":"2024-04-03T09:04:08.736929Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# Train","metadata":{}},{"cell_type":"code","source":"with strategy.scope():\n # Create generators\n monet_generator_optimizer = optimizers.Adam(2e-4, beta_1=0.5)\n photo_generator_optimizer = optimizers.Adam(2e-4, beta_1=0.5)\n\n # Create discriminators\n monet_discriminator_optimizer = optimizers.Adam(2e-4, beta_1=0.5)\n photo_discriminator_optimizer = optimizers.Adam(2e-4, beta_1=0.5)\n \n # Create GAN\n gan_model = CycleGan(monet_generator, photo_generator, \n monet_discriminator, photo_discriminator)\n\n gan_model.compile(m_gen_optimizer=monet_generator_optimizer,\n p_gen_optimizer=photo_generator_optimizer,\n m_disc_optimizer=monet_discriminator_optimizer,\n p_disc_optimizer=photo_discriminator_optimizer,\n gen_loss_fn=generator_loss,\n disc_loss_fn=discriminator_loss,\n cycle_loss_fn=calc_cycle_loss,\n identity_loss_fn=identity_loss)\n \n\nhistory = gan_model.fit(get_gan_dataset(MONET_FILENAMES, PHOTO_FILENAMES, batch_size=BATCH_SIZE), \n steps_per_epoch=(n_monet_samples//BATCH_SIZE),\n epochs=EPOCHS,\n verbose=2).history","metadata":{"_kg_hide-output":true,"execution":{"iopub.status.busy":"2024-04-03T09:04:08.739588Z","iopub.execute_input":"2024-04-03T09:04:08.74029Z"},"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# Visualize predictions","metadata":{}},{"cell_type":"code","source":"display_generated_samples(load_dataset(PHOTO_FILENAMES).batch(1), monet_generator, 8)","metadata":{"_kg_hide-input":true,"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Make predictions","metadata":{}},{"cell_type":"code","source":"os.makedirs('../images/') # Create folder to save generated images\n\npredict_and_save(load_dataset(PHOTO_FILENAMES).batch(1), monet_generator, '../images/')","metadata":{"_kg_hide-input":true,"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# Submission file","metadata":{}},{"cell_type":"code","source":"shutil.make_archive('/kaggle/working/images/', 'zip', '../images')\n\nprint(f\"Generated samples: {len([name for name in os.listdir('../images/') if os.path.isfile(os.path.join('../images/', name))])}\")","metadata":{"_kg_hide-input":true,"trusted":true},"outputs":[],"execution_count":null}]}