


(This post was jointly written by the winning team, see details below)
\nFirst, we wish to express our congratulations to the winners and to all the nominees as well for their remarkable achievements and continued excellence and look forward to exciting times in object detection algorithms.
\nIn addition, many thanks to Kaggle and the organizers for holding this interesting competition. And special thanks to my colleagues @orkatz2 (Or Katz) and @solomonk (Shlomo Kashani, author of the book “Deep Learning Interviews”).
\nOur solution is based on the excellent MMDetection framework (https://github.com/open-mmlab/mmdetection). We evaluated and tested numerous models in an attempt to find the ones which are better suited for wheat detection. Why? Because there is not always a direct correlation between the COCO mAP score, as reported by the authors of the original models, and the actual mAP on the wheat corpus. Therefore, experimentation was extremely important. Amongst the many models we evaluated in MMDet are:
\nWe then trained an ensemble of the top-performing models which were:
\nTo increase the score a single round of pseudo labelling was applied to each model. Additionally, for a much better generalization of our models, we used heavy augmentations.
\nIn the original corpus provided by the organizers, the training images were cropped from an original set of larger images. Therefore, we collected and assembled the original puzzles resulting in a corpus of 1330 puzzle images. The puzzle collection algorithm we adopted was based on https://github.com/lRomul/argus-tgs-salt/blob/master/mosaic/create_mosaic.py. But we were unsuccessful in collecting the bounding boxes for puzzles. Mainly because of the existence of bounding boxes that are located on or in the vicinity the border of the image. For this reason, we generated crops for the puzzles offline in addition to training images and generated boxes for them using pseudo labelling.
\nWe used MultilabelStratifiedKFold with 5 folds (https://github.com/trent-b/iterative-stratification) stratified by the number of boxes, a median of box areas and source of images. We guaranteed that there isn’t any leak between the sub-folds, so that the images of one puzzle were used only in that one particular fold.
\nReferring to the paper https://arxiv.org/abs/2005.02162, one can see wheat heads from different sources. We assumed that the wheat heads of usask_1, ethz_1 sources are very different from the test sources (UTokyo_1, UTokyo_2, UQ_1, NAU_1). Therefore, we did not use these sources for validation.
\nHowever, our validation scores did not correlate well with the Kaggle LB. We only noticed global improvements (for example, DetectoRS is better than UniverseNet). Local improvements such as augmentation parameters, WBF parameters etc. did not correlate. We, therefore, shifted our attention to the LB scores mainly.
\nWe trained our models only on the first fold.
\nDue to the relatively small size of our training set, and another test set distribution, our approach relied heavily on data augmentation. During training, we utilized an extensive data augmentation protocol:
\na, b, c, d -- randomly selected images. Then we just do the following:top = np.concatenate([a, b], axis=1)\nbottom = np.concatenate([c, d], axis=1)\nresult = np.concatenate([top, bottom], axis=0)\na, b -- randomly selected images. Then: result = (a + b) / 2[(768 + 32 * i, 768 + 32 * i) for i in range(25)]. | \n | \n
|---|---|
| \n | \n
SPIKE dataset: https://www.kaggle.com/c/global-wheat-detection/discussion/164346
\nWe used DetectoRS with ResNet50 and UniverseNet+GFL with Res2Net101 as main models. DetectoRS was a little bit more accurate and however much slower to train than UniverseNet:
\nFor DetectoRS we used:
\nIn general, we used a multi-stage training pipeline:
\n
We used TTA6 (Test Time Augmentation) for all our models:
\nFor TTA was used a standard MMDet algorithm with NMS that looks like this for two-stage detectors (DetectoRS):
\n
For one-stage detectors (UniverseNet), the algorithm is similar, only without the part with RoiAlign, Head, etc.
\nconfidence = np.mean(scores > 0.75). If the confidence was greater than 0.6 we accepted this image and used for pseudo labelling.We used WBF (https://github.com/ZFTurbo/Weighted-Boxes-Fusion) for the ensemble. The distribution of DetectoRS and UniverseNet scores is different. So we applied scaling using rankdata (https://docs.scipy.org/doc/scipy/reference/generated/scipy.stats.rankdata.html):
scaled_scores = 0.5 * (rankdata(scores) / len(scores)) + 0.5.\nWBF parameters:
\n
Thanks to internet service provider HOSTKEY (https://www.hostkey.com) that gave me a grant for access to GPU servers.
\nThe code will be published soon.
", "messages": [ { "id": 959429, "postDate": "2020-08-05T15:21:21.660Z", "content": "(This post was jointly written by the winning team, see details below)
\nFirst, we wish to express our congratulations to the winners and to all the nominees as well for their remarkable achievements and continued excellence and look forward to exciting times in object detection algorithms.
\nIn addition, many thanks to Kaggle and the organizers for holding this interesting competition. And special thanks to my colleagues @orkatz2 (Or Katz) and @solomonk (Shlomo Kashani, author of the book “Deep Learning Interviews”).
\nOur solution is based on the excellent MMDetection framework (https://github.com/open-mmlab/mmdetection). We evaluated and tested numerous models in an attempt to find the ones which are better suited for wheat detection. Why? Because there is not always a direct correlation between the COCO mAP score, as reported by the authors of the original models, and the actual mAP on the wheat corpus. Therefore, experimentation was extremely important. Amongst the many models we evaluated in MMDet are:
\nWe then trained an ensemble of the top-performing models which were:
\nTo increase the score a single round of pseudo labelling was applied to each model. Additionally, for a much better generalization of our models, we used heavy augmentations.
\nIn the original corpus provided by the organizers, the training images were cropped from an original set of larger images. Therefore, we collected and assembled the original puzzles resulting in a corpus of 1330 puzzle images. The puzzle collection algorithm we adopted was based on https://github.com/lRomul/argus-tgs-salt/blob/master/mosaic/create_mosaic.py. But we were unsuccessful in collecting the bounding boxes for puzzles. Mainly because of the existence of bounding boxes that are located on or in the vicinity the border of the image. For this reason, we generated crops for the puzzles offline in addition to training images and generated boxes for them using pseudo labelling.
\nWe used MultilabelStratifiedKFold with 5 folds (https://github.com/trent-b/iterative-stratification) stratified by the number of boxes, a median of box areas and source of images. We guaranteed that there isn’t any leak between the sub-folds, so that the images of one puzzle were used only in that one particular fold.
\nReferring to the paper https://arxiv.org/abs/2005.02162, one can see wheat heads from different sources. We assumed that the wheat heads of usask_1, ethz_1 sources are very different from the test sources (UTokyo_1, UTokyo_2, UQ_1, NAU_1). Therefore, we did not use these sources for validation.
\nHowever, our validation scores did not correlate well with the Kaggle LB. We only noticed global improvements (for example, DetectoRS is better than UniverseNet). Local improvements such as augmentation parameters, WBF parameters etc. did not correlate. We, therefore, shifted our attention to the LB scores mainly.
\nWe trained our models only on the first fold.
\nDue to the relatively small size of our training set, and another test set distribution, our approach relied heavily on data augmentation. During training, we utilized an extensive data augmentation protocol:
\na, b, c, d -- randomly selected images. Then we just do the following:top = np.concatenate([a, b], axis=1)\nbottom = np.concatenate([c, d], axis=1)\nresult = np.concatenate([top, bottom], axis=0)\na, b -- randomly selected images. Then: result = (a + b) / 2[(768 + 32 * i, 768 + 32 * i) for i in range(25)]. | \n | \n
|---|---|
| \n | \n
SPIKE dataset: https://www.kaggle.com/c/global-wheat-detection/discussion/164346
\nWe used DetectoRS with ResNet50 and UniverseNet+GFL with Res2Net101 as main models. DetectoRS was a little bit more accurate and however much slower to train than UniverseNet:
\nFor DetectoRS we used:
\nIn general, we used a multi-stage training pipeline:
\n
We used TTA6 (Test Time Augmentation) for all our models:
\nFor TTA was used a standard MMDet algorithm with NMS that looks like this for two-stage detectors (DetectoRS):
\n
For one-stage detectors (UniverseNet), the algorithm is similar, only without the part with RoiAlign, Head, etc.
\nconfidence = np.mean(scores > 0.75). If the confidence was greater than 0.6 we accepted this image and used for pseudo labelling.We used WBF (https://github.com/ZFTurbo/Weighted-Boxes-Fusion) for the ensemble. The distribution of DetectoRS and UniverseNet scores is different. So we applied scaling using rankdata (https://docs.scipy.org/doc/scipy/reference/generated/scipy.stats.rankdata.html):
scaled_scores = 0.5 * (rankdata(scores) / len(scores)) + 0.5.\nWBF parameters:
\n
Thanks to internet service provider HOSTKEY (https://www.hostkey.com) that gave me a grant for access to GPU servers.
\nThe code will be published soon.
", "rawMarkdown": "# Introduction\n(This post was jointly written by the winning team, see details below)\n\nFirst, we wish to express our congratulations to the winners and to all the nominees as well for their remarkable achievements and continued excellence and look forward to exciting times in object detection algorithms.\n\nIn addition, many thanks to Kaggle and the organizers for holding this interesting competition. And special thanks to my colleagues @orkatz2 (Or Katz) and @solomonk (Shlomo Kashani, author of the book “Deep Learning Interviews”).\n\n# Code\n- training code: https://github.com/amirassov/kaggle-global-wheat-detection\n- submission code: [pseudo ensemble: detectors (3 st)+universenet r10](https://www.kaggle.com/amiras/pseudo-ensemble-detectors-3-st-universenet-r10)\n\n# Summary\nOur solution is based on the excellent MMDetection framework (https://github.com/open-mmlab/mmdetection). We evaluated and tested numerous models in an attempt to find the ones which are better suited for wheat detection. Why? Because there is not always a direct correlation between the COCO mAP score, as reported by the authors of the original models, and the actual mAP on the wheat corpus. Therefore, experimentation was extremely important. Amongst the many models we evaluated in MMDet are: \n- GFocal\n- ATSS\n- UniverseNet \n- DetectorRS \n- SOLO-v2 (used for segmentation but we experimented with it anyway)\n\nWe then trained an ensemble of the top-performing models which were: \n- DetectoRS with the ResNet50 backbone (https://github.com/joe-siyuan-qiao/DetectoRS)\n- UniverseNet+GFL with the Res2Net101 backbone (https://github.com/shinya7y/UniverseNet)\n\nTo increase the score a single round of pseudo labelling was applied to each model. Additionally, for a much better generalization of our models, we used heavy augmentations.\n\n# Jigsaw puzzles\nIn the original corpus provided by the organizers, the training images were cropped from an original set of larger images. Therefore, we collected and assembled the original puzzles resulting in a corpus of 1330 puzzle images. The puzzle collection algorithm we adopted was based on https://github.com/lRomul/argus-tgs-salt/blob/master/mosaic/create_mosaic.py. But we were unsuccessful in collecting the bounding boxes for puzzles. Mainly because of the existence of bounding boxes that are located on or in the vicinity the border of the image. For this reason, we generated crops for the puzzles offline in addition to training images and generated boxes for them using pseudo labelling.\n\n# Validation approach \nWe used MultilabelStratifiedKFold with 5 folds (https://github.com/trent-b/iterative-stratification) stratified by the number of boxes, a median of box areas and source of images. We guaranteed that there isn’t any leak between the sub-folds, so that the images of one puzzle were used only in that one particular fold.\n\nReferring to the paper https://arxiv.org/abs/2005.02162, one can see wheat heads from different sources. We assumed that the wheat heads of usask_1, ethz_1 sources are very different from the test sources (UTokyo_1, UTokyo_2, UQ_1, NAU_1). Therefore, we did not use these sources for validation.\n\nHowever, our validation scores did not correlate well with the Kaggle LB. We only noticed global improvements (for example, DetectoRS is better than UniverseNet). Local improvements such as augmentation parameters, WBF parameters etc. did not correlate. We, therefore, shifted our attention to the LB scores mainly. \n\nWe trained our models only on the first fold.\n\n# Augmentations\nDue to the relatively small size of our training set, and another test set distribution, our approach relied heavily on data augmentation. During training, we utilized an extensive data augmentation protocol:\n- Various augmentations from albumentations library (https://albumentations.ai):\n - HorizontalFlip, ShiftScaleRotate, RandomRotate90\n - RandomBrightnessContrast, HueSaturationValue, RGBShift\n - RandomGamma\n - CLAHE\n - Blur, MotionBlur\n - GaussNoise\n - ImageCompression\n - CoarseDropout\n- RandomBBoxesSafeCrop. Randomly select N boxes in the image and find their union. Then we cropped the image keeping this unified.\n- Image colorization (https://www.kaggle.com/orkatz2/pytorch-pix-2-pix-for-image-colorization) \n- Style transfer (https://github.com/bethgelab/stylize-datasets). A random image from a small test (10 images) was used as a style. \n- Mosaic augmentation. `a, b, c, d` -- randomly selected images. Then we just do the following:\n```\ntop = np.concatenate([a, b], axis=1)\nbottom = np.concatenate([c, d], axis=1)\nresult = np.concatenate([top, bottom], axis=0)\n```\n- Mixup augmentation. `a, b` -- randomly selected images. Then: `result = (a + b) / 2`\n- Multi-scale Training. In each iteration, the scale of image is randomly sampled from `[(768 + 32 * i, 768 + 32 * i) for i in range(25)]`.\n- All augmentations except colorization and style transfer were applied online.\nExamples of augmented images:\n\n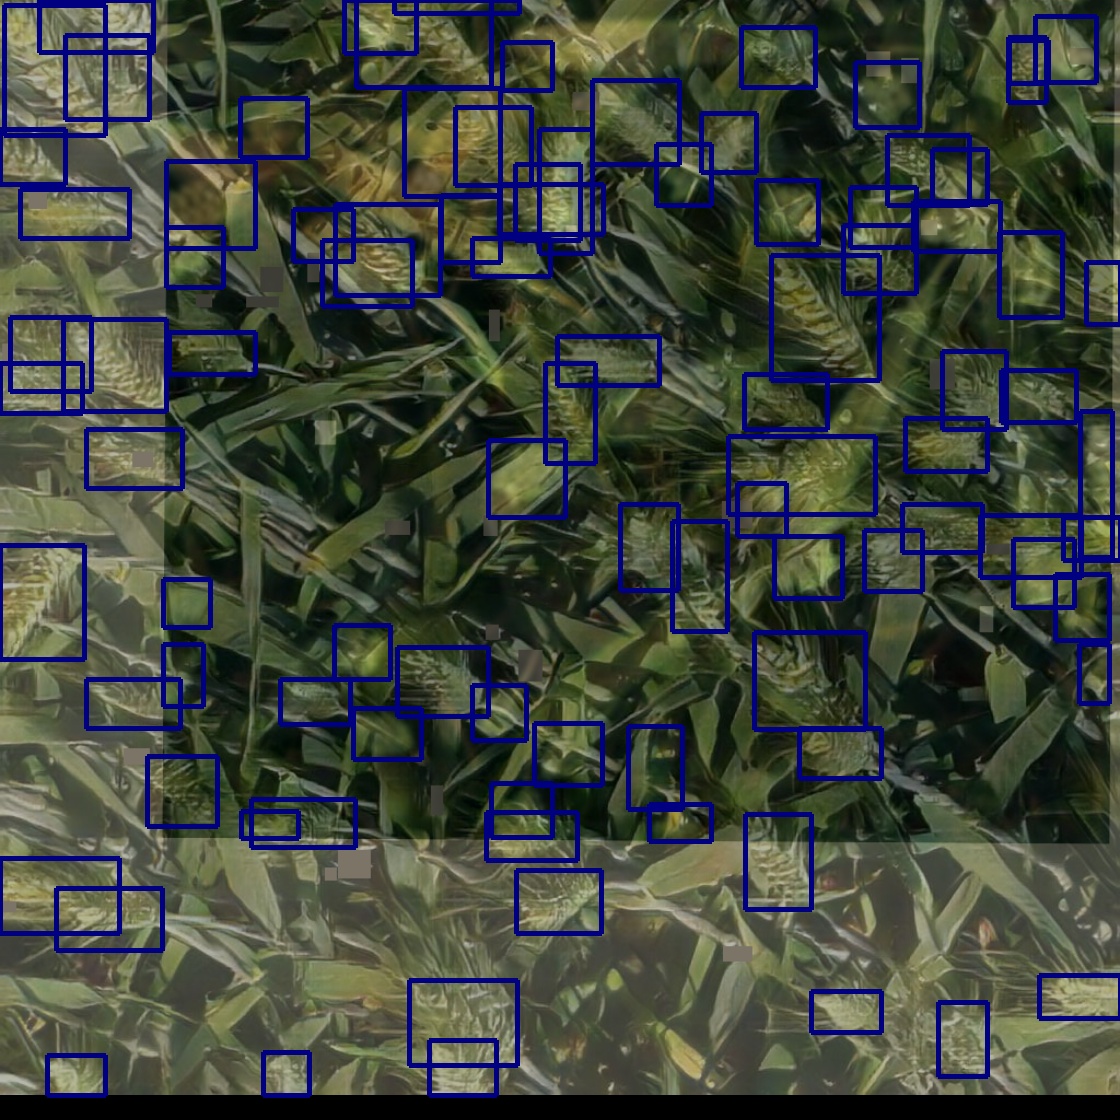 | 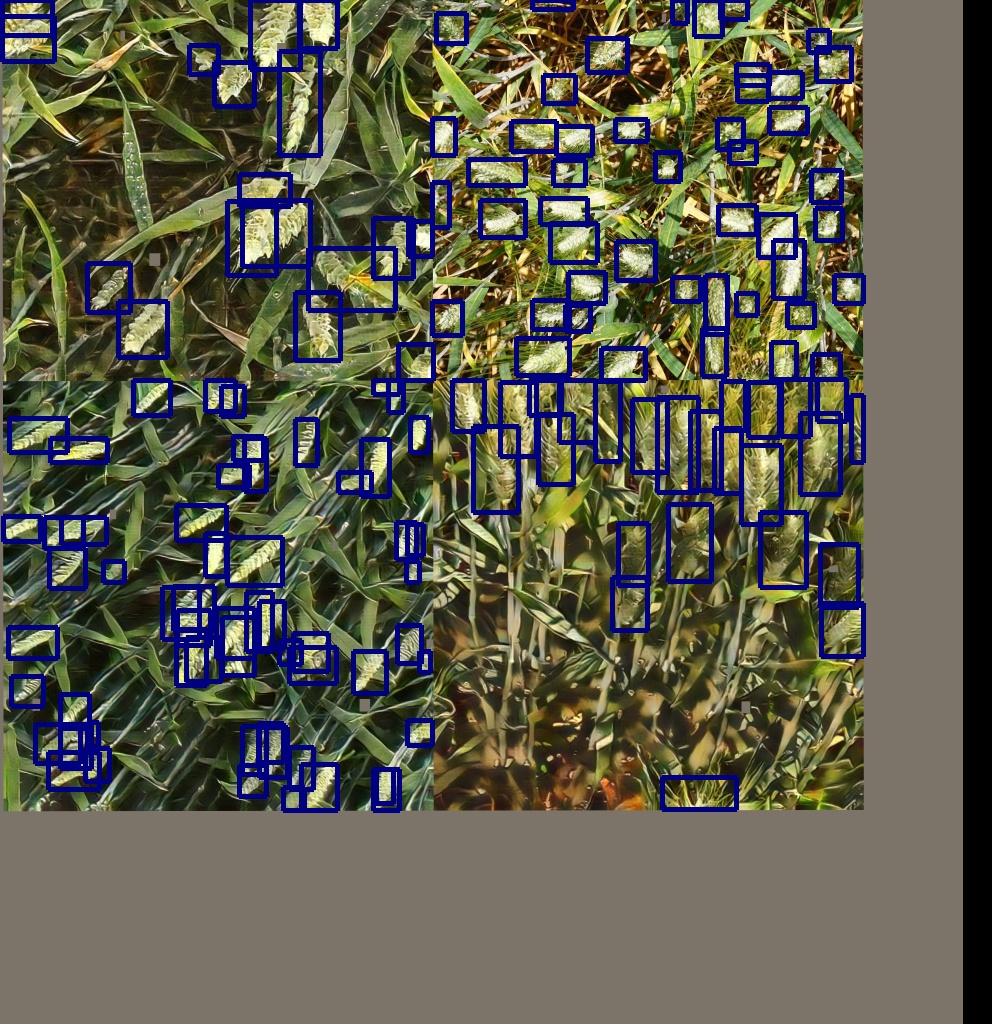 \n:-------------------------:|:-------------------------:\n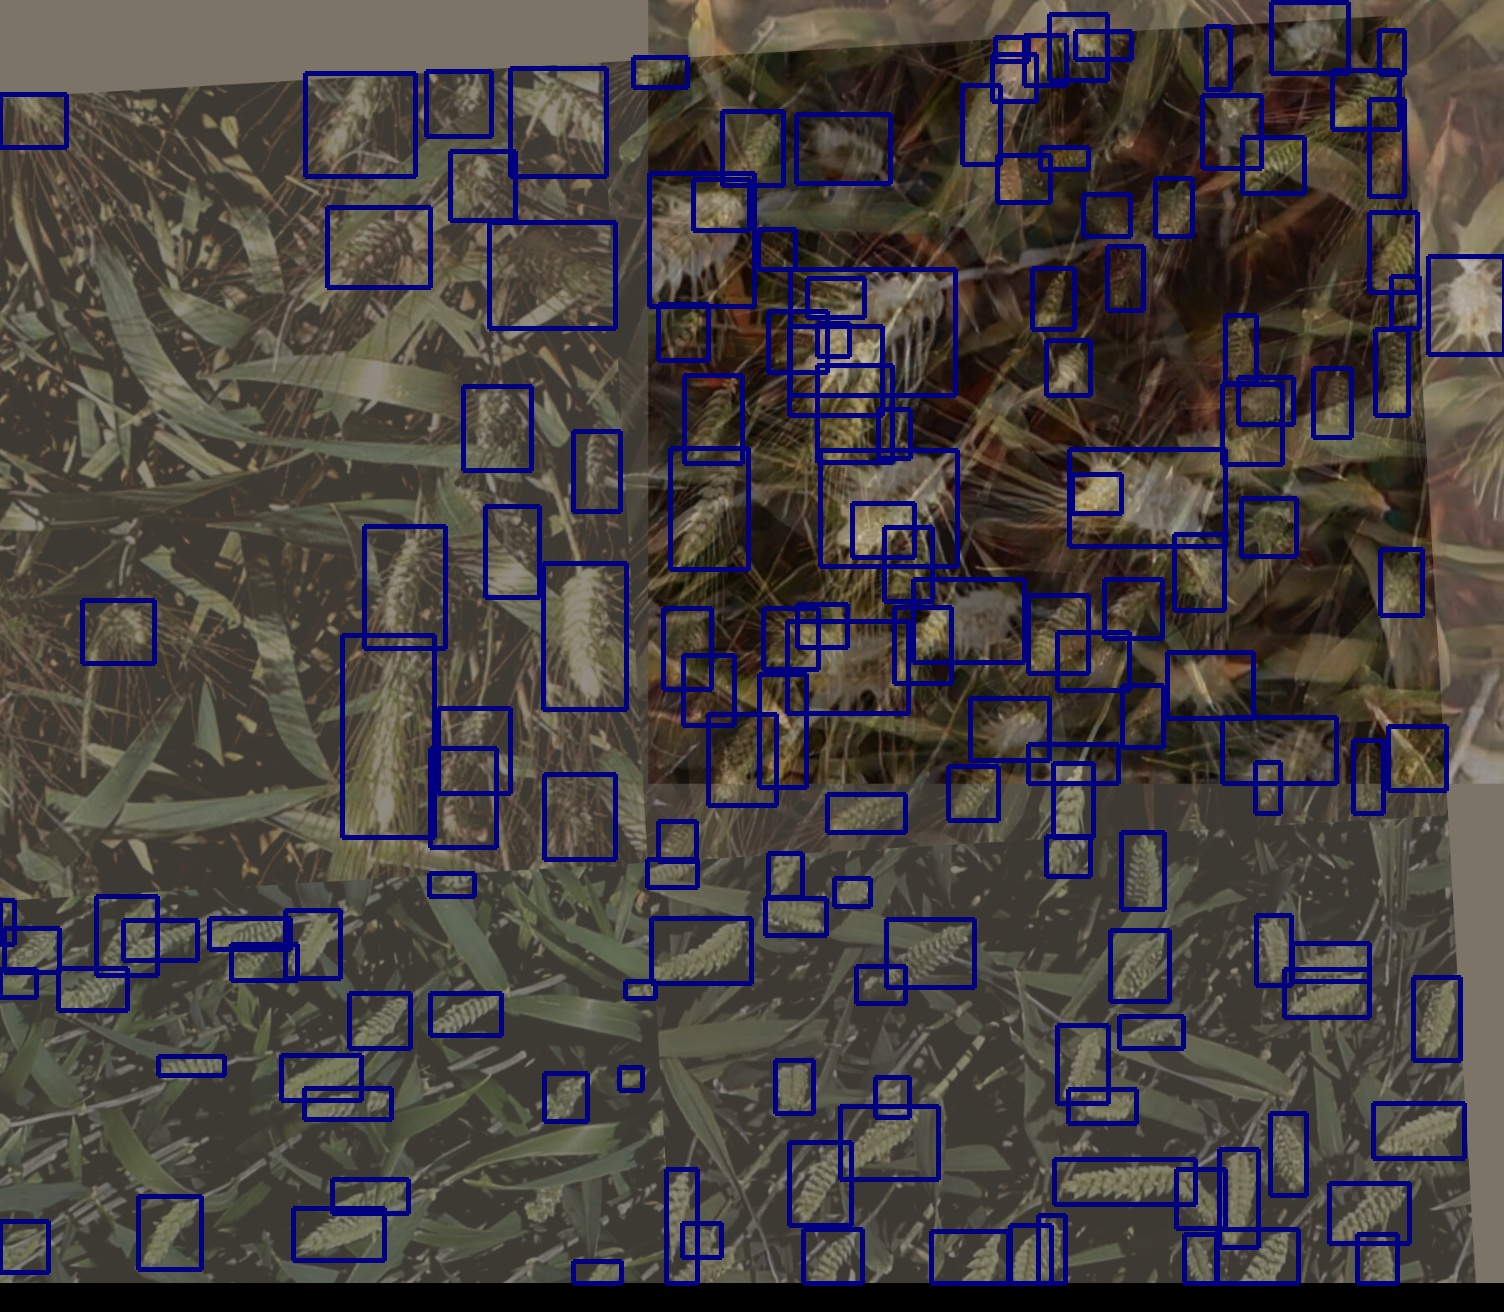 | 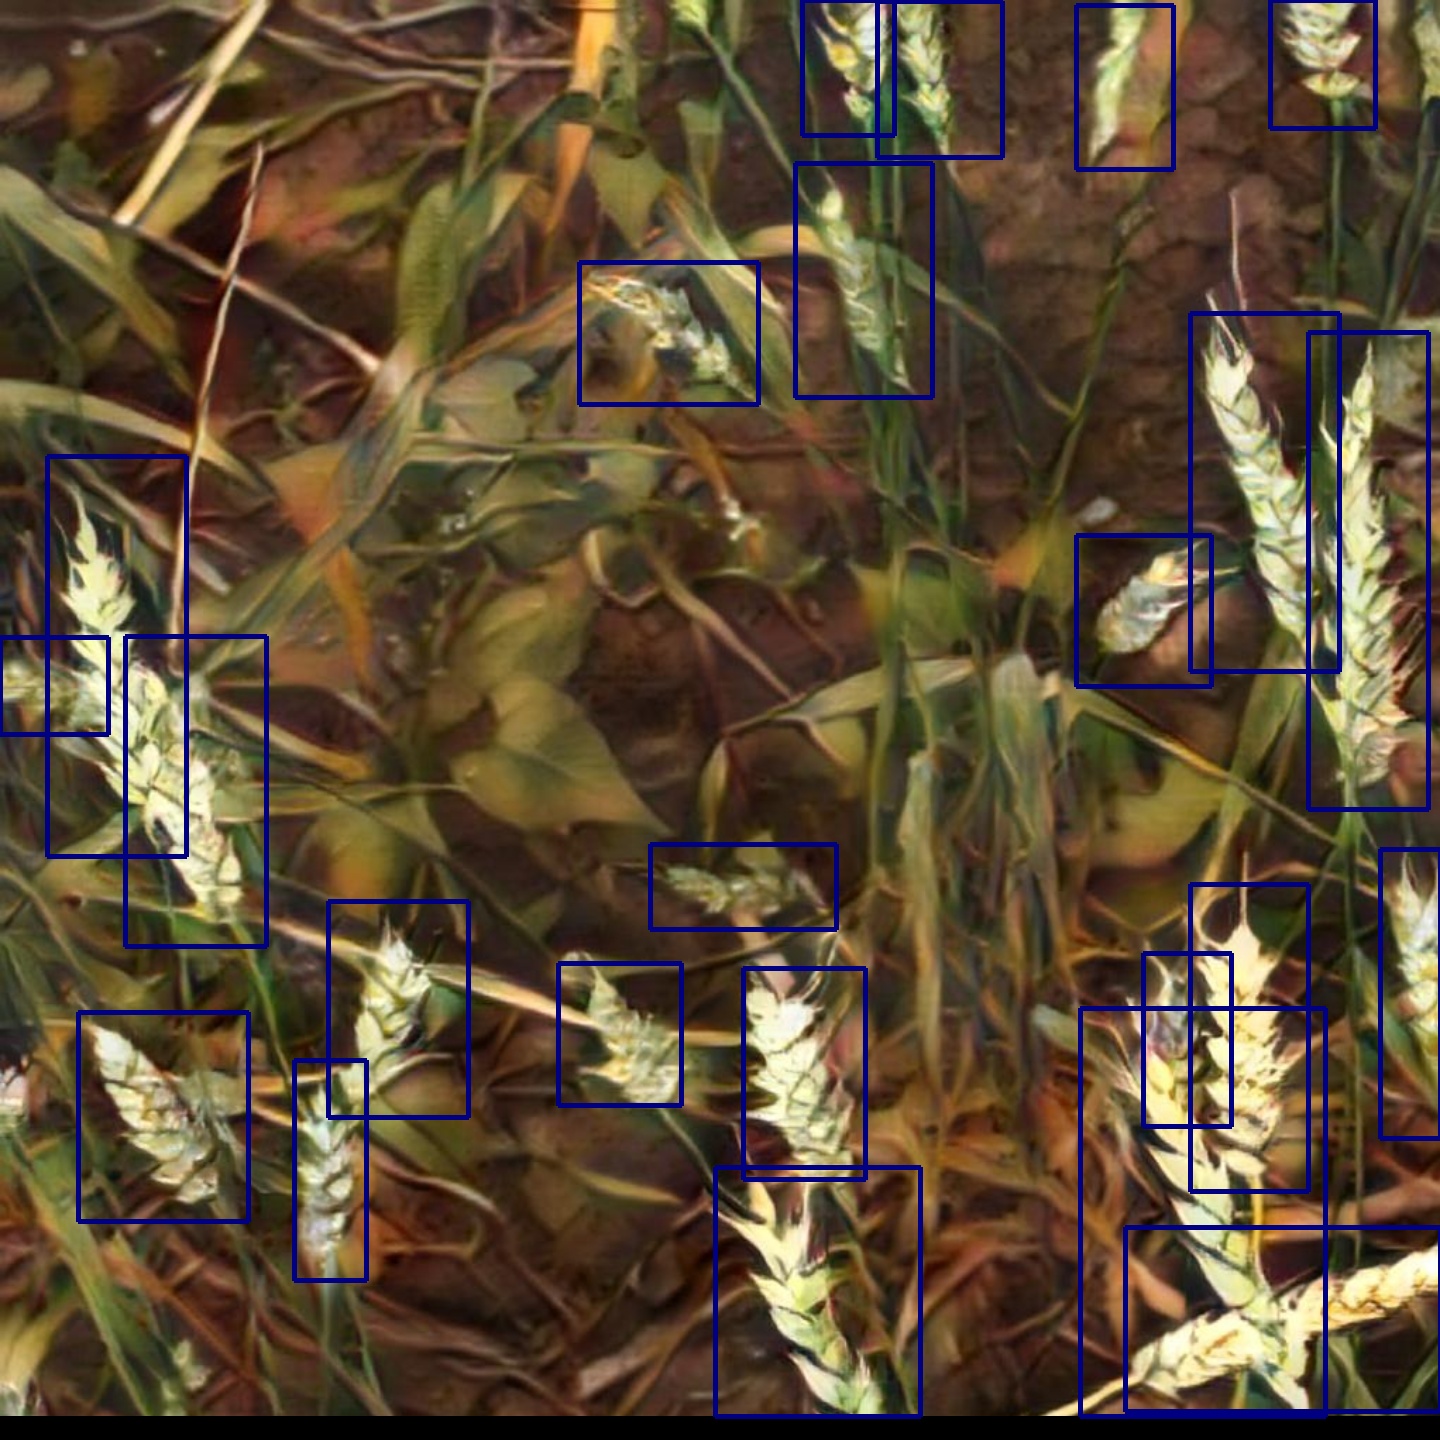\n\n# External data:\nSPIKE dataset: https://www.kaggle.com/c/global-wheat-detection/discussion/164346\n\n# Models\nWe used DetectoRS with ResNet50 and UniverseNet+GFL with Res2Net101 as main models. DetectoRS was a little bit more accurate and however much slower to train than UniverseNet:\n- Single DetectoRS Public LB score without pseudo labeling: 0.7592\n- Single UniverseNet Public LB score without pseudo labeling: 0.7567\n\nFor DetectoRS we used:\n- LabelSmoothCrossEntropyLoss with parameter 0.1\n- Empirical Attention (https://github.com/open-mmlab/mmdetection/tree/master/configs/empirical_attention)\n\n# Training pipeline\nIn general, we used a multi-stage training pipeline:\n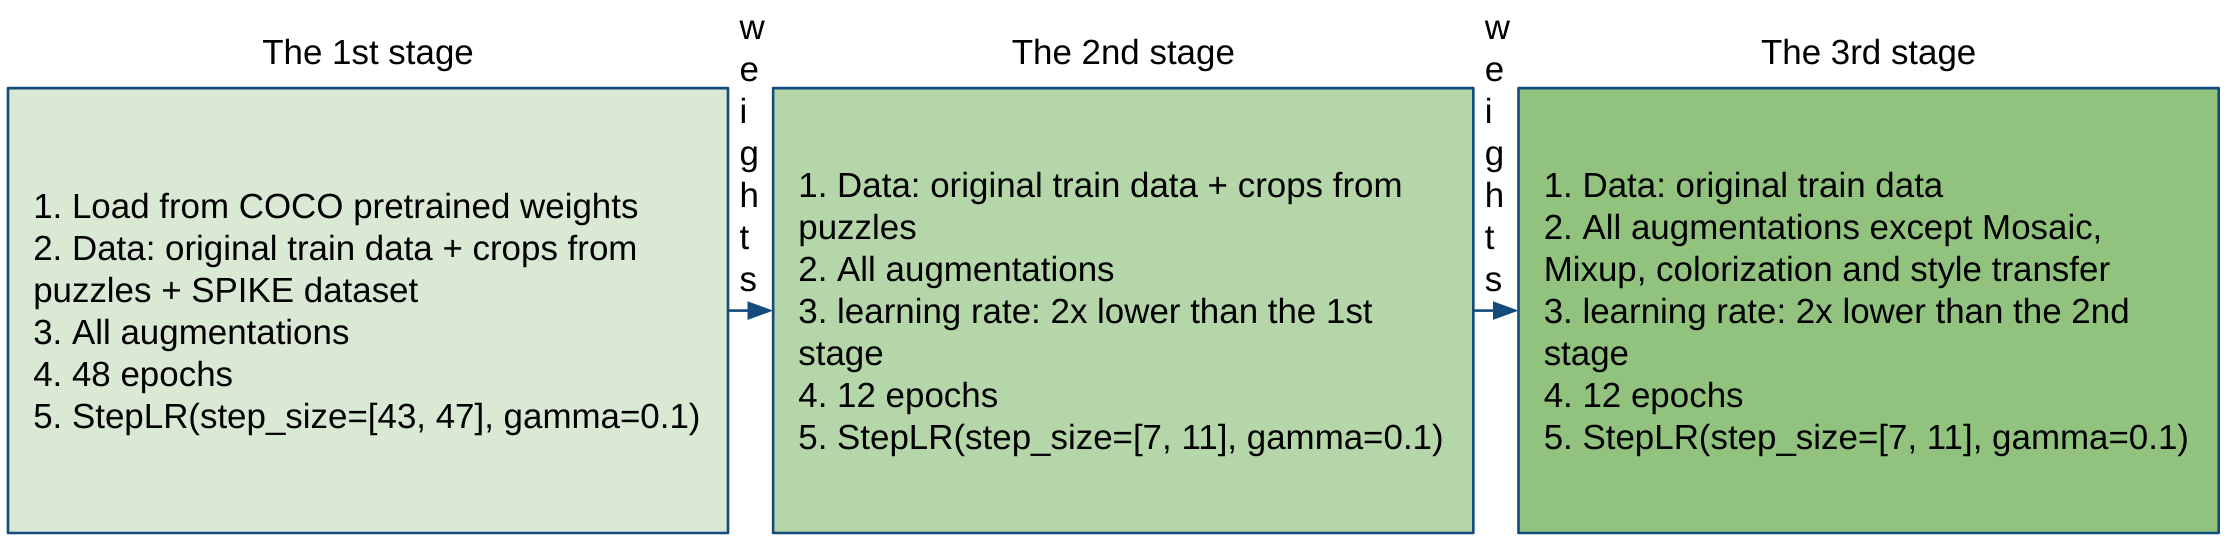\n\n# Model inference\nWe used TTA6 (Test Time Augmentation) for all our models:\n- Multi-scale Testing with scales [(1408, 1408), (1536, 1536)]\n- Flips: [original, horizontal, vertical]\n\nFor TTA was used a standard MMDet algorithm with NMS that looks like this for two-stage detectors (DetectoRS):\n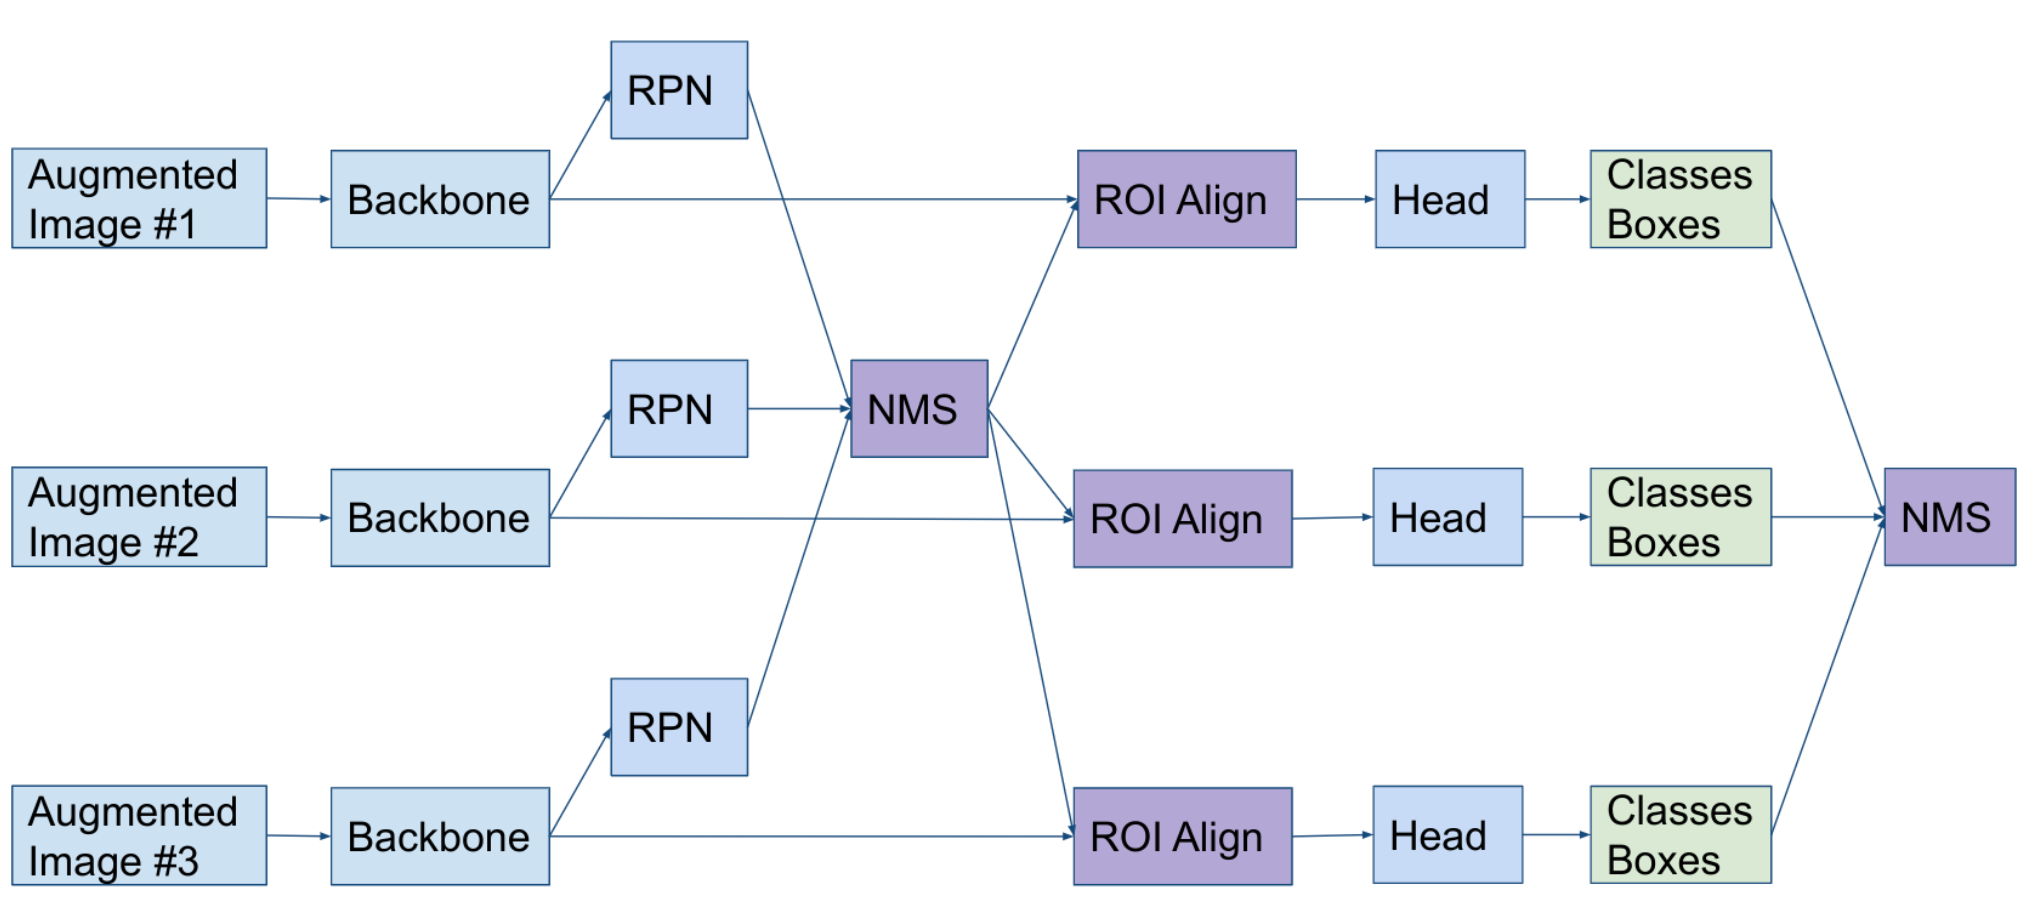\n\nFor one-stage detectors (UniverseNet), the algorithm is similar, only without the part with RoiAlign, Head, etc.\n\n# Pseudo labelling\n- Sampling positive examples. We predicted the test image and received its scores and the bounding boxes. Then we calculated `confidence = np.mean(scores > 0.75)`. If the confidence was greater than 0.6 we accepted this image and used for pseudo labelling.\n- Sources [usask_1, ethz_1] and augmentations like mosaic, mixup, colorization, style transfer weren’t used for pseudo labelling.\n- 1 epoch, 1 round, 1 stage.\n- Data: original data + 3 x pseudo test data\n\n# Ensemble\nWe used WBF (https://github.com/ZFTurbo/Weighted-Boxes-Fusion) for the ensemble. The distribution of DetectoRS and UniverseNet scores is different. So we applied scaling using `rankdata` (https://docs.scipy.org/doc/scipy/reference/generated/scipy.stats.rankdata.html):\n```\nscaled_scores = 0.5 * (rankdata(scores) / len(scores)) + 0.5.\n```\n\nWBF parameters:\n- weights=[0.65, 0.35] respectively for models [DetectoRS, UniverseNet]\n- iou_thr=0.55\n- score_thr=0.45\n\n# Our final submission pipeline (0.7262 on Private LB and 0.7734 on Public LB):\n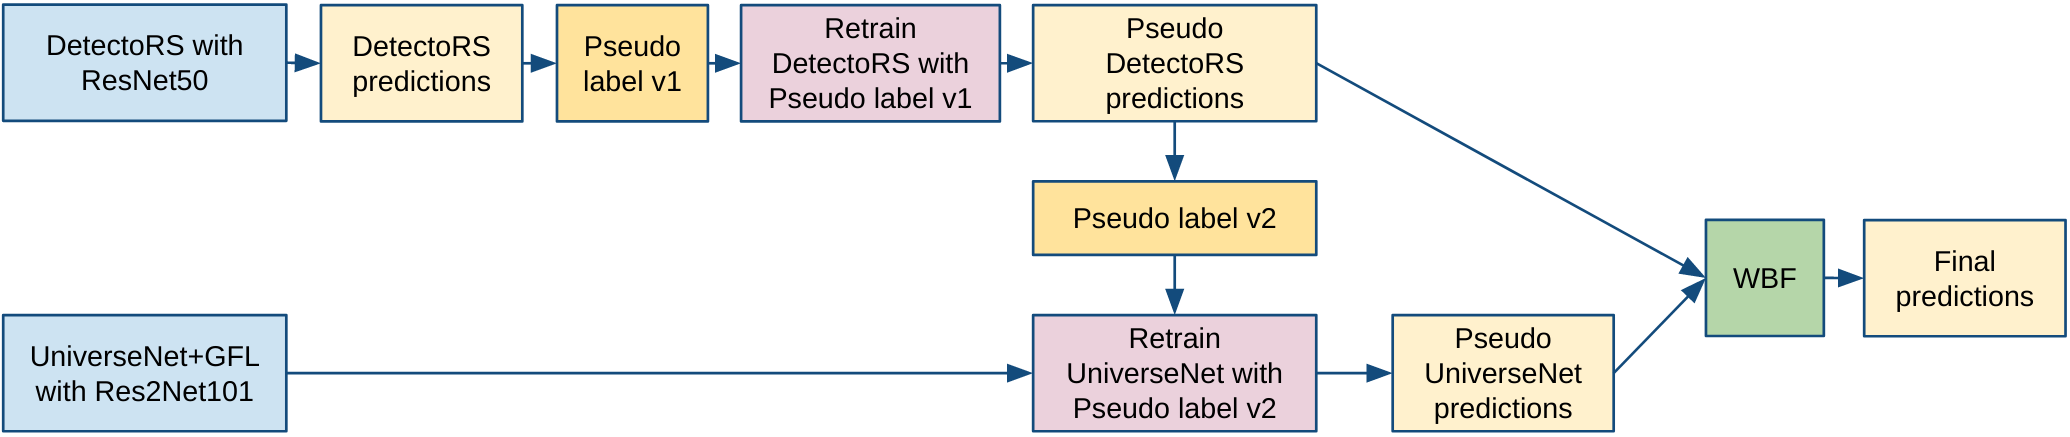\n\n# Some observations from our submissions:\n- Pseudo crops from jigsaw puzzles (DetectoRS R50): 0.7513 -> 0.7582\n- Tuning of pseudo labeling parameters for sampling positive examples (ensemble): 0.7709 -> 0.7729\n- Pseudo labeling (DetectoRS R50): 0.7582 -> 0.7691\n- Pseudo labeling (UniverseNet Res2Net50): 0.7494 -> 0.7627\n- SPIKE dataset (DetectoRS R50): 0.7582 -> 0.7592\n- Deleting [usask1, ethz1] from pseudo labeling (DetectoRS R50): 0.7678 -> 0.7691\n\n# What we didn’t do:\n- MMDetection and YOLOV5 ensemble. That was the main goal but since YOLOV5 was disqualified we gave up this option.\n- MMDetection and EfficientDet ensemble. We only managed to make a submission for the first time on the last day but we could not get a good enough result. We believe that if we had a few more days we could improve the result by tune the WBF parameters.\n- We stopped improving YOLOV5 about a month before the end of the competition. \n\n# What didn’t work:\n- Wheat Ears Detection Dataset: CV improved, but LB did not.\n- More than 1 rounds of pseudo labeling with the same model.\n- Scale-aware testing like this: https://drive.google.com/file/d/14VwSjMeRZUtisZtqQPmbll6w4zvZXIAQ\n- Rotate90 TTA for DetectoRS and UniverseNet\n\n# Acknowledgements\nThanks to internet service provider HOSTKEY (https://www.hostkey.com) that gave me a grant for access to GPU servers.\n\n\n**The code will be published soon.**\n\n", "votes": 266 }, { "id": 959432, "postDate": "2020-08-05T15:23:55.267Z", "content": "I am sooooo proud of both of you Amir and Or! what a great team!!!
", "rawMarkdown": "I am sooooo proud of both of you Amir and Or! what a great team!!! ", "votes": 11 }, { "id": 963728, "postDate": "2020-08-09T08:37:11.937Z", "content": "Great work!
", "rawMarkdown": "Great work!", "votes": 3 }, { "id": 959471, "postDate": "2020-08-05T15:57:57.460Z", "content": "Thanks for sharing!\nIt looks like GANs didn't work in your solution.\nCongratulation @amiras to new grand master!
", "rawMarkdown": "Thanks for sharing!\nIt looks like GANs didn't work in your solution.\nCongratulation @amiras to new grand master!", "votes": 3 }, { "id": 978012, "postDate": "2020-08-19T21:15:43.633Z", "content": "Congratulations on becoming a GM! Great achievement. I was a bit scared there, you were 1 place out of the Gold zone. That would have been quite unfortunate.
", "rawMarkdown": "Congratulations on becoming a GM! Great achievement. I was a bit scared there, you were 1 place out of the Gold zone. That would have been quite unfortunate.", "votes": 1 }, { "id": 967409, "postDate": "2020-08-12T08:24:23.177Z", "content": "Thanks for sharing the information with me.mmdet is nice
", "rawMarkdown": "Thanks for sharing the information with me.mmdet is nice", "votes": 1 }, { "id": 965494, "postDate": "2020-08-10T17:12:56.977Z", "content": "This is great, thanks a lot for sharing 💚 \nand, Congratulations 😍
", "rawMarkdown": "This is great, thanks a lot for sharing 💚 \nand, Congratulations 😍 ", "votes": 1 }, { "id": 963274, "postDate": "2020-08-08T20:28:10.553Z", "content": "Nice work. Congratulations
", "rawMarkdown": "Nice work. Congratulations", "votes": 1 }, { "id": 960519, "postDate": "2020-08-06T13:27:32.033Z", "content": "Great work!
", "rawMarkdown": "Great work!", "votes": 1 }, { "id": 959924, "postDate": "2020-08-06T03:08:22.260Z", "content": "Congratulations to you and team. Thanks for writeup your team solution @amiras
", "rawMarkdown": "Congratulations to you and team. Thanks for writeup your team solution @amiras", "votes": 1 }, { "id": 959489, "postDate": "2020-08-05T16:11:42.183Z", "content": "Great solution! Gratz
", "rawMarkdown": "Great solution! Gratz", "votes": 2 }, { "id": 959483, "postDate": "2020-08-05T16:07:48.973Z", "content": "Thank you for the detailed explanation.
\n\nCongrats @amiras and your awesome team!
", "rawMarkdown": "Thank you for the detailed explanation.\n\nCongrats @amiras and your awesome team! ", "votes": 2 }, { "id": 1250783, "postDate": "2021-03-24T09:18:45.973Z", "content": "@amiras Great solution. May iI asked what was your plan on tuning the wbf parameters? Thank you
", "rawMarkdown": "@amiras Great solution. May iI asked what was your plan on tuning the wbf parameters? Thank you" }, { "id": 986049, "postDate": "2020-08-26T07:00:49.457Z", "content": "Hello,Why you didnot use Mosaic in P-label training?
", "rawMarkdown": "Hello,Why you didnot use Mosaic in P-label training?" }, { "id": 986048, "postDate": "2020-08-26T07:00:49.443Z", "content": "Hello,Why you didnot use Mosaic in P-label training?
", "rawMarkdown": "Hello,Why you didnot use Mosaic in P-label training?" }, { "id": 974503, "postDate": "2020-08-18T00:59:21.743Z", "content": "Great info. Thanks for also sharing some info about the sub-optimal pipelines. Good to be reminder that often times finding the right approach is about eliminating the wrong approaches.
", "rawMarkdown": "Great info. Thanks for also sharing some info about the sub-optimal pipelines. Good to be reminder that often times finding the right approach is about eliminating the wrong approaches." }, { "id": 971835, "postDate": "2020-08-16T01:09:57.430Z", "content": "Great work! Could you please share your UniverseNet's code or config file for me .
", "rawMarkdown": "Great work! Could you please share your UniverseNet's code or config file for me . " }, { "id": 969919, "postDate": "2020-08-14T04:10:44.440Z", "content": "Congratulations on first place and thank you for sharing 👊
", "rawMarkdown": "Congratulations on first place and thank you for sharing 👊" }, { "id": 969720, "postDate": "2020-08-13T22:04:34.723Z", "content": "Impressive work!
", "rawMarkdown": "Impressive work!" }, { "id": 968801, "postDate": "2020-08-13T08:46:12.573Z", "content": "Thanks for the information. For a beginner like me, this knowledge is really helpful
", "rawMarkdown": "Thanks for the information. For a beginner like me, this knowledge is really helpful" }, { "id": 967053, "postDate": "2020-08-11T21:40:51.387Z", "content": "Nice work! Congratulations and thanks for sharing!
", "rawMarkdown": "Nice work! Congratulations and thanks for sharing!" }, { "id": 965935, "postDate": "2020-08-11T01:52:58.163Z", "content": "First post I ever read, it was great. Thanks!
", "rawMarkdown": "First post I ever read, it was great. Thanks!" }, { "id": 964685, "postDate": "2020-08-10T05:12:07.413Z", "content": "thanks for sharing, I look forward to your code
", "rawMarkdown": "thanks for sharing, I look forward to your code" }, { "id": 964037, "postDate": "2020-08-09T14:33:47.430Z", "content": "Congratulations! Great work!
", "rawMarkdown": "Congratulations! Great work!" }, { "id": 963956, "postDate": "2020-08-09T13:15:36.387Z", "content": "Congratulations! Great work!
", "rawMarkdown": "Congratulations! Great work!" }, { "id": 963796, "postDate": "2020-08-09T09:44:08.490Z", "content": "This is nice work
", "rawMarkdown": "This is nice work " }, { "id": 963739, "postDate": "2020-08-09T08:48:24.433Z", "content": "I look forward to the code being published.\nGreat work!
", "rawMarkdown": "I look forward to the code being published.\nGreat work!" }, { "id": 963676, "postDate": "2020-08-09T07:52:20.860Z", "content": "This is excellent work
", "rawMarkdown": "This is excellent work" }, { "id": 963233, "postDate": "2020-08-08T19:16:28.583Z", "content": "poi poi koira hisab raikhen
", "rawMarkdown": "poi poi koira hisab raikhen" }, { "id": 963141, "postDate": "2020-08-08T17:34:15.213Z", "content": "great work
", "rawMarkdown": "great work\n" }, { "id": 963088, "postDate": "2020-08-08T16:52:48.027Z", "content": "Great work!
", "rawMarkdown": "Great work!" }, { "id": 962890, "postDate": "2020-08-08T14:21:31.560Z", "content": "good job!!!
", "rawMarkdown": "good job!!!" }, { "id": 962678, "postDate": "2020-08-08T10:38:35.863Z", "content": "Well Done!
", "rawMarkdown": "Well Done!" }, { "id": 962667, "postDate": "2020-08-08T10:23:14.763Z", "content": "Thanks for sharing your awesome solution, with so much detail.
\nCongratulations, very well deserved!
Great solution. Good job!
", "rawMarkdown": "Great solution. Good job!" }, { "id": 962572, "postDate": "2020-08-08T08:45:17.133Z", "content": "Interesting work
", "rawMarkdown": "Interesting work" }, { "id": 962355, "postDate": "2020-08-08T04:43:12.787Z", "content": "quite interesting work
", "rawMarkdown": "quite interesting work" }, { "id": 962196, "postDate": "2020-08-07T22:49:42.110Z", "content": "Great solve
", "rawMarkdown": "Great solve" }, { "id": 961969, "postDate": "2020-08-07T17:04:36.760Z", "content": "Thank you for sharing the details! Great explanation!
", "rawMarkdown": "Thank you for sharing the details! Great explanation!" }, { "id": 961737, "postDate": "2020-08-07T13:14:11.267Z", "content": "Great Work!!
", "rawMarkdown": "Great Work!!" }, { "id": 961583, "postDate": "2020-08-07T10:01:32.600Z", "content": "Great work! :)
", "rawMarkdown": "Great work! :) " }, { "id": 961443, "postDate": "2020-08-07T07:33:12.163Z", "content": "Congratulations!
", "rawMarkdown": "Congratulations!" }, { "id": 961187, "postDate": "2020-08-07T01:30:48.680Z", "content": "Great work!Do you have plans for open source code?
", "rawMarkdown": "Great work!Do you have plans for open source code?" }, { "id": 961016, "postDate": "2020-08-06T21:03:37.093Z", "content": "Style transfer is genius in this case! Have you checked the impact on the final score?\nThanks for sharing, and congratulations for you and your team.
", "rawMarkdown": "Style transfer is genius in this case! Have you checked the impact on the final score?\nThanks for sharing, and congratulations for you and your team.", "replies": [ { "id": 967645, "postDate": "2020-08-12T11:58:48.160Z", "content": "Unfortunately, during the competition, we did not check the individual impact of this feature on the public score. I can only say that the metric on validation did not decrease. I'll write if I check it in the future.
", "rawMarkdown": "Unfortunately, during the competition, we did not check the individual impact of this feature on the public score. I can only say that the metric on validation did not decrease. I'll write if I check it in the future.", "votes": 1 } ] }, { "id": 960965, "postDate": "2020-08-06T20:24:52.127Z", "content": "Congratulations
", "rawMarkdown": "Congratulations" }, { "id": 960930, "postDate": "2020-08-06T19:49:24.573Z", "content": "Great work!
", "rawMarkdown": "Great work!" }, { "id": 960911, "postDate": "2020-08-06T19:31:25.720Z", "content": "Thank you for the detailed explanation.
\n\nCongrats @amiras and your awesome team!
", "rawMarkdown": "Thank you for the detailed explanation.\n\nCongrats @amiras and your awesome team!" }, { "id": 960791, "postDate": "2020-08-06T17:15:02.280Z", "content": "Great work
", "rawMarkdown": "Great work" }, { "id": 960785, "postDate": "2020-08-06T17:10:31.733Z", "content": "How efficient has it been the use of 'RetinaNet' while making the ensemble instead of YOLO? Just curious to understand.
\n\nGreat work I would say for the task performed and Congratulations!
", "rawMarkdown": "How efficient has it been the use of 'RetinaNet' while making the ensemble instead of YOLO? Just curious to understand.\n\nGreat work I would say for the task performed and Congratulations!", "replies": [ { "id": 967637, "postDate": "2020-08-12T11:52:47.313Z", "content": "We didn't use Retinanet and YOLO to build the ensemble. We used DetectoRS and UniverseNet
", "rawMarkdown": "We didn't use Retinanet and YOLO to build the ensemble. We used DetectoRS and UniverseNet", "votes": 1 } ] }, { "id": 960778, "postDate": "2020-08-06T17:07:56.107Z", "content": "It's really a great job.Thanks for sharing!\nBut I am not sure what is the meaning of \"We trained our models only on the first fold\".Do you mean you are training your models in the same fold(1/5 dataset)?
", "rawMarkdown": "It's really a great job.Thanks for sharing!\nBut I am not sure what is the meaning of \"We trained our models only on the first fold\".Do you mean you are training your models in the same fold(1/5 dataset)?", "replies": [ { "id": 967634, "postDate": "2020-08-12T11:49:43.653Z", "content": "We trained models on 4/5 of the dataset and validated on 1/5
", "rawMarkdown": "We trained models on 4/5 of the dataset and validated on 1/5 ", "votes": 2 } ] }, { "id": 960664, "postDate": "2020-08-06T15:24:38.493Z", "content": "Great piece of work!!
", "rawMarkdown": "Great piece of work!! " }, { "id": 960662, "postDate": "2020-08-06T15:22:45.587Z", "content": "Cool
", "rawMarkdown": "Cool" }, { "id": 960506, "postDate": "2020-08-06T13:08:41.737Z", "content": "wow!
", "rawMarkdown": "wow!" }, { "id": 960121, "postDate": "2020-08-06T06:49:11.170Z", "content": "Very Impressive!!!. Huge Thanks for sharing!!
", "rawMarkdown": "Very Impressive!!!. Huge Thanks for sharing!!" }, { "id": 959969, "postDate": "2020-08-06T04:09:25.023Z", "content": "Great works! Thanks for sharing, such a informative solution with tons of knowledge 💯
", "rawMarkdown": "Great works! Thanks for sharing, such a informative solution with tons of knowledge 💯 " }, { "id": 959686, "postDate": "2020-08-05T20:13:22.670Z", "content": "Sorry for a silly questions, but I still wonder how is TTA effective in Object detection as every different augmentation will gove us different bounding boxes so how do we get correct prediction at last?
", "rawMarkdown": "Sorry for a silly questions, but I still wonder how is TTA effective in Object detection as every different augmentation will gove us different bounding boxes so how do we get correct prediction at last?", "replies": [ { "id": 959824, "postDate": "2020-08-05T23:39:14.133Z", "content": "That's where WBF comes in. It merges bboxes for ensemble, whether from TTA or multiple models.
", "rawMarkdown": "That's where WBF comes in. It merges bboxes for ensemble, whether from TTA or multiple models." }, { "id": 960138, "postDate": "2020-08-06T07:08:21.050Z", "content": "For TTA was used a standard MMDet algorithm with NMS that looks like this for two-stage detectors (DetectoRS):
\n
For one-stage detectors (UniverseNet), the algorithm is similar, only without the part with RoiAlign, Head, etc.
\nWBF was used only for ensemble of two models.
", "rawMarkdown": "For TTA was used a standard MMDet algorithm with NMS that looks like this for two-stage detectors (DetectoRS):\n\n\nFor one-stage detectors (UniverseNet), the algorithm is similar, only without the part with RoiAlign, Head, etc.\n\nWBF was used only for ensemble of two models.", "votes": 5 } ] }, { "id": 959658, "postDate": "2020-08-05T19:34:11.197Z", "content": "Thank you for the detailed explanation.
\n\nCongrats @amiras and your awesome team!
", "rawMarkdown": "Thank you for the detailed explanation.\n\nCongrats @amiras and your awesome team!" }, { "id": 959636, "postDate": "2020-08-05T19:08:00.620Z", "content": "Congratulations! Hard work payed back indeed, awesome insights to the approach. Thank you so much for sharing!
", "rawMarkdown": "Congratulations! Hard work payed back indeed, awesome insights to the approach. Thank you so much for sharing!" }, { "id": 959632, "postDate": "2020-08-05T19:02:30.773Z", "content": "Congratulations!
", "rawMarkdown": "Congratulations! " }, { "id": 959611, "postDate": "2020-08-05T18:35:17.710Z", "content": "Thanks very much for sharing the solution, and congratulations on the phenomenal effort! I have a question about your post. Would you be able to indicate which of the many methods you applied provided the most boost vs those which you're not sure helped much?
", "rawMarkdown": "Thanks very much for sharing the solution, and congratulations on the phenomenal effort! I have a question about your post. Would you be able to indicate which of the many methods you applied provided the most boost vs those which you're not sure helped much?", "replies": [ { "id": 960163, "postDate": "2020-08-06T07:26:08.880Z", "content": "Here are some observations from our submissions:\n- Pseudo crops from jigsaw puzzles (DetectoRS R50): 0.7513 -> 0.7582\n- Tuning of pseudo labeling parameters for sampling positive examples (ensemble): 0.7709 -> 0.7729\n- Pseudo labeling (DetectoRS R50): 0.7582 -> 0.7691\n- Pseudo labeling (UniverseNet Res2Net50): 0.7494 -> 0.7627\n- SPIKE dataset (DetectoRS R50): 0.7582 -> 0.7592\n- Deleting [usask1, ethz1] from pseudo labeling (DetectoRS R50): 0.7678 -> 0.7691
", "rawMarkdown": "Here are some observations from our submissions:\n- Pseudo crops from jigsaw puzzles (DetectoRS R50): 0.7513 -> 0.7582\n- Tuning of pseudo labeling parameters for sampling positive examples (ensemble): 0.7709 -> 0.7729\n- Pseudo labeling (DetectoRS R50): 0.7582 -> 0.7691\n- Pseudo labeling (UniverseNet Res2Net50): 0.7494 -> 0.7627\n- SPIKE dataset (DetectoRS R50): 0.7582 -> 0.7592\n- Deleting [usask1, ethz1] from pseudo labeling (DetectoRS R50): 0.7678 -> 0.7691", "votes": 7 }, { "id": 960187, "postDate": "2020-08-06T07:52:09.830Z", "content": "Awesome! Thanks
", "rawMarkdown": "Awesome! Thanks" } ] }, { "id": 959602, "postDate": "2020-08-05T18:28:09.550Z", "content": "Many thanks and congratulations on new grandmaster @amiras!! You deserve the winner with lots of works and knowledge. I've learned a lot
", "rawMarkdown": "Many thanks and congratulations on new grandmaster @amiras!! You deserve the winner with lots of works and knowledge. I've learned a lot" }, { "id": 959553, "postDate": "2020-08-05T17:28:48.937Z", "content": "Congratulations!
\n\nI noticed that you trained only 1 epoch on pseudo-label model. I am wondering how much gain you got from it?
", "rawMarkdown": "Congratulations! \n\nI noticed that you trained only 1 epoch on pseudo-label model. I am wondering how much gain you got from it? ", "replies": [ { "id": 959569, "postDate": "2020-08-05T17:43:38.827Z", "content": "Thanks!
\n\nFor DetectoRS (one of the old models): 0.7582 -> 0.7691\nFor UniverseNet with Res2Net50: 0.7494 -> 0.7627
", "rawMarkdown": "Thanks! \n\nFor DetectoRS (one of the old models): 0.7582 -> 0.7691\nFor UniverseNet with Res2Net50: 0.7494 -> 0.7627", "votes": 4 }, { "id": 959783, "postDate": "2020-08-05T22:11:28.580Z", "content": "Thanks for the info. I have another question: in the pseudo labeling section, you state \"Data: original data + 3 x pseudo test data\"
\n\nDo you mean in each training epoch, each selected test image is sampled 3 times, while each original training image is sampled once?
", "rawMarkdown": "Thanks for the info. I have another question: in the pseudo labeling section, you state \"Data: original data + 3 x pseudo test data\"\n\nDo you mean in each training epoch, each selected test image is sampled 3 times, while each original training image is sampled once?" }, { "id": 959915, "postDate": "2020-08-06T03:03:21.060Z", "content": "Yes. I think therefore 1 epoch is enough.
", "rawMarkdown": "Yes. I think therefore 1 epoch is enough.", "votes": 3 }, { "id": 961193, "postDate": "2020-08-07T01:44:44.333Z", "content": "Thanks a lot! Looking forward to your code for more details 👍👍👍
", "rawMarkdown": "Thanks a lot! Looking forward to your code for more details 👍👍👍" } ] }, { "id": 965422, "postDate": "2020-08-10T16:00:06.633Z", "rawMarkdown": "", "votes": -1, "isDeleted": true }, { "id": 963494, "postDate": "2020-08-09T04:38:59.063Z", "rawMarkdown": "", "isDeleted": true }, { "id": 963471, "postDate": "2020-08-09T04:10:26.940Z", "rawMarkdown": "", "isDeleted": true }, { "id": 963470, "postDate": "2020-08-09T04:10:17.010Z", "rawMarkdown": "", "isDeleted": true }, { "id": 962408, "postDate": "2020-08-08T05:38:41.710Z", "rawMarkdown": "", "isDeleted": true }, { "id": 961582, "postDate": "2020-08-07T10:01:10.280Z", "rawMarkdown": "", "isDeleted": true }, { "id": 961430, "postDate": "2020-08-07T07:20:58.393Z", "rawMarkdown": "", "isDeleted": true }, { "id": 963695, "postDate": "2020-08-09T08:08:23Z", "content": "Thank for sharing, Great solution!
", "rawMarkdown": "Thank for sharing, Great solution!", "votes": 11 }, { "id": 961340, "postDate": "2020-08-07T05:28:48.720Z", "content": "Thank you for the detailed explanation.
", "rawMarkdown": "Thank you for the detailed explanation.", "votes": 1 }, { "id": 959476, "postDate": "2020-08-05T16:00:58.067Z", "content": "huge. Thank for sharing
", "rawMarkdown": "huge. Thank for sharing", "votes": 1 }, { "id": 974345, "postDate": "2020-08-17T23:12:38.733Z", "content": "Thanks for sharing!!!!!!
", "rawMarkdown": "Thanks for sharing!!!!!!" }, { "id": 971983, "postDate": "2020-08-16T06:22:33.110Z", "content": "Great Work !! thanks for sharing
", "rawMarkdown": "Great Work !! thanks for sharing" }, { "id": 968798, "postDate": "2020-08-13T08:45:10.493Z", "content": "Thanks for the information
", "rawMarkdown": "Thanks for the information" }, { "id": 967349, "postDate": "2020-08-12T07:20:17.787Z", "content": "Thank for sharing
", "rawMarkdown": "Thank for sharing" }, { "id": 966933, "postDate": "2020-08-11T19:13:26.967Z", "content": "Great work and thanks for sharing…
", "rawMarkdown": "Great work and thanks for sharing..." }, { "id": 966084, "postDate": "2020-08-11T05:46:08.043Z", "content": "Congratulations! Thanks for sharing!
", "rawMarkdown": "Congratulations! Thanks for sharing!" }, { "id": 965500, "postDate": "2020-08-10T17:18:39.943Z", "content": "Keep sharing bro!! Thanks
", "rawMarkdown": "Keep sharing bro!! Thanks" }, { "id": 964924, "postDate": "2020-08-10T09:15:11.207Z", "content": "So informative! Thanks a lot.
", "rawMarkdown": "So informative! Thanks a lot." }, { "id": 963244, "postDate": "2020-08-08T19:34:13.457Z", "content": "Perfect.Thank for sharing
", "rawMarkdown": "Perfect.Thank for sharing" }, { "id": 963075, "postDate": "2020-08-08T16:36:54.887Z", "content": "Thanks for sharing!
", "rawMarkdown": "Thanks for sharing!" }, { "id": 961878, "postDate": "2020-08-07T15:22:54.510Z", "content": "Very Interesting, thank you!
", "rawMarkdown": "Very Interesting, thank you!" }, { "id": 961459, "postDate": "2020-08-07T07:41:19.243Z", "content": "Congratulations.
\nThanks for sharing
I enjoyed reading thank you very much.
", "rawMarkdown": "I enjoyed reading thank you very much." }, { "id": 960320, "postDate": "2020-08-06T10:01:44.937Z", "content": "Congratulations and thanks for sharing!
", "rawMarkdown": "Congratulations and thanks for sharing!" }, { "id": 959927, "postDate": "2020-08-06T03:11:34.383Z", "content": "Informative! Thank you :)
", "rawMarkdown": "Informative! Thank you :) " } ], "comments": [ { "id": 959432, "author_name": "QuantScientist", "author_url": "", "post_date": "2020-08-05T15:23:55.267000", "content": "I am sooooo proud of both of you Amir and Or! what a great team!!!
", "votes": 11, "replies": [] }, { "id": 963728, "author_name": "", "author_url": "", "post_date": "2020-08-09T08:37:11.937000", "content": "Great work!
", "votes": 3, "replies": [] }, { "id": 959471, "author_name": "DungNB", "author_url": "", "post_date": "2020-08-05T15:57:57.460000", "content": "Thanks for sharing!\nIt looks like GANs didn't work in your solution.\nCongratulation @amiras to new grand master!
", "votes": 3, "replies": [] }, { "id": 978012, "author_name": "Stanley Zheng", "author_url": "", "post_date": "2020-08-19T21:15:43.633000", "content": "Congratulations on becoming a GM! Great achievement. I was a bit scared there, you were 1 place out of the Gold zone. That would have been quite unfortunate.
", "votes": 1, "replies": [] }, { "id": 967409, "author_name": "", "author_url": "", "post_date": "2020-08-12T08:24:23.177000", "content": "Thanks for sharing the information with me.mmdet is nice
", "votes": 1, "replies": [] }, { "id": 965494, "author_name": "Abdur Rahim", "author_url": "", "post_date": "2020-08-10T17:12:56.977000", "content": "This is great, thanks a lot for sharing 💚 \nand, Congratulations 😍
", "votes": 1, "replies": [] }, { "id": 963274, "author_name": "jayanth97", "author_url": "", "post_date": "2020-08-08T20:28:10.553000", "content": "Nice work. Congratulations
", "votes": 1, "replies": [] }, { "id": 960519, "author_name": "Asuto Goodman", "author_url": "", "post_date": "2020-08-06T13:27:32.033000", "content": "Great work!
", "votes": 1, "replies": [] }, { "id": 959924, "author_name": "KhanhVD", "author_url": "", "post_date": "2020-08-06T03:08:22.260000", "content": "Congratulations to you and team. Thanks for writeup your team solution @amiras
", "votes": 1, "replies": [] }, { "id": 959489, "author_name": "Alimbekov Renat [dsmlkz]", "author_url": "", "post_date": "2020-08-05T16:11:42.183000", "content": "Great solution! Gratz
", "votes": 2, "replies": [] }, { "id": 959483, "author_name": "Heroseo", "author_url": "", "post_date": "2020-08-05T16:07:48.973000", "content": "Thank you for the detailed explanation.
\n\nCongrats @amiras and your awesome team!
", "votes": 2, "replies": [] }, { "id": 1250783, "author_name": "Nguyen Phuc Dat", "author_url": "", "post_date": "2021-03-24T09:18:45.973000", "content": "@amiras Great solution. May iI asked what was your plan on tuning the wbf parameters? Thank you
", "votes": 0, "replies": [] }, { "id": 986049, "author_name": "Zekun", "author_url": "", "post_date": "2020-08-26T07:00:49.457000", "content": "Hello,Why you didnot use Mosaic in P-label training?
", "votes": 0, "replies": [] }, { "id": 986048, "author_name": "Zekun", "author_url": "", "post_date": "2020-08-26T07:00:49.443000", "content": "Hello,Why you didnot use Mosaic in P-label training?
", "votes": 0, "replies": [] }, { "id": 974503, "author_name": "Calvin Miller", "author_url": "", "post_date": "2020-08-18T00:59:21.743000", "content": "Great info. Thanks for also sharing some info about the sub-optimal pipelines. Good to be reminder that often times finding the right approach is about eliminating the wrong approaches.
", "votes": 0, "replies": [] }, { "id": 971835, "author_name": "wangstone", "author_url": "", "post_date": "2020-08-16T01:09:57.430000", "content": "Great work! Could you please share your UniverseNet's code or config file for me .
", "votes": 0, "replies": [] }, { "id": 969919, "author_name": "Alin Cijov", "author_url": "", "post_date": "2020-08-14T04:10:44.440000", "content": "Congratulations on first place and thank you for sharing 👊
", "votes": 0, "replies": [] }, { "id": 969720, "author_name": "Eric J", "author_url": "", "post_date": "2020-08-13T22:04:34.723000", "content": "Impressive work!
", "votes": 0, "replies": [] }, { "id": 968801, "author_name": "The_unknown", "author_url": "", "post_date": "2020-08-13T08:46:12.573000", "content": "Thanks for the information. For a beginner like me, this knowledge is really helpful
", "votes": 0, "replies": [] }, { "id": 967053, "author_name": "Pedro Zaterka", "author_url": "", "post_date": "2020-08-11T21:40:51.387000", "content": "Nice work! Congratulations and thanks for sharing!
", "votes": 0, "replies": [] }, { "id": 965935, "author_name": "Paul Gotcher", "author_url": "", "post_date": "2020-08-11T01:52:58.163000", "content": "First post I ever read, it was great. Thanks!
", "votes": 0, "replies": [] }, { "id": 964685, "author_name": "mrlcv", "author_url": "", "post_date": "2020-08-10T05:12:07.413000", "content": "thanks for sharing, I look forward to your code
", "votes": 0, "replies": [] }, { "id": 964037, "author_name": "sai krishna", "author_url": "", "post_date": "2020-08-09T14:33:47.430000", "content": "Congratulations! Great work!
", "votes": 0, "replies": [] }, { "id": 963956, "author_name": "Casimir Rönnlöf", "author_url": "", "post_date": "2020-08-09T13:15:36.387000", "content": "Congratulations! Great work!
", "votes": 0, "replies": [] }, { "id": 963796, "author_name": "Laxmikanta Nayak", "author_url": "", "post_date": "2020-08-09T09:44:08.490000", "content": "This is nice work
", "votes": 0, "replies": [] }, { "id": 963739, "author_name": "takayukiblue", "author_url": "", "post_date": "2020-08-09T08:48:24.433000", "content": "I look forward to the code being published.\nGreat work!
", "votes": 0, "replies": [] }, { "id": 963676, "author_name": "kengo katayama", "author_url": "", "post_date": "2020-08-09T07:52:20.860000", "content": "This is excellent work
", "votes": 0, "replies": [] }, { "id": 963233, "author_name": "Mrinmoy Nil", "author_url": "", "post_date": "2020-08-08T19:16:28.583000", "content": "poi poi koira hisab raikhen
", "votes": 0, "replies": [] }, { "id": 963141, "author_name": "Prashant Malav", "author_url": "", "post_date": "2020-08-08T17:34:15.213000", "content": "great work
", "votes": 0, "replies": [] }, { "id": 963088, "author_name": "", "author_url": "", "post_date": "2020-08-08T16:52:48.027000", "content": "", "votes": 0, "replies": [] }, { "id": 962890, "author_name": "", "author_url": "", "post_date": "2020-08-08T14:21:31.560000", "content": "", "votes": 0, "replies": [] }, { "id": 962678, "author_name": "", "author_url": "", "post_date": "2020-08-08T10:38:35.863000", "content": "", "votes": 0, "replies": [] }, { "id": 962667, "author_name": "", "author_url": "", "post_date": "2020-08-08T10:23:14.763000", "content": "", "votes": 0, "replies": [] }, { "id": 962590, "author_name": "", "author_url": "", "post_date": "2020-08-08T08:56:39.113000", "content": "", "votes": 0, "replies": [] }, { "id": 962572, "author_name": "", "author_url": "", "post_date": "2020-08-08T08:45:17.133000", "content": "", "votes": 0, "replies": [] }, { "id": 962355, "author_name": "", "author_url": "", "post_date": "2020-08-08T04:43:12.787000", "content": "", "votes": 0, "replies": [] }, { "id": 962196, "author_name": "", "author_url": "", "post_date": "2020-08-07T22:49:42.110000", "content": "", "votes": 0, "replies": [] }, { "id": 961969, "author_name": "", "author_url": "", "post_date": "2020-08-07T17:04:36.760000", "content": "", "votes": 0, "replies": [] }, { "id": 961737, "author_name": "", "author_url": "", "post_date": "2020-08-07T13:14:11.267000", "content": "", "votes": 0, "replies": [] }, { "id": 961583, "author_name": "", "author_url": "", "post_date": "2020-08-07T10:01:32.600000", "content": "", "votes": 0, "replies": [] }, { "id": 961443, "author_name": "", "author_url": "", "post_date": "2020-08-07T07:33:12.163000", "content": "", "votes": 0, "replies": [] }, { "id": 961187, "author_name": "", "author_url": "", "post_date": "2020-08-07T01:30:48.680000", "content": "", "votes": 0, "replies": [] }, { "id": 961016, "author_name": "", "author_url": "", "post_date": "2020-08-06T21:03:37.093000", "content": "", "votes": 0, "replies": [ { "id": 967645, "author_name": "", "author_url": "", "post_date": "2020-08-12T11:58:48.160000", "content": "", "votes": 1, "replies": [] } ] }, { "id": 960965, "author_name": "", "author_url": "", "post_date": "2020-08-06T20:24:52.127000", "content": "", "votes": 0, "replies": [] }, { "id": 960930, "author_name": "", "author_url": "", "post_date": "2020-08-06T19:49:24.573000", "content": "", "votes": 0, "replies": [] }, { "id": 960911, "author_name": "", "author_url": "", "post_date": "2020-08-06T19:31:25.720000", "content": "", "votes": 0, "replies": [] }, { "id": 960791, "author_name": "", "author_url": "", "post_date": "2020-08-06T17:15:02.280000", "content": "", "votes": 0, "replies": [] }, { "id": 960785, "author_name": "", "author_url": "", "post_date": "2020-08-06T17:10:31.733000", "content": "", "votes": 0, "replies": [ { "id": 967637, "author_name": "", "author_url": "", "post_date": "2020-08-12T11:52:47.313000", "content": "", "votes": 1, "replies": [] } ] }, { "id": 960778, "author_name": "", "author_url": "", "post_date": "2020-08-06T17:07:56.107000", "content": "", "votes": 0, "replies": [ { "id": 967634, "author_name": "", "author_url": "", "post_date": "2020-08-12T11:49:43.653000", "content": "", "votes": 2, "replies": [] } ] }, { "id": 960664, "author_name": "", "author_url": "", "post_date": "2020-08-06T15:24:38.493000", "content": "", "votes": 0, "replies": [] }, { "id": 960662, "author_name": "", "author_url": "", "post_date": "2020-08-06T15:22:45.587000", "content": "", "votes": 0, "replies": [] }, { "id": 960506, "author_name": "", "author_url": "", "post_date": "2020-08-06T13:08:41.737000", "content": "", "votes": 0, "replies": [] }, { "id": 960121, "author_name": "", "author_url": "", "post_date": "2020-08-06T06:49:11.170000", "content": "", "votes": 0, "replies": [] }, { "id": 959969, "author_name": "", "author_url": "", "post_date": "2020-08-06T04:09:25.023000", "content": "", "votes": 0, "replies": [] }, { "id": 959686, "author_name": "", "author_url": "", "post_date": "2020-08-05T20:13:22.670000", "content": "", "votes": 0, "replies": [ { "id": 959824, "author_name": "", "author_url": "", "post_date": "2020-08-05T23:39:14.133000", "content": "", "votes": 0, "replies": [] }, { "id": 960138, "author_name": "", "author_url": "", "post_date": "2020-08-06T07:08:21.050000", "content": "", "votes": 5, "replies": [] } ] }, { "id": 959658, "author_name": "", "author_url": "", "post_date": "2020-08-05T19:34:11.197000", "content": "", "votes": 0, "replies": [] }, { "id": 959636, "author_name": "", "author_url": "", "post_date": "2020-08-05T19:08:00.620000", "content": "", "votes": 0, "replies": [] }, { "id": 959632, "author_name": "", "author_url": "", "post_date": "2020-08-05T19:02:30.773000", "content": "", "votes": 0, "replies": [] }, { "id": 959611, "author_name": "", "author_url": "", "post_date": "2020-08-05T18:35:17.710000", "content": "", "votes": 0, "replies": [ { "id": 960163, "author_name": "", "author_url": "", "post_date": "2020-08-06T07:26:08.880000", "content": "", "votes": 7, "replies": [] }, { "id": 960187, "author_name": "", "author_url": "", "post_date": "2020-08-06T07:52:09.830000", "content": "", "votes": 0, "replies": [] } ] }, { "id": 959602, "author_name": "", "author_url": "", "post_date": "2020-08-05T18:28:09.550000", "content": "", "votes": 0, "replies": [] }, { "id": 959553, "author_name": "", "author_url": "", "post_date": "2020-08-05T17:28:48.937000", "content": "", "votes": 0, "replies": [ { "id": 959569, "author_name": "", "author_url": "", "post_date": "2020-08-05T17:43:38.827000", "content": "", "votes": 4, "replies": [] }, { "id": 959783, "author_name": "", "author_url": "", "post_date": "2020-08-05T22:11:28.580000", "content": "", "votes": 0, "replies": [] }, { "id": 959915, "author_name": "", "author_url": "", "post_date": "2020-08-06T03:03:21.060000", "content": "", "votes": 3, "replies": [] }, { "id": 961193, "author_name": "", "author_url": "", "post_date": "2020-08-07T01:44:44.333000", "content": "", "votes": 0, "replies": [] } ] }, { "id": 965422, "author_name": "", "author_url": "", "post_date": "2020-08-10T16:00:06.633000", "content": "", "votes": -1, "replies": [] }, { "id": 963494, "author_name": "", "author_url": "", "post_date": "2020-08-09T04:38:59.063000", "content": "", "votes": 0, "replies": [] }, { "id": 963471, "author_name": "", "author_url": "", "post_date": "2020-08-09T04:10:26.940000", "content": "", "votes": 0, "replies": [] }, { "id": 963470, "author_name": "", "author_url": "", "post_date": "2020-08-09T04:10:17.010000", "content": "", "votes": 0, "replies": [] }, { "id": 962408, "author_name": "", "author_url": "", "post_date": "2020-08-08T05:38:41.710000", "content": "", "votes": 0, "replies": [] }, { "id": 961582, "author_name": "", "author_url": "", "post_date": "2020-08-07T10:01:10.280000", "content": "", "votes": 0, "replies": [] }, { "id": 961430, "author_name": "", "author_url": "", "post_date": "2020-08-07T07:20:58.393000", "content": "", "votes": 0, "replies": [] }, { "id": 963695, "author_name": "", "author_url": "", "post_date": "2020-08-09T08:08:23", "content": "", "votes": 11, "replies": [] }, { "id": 961340, "author_name": "", "author_url": "", "post_date": "2020-08-07T05:28:48.720000", "content": "", "votes": 1, "replies": [] }, { "id": 959476, "author_name": "", "author_url": "", "post_date": "2020-08-05T16:00:58.067000", "content": "", "votes": 1, "replies": [] }, { "id": 974345, "author_name": "", "author_url": "", "post_date": "2020-08-17T23:12:38.733000", "content": "", "votes": 0, "replies": [] }, { "id": 971983, "author_name": "", "author_url": "", "post_date": "2020-08-16T06:22:33.110000", "content": "", "votes": 0, "replies": [] }, { "id": 968798, "author_name": "", "author_url": "", "post_date": "2020-08-13T08:45:10.493000", "content": "", "votes": 0, "replies": [] }, { "id": 967349, "author_name": "", "author_url": "", "post_date": "2020-08-12T07:20:17.787000", "content": "", "votes": 0, "replies": [] }, { "id": 966933, "author_name": "", "author_url": "", "post_date": "2020-08-11T19:13:26.967000", "content": "", "votes": 0, "replies": [] }, { "id": 966084, "author_name": "", "author_url": "", "post_date": "2020-08-11T05:46:08.043000", "content": "", "votes": 0, "replies": [] }, { "id": 965500, "author_name": "", "author_url": "", "post_date": "2020-08-10T17:18:39.943000", "content": "", "votes": 0, "replies": [] }, { "id": 964924, "author_name": "", "author_url": "", "post_date": "2020-08-10T09:15:11.207000", "content": "", "votes": 0, "replies": [] }, { "id": 963244, "author_name": "", "author_url": "", "post_date": "2020-08-08T19:34:13.457000", "content": "", "votes": 0, "replies": [] }, { "id": 963075, "author_name": "", "author_url": "", "post_date": "2020-08-08T16:36:54.887000", "content": "", "votes": 0, "replies": [] }, { "id": 961878, "author_name": "", "author_url": "", "post_date": "2020-08-07T15:22:54.510000", "content": "", "votes": 0, "replies": [] }, { "id": 961459, "author_name": "", "author_url": "", "post_date": "2020-08-07T07:41:19.243000", "content": "", "votes": 0, "replies": [] }, { "id": 960739, "author_name": "", "author_url": "", "post_date": "2020-08-06T16:38:57.323000", "content": "", "votes": 0, "replies": [] }, { "id": 960320, "author_name": "", "author_url": "", "post_date": "2020-08-06T10:01:44.937000", "content": "", "votes": 0, "replies": [] }, { "id": 959927, "author_name": "", "author_url": "", "post_date": "2020-08-06T03:11:34.383000", "content": "", "votes": 0, "replies": [] } ], "raw_markdown_by_id": { "959429": "# Introduction\n(This post was jointly written by the winning team, see details below)\n\nFirst, we wish to express our congratulations to the winners and to all the nominees as well for their remarkable achievements and continued excellence and look forward to exciting times in object detection algorithms.\n\nIn addition, many thanks to Kaggle and the organizers for holding this interesting competition. And special thanks to my colleagues @orkatz2 (Or Katz) and @solomonk (Shlomo Kashani, author of the book “Deep Learning Interviews”).\n\n# Code\n- training code: https://github.com/amirassov/kaggle-global-wheat-detection\n- submission code: [pseudo ensemble: detectors (3 st)+universenet r10](https://www.kaggle.com/amiras/pseudo-ensemble-detectors-3-st-universenet-r10)\n\n# Summary\nOur solution is based on the excellent MMDetection framework (https://github.com/open-mmlab/mmdetection). We evaluated and tested numerous models in an attempt to find the ones which are better suited for wheat detection. Why? Because there is not always a direct correlation between the COCO mAP score, as reported by the authors of the original models, and the actual mAP on the wheat corpus. Therefore, experimentation was extremely important. Amongst the many models we evaluated in MMDet are: \n- GFocal\n- ATSS\n- UniverseNet \n- DetectorRS \n- SOLO-v2 (used for segmentation but we experimented with it anyway)\n\nWe then trained an ensemble of the top-performing models which were: \n- DetectoRS with the ResNet50 backbone (https://github.com/joe-siyuan-qiao/DetectoRS)\n- UniverseNet+GFL with the Res2Net101 backbone (https://github.com/shinya7y/UniverseNet)\n\nTo increase the score a single round of pseudo labelling was applied to each model. Additionally, for a much better generalization of our models, we used heavy augmentations.\n\n# Jigsaw puzzles\nIn the original corpus provided by the organizers, the training images were cropped from an original set of larger images. Therefore, we collected and assembled the original puzzles resulting in a corpus of 1330 puzzle images. The puzzle collection algorithm we adopted was based on https://github.com/lRomul/argus-tgs-salt/blob/master/mosaic/create_mosaic.py. But we were unsuccessful in collecting the bounding boxes for puzzles. Mainly because of the existence of bounding boxes that are located on or in the vicinity the border of the image. For this reason, we generated crops for the puzzles offline in addition to training images and generated boxes for them using pseudo labelling.\n\n# Validation approach \nWe used MultilabelStratifiedKFold with 5 folds (https://github.com/trent-b/iterative-stratification) stratified by the number of boxes, a median of box areas and source of images. We guaranteed that there isn’t any leak between the sub-folds, so that the images of one puzzle were used only in that one particular fold.\n\nReferring to the paper https://arxiv.org/abs/2005.02162, one can see wheat heads from different sources. We assumed that the wheat heads of usask_1, ethz_1 sources are very different from the test sources (UTokyo_1, UTokyo_2, UQ_1, NAU_1). Therefore, we did not use these sources for validation.\n\nHowever, our validation scores did not correlate well with the Kaggle LB. We only noticed global improvements (for example, DetectoRS is better than UniverseNet). Local improvements such as augmentation parameters, WBF parameters etc. did not correlate. We, therefore, shifted our attention to the LB scores mainly. \n\nWe trained our models only on the first fold.\n\n# Augmentations\nDue to the relatively small size of our training set, and another test set distribution, our approach relied heavily on data augmentation. During training, we utilized an extensive data augmentation protocol:\n- Various augmentations from albumentations library (https://albumentations.ai):\n - HorizontalFlip, ShiftScaleRotate, RandomRotate90\n - RandomBrightnessContrast, HueSaturationValue, RGBShift\n - RandomGamma\n - CLAHE\n - Blur, MotionBlur\n - GaussNoise\n - ImageCompression\n - CoarseDropout\n- RandomBBoxesSafeCrop. Randomly select N boxes in the image and find their union. Then we cropped the image keeping this unified.\n- Image colorization (https://www.kaggle.com/orkatz2/pytorch-pix-2-pix-for-image-colorization) \n- Style transfer (https://github.com/bethgelab/stylize-datasets). A random image from a small test (10 images) was used as a style. \n- Mosaic augmentation. `a, b, c, d` -- randomly selected images. Then we just do the following:\n```\ntop = np.concatenate([a, b], axis=1)\nbottom = np.concatenate([c, d], axis=1)\nresult = np.concatenate([top, bottom], axis=0)\n```\n- Mixup augmentation. `a, b` -- randomly selected images. Then: `result = (a + b) / 2`\n- Multi-scale Training. In each iteration, the scale of image is randomly sampled from `[(768 + 32 * i, 768 + 32 * i) for i in range(25)]`.\n- All augmentations except colorization and style transfer were applied online.\nExamples of augmented images:\n\n |  \n:-------------------------:|:-------------------------:\n | \n\n# External data:\nSPIKE dataset: https://www.kaggle.com/c/global-wheat-detection/discussion/164346\n\n# Models\nWe used DetectoRS with ResNet50 and UniverseNet+GFL with Res2Net101 as main models. DetectoRS was a little bit more accurate and however much slower to train than UniverseNet:\n- Single DetectoRS Public LB score without pseudo labeling: 0.7592\n- Single UniverseNet Public LB score without pseudo labeling: 0.7567\n\nFor DetectoRS we used:\n- LabelSmoothCrossEntropyLoss with parameter 0.1\n- Empirical Attention (https://github.com/open-mmlab/mmdetection/tree/master/configs/empirical_attention)\n\n# Training pipeline\nIn general, we used a multi-stage training pipeline:\n\n\n# Model inference\nWe used TTA6 (Test Time Augmentation) for all our models:\n- Multi-scale Testing with scales [(1408, 1408), (1536, 1536)]\n- Flips: [original, horizontal, vertical]\n\nFor TTA was used a standard MMDet algorithm with NMS that looks like this for two-stage detectors (DetectoRS):\n\n\nFor one-stage detectors (UniverseNet), the algorithm is similar, only without the part with RoiAlign, Head, etc.\n\n# Pseudo labelling\n- Sampling positive examples. We predicted the test image and received its scores and the bounding boxes. Then we calculated `confidence = np.mean(scores > 0.75)`. If the confidence was greater than 0.6 we accepted this image and used for pseudo labelling.\n- Sources [usask_1, ethz_1] and augmentations like mosaic, mixup, colorization, style transfer weren’t used for pseudo labelling.\n- 1 epoch, 1 round, 1 stage.\n- Data: original data + 3 x pseudo test data\n\n# Ensemble\nWe used WBF (https://github.com/ZFTurbo/Weighted-Boxes-Fusion) for the ensemble. The distribution of DetectoRS and UniverseNet scores is different. So we applied scaling using `rankdata` (https://docs.scipy.org/doc/scipy/reference/generated/scipy.stats.rankdata.html):\n```\nscaled_scores = 0.5 * (rankdata(scores) / len(scores)) + 0.5.\n```\n\nWBF parameters:\n- weights=[0.65, 0.35] respectively for models [DetectoRS, UniverseNet]\n- iou_thr=0.55\n- score_thr=0.45\n\n# Our final submission pipeline (0.7262 on Private LB and 0.7734 on Public LB):\n\n\n# Some observations from our submissions:\n- Pseudo crops from jigsaw puzzles (DetectoRS R50): 0.7513 -> 0.7582\n- Tuning of pseudo labeling parameters for sampling positive examples (ensemble): 0.7709 -> 0.7729\n- Pseudo labeling (DetectoRS R50): 0.7582 -> 0.7691\n- Pseudo labeling (UniverseNet Res2Net50): 0.7494 -> 0.7627\n- SPIKE dataset (DetectoRS R50): 0.7582 -> 0.7592\n- Deleting [usask1, ethz1] from pseudo labeling (DetectoRS R50): 0.7678 -> 0.7691\n\n# What we didn’t do:\n- MMDetection and YOLOV5 ensemble. That was the main goal but since YOLOV5 was disqualified we gave up this option.\n- MMDetection and EfficientDet ensemble. We only managed to make a submission for the first time on the last day but we could not get a good enough result. We believe that if we had a few more days we could improve the result by tune the WBF parameters.\n- We stopped improving YOLOV5 about a month before the end of the competition. \n\n# What didn’t work:\n- Wheat Ears Detection Dataset: CV improved, but LB did not.\n- More than 1 rounds of pseudo labeling with the same model.\n- Scale-aware testing like this: https://drive.google.com/file/d/14VwSjMeRZUtisZtqQPmbll6w4zvZXIAQ\n- Rotate90 TTA for DetectoRS and UniverseNet\n\n# Acknowledgements\nThanks to internet service provider HOSTKEY (https://www.hostkey.com) that gave me a grant for access to GPU servers.\n\n\n**The code will be published soon.**\n\n", "959432": "I am sooooo proud of both of you Amir and Or! what a great team!!! ", "963728": "Great work!", "959471": "Thanks for sharing!\nIt looks like GANs didn't work in your solution.\nCongratulation @amiras to new grand master!", "978012": "Congratulations on becoming a GM! Great achievement. I was a bit scared there, you were 1 place out of the Gold zone. That would have been quite unfortunate.", "967409": "Thanks for sharing the information with me.mmdet is nice", "965494": "This is great, thanks a lot for sharing 💚 \nand, Congratulations 😍 ", "963274": "Nice work. Congratulations", "960519": "Great work!", "959924": "Congratulations to you and team. Thanks for writeup your team solution @amiras", "959489": "Great solution! Gratz", "959483": "Thank you for the detailed explanation.\n\nCongrats @amiras and your awesome team! ", "1250783": "@amiras Great solution. May iI asked what was your plan on tuning the wbf parameters? Thank you", "986049": "Hello,Why you didnot use Mosaic in P-label training?", "986048": "Hello,Why you didnot use Mosaic in P-label training?", "974503": "Great info. Thanks for also sharing some info about the sub-optimal pipelines. Good to be reminder that often times finding the right approach is about eliminating the wrong approaches.", "971835": "Great work! Could you please share your UniverseNet's code or config file for me . ", "969919": "Congratulations on first place and thank you for sharing 👊", "969720": "Impressive work!", "968801": "Thanks for the information. For a beginner like me, this knowledge is really helpful", "967053": "Nice work! Congratulations and thanks for sharing!", "965935": "First post I ever read, it was great. Thanks!", "964685": "thanks for sharing, I look forward to your code", "964037": "Congratulations! Great work!", "963956": "Congratulations! Great work!", "963796": "This is nice work ", "963739": "I look forward to the code being published.\nGreat work!", "963676": "This is excellent work", "963233": "poi poi koira hisab raikhen", "963141": "great work\n", "963088": "Great work!", "962890": "good job!!!", "962678": "Well Done!", "962667": "Thanks for sharing your awesome solution, with so much detail.\nCongratulations, very well deserved!", "962590": "Great solution. Good job!", "962572": "Interesting work", "962355": "quite interesting work", "962196": "Great solve", "961969": "Thank you for sharing the details! Great explanation!", "961737": "Great Work!!", "961583": "Great work! :) ", "961443": "Congratulations!", "961187": "Great work!Do you have plans for open source code?", "961016": "Style transfer is genius in this case! Have you checked the impact on the final score?\nThanks for sharing, and congratulations for you and your team.", "960965": "Congratulations", "960930": "Great work!", "960911": "Thank you for the detailed explanation.\n\nCongrats @amiras and your awesome team!", "960791": "Great work", "960785": "How efficient has it been the use of 'RetinaNet' while making the ensemble instead of YOLO? Just curious to understand.\n\nGreat work I would say for the task performed and Congratulations!", "960778": "It's really a great job.Thanks for sharing!\nBut I am not sure what is the meaning of \"We trained our models only on the first fold\".Do you mean you are training your models in the same fold(1/5 dataset)?", "960664": "Great piece of work!! ", "960662": "Cool", "960506": "wow!", "960121": "Very Impressive!!!. Huge Thanks for sharing!!", "959969": "Great works! Thanks for sharing, such a informative solution with tons of knowledge 💯 ", "959686": "Sorry for a silly questions, but I still wonder how is TTA effective in Object detection as every different augmentation will gove us different bounding boxes so how do we get correct prediction at last?", "959658": "Thank you for the detailed explanation.\n\nCongrats @amiras and your awesome team!", "959636": "Congratulations! Hard work payed back indeed, awesome insights to the approach. Thank you so much for sharing!", "959632": "Congratulations! ", "959611": "Thanks very much for sharing the solution, and congratulations on the phenomenal effort! I have a question about your post. Would you be able to indicate which of the many methods you applied provided the most boost vs those which you're not sure helped much?", "959602": "Many thanks and congratulations on new grandmaster @amiras!! You deserve the winner with lots of works and knowledge. I've learned a lot", "959553": "Congratulations! \n\nI noticed that you trained only 1 epoch on pseudo-label model. I am wondering how much gain you got from it? ", "965422": "", "963494": "", "963471": "", "963470": "", "962408": "", "961582": "", "961430": "", "963695": "Thank for sharing, Great solution!", "961340": "Thank you for the detailed explanation.", "959476": "huge. Thank for sharing", "974345": "Thanks for sharing!!!!!!", "971983": "Great Work !! thanks for sharing", "968798": "Thanks for the information", "967349": "Thank for sharing", "966933": "Great work and thanks for sharing...", "966084": "Congratulations! Thanks for sharing!", "965500": "Keep sharing bro!! Thanks", "964924": "So informative! Thanks a lot.", "963244": "Perfect.Thank for sharing", "963075": "Thanks for sharing!", "961878": "Very Interesting, thank you!", "961459": "Congratulations.\nThanks for sharing", "960739": "I enjoyed reading thank you very much.", "960320": "Congratulations and thanks for sharing!", "959927": "Informative! Thank you :) " } }