
Congrats to all winners! And thanks to organizers!\nThe competition was very very difficult for me, but fortunately I got 26th place.\nI share my gotten knowledge.
\n\nI used a huggingface transformer and customized the head of the model.
\n\n
As you know, I imitated the first solution of the jigsaw.
\n\nBERT-base-cased, BERT-base-uncased and XLNet-base-case with this header were weighted at 2:4:4.
\n\nI add category token. like below;
\n\n\n[CLS] [CATEGORY_TOKEN] question_title [SEP] question_body [SEP] ansewr [SEP]\n\nIt raised 0.05 my CV.
I read this Discussion.\nI calculated the common denominator and binned the predicted values.\nOptimized binning with features like OptimizeRounder.
\n\nThank you!!
", "comments": [ { "id": 744216, "author_name": "YaGana Sheriff-Hussaini", "author_url": "", "post_date": "2020-02-12T16:59:18.170000", "content": "Congrats @takamichitoda and thanks for sharing your code.
", "votes": 1, "replies": [] }, { "id": 743638, "author_name": "Ailurophile", "author_url": "", "post_date": "2020-02-12T06:45:26.110000", "content": "Congratulations!\nThanks for Sharing your Approach & Insights!! @takamichitoda
", "votes": 1, "replies": [] }, { "id": 743461, "author_name": "Aditya Soni", "author_url": "", "post_date": "2020-02-12T04:40:14.563000", "content": "When we added Domain Categories, it didn't help at all :(
", "votes": 1, "replies": [ { "id": 743663, "author_name": "Takamichi Toda", "author_url": "", "post_date": "2020-02-12T07:08:53.003000", "content": "Oh, really? In my case, all three model improves when add category.\nI can't explain it, sorry...
", "votes": 0, "replies": [] } ] }, { "id": 743449, "author_name": "Chris Deotte", "author_url": "", "post_date": "2020-02-12T04:20:30.397000", "content": "Great job. Creative model. Adding a category token was very clever. Inputting category early in the model allows all hidden layers to pay attention to it. Can you explain the steps to add a custom token?
", "votes": 1, "replies": [ { "id": 743451, "author_name": "Nirjhar Roy", "author_url": "", "post_date": "2020-02-12T04:25:21.920000", "content": "I think its here : \nhttps://github.com/trtd56/KaggleQuest/blob/master/work/Quest_BERT-train.ipynb
\n\n```\ntokenizer = tokenizer_class.from_pretrained(pretrained_weights)
\n\ncategories = train[\"category\"].unique().tolist()\ncategories = [f\"[{c}]\" for c in categories]\ntokenizer.add_tokens(categories)
\n\ntokenizer.added_tokens_encoder\n```
", "votes": 2, "replies": [] }, { "id": 743455, "author_name": "Chris Deotte", "author_url": "", "post_date": "2020-02-12T04:29:35.120000", "content": "Wow awesome.
", "votes": 1, "replies": [] } ] }, { "id": 743439, "author_name": "Gerwyn", "author_url": "", "post_date": "2020-02-12T04:07:50.843000", "content": "Congrats and thanks for the write up!! :)
\n\nMay i ask how much difference in CV for your xlnet/bert cased vs bert base uncased?
", "votes": 1, "replies": [ { "id": 743459, "author_name": "Takamichi Toda", "author_url": "", "post_date": "2020-02-12T04:35:03.570000", "content": "My CV is that:\n- BERT-uncased: 0.4109153513\n- BERT-cased:0.4047241234\n- XLNet-cased:0.407151191
\n\nand tried mix result is:\n|BERT-uncased|BERT-cased|XLNet-cased|CV|\n| -- | -- | -- | -- |\n|0.3|0.3|0.3|0.421838540812048|\n|0.5|0.2|0.3|0.42176727179908|\n|0.4|0.2|0.4|0.422223424005272|
", "votes": 1, "replies": [] }, { "id": 743478, "author_name": "Gerwyn", "author_url": "", "post_date": "2020-02-12T05:17:12.563000", "content": "wow thanks for the details!
\n\nI also can't beat my bert base uncased baseline with cased and xlnet version too
", "votes": 1, "replies": [] } ] }, { "id": 744000, "author_name": "Nandhu Elango", "author_url": "", "post_date": "2020-02-12T13:17:11.973000", "content": "Very nice and clean code for better understanding👍
", "votes": 0, "replies": [] } ], "comment_count": 11, "messages": [ { "id": 743394, "postDate": "2020-02-12T02:55:53.030Z", "content": "Congrats to all winners! And thanks to organizers!\nThe competition was very very difficult for me, but fortunately I got 26th place.\nI share my gotten knowledge.
\n\nI used a huggingface transformer and customized the head of the model.
\n\n
As you know, I imitated the first solution of the jigsaw.
\n\nBERT-base-cased, BERT-base-uncased and XLNet-base-case with this header were weighted at 2:4:4.
\n\nI add category token. like below;
\n\n\n[CLS] [CATEGORY_TOKEN] question_title [SEP] question_body [SEP] ansewr [SEP]\n\nIt raised 0.05 my CV.
I read this Discussion.\nI calculated the common denominator and binned the predicted values.\nOptimized binning with features like OptimizeRounder.
\n\nThank you!!
", "rawMarkdown": "Congrats to all winners! And thanks to organizers!\nThe competition was very very difficult for me, but fortunately I got 26th place.\nI share my gotten knowledge.\n\n### modeling\n\nI used a huggingface transformer and customized the head of the model.\n\n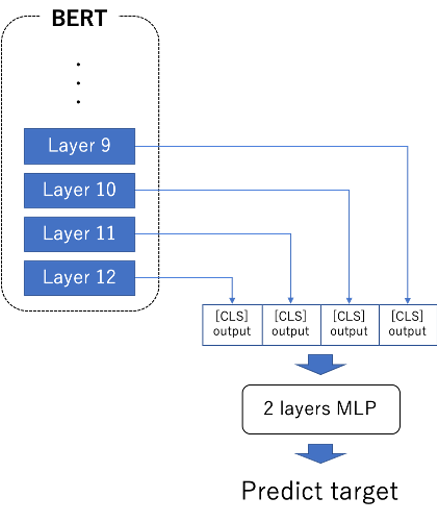\n\n\nAs you know, I imitated the first solution of the [jigsaw](https://www.kaggle.com/c/jigsaw-unintended-bias-in-toxicity-classification/discussion/103280).\n\nBERT-base-cased, BERT-base-uncased and XLNet-base-case with this header were weighted at 2:4:4.\n\n### Parameter\n\n- 10 GroupFold\n- epoch: 3\n- batch size: 8\n- optimizer: AdamW\n - OneCycleLR\n - max_lr=5e-5 (decay*0.9)\n- loss: BCE + MSE(MSE weighted by label frequency)\n\n### Token\n\nI add category token. like below;\n\n```\n[CLS] [CATEGORY_TOKEN] question_title [SEP] question_body [SEP] ansewr [SEP]\n```\nIt raised 0.05 my CV.\n\n### Optimize binning\n\nI read [this Discussion](https://www.kaggle.com/c/google-quest-challenge/discussion/119177).\nI calculated the common denominator and binned the predicted values.\nOptimized binning with features like [OptimizeRounder](https://www.kaggle.com/c/petfinder-adoption-prediction/discussion/76107).\n\n### not work for me\n- pseudo label\n- MultiSample Dropout\n- SWA\n- AdaBound\n- FocalLoss\n- RoBERTa, ALBERT\n- Prediction with Special Token for each target\n\n### my code\n- train: https://github.com/trtd56/KaggleQuest\n- predict : https://www.kaggle.com/takamichitoda/26th-place-solution?scriptVersionId=28524791\n\nThank you!!", "votes": 14 }, { "id": 744216, "postDate": "2020-02-12T16:59:18.170Z", "content": "Congrats @takamichitoda and thanks for sharing your code.
", "rawMarkdown": "Congrats @takamichitoda and thanks for sharing your code.", "votes": 1 }, { "id": 743638, "postDate": "2020-02-12T06:45:26.110Z", "content": "Congratulations!\nThanks for Sharing your Approach & Insights!! @takamichitoda
", "rawMarkdown": "Congratulations!\nThanks for Sharing your Approach & Insights!! @takamichitoda ", "votes": 1 }, { "id": 743461, "postDate": "2020-02-12T04:40:14.563Z", "content": "When we added Domain Categories, it didn't help at all :(
", "rawMarkdown": "When we added Domain Categories, it didn't help at all :(", "votes": 1, "replies": [ { "id": 743663, "postDate": "2020-02-12T07:08:53.003Z", "content": "Oh, really? In my case, all three model improves when add category.\nI can't explain it, sorry...
", "rawMarkdown": "Oh, really? In my case, all three model improves when add category.\nI can't explain it, sorry..." } ] }, { "id": 743449, "postDate": "2020-02-12T04:20:30.397Z", "content": "Great job. Creative model. Adding a category token was very clever. Inputting category early in the model allows all hidden layers to pay attention to it. Can you explain the steps to add a custom token?
", "rawMarkdown": "Great job. Creative model. Adding a category token was very clever. Inputting category early in the model allows all hidden layers to pay attention to it. Can you explain the steps to add a custom token?", "votes": 1, "replies": [ { "id": 743451, "postDate": "2020-02-12T04:25:21.920Z", "content": "I think its here : \nhttps://github.com/trtd56/KaggleQuest/blob/master/work/Quest_BERT-train.ipynb
\n\n```\ntokenizer = tokenizer_class.from_pretrained(pretrained_weights)
\n\ncategories = train[\"category\"].unique().tolist()\ncategories = [f\"[{c}]\" for c in categories]\ntokenizer.add_tokens(categories)
\n\ntokenizer.added_tokens_encoder\n```
", "rawMarkdown": "I think its here : \nhttps://github.com/trtd56/KaggleQuest/blob/master/work/Quest_BERT-train.ipynb\n\n```\ntokenizer = tokenizer_class.from_pretrained(pretrained_weights)\n\ncategories = train[\"category\"].unique().tolist()\ncategories = [f\"[{c}]\" for c in categories]\ntokenizer.add_tokens(categories)\n\ntokenizer.added_tokens_encoder\n```", "votes": 2 }, { "id": 743455, "postDate": "2020-02-12T04:29:35.120Z", "content": "Wow awesome.
", "rawMarkdown": "Wow awesome.", "votes": 1 } ] }, { "id": 743439, "postDate": "2020-02-12T04:07:50.843Z", "content": "Congrats and thanks for the write up!! :)
\n\nMay i ask how much difference in CV for your xlnet/bert cased vs bert base uncased?
", "rawMarkdown": "Congrats and thanks for the write up!! :)\n\nMay i ask how much difference in CV for your xlnet/bert cased vs bert base uncased? ", "votes": 1, "replies": [ { "id": 743459, "postDate": "2020-02-12T04:35:03.570Z", "content": "My CV is that:\n- BERT-uncased: 0.4109153513\n- BERT-cased:0.4047241234\n- XLNet-cased:0.407151191
\n\nand tried mix result is:\n|BERT-uncased|BERT-cased|XLNet-cased|CV|\n| -- | -- | -- | -- |\n|0.3|0.3|0.3|0.421838540812048|\n|0.5|0.2|0.3|0.42176727179908|\n|0.4|0.2|0.4|0.422223424005272|
", "rawMarkdown": "My CV is that:\n- BERT-uncased: 0.4109153513\n- BERT-cased:0.4047241234\n- XLNet-cased:0.407151191\n\nand tried mix result is:\n|BERT-uncased|BERT-cased|XLNet-cased|CV|\n| -- | -- | -- | -- |\n|0.3|0.3|0.3|0.421838540812048|\n|0.5|0.2|0.3|0.42176727179908|\n|0.4|0.2|0.4|0.422223424005272|\n", "votes": 1 }, { "id": 743478, "postDate": "2020-02-12T05:17:12.563Z", "content": "wow thanks for the details!
\n\nI also can't beat my bert base uncased baseline with cased and xlnet version too
", "rawMarkdown": "wow thanks for the details! \n\nI also can't beat my bert base uncased baseline with cased and xlnet version too ", "votes": 1 } ] }, { "id": 744000, "postDate": "2020-02-12T13:17:11.973Z", "content": "Very nice and clean code for better understanding👍
", "rawMarkdown": "Very nice and clean code for better understanding👍 " } ], "complete": true, "source": "live", "fetched_at": "2026-10-19T19:08:25Z", "competition_id": 7968, "competition_slug": "google-quest-challenge", "team_id": 4015315, "solution_url": "/competitions/google-quest-challenge/writeups/takamichi-toda-26-place-solution" }